







Background
Cyera Research is advancing the use of Large Language Models (LLMs) in vulnerability research. In this study, our researchers fine-tuned existing LLMs to create specialized workflows that move beyond static analysis to perform contextual code tracing. This approach allowed us to independently uncover a critical Guest-to-Host escape vulnerability in VirtualBox’s VMSVGA driver.
While traditional tools failed to detect the bug - and off-the-shelf LLMs lacked the specific context - our LLM-driven protocol successfully identified the deep logic flaw, enabling us to develop a Proof of Concept (PoC) that crashed the hypervisor. This work is part of Cyera Research Labs’ broader mission to explore the intersection of AI and security, demonstrating how LLMs can serve as force multipliers in deep technical analysis.
Vulnerability research is traditionally a high-latency process. It requires deep understanding of complex codebases, manual tracing of data flows, and significant time spent validating leads. The “10x Researcher” isn’t someone who types faster; it’s someone who can filter noise faster.
In this research, we explored whether AI agents-specifically LLMs operating with custom personas and protocols-could accelerate this process to find critical Guest-to-Host escape vulnerabilities in Oracle VirtualBox.
This experiment targeted the VirtualBox VBox/Devices directory, specifically the SVGA graphics adapter. The results were significant:
vmsvgaR3RectCopy.This post details the methodology, the false starts, and the technical deep dive into the vulnerability found.
Before deploying our custom agents, we followed a standard, rigorous vulnerability research methodology: automated static analysis followed by AI-assisted triage. The goal was to quickly filter low-hanging fruit before diving into manual review.
We started by scanning the entire src/VBox/Devices/Graphics directory using Semgrep with the comprehensive semgrep-rules/c ruleset. We cast a wide net, looking for anything related to memory management, integer arithmetic, and buffer handling.
The output turned into an enormous, noisy dataset—over four million characters long. It included thousands of “findings,” but the signal-to-noise ratio was terrible. Semgrep flagged:
memcpy that depended on a variable size (even if validated 5 lines up).Faced with thousands of leads, manually reviewing each one was unfeasible. We decided to use a powerful LLM to act as a “Tier 1 Analyst” to filter the noise.
We utilized Claude 4.1 Opus to process the Semgrep JSON output. The prompt instructed the model to:
Despite the sophisticated prompt, this workflow failed to uncover any critical bugs. We churned through hundreds of findings, only to end up with a folder full of irrelevant lead files:
Why did it fail?
strcpy is bad”) rather than logic patterns (like “this integer wrap-around bypasses the bounds check”).This failure was a crucial pivot point. We realized that treating the AI as a “filter” for static analysis tools was inefficient. To find deep logic bugs, the AI needed to be the hunter, not just the cleaner. This led us to the “Prompt Strategy” in Phase 2.
To overcome these limitations, we pivoted our approach based on emerging research on LLMs for vulnerability analysis. We moved away from simple “bug finding” queries and instead engineered a specific research protocol grounded in recent academic findings.
Recent studies have demonstrated that LLMs excel at tracing data flow through complex code structures, often outperforming traditional static analysis in handling semantic nuance.
LLMDFA: Analyzing Dataflow in Code with Large Language Models (arXiv:2402.10754) demonstrates that LLMs can effectively model data dependencies without the need for compilation, a critical capability when analyzing partial driver code.
CRUXEval: A Benchmark for Code Reasoning, Understanding and Execution (arXiv:2401.03065) highlights the ability of models like Claude to predict execution output and input-output mappings, which is essential for tracing Guest-controlled inputs to Host sinks.
We hypothesized that by explicitly instructing the model to "trace" the execution path rather than "find bugs," we could leverage this latent capability to map the attack surface more accurately. This hypothesis was grounded in empirical evidence: the foundational studies above demonstrate that LLMs possess inherent code-tracing capabilities that can be effectively applied to security analysis. With this capability validated, the question shifted from "Can LLMs trace execution paths?" to "How do we direct this capability toward domain-specific vulnerability patterns?"
A key insight from Automated Vulnerability Validation and Verification (arXiv:2509.24037) and Teams of LLM Agents can Exploit Zero-Day Vulnerabilities (arXiv:2406.01637) is that generic models struggle with domain-specific vulnerability classes unless primed with relevant definitions and examples.
Instead of performing expensive parameter fine-tuning, we implemented “Context Fine-Tuning” via the system prompt. We augmented the model’s context with:
This strategy effectively transformed Claude from a general-purpose model into a specialized Guest-to-Host security auditor-primed to recognize virtualization-specific attack patterns without expensive retraining. The papers above validated that such prompt-based specialization can achieve domain-specific vulnerability detection comparable to fine-tuned models.
Combining the flow-tracing capabilities with the vulnerability-specific context, we created a rigorous analysis protocol. We stopped asking the AI to “find bugs” and instead instructed it to act as a specialized AI Security Auditing Agent.
The protocol forced the agent to follow a strict analysis flow for every file:
"unreachable": true.This shift was decisive. It moved the AI from being a “Linter” (pattern matching) to being a “Tracer” (reasoning about execution state), directly enabling the discovery of the complex logic bugs in the subsequent phases.
While this protocol was successful, it is important to acknowledge a fundamental limitation identified in FormulaOne: Measuring the Depth of Algorithmic Reasoning Beyond Competitive Programming (arXiv:2507.13337). The study highlights that current LLMs struggle significantly with “expertise problems”- tasks requiring deep, multi-step reasoning that goes beyond surface-level pattern matching.
Real-world vulnerability research is an expertise domain. A complex exploit chain might require 15, 20, or even 30 logical steps to go from a primitive to a stable shell. Current models operate effectively at a “depth” of 2-3 steps (e.g., spotting a missing check). They often fail to maintain the coherent state tracking required for deep 20-step chains (e.g., “If I corrupt this pointer here, how does it affect the heap layout three function calls later?”).
To truly reach state-of-the-art performance in vulnerability research, we believe the next frontier is not just better prompting, but a different type of learning paradigm-one that trains models to operate at the “right depth” of reasoning (20-30 steps) rather than just predicting the next token. We plan to explore this “Deep Reasoning for Exploitation” in a future blog post.
The first major lead generated by the agent was a Use-After-Free (UAF) vulnerability in src/VBox/Devices/Graphics/DevVGA-SVGA-cmd.cpp.
The agent flagged a race condition in the Memory Object Buffer (MOB) management. The logic appeared sound and followed a classic UAF pattern.
The Vulnerable Pattern
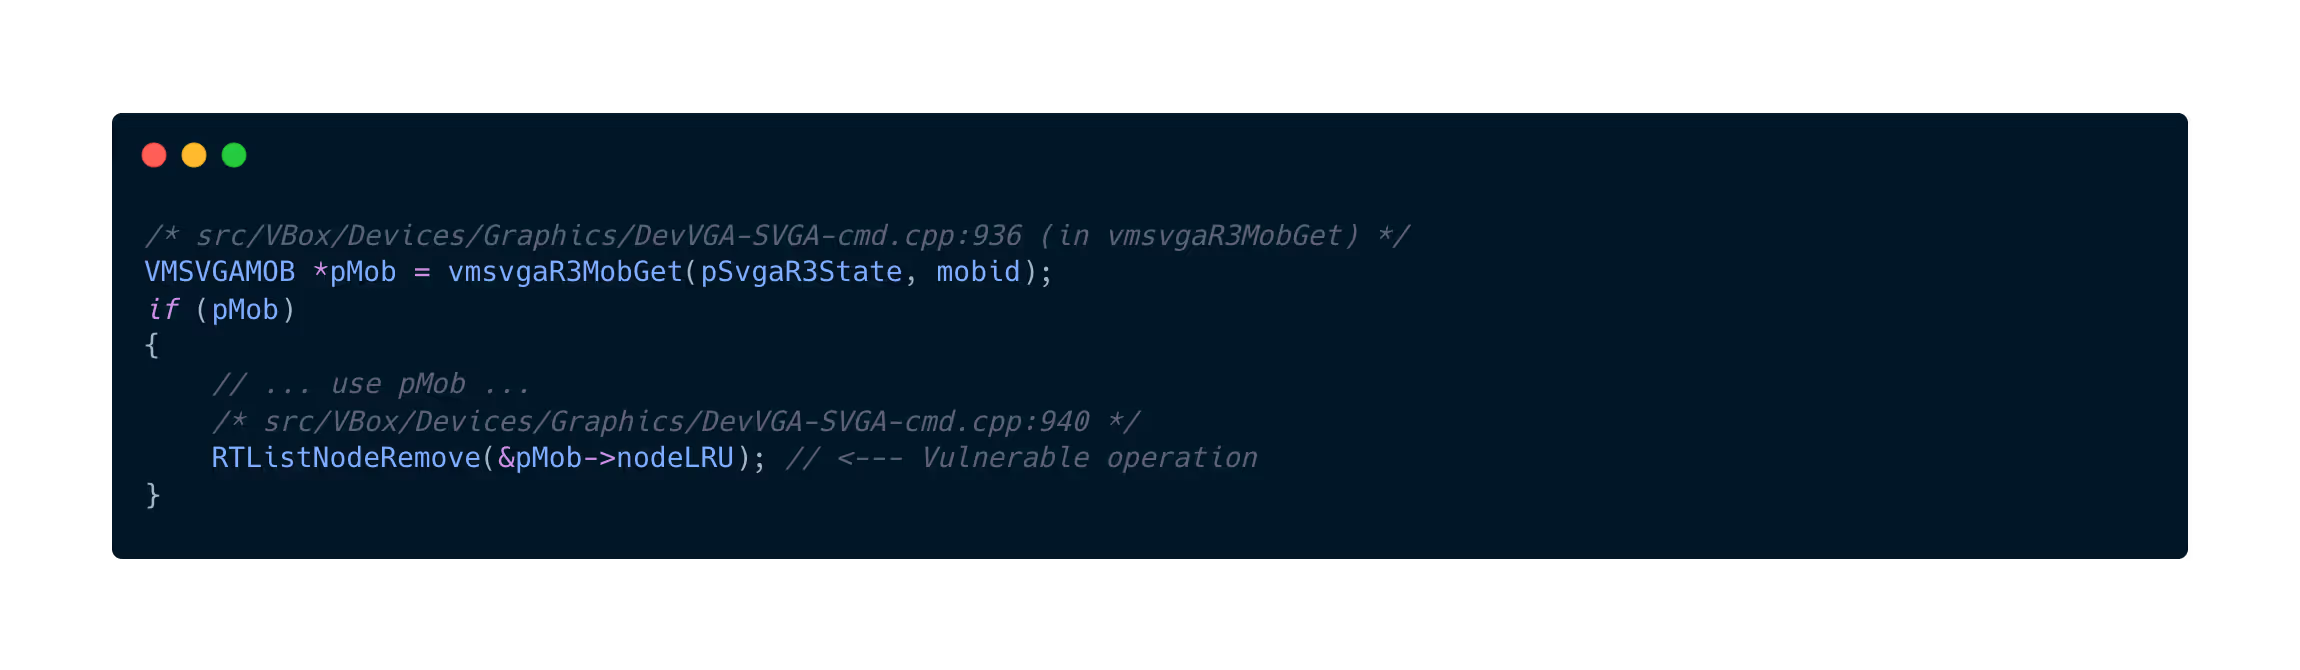
The agent identified two competing operations reachable from the Guest
1. Thread A (Usage):
2. Thread B (Destruction):
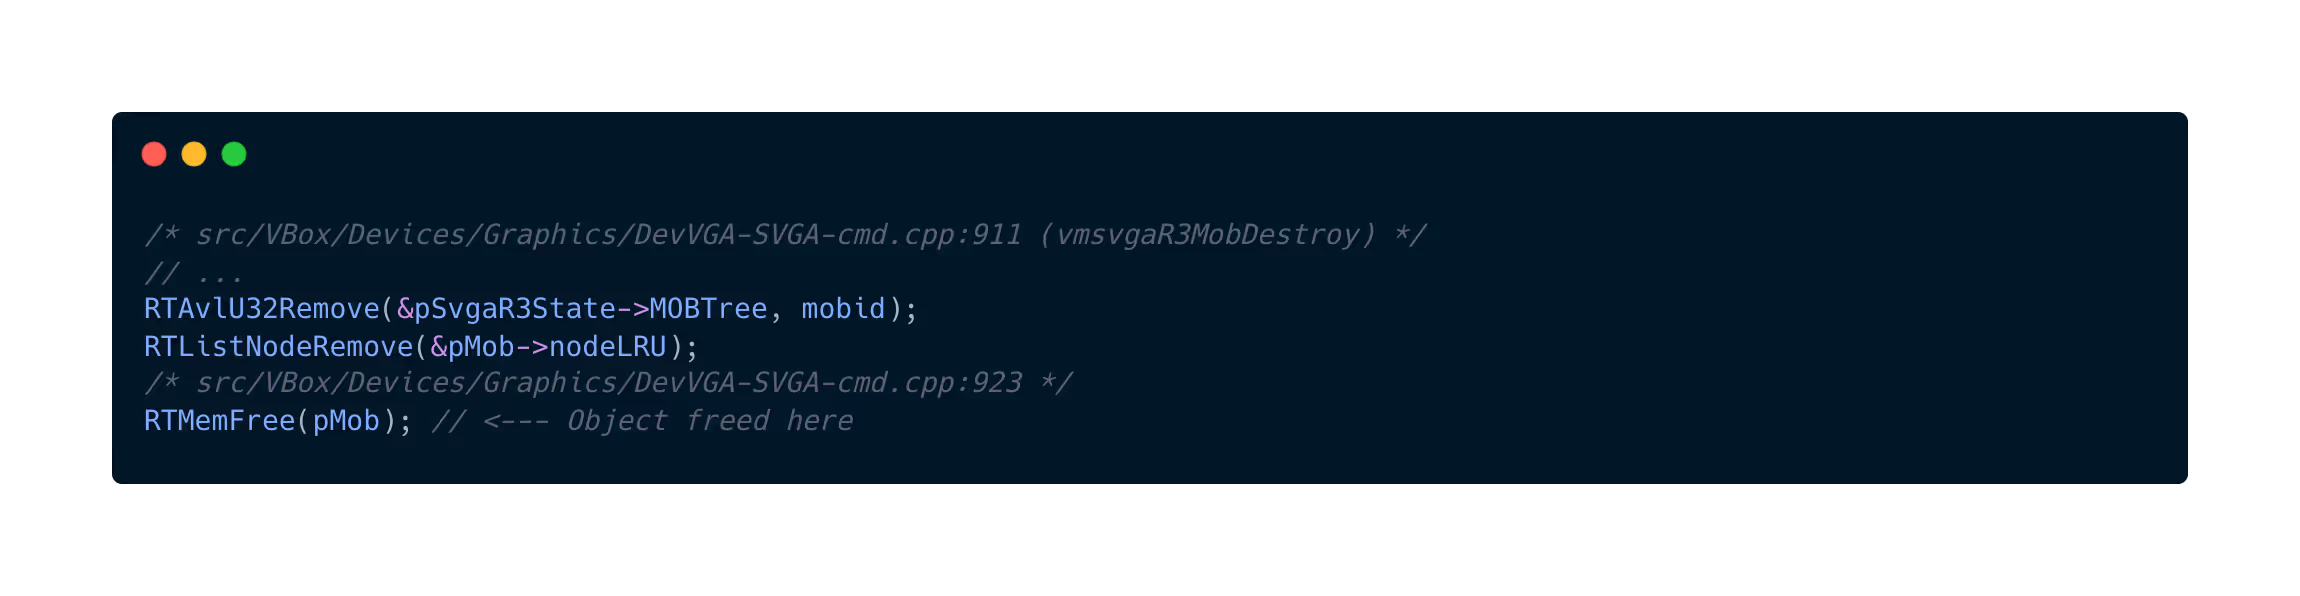
If Thread B executes RTMemFree while Thread A has already passed the pMob check but hasn’t yet called RTListNodeRemove, Thread A will attempt to unlink a node inside freed memory. This is a textbook write-what-where primitive (modifying prev->next and next->prev pointers in freed memory).
We initially attempted to trigger this with aggressive multi-threaded racing, but failed. We then provided the AI with broader context-specifically the device communication protocols defined in the headers and the communicate.c test POC logic.
The AI performed a deeper analysis of the command submission mechanism and discovered the “Doorbell Protocol”, which enforces synchronization:
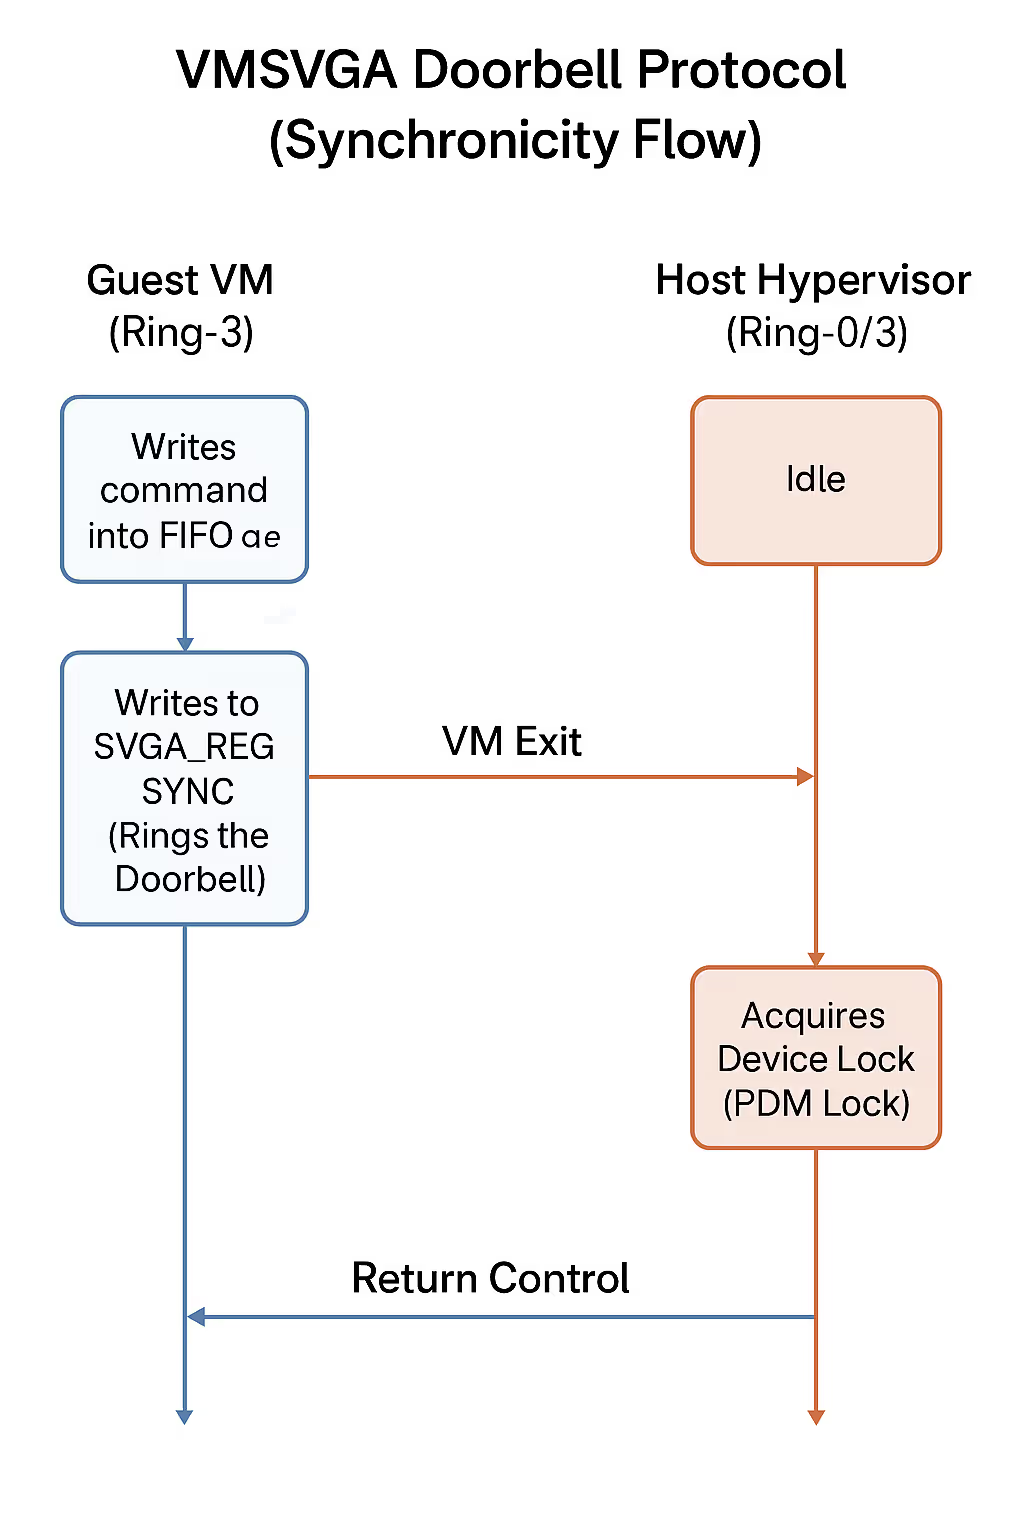
1. FIFO Queue (Guest Side): The Guest writes 3D commands (like DEFINE_GB_MOB or UPDATE_GB_SURFACE) into a shared memory ring buffer (FIFO). These writes are just memory operations and do not immediately trigger Host processing.
2. The “Doorbell” (Guest Side): To notify the Host that new commands are ready, the Guest performs an I/O port write to SVGA_REG_SYNC (Value 1).
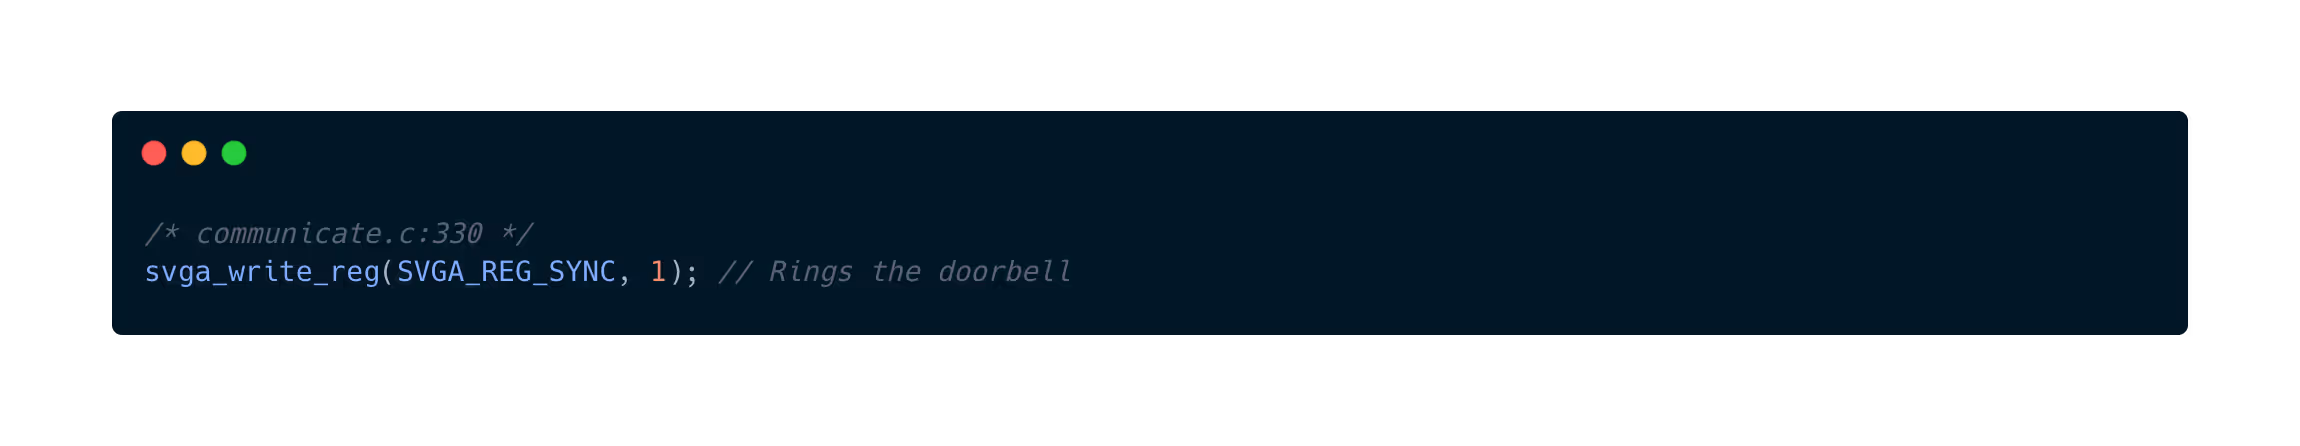
3. TVM Exit (Hypervisor): This I/O write is a privileged operation that triggers a VM Exit. The CPU pauses the Guest execution and transfers control to the VirtualBox Hypervisor.
4. The Main Thread Lock (Host Side): The Hypervisor handles the I/O exit by acquiring the device lock (VirtualBox's PDM device lock, analogous to QEMU's BQL).
5. Serialized Execution: The DevVGA-SVGA.cpp dispatcher reads the FIFO and executes all pending commands in a tight loop, sequentially, within that single thread context. It does not release the lock until the batch is processed.
This “Doorbell Protocol” effectively serializes the “concurrent” Guest operations. Even if the Guest OS has two threads running on two vCPUs-one sending “Usage” commands and one sending “Destruction” commands-they ultimately funnel into the same FIFO.
The race condition requires vmsvgaR3MobDestroy to execute during the execution of vmsvgaR3MobGet. But because of the single-threaded dispatcher:
vmsvgaR3MobGet, which returns NULL because the MOB is gone. Safe.There is no preemption point inside the command handlers. The “Race” was an illusion created by looking at the code without understanding the runtime execution model.
The initial failure to detect this serialization highlights a key weakness in LLM-based auditing: Local vs. Global Context.
DevVGA-SVGA-cmd.cpp, the AI saw two functions manipulating a shared object without locks. It correctly identified a “Thread Safety Violation” pattern.DevVGA-SVGA.cpp) or that the I/O port handler enforces a global lock.It was only after we explicitly fed it the communication protocol documentation and the communicate.c POC that it could link the high-level architecture to the low-level code flaw. This reinforces the need for RAG (Retrieval-Augmented Generation) systems that can provide architectural context to code analysis agents.
The agent’s second major lead was a mathematical anomaly in the vmsvgaR3RectCopy function.
vmsvgaR3RectCopyThis function implements the SVGA_CMD_RECT_COPY command, a fundamental 2D acceleration primitive. Its purpose is to move rectangular blocks of pixels within the VRAM buffer (Video RAM). This is commonly used for:
Crucially, this function operates entirely in the Host’s address space but uses relative offsets provided by the Guest. It calculates a source address (pSrc) and a destination address (pDst) by adding Guest-provided X/Y coordinates to the base address of the VRAM allocation (pSvgaR3State->pbVRam). Because VRAM is just a linear chunk of heap memory on the Host, any copy operation that exceeds the bounds of this buffer risks reading or writing to adjacent Host memory-a classic Out-of-Bounds (OOB) access.
The vulnerable code block was intended to validate that the copy operation stays within the bounds of the Framebuffer (VRAM).
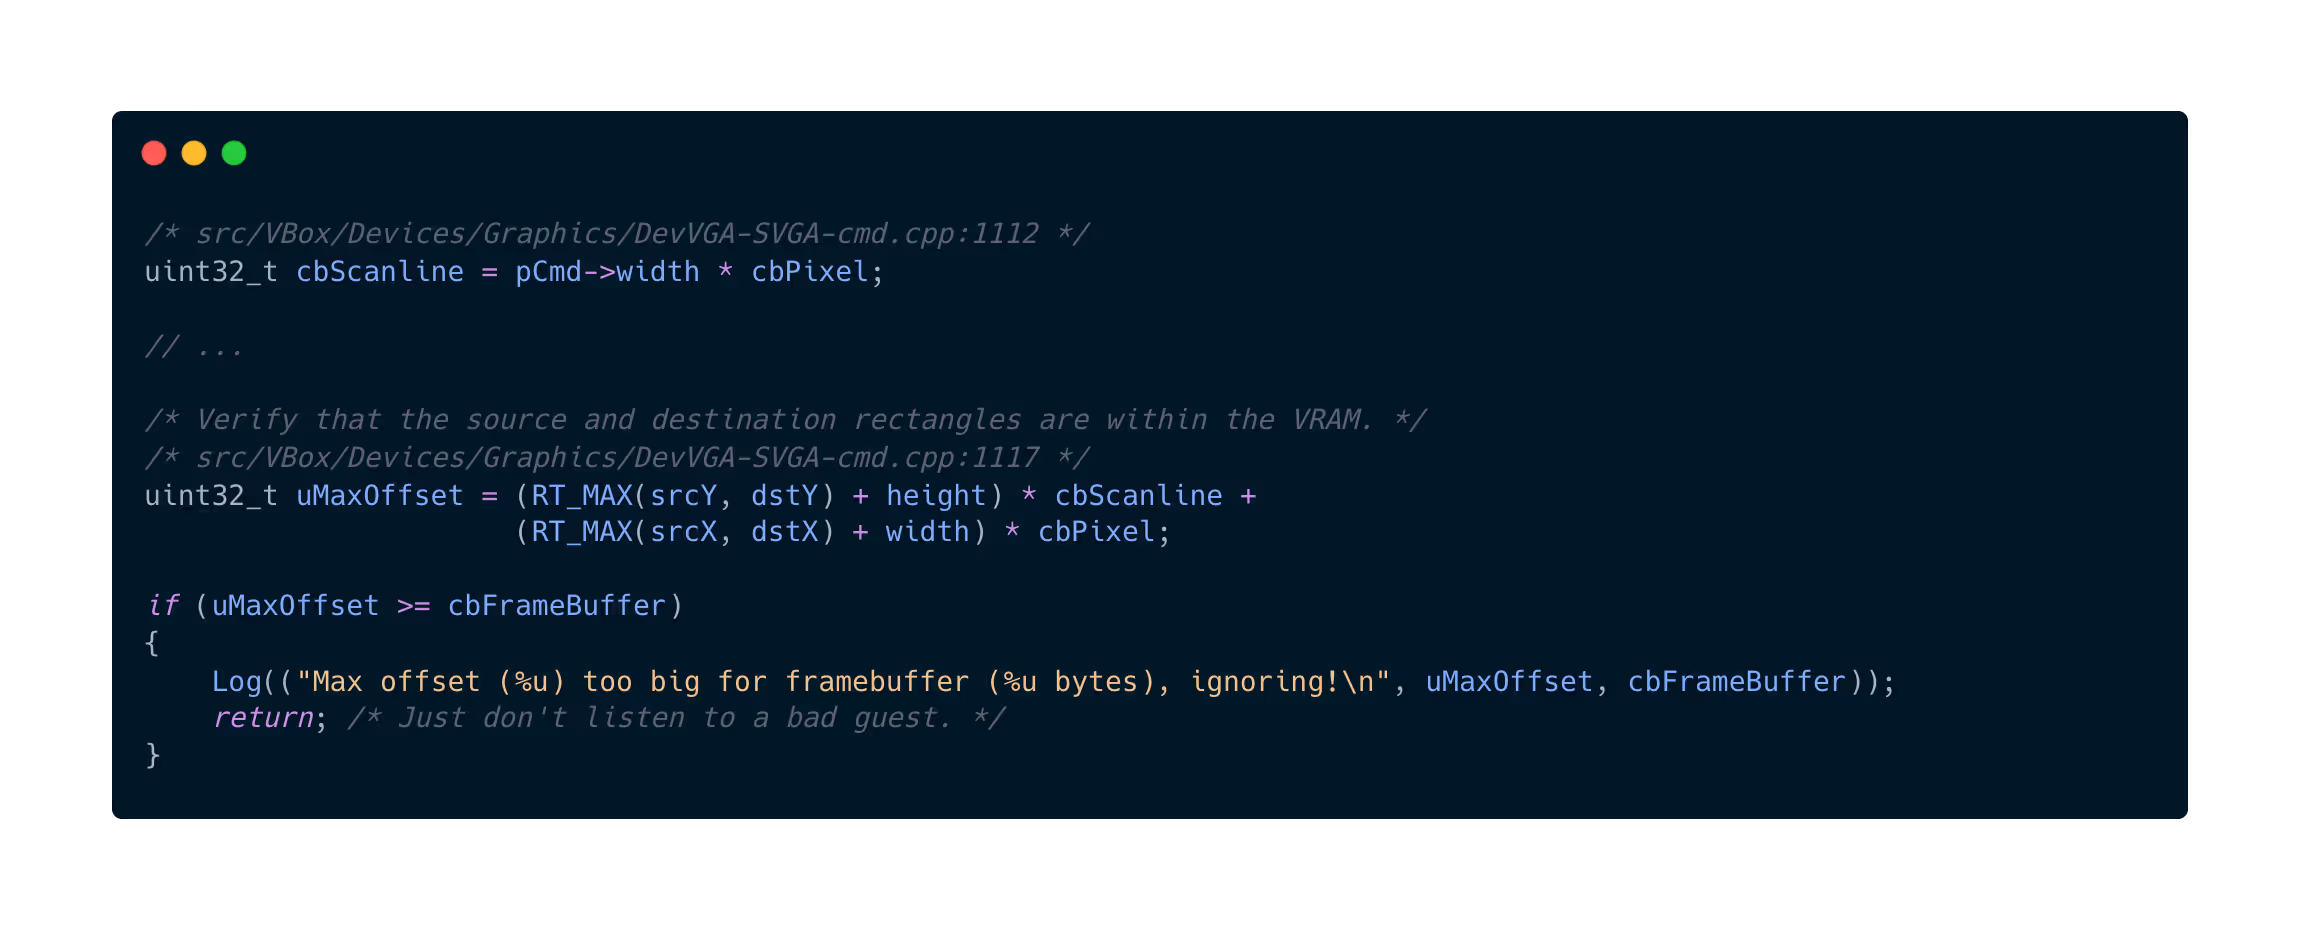
The agent identified a critical mismatch:
uMaxOffset is a uint32_t (32-bit unsigned integer).cbScanline is derived from Guest input (pCmd->width) and can be large.dstY and height are Guest-controlled 32-bit integers.The validation logic calculates the “end” of the rectangle. If a malicious guest provides values such that the multiplication overflows the 32-bit limit, the result uMaxOffset will wrap around to a small value.
The Math of the Exploit:
uMaxOffset >= cbFrameBuffer.cbFrameBuffer is typically 256MB (0x10000000).dstY = 8191 (0x1FFF)height = 1cbScanline = 1,048,576 (0x100000 - 1MB)cbPixel = 4Let’s calculate uMaxOffset:
(dstY + height) * cbScanline= (8191 + 1) * 1,048,576= 8192 * 1,048,576= 8,589,934,592
In hex, 8,589,934,592 is 0x200000000. This value is too large for a 32-bit integer (uint32_t). It wraps modulo 2^32: 0x200000000 % 0x100000000 = 0.
So, uMaxOffset becomes 0 (plus the small X-offset part). 0 < 256MB. The check passes.
The driver assumes the coordinates are valid. It then proceeds to perform a memmove using the original inputs (which are relative offsets).
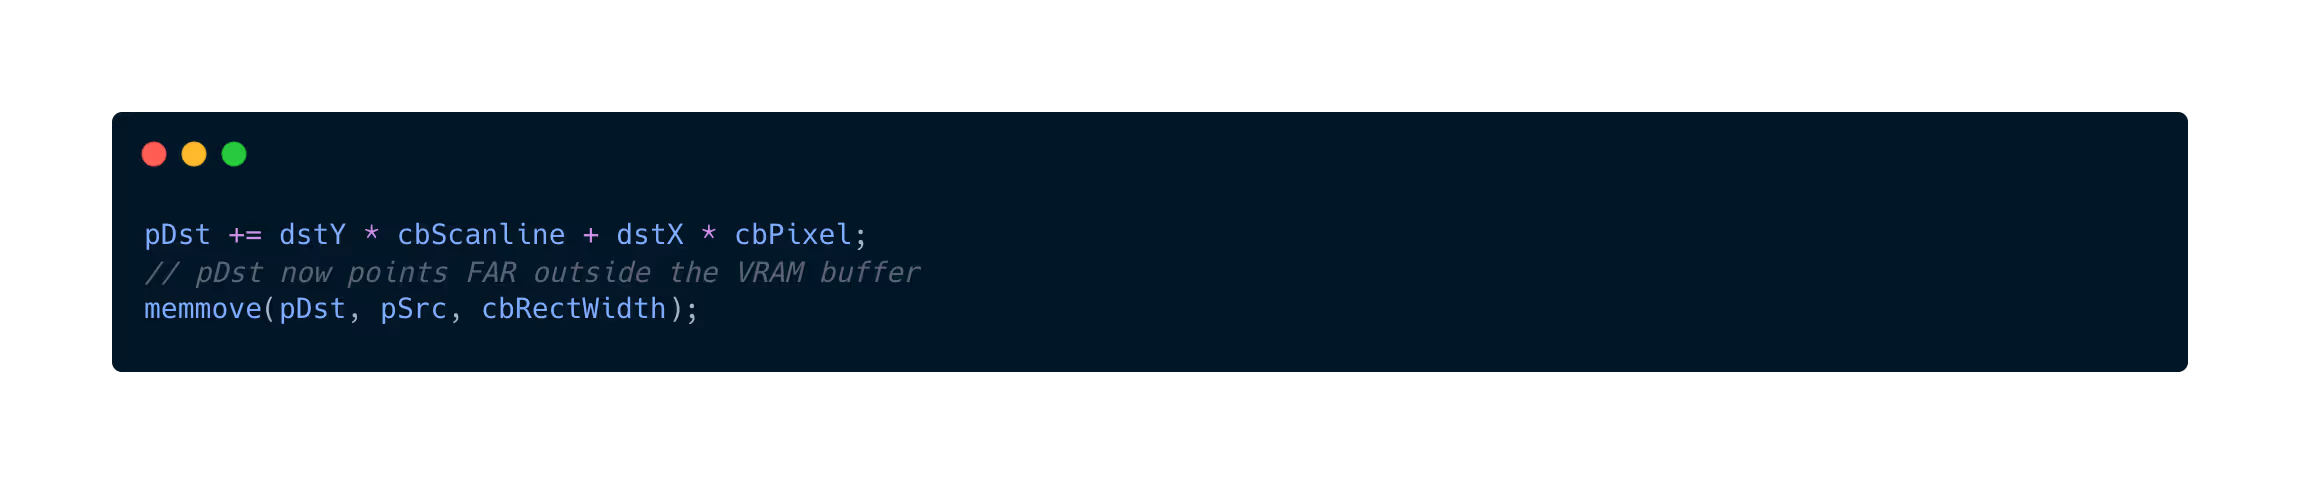
Crucially, while the validation variable uMaxOffset was explicitly typed as uint32_t (causing the wrap-around check to pass), the actual pointer arithmetic for pDst on the 64-bit Host promotes to size_t. This means the offset addition does not wrap, pointing pDst to a valid address far outside the VRAM buffer. In the VirtualBox process, the VRAM is often allocated via mmap, and directly adjacent to it are other heap allocations or loaded shared libraries.
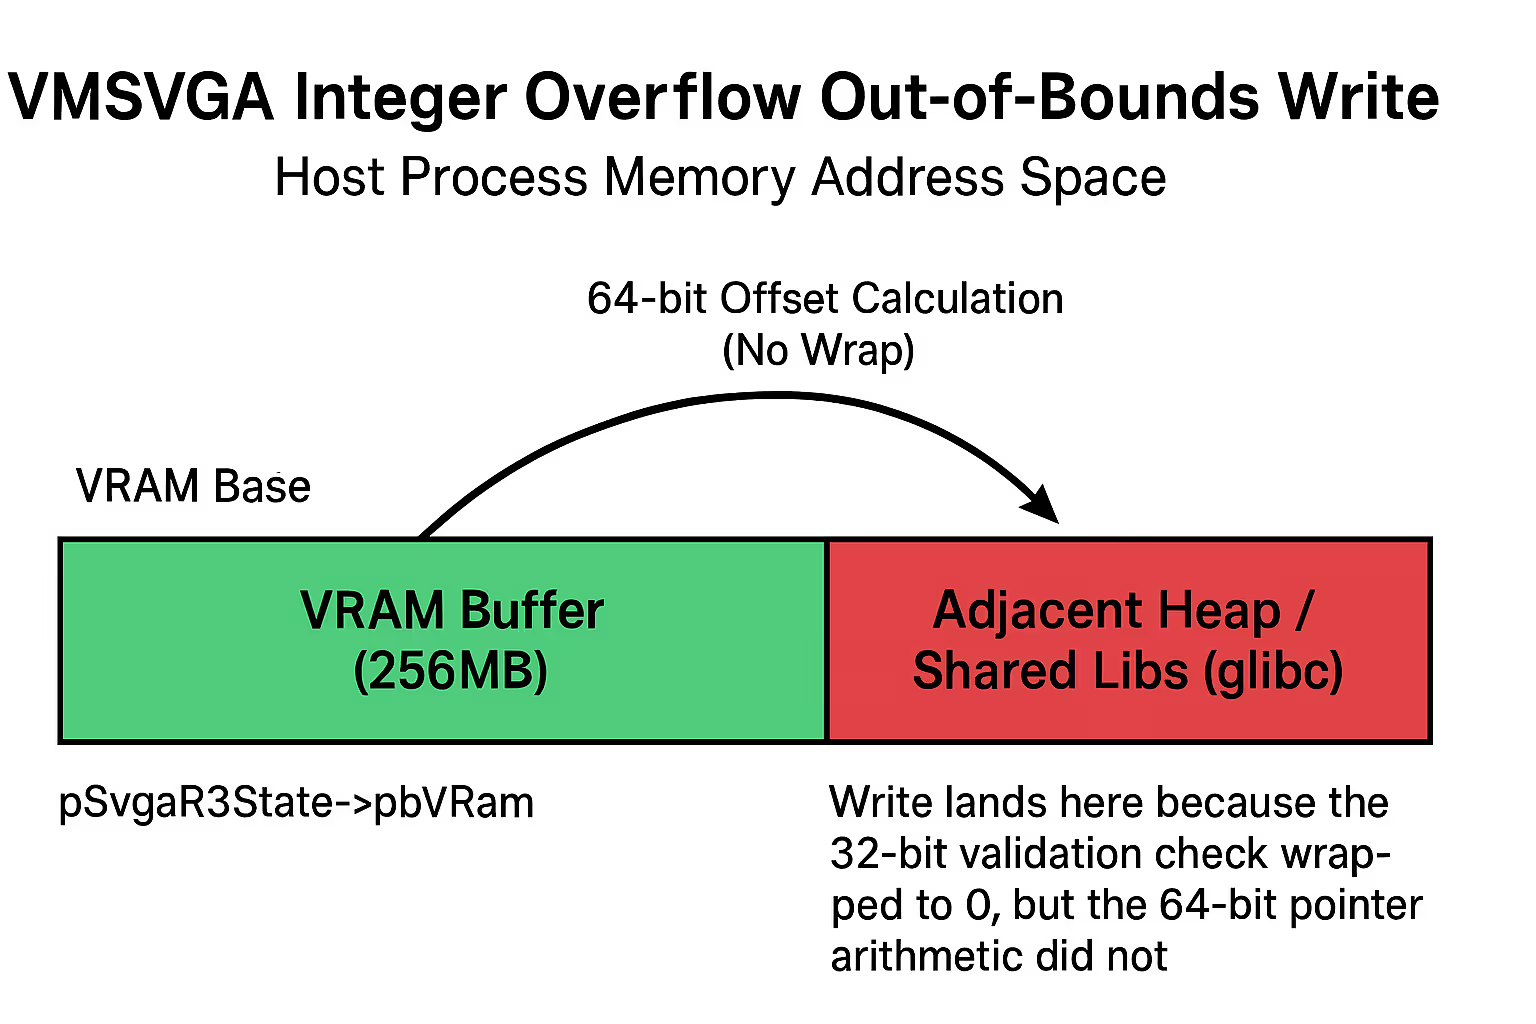
This Integer Overflow provided two powerful primitives:
srcY) to overflow, we could force the emulator to copy data from Host memory (outside VRAM) into the Guest’s VRAM. dstY), we could copy data from the Guest’s VRAM into arbitrary Host memory. Finding the bug is only half the battle. The second, often more time-consuming half is building a stable test POC to trigger it. This is where the AI agent proved to be a transformative force multiplier.
Traditionally, testing a graphics driver vulnerability requires writing a custom kernel module or a complex user-space driver to map MMIO regions, initialize the FIFO, and craft raw commands. This “setup tax” can take days of engineering before you even test your first hypothesis.
The AI Advantage:
DevVGA-SVGA.h), and it auto-generated the corresponding C structs and bitwise macros for our PoC.mmap logic, the agent generated a working user-space POC (communicate.c) using /dev/mem in under 30 minutes.This capability drastically reduced the feedback loop. We could test a hypothesis (“Does this register trigger a VM exit?”), fail, tweak the code, and retry in minutes rather than hours. The AI didn’t just find the needle; it built the magnet we used to pull it out.
Before weaponizing our primitives, we had to map the defensive landscape.
Our testing environment mimicked a rigorous, layered virtualization setup:
This “Triple Emulation” setup was crucial. It allowed us to debug the Level 1 Hypervisor (the victim) from the outside (Host Windows) while launching attacks from the inside (Level 2 Guest), simulating a real-world cloud breakout scenario.
The victim system (Ubuntu 22.04) enforces strict default protections:
randomize_va_space=2, the base addresses of the heap, stack, and shared libraries are randomized on every execution. This prevents us from hardcoding any addresses in our exploit.malloc implementations include “Safe Linking,” which XORs linked list pointers with random cookies. This effectively kills trivial heap metadata corruption attacks.Analyzing the VirtualBoxVM binary revealed a hardened target. We verified this using standard tools:
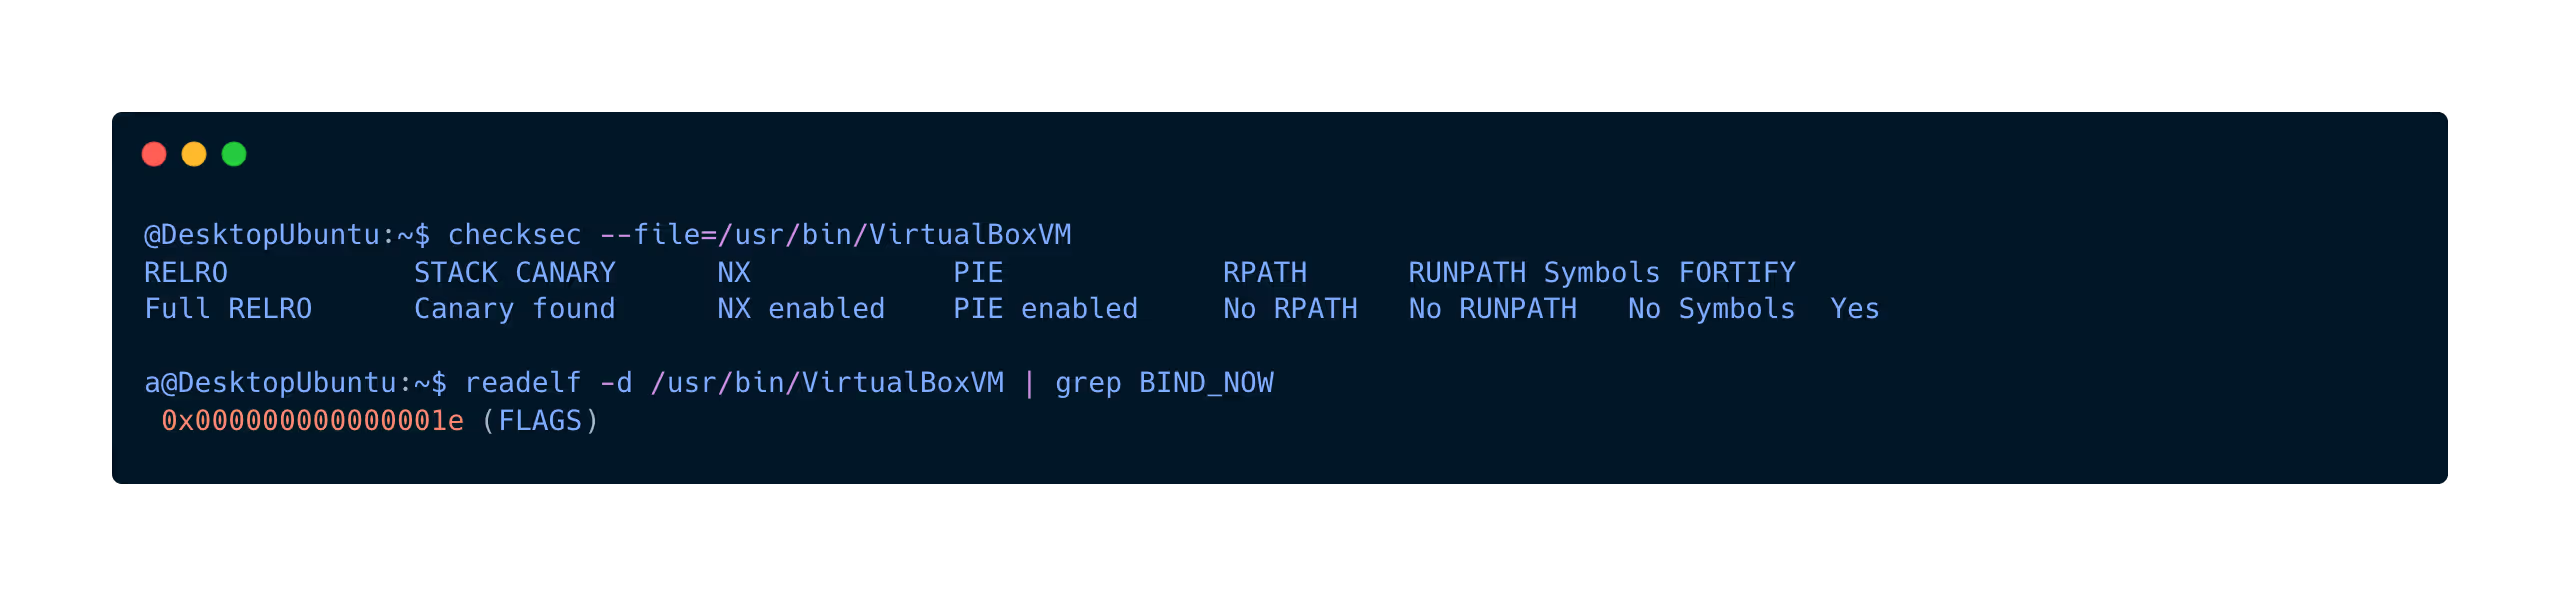
printf with system.Given these defenses, we needed a strategy to bypass ASLR and NX. We decided to chain our two primitives:
srcY) to scan the Host memory adjacent to VRAM. Our goal is to find a pointer into libc.so. Since libc is often mapped near VRAM, we can leak a valid address to defeat ASLR and calculate the base of libc.libc base, we target a specific Virtual Method Table (VTable) within libc’s writable data segment (e.g., _IO_file_jumps or similar structures used during file operations or error handling). By overwriting a function pointer in this table with the address of system or a ROP gadget, we can gain code execution.To bypass PIE, we targeted libc.so instead of the VirtualBoxVM binary. Why?
libc structures (like _IO_FILE vtables) are well-known targets.libc structure managed on the heap, we could redirect execution to a “magic gadget” ( system("/bin/sh")) once we resolved the ASLR slide via the info leak.To validate the finding, we developed rect_copy_test.c and svga_write_primitive_crash_poc.c.
1. Initialization: The PoC initializes the SVGA device and maps the FIFO command queue.
2. Setup VRAM: We define a screen with a massive pitch (1MB) to facilitate the overflow multiplication.
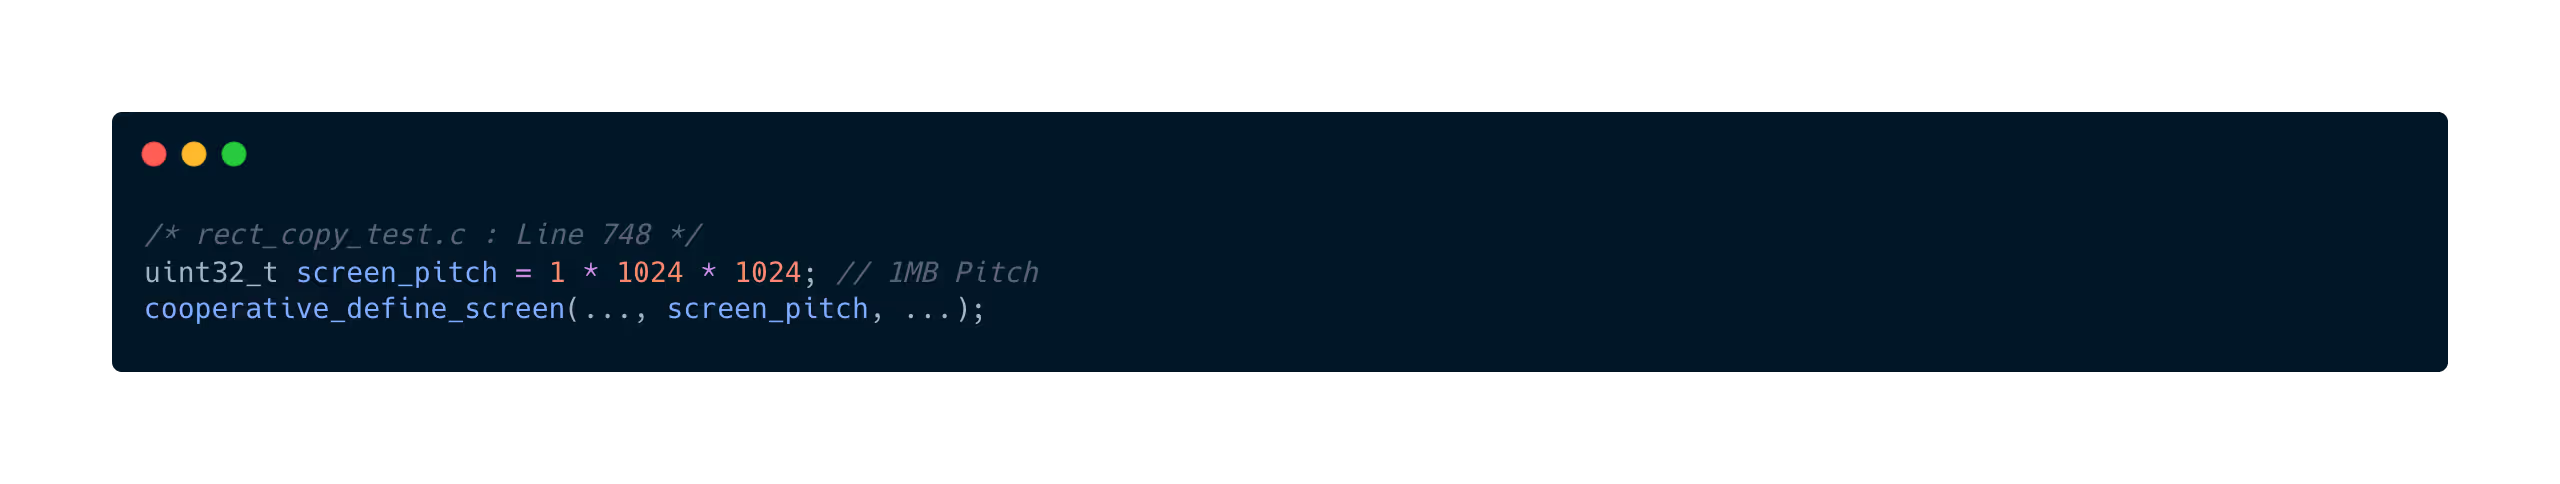
3. Heap Spray (Payload): We fill the VRAM with a recognizable pattern (0xBADC0FFE). c /
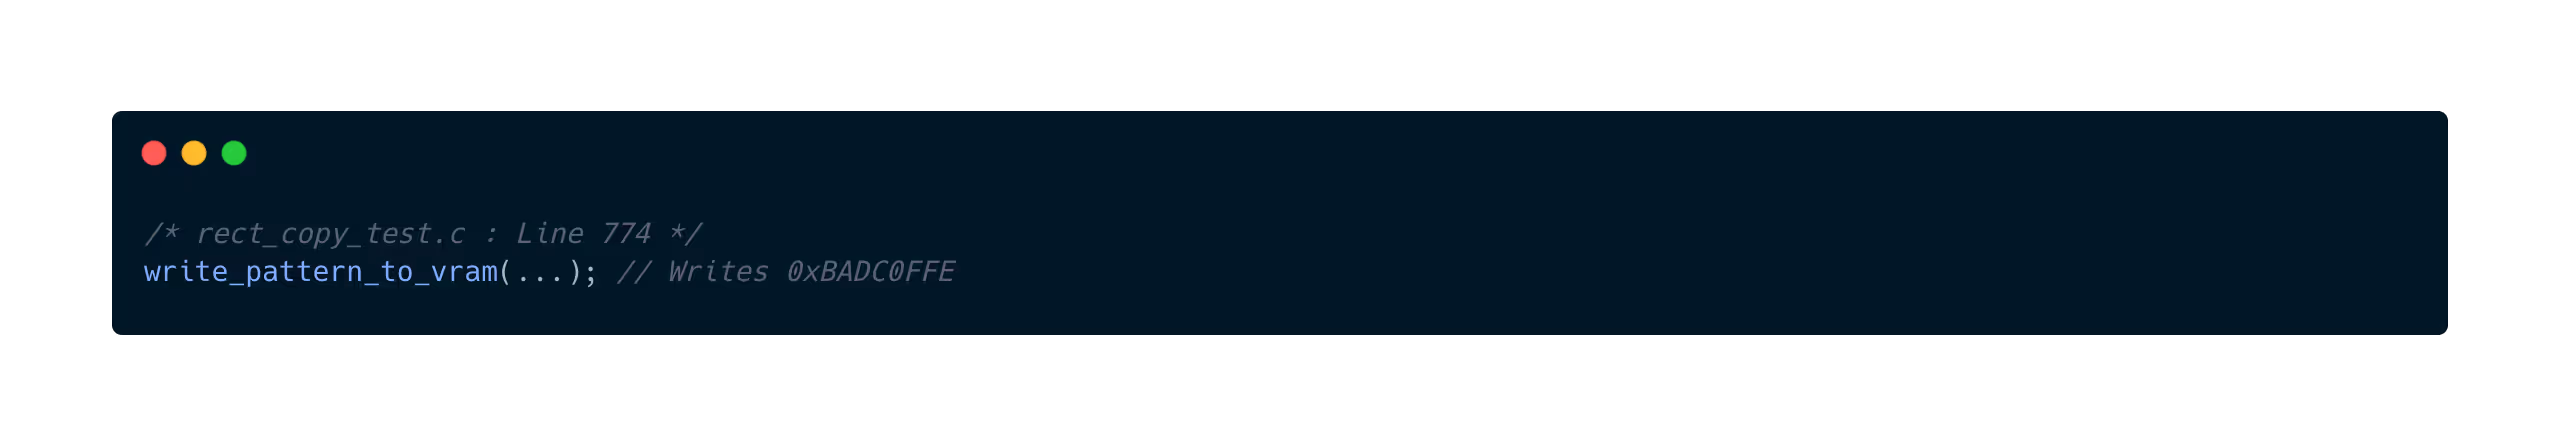
4. Trigger: We send a SVGA_CMD_RECT_COPY command with the calculated overflow parameters.
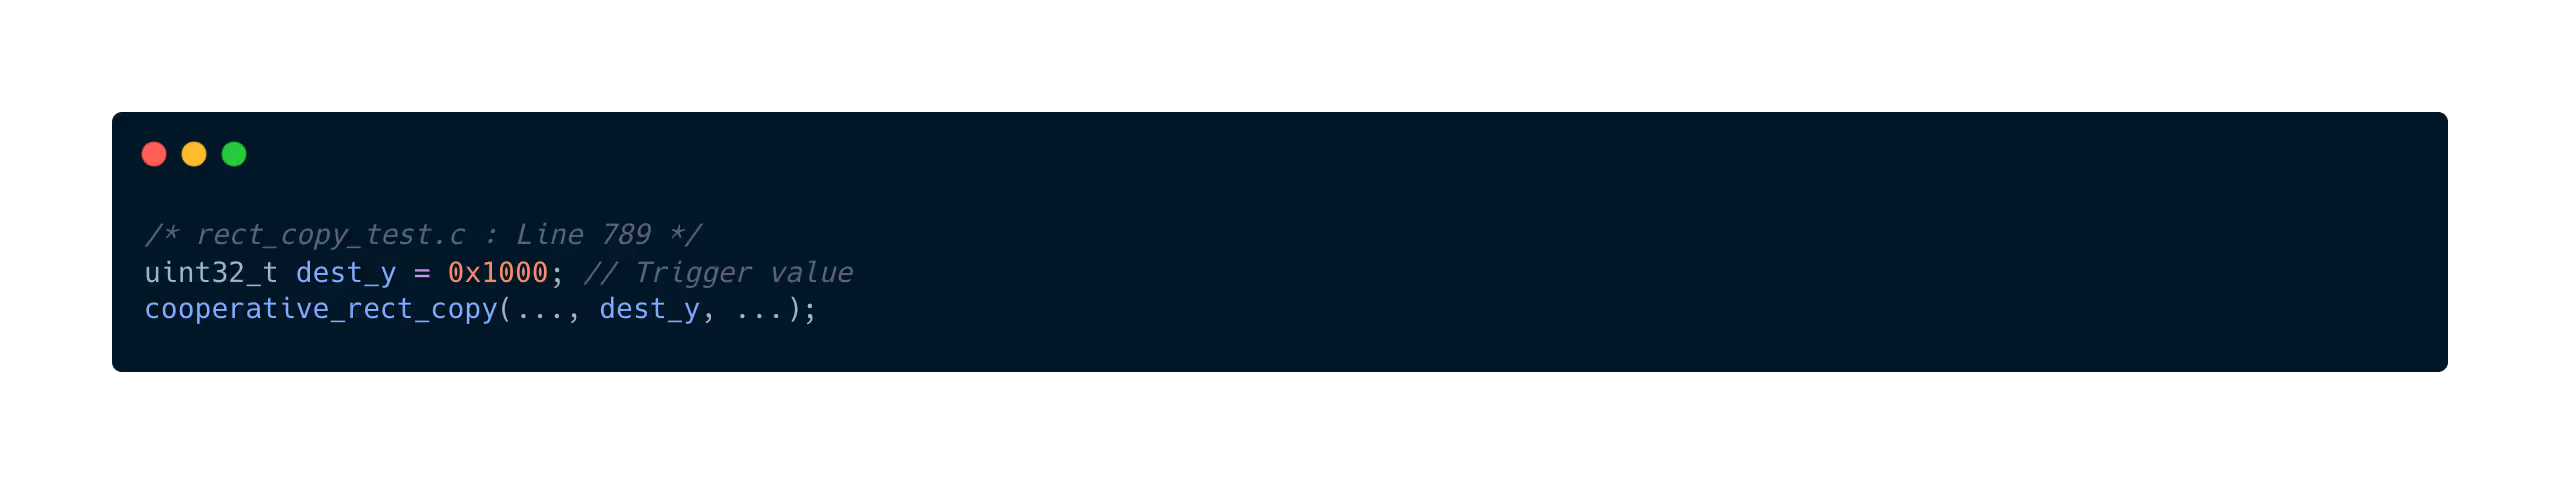
While the demo crashes the host, the weaponized exploit follows a precise sequence:
libc.so mapping in the Host’s virtual address space.vmsvgaR3RectCopy overflow with a modified srcY to perform an Out-of-Bounds Read. This isn’t a single shot; we execute this in a loop. We iteratively increment the offset to scan 4KB chunks of Host memory adjacent to our VRAM, effectively “walking” the heap.libc signatures (pointers to _IO_2_1_stderr_ or similar symbols). We repeat the read/scan loop until a valid signature is found. Once found, we calculate the exact base address of libc and the ASLR slide. dstY overflow parameters to target the _IO_file_jumps vtable (or a similar function pointer array) inside the writable data segment of the now-located libc. __overflow or __xsputn function pointer with the address of system().libc to use the corrupted structure (e.g., by triggering an error log on the Host), causing it to jump to system("/bin/sh") instead of printing an error message.When the PoC runs in the Guest VM:
vmsvgaR3RectCopy calculates the bounds. The 32-bit integer wraps to 0. validation passes.memmove is called. The destination pointer is calculated relative to the VRAM base: VRAM_BASE + (0x1000 * 0x100000).0x10000000 = 256MB) is exactly the size of the VRAM. The write lands immediately after the VRAM buffer.In our video artifact (VBoxGuestToHostWritePrimitiveCrash.mp4), the execution of the PoC leads to an immediate “Guru Meditation” or full process crash of the VirtualBox GUI, confirming the write primitive. Debugging the core dump showed our 0xBADC0FFE pattern present in the registers and memory at the crash site.
We compiled our findings into a detailed technical advisory, which we submitted to Oracle.
The response confirmed the validity of the vulnerability. It was identified as a duplicate of an issue reported shortly before our submission (assigned CVE-2025-53024) and was patched in VirtualBox 7.2.0_RC1. The patch introduced size64_t (64-bit integers) for the bounds calculation, preventing the wrap-around.
The AI-augmented workflow did not replace the researcher. It failed to understand threading contexts (the UAF rabbit hole) and required human validation to confirm the exploitability of the overflow.
However, it significantly optimized the process:
(A+B)*C that is notoriously difficult for humans to spot during a quick skim, especially when variable types are implicit.This research demonstrates that while AI cannot run on “autopilot,” a customized, persona-driven AI agent acts as a powerful force multiplier. It doesn’t just “find bugs”; it generates high-quality hypotheses that a skilled researcher can then verify and weaponize.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。