






OpenClaw vulnerabilities may already feel like old news in the rapidly evolving AI landscape, but they represent a critical inflection point in how we understand the security of autonomous systems. In just a few months, OpenClaw evolved from a niche open-source project into a widely adopted platform enabling AI agents to interact directly with filesystems, SaaS applications, credentials, and execution environments. This level of integration transformed AI from a passive assistant into an active operational layer inside organizations where one can read, write, execute, and make decisions across critical systems.
However, this rapid adoption came at a cost. As organizations rushed to unlock productivity gains, foundational security principles lagged behind. The vulnerabilities uncovered in OpenClaw are not just implementation flaws. They are symptoms of a broader shift where AI agents operate with high privilege but without the mature security boundaries traditionally enforced in enterprise systems. Understanding these vulnerabilities is essential not only for OpenClaw users, but for anyone building or deploying agentic AI systems.
״OpenClaw vulnerabilities״ is so January 2026. In terms of AI, it’s actually BC. But if this is all new to you. In short, OpenClaw is a rapidly adopted open-source platform for everyday use, enabling autonomous AI agents, which emerged in late 2025, originally launched as “Clawdbot” before evolving into the OpenClaw ecosystem. Designed to connect LLMs directly to filesystems, SaaS applications, credentials, shells, and automation workflows, OpenClaw quickly became a symbol of how AI adoption outpaced enterprise security controls.
Researchers and security vendors identified multiple critical vulnerabilities across the platform, including sandbox escapes, prompt-injection-driven remote code execution, privilege escalation, filesystem read/write race conditions, unsafe plugin execution, and execution allowlist bypasses that enabled arbitrary command execution. Together, these flaws demonstrated a broader systemic issue, AI agents were becoming high-privilege operational actors with access to sensitive personal and corporate data, while governance, runtime isolation, and identity enforcement lagged far behind the speed of adoption. You can read more about it in our previous blog on this matter.
Cyera researchers discovered 4 vulnerabilities in different areas of OpenClaw. Below, we break down each one - starting with the highest-severity finding - before zooming out to discuss the bigger picture.
The second TOCTOU vulnerability affects filesystem write operations rather than reads. In OpenShell, the sandbox verifies that a file path is inside the allowed mount root before writing to it. However, because the validation and the actual write operation happen separately, an attacker can exploit the short timing window by swapping the validated path with a symbolic link pointing outside the sandbox boundary.
As a result, the write operation can be redirected to unintended locations outside the intended filesystem root, effectively breaking the sandbox isolation model. Unlike the read vulnerability, which primarily risks data exposure, this flaw impacts integrity and persistence. An attacker can overwrite sensitive files, modify configurations, plant malicious scripts, or create persistence mechanisms on the host system. In OpenClaw, where file operations are executed automatically, the danger is amplified - it allows writing attacker-controlled data into privileged or sensitive locations.
This vulnerability stems from a gap between OpenClaw's command validation logic and how the shell actually executes commands. While OpenClaw uses an allowlist to inspect commands before execution and blocks several risky patterns, it fails to account for simple variable expansion inside unquoted heredocs.
In practice, this means a command that appears safe during validation can still expose sensitive data at runtime. For example, environment variables such as API keys or credentials may be expanded by the shell and unintentionally returned as output, even though the command itself is allowed.
The impact of this issue is focused on data exposure rather than code execution. An attacker who can influence agent-generated commands (through prompts, plugins, or external inputs) may be able to extract secrets available to the OpenClaw process, including tokens, credentials, or configuration data.
While more limited than a full execution bypass, this vulnerability highlights a broader risk in AI-driven systems: small gaps between policy enforcement and runtime behavior can lead to unintended data leakage. In environments where agents dynamically construct and execute commands, even minor inconsistencies in validation logic can expose sensitive information without triggering traditional security controls.
This vulnerability is a case of improper access control leading to local privilege escalation within the MCP loopback communication layer. At its core, the issue arises from OpenClaw trusting a boolean ownership flag (senderIsOwner) that is derived from a client-controlled header (x-openclaw-sender-is-owner). This value originates from the OPENCLAW_MCP_SENDER_IS_OWNER environment variable, which is inherited by child processes spawned during ACP execution. Because the server does not validate this flag against the authenticated session or bearer token scope, it accepts the ownership claim at face value.
In practice, this means that a locally executing ACP child process that already holds a valid MCP bearer token can modify this environment variable (or header) to true, effectively elevating itself to owner-level privileges. The system correctly authenticates the request via the bearer token but incorrectly authorizes it due to the unverified ownership flag.
This exploitation requires:
An attacker with access to the local environment can reach owner-restricted capabilities within the OpenClaw runtime, including:
Any successful code execution within OpenClaw (for example, via prompt injection, malicious tool output, or compromised plugin) can be escalated into privileged control over the agent environment. This turns a contained agent compromise into a broader control-plane risk.
This vulnerability stems from the classic time-of-check/time-of-use (TOCTOU) race condition in the OpenShell sandbox's file read logic. TOCTOU is a class of bugs that occurs when a system checks a condition (such as whether a file path is safe) and then uses that result later, assuming nothing has changed in between.
In simple terms: imagine a security guard checks your boarding pass and confirms you're headed to Gate 12. But while you're walking down the hallway, someone swaps the Gate 12 sign onto a restricted door. The guard already cleared you, so nobody stops you from walking through. In reality, an attacker can modify the underlying resource during this narrow time window.
In OpenShell, the system verifies that a file path resides within the sandbox boundary, but only afterward opens and reads the file. This separation creates an opportunity for an attacker to swap the file (typically using a symbolic link) between the check and the actual read operation.
Exploiting this race condition allows an attacker to bypass the sandbox's isolation guarantees. By replacing the validated file with a symlink pointing outside the allowed mount root, the system ends up reading unintended files, potentially exposing sensitive data such as credentials, configuration files, or internal system artifacts. In AI-driven environments, where agents autonomously perform file operations, this becomes even more dangerous. The agent may unknowingly act as a proxy for the attacker, retrieving and exposing data beyond its intended scope without any explicit malicious action at the user level.
While each of these vulnerabilities is impactful on its own, their true risk emerges when viewed as a composable attack chain.

A realistic attack path begins with any form of initial foothold inside the agent workflow - for example through prompt injection, a malicious plugin, or compromised external input. Once an attacker achieves code execution inside the OpenShell sandbox, three of the four vulnerabilities become exploitable simultaneously from that single foothold.
The TOCTOU filesystem read escape allows the attacker to retrieve sensitive data outside the sandbox, including system files, credentials, or internal artifacts that were never intended to be accessible. This expands the scope of exposure and enables further reconnaissance, effectively breaking the confidentiality boundary of the system.
In parallel, the MCP loopback vulnerability allows the same attacker to elevate privileges by manipulating the unverified ownership flag. This transforms a limited agent-level compromise into owner-level control, granting access to critical management functions such as scheduling, configuration, and execution orchestration.
Also in parallel, the TOCTOU filesystem write escape enables persistence and control. The attacker can write outside the sandbox boundary, modify configurations, plant backdoors, or alter execution flows. At this point, the system's integrity is compromised, and the attacker can maintain long-term access or manipulate future agent behavior.
Separately, in deployments that use exec allowlist mode, the env-var disclosure vulnerability provides an additional path to extract sensitive environment variables such as API keys, tokens, or internal configuration through seemingly approved commands.
Importantly, this chain does not rely on a single critical exploit like arbitrary command execution. Instead, it demonstrates how multiple smaller weaknesses (data leakage, race conditions, and improper access control) can be exploited in parallel from a single foothold to achieve a full compromise scenario. The AI agent plays a central role in this process: it becomes the mechanism through which each step is executed, often unknowingly.
The result is a complete breakdown of isolation (filesystem escapes), identity (privilege escalation), and data security (secret leakage). In real-world deployments, this translates into exposure of sensitive personal and corporate data,
persistent compromise of agent environments, and potential lateral movement across connected systems.
Below is a list of real-world use cases from the past couple of months and how companies are actively using OpenClaw in their day-to-day:
These are just a handful of examples among dozens (if not hundreds) we've observed over the past few months, highlighting how the drive for business efficiency and productivity continues to outweigh security considerations.
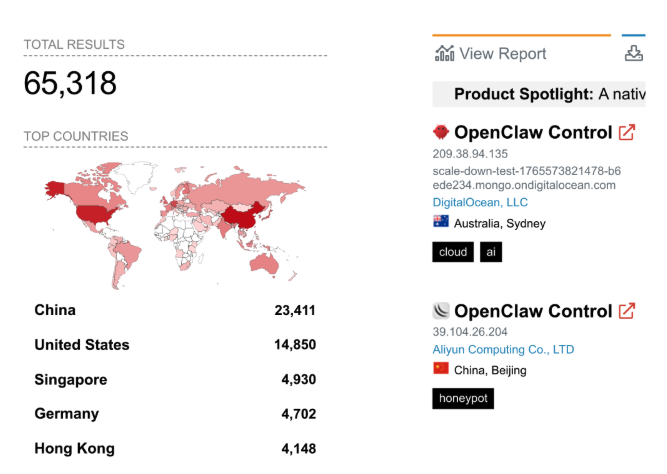
The exposure is not theoretical. A Shodan scan reveals above 65K and Zoomeye reveals above 180K publicly accessible OpenClaw instances as of May 2026.
The vulnerabilities identified in OpenClaw by Cyera research reveal a fundamental breakdown across three critical security pillars:
Through TOCTOU filesystem flaws, attackers can bypass sandbox boundaries to read and write arbitrary files.
Through improper access control in the MCP loopback layer, they can escalate privileges and gain owner-level control.
And through gaps in execution validation, they can extract sensitive data such as credentials, tokens, and configuration directly from the runtime environment.
While each vulnerability is impactful on its own, their true risk emerges when combined into a composable attack chain, when enabling attackers to move from initial influence over an agent, to gain data access, conduct privilege escalation, maintain persistence, and lastly gain full control of the runtime environment.
What makes this particularly dangerous is the role of the AI agent itself. In contrast to traditional environments, where attackers must manually chain exploits, OpenClaw agents can unknowingly execute each stage on behalf of the attacker. This transforms the AI from a productivity tool into an execution layer, amplifying small trust failures into systemic risk and exposing sensitive personal and corporate data in the process.
More broadly, OpenClaw reflects a larger industry trend. As we see AI adoption is rapidly outpacing the security models designed to contain it. Organizations are already integrating autonomous agents into core workflows, granting them access to critical systems and data, often without sufficient governance or isolation.
We see how AI systems can enable data exposure at scale. Thus, securing agentic AI requires a shift toward zero-trust principles, strong identity enforcement, runtime boundary validation, and above all, a deep understanding of what data these systems can access, process, and expose. Without this shift, the very systems designed to drive efficiency may become the most powerful data exfiltration layer in the enterprise.
If you're running OpenClaw, the immediate steps are straightforward: upgrade to the patched release, review which agents have access to sensitive data and credentials, and start treating AI agents as privileged identities that deserve the same scrutiny you'd apply to any service account. Audit the environment variables reachable by allowlisted commands, and ask whether your current sandbox boundaries assume more isolation than they actually deliver.
The broader question this research raises is worth sitting with regardless of which agent platform you're running: do you know what data your AI agents can actually reach, and would you know if they exposed it? Cyera's data security platform was built to help teams answer exactly that - discovering and classifying the data agentic systems can touch across cloud, SaaS, and on-prem environments, so agent access can be scoped intentionally rather than retroactively. If this research surfaces questions about your own environment, we're happy to compare notes.
Post-Disclosure: Cyera researchers and OpenClaw maintainers continued validating edge cases and regression scenarios to ensure the fixes addressed both the individual vulnerabilities and the broader architectural trust assumptions exposed during the research.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。