








Uncategorized 3 Minutes
Authors: Axel Boesenach and Erik Schamper
In this blog post we will go into a user-friendly memory scanning Python library that was created out of the necessity of having more control during memory scanning. We will give an overview of how this library works, share the thought process and the why’s. This blog post will not cover the inner workings of the memory management of the respective platforms.
Memory scanning is the practice of iterating over the different processes running on a computer system and searching through their memory regions for a specific pattern. There can be a myriad of reasons to scan the memory of certain processes. The most common use cases are probably credential access (accessing the memory of the lsass.exe process for example), scanning for possible traces of malware and implants or recovery of interesting data, such as cryptographic material.
If time is as valuable to you as it is to us at Fox-IT, you probably noticed that performing a full memory scan looking for a pattern is a very time-consuming process, to say the least.
Why is scanning memory so time consuming when you know what you are looking for, and more importantly; how can this scanning process be sped up? While looking into different detection techniques to identify running Cobalt Strike beacons, we noticed something we could easily filter on, speeding up our scanning processes: memory attributes.
Speed up scanning with memory attributes
Memory attributes are comparable to the permission system we all know and love on our regular file and directory structures. The permission system dictates what kind of actions are allowed within a specific memory region and can be changed to different sets of attributes by their respective API calls.
The following memory attributes exist on both the Windows and UNIX platforms:
- Read (R)
- Write

- Execute (E)
The Windows platform has some extra permission attributes, plus quite an extensive list of allocation1 and protection2 attributes. These attributes can also be used to filter when looking for specific patterns within memory regions but are not important to go into right now.
So how do we leverage this information about attributes to speed up our scanning processes? It turns out that by filtering the regions to scan based on the memory attributes set for the regions, we can speed up our scanning process tremendously before even starting to look for our specified patterns.
Say for example we are looking for a specific byte pattern of an implant that is present in a certain memory region of a running process on the Windows platform. We already know what pattern we are looking for and we also know that the memory regions used by this specific implant are always set to:
| Type | Protection | Initial |
|---|---|---|
| PRV | ERW | ERW |
Depending on what is running on the system, filtering on the above memory attributes already rules out a large portion of memory regions for most running processes on a Windows system.
If we take a notepad.exe process as an example, we can see that the different sections of the executable have their respective rights. The .text section of an executable contains executable code and is thus marked with the E permission as its protection:
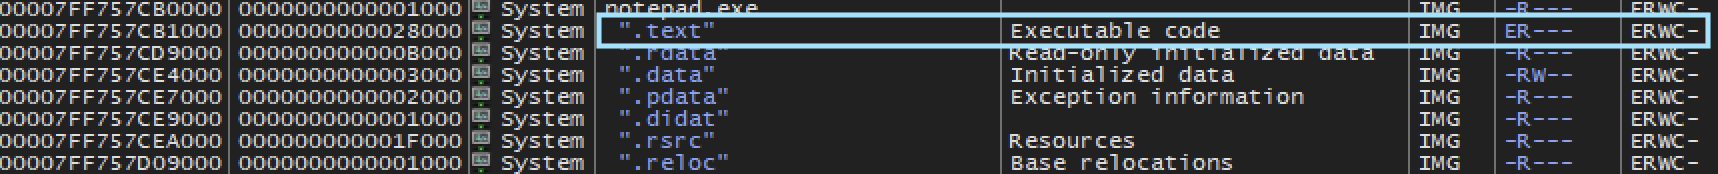
If we were looking for just the sections and regions that are marked as being executable, we would only need to scan the .text section of the notepad.exe process. If we scan all the regions of every running process on the system, disregarding the memory attributes which are set, scanning for a pattern will take quite a bit longer.
Introducing Skrapa
We’ve incorporated the techniques described above into an easy to install Python package. The package is designed and tested to work on Linux and Microsoft Windows systems. Some of the notable features include:
- Configurable scanning:
- Scan all the process memory, specific processes by name or process identifier.
- Regex and YARA support.
- Support for user callback functions, define custom functions that execute routines when user specified conditions are met.
- Easy to incorporate in bigger projects and scripts due to easy to use API.
The package was designed to be easily extensible by the end users, providing an API that can be leveraged to perform more.
Where to find Skrapa?
The Python library is available on our GitHub, together with some examples showing scenarios on how to use it.
GitHub: https://github.com/fox-it/skrapa
References