











Rejourney.co has scaled to over 1.3 MILLION session replays from app developers over the world.
Rejourney is an alternative to sentry.io and posthog.com for indie React Native developers.
Quick growth for any startup is hard. However, the difficulty is far greater when your startup handles hundreds to thousands of small files ingested every minute. Every startup dreams of that "hockey stick" moment, but as we recently learned at Rejourney, the infrastructure that supports 10,000 sessions a day doesn't always handle 100,000 with the same grace.
Last month, we officially onboarded new customers with expansive user bases across several high-traffic mobile apps. It was a milestone for our team, but it also quickly became an "all-hands-on-deck" engineering challenge.
The "Accidental" DDoS
The trouble started almost immediately after they loaded Rejourney live on their apps. Within minutes, our ingestion metrics spiked by an order of magnitude.
At the edge, Cloudflare’s automated security systems saw this sudden, massive influx of traffic to our API and did exactly what they were programmed to do: they flagged it as a Distributed Denial of Service (DDoS) attack. Legitimate session data from thousands of users was being dropped before it even reached our infrastructure.
Our immediate fix was to implement a bypass filter for our specific API endpoint. We wanted to ensure no data was lost and that the onboarding experience was seamless. We flipped the switch, the "Attack Mode" subsided, and the floodgates opened.
Thundering Herd
Opening the floodgates is only a good idea if your reservoir can handle the volume. By bypassing the edge protection, we redirected the full, unthrottled weight of the traffic directly to our origin server.
At the time, our backend was running on a single-node K3s cluster. While we’ve optimized our ingestion pipeline to be lean, no single node is immune to a "thundering herd." As thousands of concurrent connections hit our API, our Ingest Pods were pinned at Max CPU, and the server eventually became unresponsive.
We realized that scaling "up" (getting a bigger VPS) was no longer enough. We needed to scale "out."
Decomposing the Ingestion Pipeline
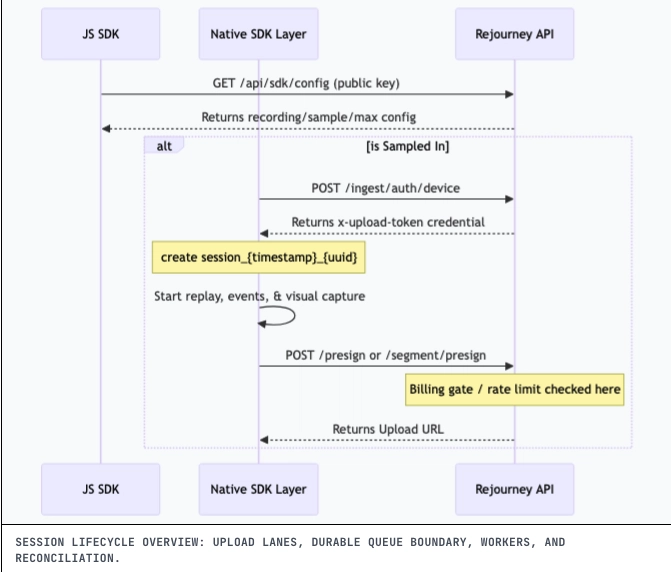
Session lifecycle architecture from SDK start through upload lanes, workers, and reconciliation
Session lifecycle overview: upload lanes, durable queue boundary, workers, and reconciliation.
The biggest bottleneck in our old setup was the "monolithic" nature of ingestion. If a pod restarted, in-memory tasks were lost. We’ve now decomposed the pipeline into five specialized, durable stages:
The Control Plane (API): Our API pods now focus exclusively on the "handshake." When the SDK calls our endpoints, we immediately create durable rows in Postgres (via PgBouncer) to track the session and ingest jobs.
The Upload Relay: We isolated heavy client upload traffic into its own ingest-upload layer. These pods act as a relay to Hetzner S3, ensuring that a flood of incoming bytes doesn't starve our core API of resources.
The Durable Queue Boundary: We moved away from in-memory task management. Work is now represented as durable rows in Postgres. If a worker pod crashes or restarts, the job still exists in the database, waiting to be claimed.
Specialized Worker Deployments: We split our processing power. ingest-workers handle lightweight metadata like events and crashes, while replay-workers tackle the heavy lifting of screenshots and hierarchies.
Self-Healing Reconciliation: A dedicated session-lifecycle-worker performs periodic sweeps to recover stuck states or abandon expired artifacts.
By using Postgres as the source of truth for state and S3 for storage, our system is now remarkably resilient. Even if Redis or individual pods face transient issues, the state survives and processing resumes exactly where it left off.
High-Availability Postgres and Redis
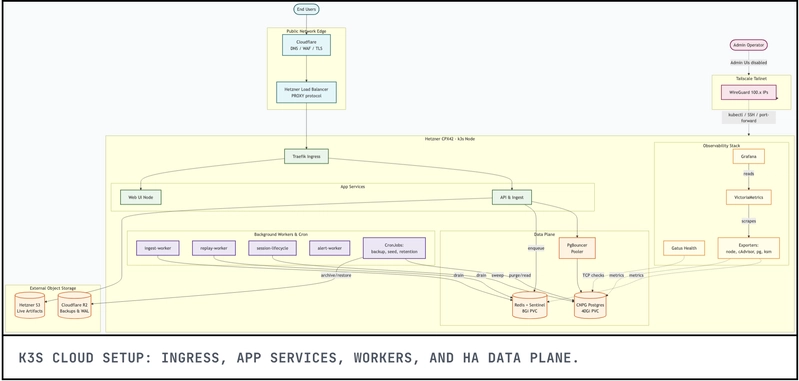
We’ve moved away from the single-node bottleneck to a High Availability configuration. We now run HA Postgres and Redis with automated failover. If a VPS goes down, the databases automatically fall back to a replica. The platform keeps moving, and the data stays safe.
K3s cloud setup showing ingress, API, workers, and data services
K3s cloud setup: ingress, app services, workers, and HA data plane.
Before
Single-node Postgres and Redis tied to one VPS.
Infrastructure maintenance had direct outage risk.
No automated failover path during node loss.
After
HA Postgres and Redis replicated across nodes.
Automated failover promotes healthy replicas quickly.
Platform continuity during host-level interruptions.
Navigating the 50 Million Object Limit
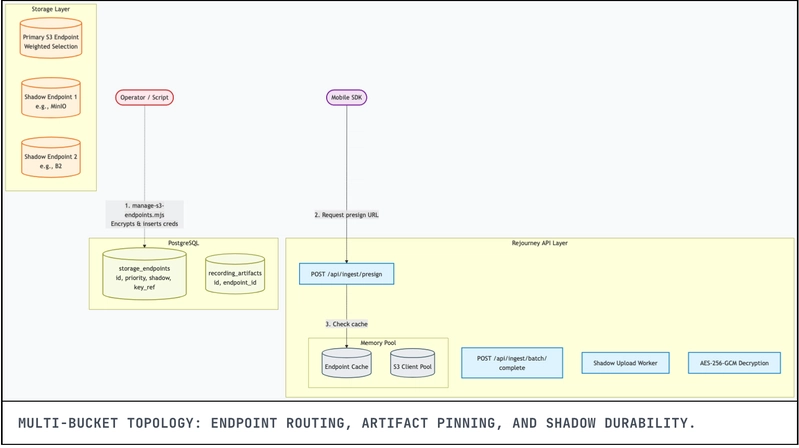
As we scaled, we hit a literal physical limit: providers like Hetzner often impose a 50-million-object limit per bucket. To bypass this, we implemented a dynamic multi-bucket topology.
Instead of hard-coding storage locations in environment variables, we moved the source of truth to a storage_endpoints table in Postgres. This allows us to manage storage with extreme granularity:
Multi-bucket topology with endpoint resolution, artifact pinning, and shadow replication
Multi-bucket topology: endpoint routing, artifact pinning, and shadow durability.
Weighted Traffic Splitting: We can resolve active buckets and perform weighted random selection to balance load across providers.
Artifact Pinning: To avoid "File Not Found" errors during migrations, we store the specific endpoint_id on every artifact. This "pins" future reads to the correct bucket, even as global defaults change.
Shadow Copies for Durability: We implemented a "Shadow" role. Once a primary write succeeds, we fan out asynchronous writes to shadow targets for extra redundancy.
Efficiency at Scale
Despite the intensity of the traffic spike, we managed to implement these changes with less than five minutes of total downtime.
This incident reinforced why we focus so much on performance. Our lightweight SDK ensures we aren't taxing the user’s device, while our new HA infrastructure ensures we can handle whatever volume the next "hockey stick" growth moment throws at us.
We’re now back to 100% stability, with a much larger "reservoir" ready for the next wave of growth. If you’ve been looking for a session replay tool that respects your app’s performance as much as you do, we’re more ready for you than ever.
Rollout Timeline
Detected false-positive edge protection and restored trusted API traffic.
Isolated upload traffic and shifted orchestration state to durable Postgres rows.
Split workers by workload, then added reconciliation for crash-safe recovery.
Enabled HA Postgres + Redis and finalized multi-bucket endpoint routing.