





A short field report on what current AI detectors actually do when you point them at frontier reasoning model output, and what I changed in my own detection workflow.
I integrate AI detection into a few small side projects—content moderation pre-filters, writing quality flags, etc. The more I relied on detection, the more concerned I became that I was trusting numbers based on stale benchmarks.
This week, a benchmark study confirmed my worst fears. It tested two popular detectors against 47 essays generated by Kimi K2 in "thinking mode," which mimics modern, high-variance LLM output.
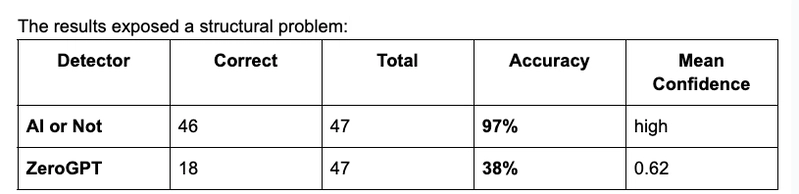
ZeroGPT missed 62% of the AI content. For context, the same study notes that ZeroGPT classifies the 1776 U.S. Declaration of Independence as 99% AI-generated. If a detector flags famously human text as AI, the false-positive ceiling is high enough to invalidate its positives on actual AI text.Why Legacy Detection Fails Modern LLMs
If you've shipped AI detection, you probably integrated it once, picked a confidence threshold, and considered the job done. This is the failure mode the benchmark exposes: Detector accuracy is not stable across model generations.
Most public detectors were built around three assumptions about older LLM output:
Low perplexity: Text is predictable and falls below a certain perplexity score $\rightarrow$ Flag as AI.
Uniform structure (Low Burstiness): Sentences have low variance in length and structure $\rightarrow$ Flag as AI.
Predictable features: Use of function-word patterns and standard transition phrases $\rightarrow$ Flag as AI.
Reasoning models like Kimi K2, Gemini 2.5 Pro, and GPT-5 break all three:
- Output is contextually adaptive, meaning perplexity varies wildly within a single response.
- Sentence variance increases during exploratory "thinking" passages.
- Token distributions are deliberately broadened to mimic human reasoning rhythms.
If your detector hasn't been retrained on current reasoning model output, it’s classifying against a distribution that no longer exists in production. The 38% accuracy is the result of this structural drift.Actionable Fixes: Hardening the Detection Pipeline
After re-checking my own setup, here are the four concrete changes I made 1 Confidence Threshold Raised to 0.85
A 0.62 mean confidence on a fully AI-positive test set indicates that individual high-looking scores can still be coin flips. For anything that triggers an action (like a submission rejection or account flag), I now require multi-signal corroboration or human review if the score is below 0.85.2. Build a Held-Out Test Set from Current Models
I’m now generating my own validation samples from current frontier models (Kimi K2, Claude Sonnet 4.6, GPT-5, Gemini 2.5 Pro) and running them through my detection layer monthly.
The set also includes "human-positive" texts (like the Declaration) to constantly monitor the false-positive rate.
Pseudo-code for the monitoring set I now keep around
HELD_OUT = {
"ai_positive": [
# 50 samples each from current frontier models
kimi_k2_samples,
claude_sonnet_4_6_samples,
gpt_5_samples,
gemini_2_5_pro_samples,
],
"human_positive": [
# public-domain texts written before 2020
declaration_of_independence,
federalist_papers_excerpts,
public_domain_essays,
],
}
- Treat Detection as a Probabilistic Component
Even 97% accuracy means a 3% misclassification rate at scale. For anything where the cost of an error is real, detection must be a signal, not a verdict.4. Verify Modality Fit
I use AI or Not for image and audio checks in my projects because it covers multiple modalities. The Kimi K2 benchmark gave me a current-model accuracy number for the text side, which closed a vital verification gap I couldn't easily verify on my own.A Minimum-Viable Detector-Monitoring Pattern
If you are running detection in a production pipeline, this is the basic ML hygiene that keeps the integration from silently failing:
LOOP (monthly):
for detector in production_pipeline:
accuracy_ai = run(detector, HELD_OUT.ai_positive)
accuracy_human = run(detector, HELD_OUT.human_positive)
mean_confidence = avg_confidence(detector, HELD_OUT.ai_positive)
   if accuracy_ai     < baseline.ai - 0.05:    alert("AI detection regressed")
   if accuracy_human  < baseline.human - 0.05: alert("FP rate increased")
   if mean_confidence < baseline.conf - 0.10:  alert("Detector going uncertain")
Most teams I've seen integrate detection once and never check it again. This pattern is essential because accuracy decays per model generation.TL;DR
97% vs 38% on Kimi K2 essays shows a structural, not a tuning, gap.
Detector accuracy decays per model generation. Re-benchmark quarterly.
Test false-positive rate against famously human text (the Declaration of Independence is a free check).
Raise your confidence threshold; one number is not a verdict.
Build a held-out test set from current models and monitor it on cadence.
If you're running detection in production and you can't name the generation of model you benchmarked against, you have an invisible calibration gap. The benchmark was the wake-up call; the monitoring pattern is what makes the fix permanent.