





Technical documentation’s audience has changed. It’s no longer just engineers reading pages — increasingly, humans and AI work together: humans make decisions, AI finds materials, organizes steps, and assists execution. Here’s how to make the same knowledge serve both.
Last month, our team shipped a major documentation update. Two weeks later, I noticed something odd: our AI assistant was giving outdated answers. The docs were right. The AI was wrong.
That’s when I realized — we were writing for humans, but forgetting the AI assistants helping them.
This isn’t just about adding llms.txt to your repo. It's about recognizing a fundamental shift: technical documentation now serves two audiences simultaneously. And if you optimize for only one, you're already behind.
Welcome to the era of Document “Skillification” — a term for making documentation AI-consumable through structured, callable capabilities. Not yet in the dictionary, but you’ll hear it more as AI Agents become mainstream.
Why This Matters Now
The audience for technical documentation has changed. In the past, it was primarily engineers reading pages. Today, more and more scenarios involve humans and AI working together: humans make decisions, while AI is responsible for finding materials, organizing steps, and assisting execution.
If documentation only exists in web page form, AI typically needs to process HTML first, then extract the main content from navigation, styling, and irrelevant information. This step reduces accuracy and slows down response times.
Therefore, what document Skillification solves is not a new buzzword, but a practical problem: how can the same body of knowledge serve both humans and AI?
What Is Document Skillification?
This can be understood in two layers.
The first layer is making documentation AI-consumable. Common entry points are llms.txt, llms-full.txt, and page-level .md exports. The focus is on enabling AI to reliably obtain structured content.
The second layer is the Skill repository. Using SKILL.md to write processes, constraints, and best practices as callable capabilities, answering "what rules to use in what scenarios."
These two layers work in tandem: the former provides content entry points, while the latter constrains usage patterns.
A Practical Implementation Roadmap
Start by adding AI entry points — no need to refactor all documentation at once. Create llms.txt, fill in .md exports for key pages, and provide llms-full.txt as needed. This way, you first ensure content is readable, then gradually improve reading accuracy and usage stability.
Then codify high-frequency actions into Skills. Examples include SQL documentation writing standards, operations troubleshooting flows, and upgrade checklists. This type of content has high reuse rates and is most prone to inconsistencies when communicated orally.
For the retrieval layer, adopt “search first, then read.” Given large and rapidly updating documentation, do not dump the entire text into context at once. You can use MCP or a database query layer. The key is not the integration form, but on-demand retrieval.
Drawing from the oceanbase-doc-skills implementation (https://github.com/amber-moe/oceanbase-doc-skills), this path is already viable: skills, rules, examples tables store structured knowledge, and QueryService retrieves results by skill name, category, or keywords, then passes them to the upper layer for invocation.
How Existing Projects Approach This
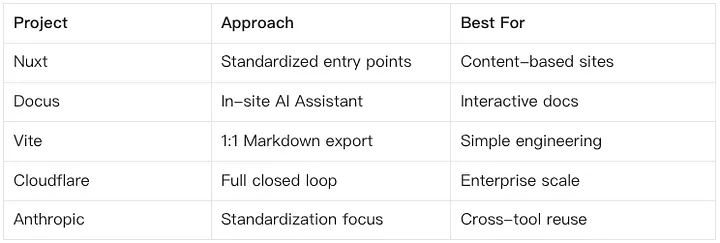
Nuxt’s approach is to standardize entry points first. Official support for llms.txt capabilities is provided, and Nuxt Content offers an LLM integration module. Instead of manually maintaining two sets of documentation, this adds an AI consumption export on top of the existing content system.
Docus leans toward “in-site capabilities.” It integrates AI Assistant and MCP into the documentation site. AI doesn’t need to preload the entire site but retrieves on demand. This reduces context pressure and improves hit controllability.
Vite’s path is straightforward: documentation pages and Markdown pages have a one-to-one correspondence — guide corresponds to guide.md. Combined with llms.txt as a directory entry point, this forms a "locate first, then fetch by page" flow. Engineering refactoring costs are relatively low.
Cloudflare’s approach is more comprehensive. Documentation entry points, Skills, and retrieval capabilities are connected together, basically forming a closed loop of content, rules, and invocation.
Anthropic’s focus is on standardization itself. Through Agent Skills specifications and example repositories, it standardizes Skill metadata, trigger descriptions, and content organization methods, facilitating cross-tool reuse.
Direct Value This Direction Brings
Reduced maintenance costs. One knowledge source can simultaneously serve web reading and AI invocation, reducing duplicate maintenance.
Reduced team memory burden. Operations statements, SQL specifications, and troubleshooting flows change from “relying on human memory” to “on-demand invocation.”
Better usability in offline scenarios. In intranet or isolated environments, llms-full.txt and local Skills can support local retrieval and assisted execution.
More consistent output. Processes and formats are front-loaded into Skills, reducing variance between different people and different models.
Problems to Address Upfront
This is not a one-time engineering effort. Specifications change, tools change, models change — Skills require continuous maintenance.
If documentation volume is large, avoid doing everything at once. A safer approach is to pilot in high-value domains first, then gradually expand.
Additionally, human-readable versions and AI consumption entry points need a synchronization mechanism. Without synchronization, you’ll eventually end up with two diverging documentation sets.
Finally, Skill instructions must be executable and verifiable. Rules written too abstractly will spiral out of control during implementation.
Conclusion
Document Skillification is not about changing how documentation is written — it’s about refactoring the knowledge delivery path: enabling the same content to support reading, retrieval, and execution simultaneously. For technical teams, this ultimately translates to lower communication costs, more stable delivery quality, and faster issue resolution cycles.
What’s Next?
→ Try it yourself: Start with llms.txt on your next documentation update.
→ Building agent skills? Check out the Anthropic Skills specification (https://github.com/anthropics/skills) for best practices.
→ Got questions? Drop a comment below — I read every one.
→ Want more? Follow for deeper dives into AI-native documentation patterns.
Is your documentation AI-ready? Share your approach in the comments.