








Data pipelines are the backbone of modern data-driven organizations. They automate the movement, transformation, and storage of data - from raw sources to actionable insights.
Python has become the go-to language for building scalable pipelines because of its rich ecosystem, flexibility, and ease of use.
This guide walks through the fundamentals, tools, and best practices for building robust data pipelines using Python.
Understanding Data Pipelines
Imagine you need to supply clean water to a village. The process involves collecting water from different sources (rivers, wells, rain), purifying it, transporting it, and storing it so people can access it whenever they need it.
A data pipeline works in a very similar way.
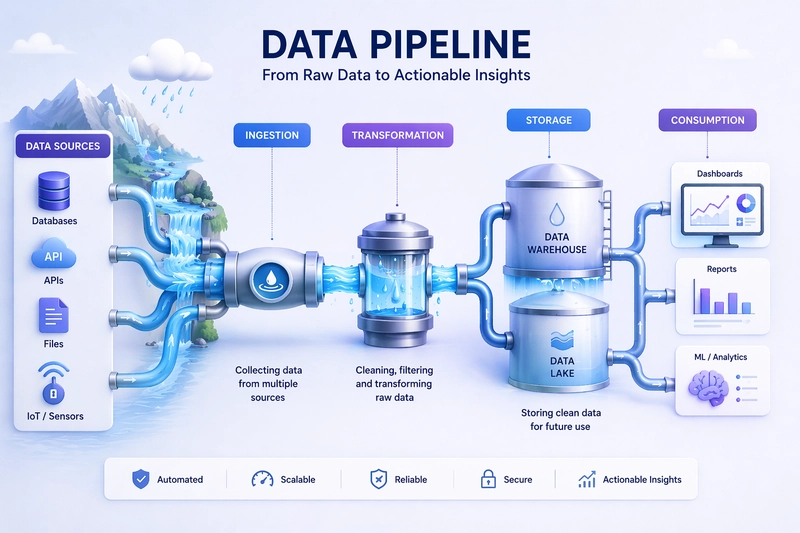
It automates the journey of raw, unstructured data from multiple sources (like databases, APIs, or IoT devices) and transforms it into clean, usable data stored in a destination (like a data warehouse) for analysis.
Components of a Data Pipeline
Let’s break it down using the same analogy:
1. Collecting Water (Data Ingestion)
Just like gathering water from lakes or wells, a pipeline starts by extracting data from sources such as databases, APIs, spreadsheets, or sensors.
The goal here is simple: get all the data into one system, no matter how scattered it is.
2. Filtering and Purifying (Data Transformation)
Raw water isn’t clean—and neither is raw data.
At this stage, the pipeline:
- Removes duplicates
- Handles missing values
- Standardizes formats
- Enriches data
This is where messy data becomes usable.
3. Transporting Through Pipes (Data Movement)
Once cleaned, water flows through pipes. In data pipelines, this represents the movement of data between systems.
This can involve:
- ETL processes
- Message queues (like Kafka)
- Cloud data transfer services
The goal is to move data efficiently without delays or bottlenecks.
4. Storing in Tanks (Data Storage)
Clean water is stored in tanks. Similarly, processed data is stored in:
- Data warehouses (like Snowflake)
- Data lakes (like AWS S3)
- Databases
This is where data becomes ready for use.
5. Accessing on Demand (Data Consumption)
Finally, people use the water.
In the same way, data is consumed through:
- Dashboards
- APIs
- Machine learning models
This is where insights actually happen.
Essential Python Libraries and Tools
Python supports every stage of a pipeline:
Data Ingestion
-
requests- API calls -
pandas- handling CSV/JSON files
Transformation
-
pandas- cleaning and aggregation -
PySpark- large-scale distributed processing
Storage
-
SQLAlchemy- database interaction -
boto3- AWS S3 integration
Orchestration
-
Apache Airflow- workflow scheduling and automation -
Dagster- modern pipeline orchestration with observability
Best Practices
Error Handling
Implement retries and proper logging to avoid silent failures.
Monitoring
Track pipeline health using tools like Airflow’s UI.
Documentation
Keep clear documentation for:
- Code
- Dependencies
- Workflow logic
Testing
Test each stage of the pipeline using:
- Unit tests
- Sample datasets
Popular Frameworks for Advanced Use Cases
- Apache Airflow - Best for complex workflows with dependencies
- Dagster - Strong focus on testing and data asset visibility
- Prefect - Simplifies building fault-tolerant pipelines
- Luigi - Good for batch processing and dependency management