


The real headache in RAG isn’t retrieval or generation — it’s the layer in between. Where does the data live? How do you keep it in sync? Who glues it all together? seekdb and Dify are both open-source. Your RAG stack — from storage to orchestration — can be self-hosted, auditable, and customizable, without locking you into closed services. This post walks through three paths, all built on one stack: RAG from scratch with seekdb, Dify + seekdb, and a knowledge base desktop app. Pick the one that fits and get it running.
Where seekdb Fits in the RAG Pipeline
A typical RAG pipeline looks like: load documents → chunk → embed → store; at query time: retrieve → (optionally) rerank → feed to LLM → generate. If your storage is a patchwork of MySQL + vector DB + full-text engine, you end up managing sync, multi-source queries, and fusion yourself. seekdb’s role: one database that holds relational data, vectors, and full-text in the same place. Write once, index automatically; one hybrid query returns results. You can use in-database AI functions for embedding and reranking when needed, so storage and retrieval live in one layer with less glue code.
Three paths we’ll cover:
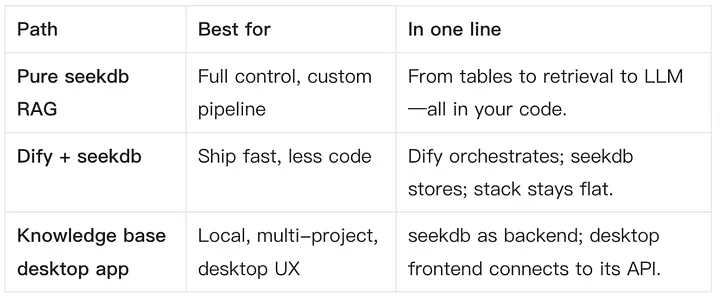
RAG from scratch with seekdb — Best if you want full control over the pipeline or already have a Python/app stack.
Dify + seekdb — Best if you want Dify for orchestration and UI and seekdb as the knowledge-base backend, collapsing the stack to Dify config + seekdb storage.
Knowledge base desktop application — Best if you want a local, multi-project desktop app with seekdb as the backend and a custom frontend.
Path 1: RAG from Scratch with seekdb (Summary)
Deploy and create tables
Run seekdb in Embedded or Client/Server mode. Create a table (or Python collection) with vector + full-text columns, and create a VECTOR INDEX and FULLTEXT INDEX.-
Load documents
- Read docs (PDF, TXT, MD, etc.) → chunk them (by paragraph, by length, with overlap, etc.).
- For each chunk, call your embedding model to get a vector (use seekdb’s in-database AI functions, or compute in your app and insert into seekdb).
- INSERT into seekdb: each row has chunk text, vector, and any metadata you need (source, doc id, segment id, etc.).
-
At query time
- Turn the user question into a query vector (same embedding).
- Use hybrid search: vector_query + full_text_query(optional) + relational filters (e.g. by knowledge-base id), and take top_k candidates.
- Optional: rerank with seekdb or in your app → pass the final context to your LLM to generate the answer.
-
Things to watch
- Chunking strategy and chunk size directly affect recall; pick one and tune from there.
- If you use in-database AI for embedding/reranking, you save a round-trip to external services.
- For full steps and code, see https://docs.seekdb.ai/seekdb/build-a-rag-system-with-seekdb/
Path 2: Dify + seekdb — Collapse the RAG Stack (Both Open-Source)
Dify handles workflow orchestration, knowledge-base setup, and the chat UI. The data source can be seekdb: Dify’s pipeline does “upload/parse → chunk → embed → write,” while storage and retrieval happen in seekdb — with strong consistency, hybrid search, and in-database AI. Dify and seekdb are both open-source, so the whole RAG stack can be self-hosted, audited, and extended. Good fit if you care about data and architecture ownership.
Configuration idea (check your Dify version for exact UI):
In Dify, set the knowledge base data source to seekdb (or wire seekdb via Dify’s supported vector store/API).
After you upload documents, Dify parses and chunks them, calls the embedding service, and writes into seekdb. At query time, Dify sends the query to seekdb, gets hybrid-search results back, and passes them to the LLM node for the final answer.
Result: no separate sync scripts or multi-database juggling — the stack is just “Dify config + seekdb.” For details, see https://en.oceanbase.com/blog/24316625920
Path 3: Knowledge Base Desktop App — Local, Multi-Project
If you’d rather skip Dify and want a local knowledge base desktop application (multiple projects, multiple docs, local search): use seekdb as the backend and a desktop client (e.g. Tauri or Electron + your frontend) to connect to seekdb’s API. The flow is the same: parse → chunk → embed → write to seekdb; at query time use hybrid search and show results or feed them to a local LLM.
There’s an official guide: https://docs.seekdb.ai/seekdb/build-kb-in-seekdb/ — it outlines the stack and steps.
Which Path to Choose?
Once you’ve got RAG or a knowledge base running with seekdb, you might wonder where it goes next. In the next post we’ll take seekdb beyond text: multimodal and agents — think travel assistant, image search, TEN+PowerMem voice assistant — and how the same stack extends to those scenarios.
Repo: https://github.com/oceanbase/seekdb (Apache 2.0 — Stars, Issues, PRs welcome)
Discord: https://discord.com/channels/1331061822945624085/1331061823465590805
Dev.to: https://dev.to/seekdb
Building RAG or an AI workflow? What’s the one thing you wish your database did better — or didn’t do at all? Drop it in the comments. We read them, and the next features we ship often come from exactly those pain points. Open source only gets better when people say what’s broken.