










The main aim of this article is to describe the limitations of ID, in terms of capacity, and the math behind the scene.
Alright, good people — ID is not complicated. Various methods can generate it, such as using a counting number, randomizing, or composing/concatenating from multi-attributes (like a national ID or college student ID). Sometimes one can ignore it because the ID is auto-generated in the database, like MongoDB.
But what if we must find out how to make the ID as short as possible? That is why we need to take time for consideration.
The Proper ID Properties
Let's think about the important properties of ID.
No duplication — no need to elaborate. If the ID is not unique, it is not an ID.
It must be sufficient — in terms of capacity, it depends on the generation method. Assume the system will contain no more than 100 records. If the ID is generated by a running number, 2 digits of decimal is fine (00–99). In contrast, the same 2 digits are not sufficient if the ID is generated by randomizing.
It can't be guessed — if someone got the ID
95, by intuition, everybody knows there are also IDs1,2, …,94. They also know there are 95 records of data. This makes the system so transparent — and you will feel very insecure if the ID is sensitive data.It should not be too long — this property is necessary if we intend the user to memorize their ID; otherwise, just ignore it.
-
Efficient to create. ID generation should not be the bottleneck of the system. It should consume a very short time and satisfy all properties above.
- The running number is far away from the good option because it can only be processed one by one which means it has to wait for the current one to be created before the next one can be processed.
- Composing from multi-attributes is edgy to violate the property numbers 2 and 3. For example, an employee ID like ENG-2024-001 (department + year + sequence). It can be guessed for sure. One can tell the department, the join year, and roughly how many employees there are.
- Rely on auto-generated methods like UUID or let the database generate for us, these methods work well for most of the use-case except a system which may use ID as the referral code for inviting new members. The referral code should not be too long while the real question is how many digits of ID that enough?
ID Collision Probability
To find the proper digit count for a randomized-generated ID, we must know the chance that a newly created one will duplicate any existing ID.
Thanks to mathematics (even though we do not get along so well) back in 1939 that explains this in a lot more simple terms the birthday problem. In short, they state that only 23 people are needed for that probability, for at least two will share a birthday, to exceed 50%. The statement is considered a paradox which seems wrong, but it's true.
⚠️ Warning, math inside!
Birthday Problem Explanation
The explanation is from Wikipedia — Birthday Problem
- Define
nas the number of 23 people - There are 2 types of events for this problem.
- Assume
Ais the probability that none in the group share the same birthday. - While
Bis the probability that at least 2 people share a birthday. - Determine the value of
Ais more simple thanBbecause people who shared the same birthday might be 2, 3,…, 23 people plus a lot of combinations, for example, there might be 1, 2,… pairs of people that share their own birthday. - We know that
A+B= 1 - Assume that a year has 365 days. Let
P1be the arrangement that all 23 people have different birthdays whileP2is all possible arrangements.-
P2= 365^23 -
P1= P(365,23) = 365!/(365-23)! = 365 x 364 x 363 x … x (365-22)
-
-
A=P1/P2= 365/365 x 364/365 x 363/365 x … x (365-22)/365 ~ 0.492703 -
B= 1 -A~ 0.507297, yeah it is 50.7297%
There are various probability estimation methods that I won't explain (cause I don't fully understand them 🥹) for the real-world application.
By the way, you don't need to understand the math behind for estimation of the collision probability. Thanks to some nice guys, they created the calculator for mankind! Please find the link below.
👉 https://zelark.github.io/nano-id-cc/
We may define a set of possible alphabet and the number of characters of ID. Plus expected ID generation rate per time then the tool will estimate the lifespan of the ID we designed.
Note: Collision chance grows exponentially, so 1% is a relatively safe magic number to indicate the capacity limit of the ID generation.
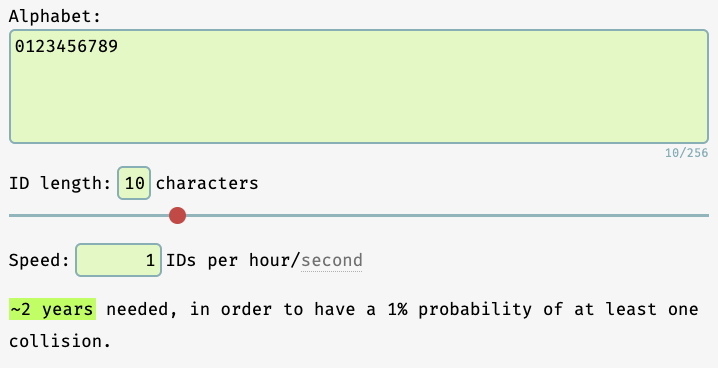example of the calculator

collision chance of the birthday problem
The UUID We Trust
One question: how long can we actually use UUID?
Since everyone says UUID is trustworthy, I'm just curious — how long can we ignore the fact that it's theoretically possible for UUID to reach its limit?
For those who don't know, UUID is 32 characters of hexadecimal. Plugging that into the calculator gives a truly extraordinary answer — UUIDs are effectively unlimited for any realistic use case.

UUID collision chance
Now, good people ~Your entire image is crafted to leave no lasting memory with anyone you encounter!

Consideration
Now we know there is a small collision chance in randomized ID generation — so what now?
We may either:
- Handle the relatively low possible collision error, or
- Ignore it because the deadline is too rushed 😅
The decision is yours!