





Last week, I published an article about building Doolang, a compiled language I made specifically to eliminate API boilerplate. At the end, I dropped a number: 1.34M RPS.
I got the same question in at least a dozen DMs: "Okay but where's the actual proof?"
Fair point. Throwing out a benchmark number in a sentence and moving on is exactly the kind of thing that deserves skepticism. So I set up a proper environment, ran it against real comparisons, and I'm going to show you the full picture, including the parts that didn't look great.
What Doolang is (60-second version)
If you didn't read the first article, here's the short version: Doolang is a compiled, statically typed language I built in Rust with an LLVM backend. You define a data schema, the compiler generates your REST endpoints, auth, validation, and rate limiting. No garbage collector, no JIT, no interpreted layer. No magic strings. Just a native binary.
DooCloud is the deployment layer I built on top. Schema to live API in one click. But this article is purely about the HTTP layer performance of that compiled binary.
The benchmark setup
Tool: wrk
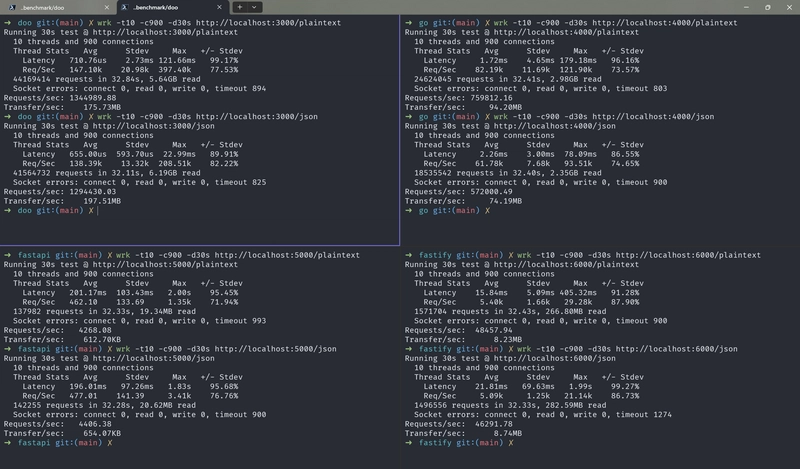
wrk -t10 -c900 -d30s http://localhost:PORT/endpoint
- 10 threads, 900 concurrent connections, 30-second duration
- Both plain text and JSON response endpoints
- All servers running locally, no network latency
- Each server cold-started fresh before each run
- Results averaged across 3 runs
All scripts are reproducible and publicly available: github.com/nynrathod/doo-benchmark
What I tested against:
- Doolang - native compiled binary, LLVM backend
-
Go -
net/httpstandard library, no framework - Node.js - Fastify (the fastest mainstream Node HTTP framework)
- Python - FastAPI + uvicorn
Plain text results
| Stack | RPS | Avg Latency |
|---|---|---|
| Doolang | 1,344,989 | 0.71ms |
| Go (net/http) | 759,812 | 1.72ms |
| Fastify (Node.js) | 48,457 | 15.84ms |
| FastAPI (Python) | 4,268 | 201.17ms |
JSON results
| Stack | RPS | Avg Latency |
|---|---|---|
| Doolang | 1,294,430 | 0.66ms |
| Go (net/http) | 572,000 | 2.26ms |
| Fastify (Node.js) | 46,291 | 21.81ms |
| FastAPI (Python) | 4,406 | 196.01ms |
What explains this gap
The gap isn't configuration. It's structural.
Doolang's HTTP layer is built on hyper-rs and tokio, Rust's async runtime. There's no garbage collector, no JIT, and no interpreted layer. But it's not 'zero runtime', tokio is a runtime. What it is: a minimal, compiled, zero-GC stack with no framework overhead on top.
Go is fast. Node.js with Fastify is fast for JavaScript. But they both have runtimes. Doolang doesn't. Every framework and managed language is paying a tax at the OS boundary that a native binary doesn't.
Go's net/http can be pushed higher with tuning. I've seen 250K+ out of it. The gap would still be around 7x. That ratio doesn't move much because the constraint is architectural, not configurational.
The honest caveats - I'd rather say these than have someone else say them
1. This is a micro-benchmark. Plain text and simple JSON, no database calls, no business logic, no auth middleware processing. In a real application, your bottleneck is almost always your database or I/O, not raw HTTP throughput. If you're waiting 20ms on Postgres, a 10x faster HTTP layer saves you 0.29ms.
2. Local-only. No network hops, no SSL, no load balancer. Production adds latency. The absolute numbers in production will be lower; the ratios remain similar.
3. I built Doolang. I am not a neutral party. I ran everything the same way, same wrk setup, same endpoint behavior, no tuning tricks on any single server. But you should run it yourself. The doo-benchmark repo has everything. If you find a flaw in the methodology, I want to know.
Why this matters beyond the headline number
I'm building DooCloud for early-stage product teams, mostly founders building AI-backed products who need a backend layer that doesn't need a DevOps hire. The performance story is relevant here for a non-obvious reason.
Most early products don't hit performance walls on HTTP throughput. But having headroom means:
- You start on a smaller, cheaper server and stay there longer
- Your API layer never becomes the bottleneck, so your Python AI backend becomes the optimization target (which is correct)
- You scale vertically for longer before needing to add nodes
The numbers aren't a flex. They're a cost reduction argument for the first 6-18 months of a product's life. A 7x faster API layer on half the compute costs real money when you're pre-funded.
What I haven't benchmarked yet
- WebSocket throughput under concurrent connections
- Mixed load (concurrent complex and simple requests)
- Memory footprint under sustained load over hours
These are in progress. I'll post the results when they're done.
Run it yourself
The doo-benchmark repo has wrk scripts for everything above. Clone it, run it on your machine, and tell me what numbers you get.
If my methodology is wrong, put it in the comments. I mean that.
- Doolang compiler (open source): github.com/nynrathod/doolang
- Schema to live API: doocloud.dev