


Full context feels safe until it isn’t. Here’s the engineering fork in the road — and real numbers from an open-source memory layer on OpenClaw.
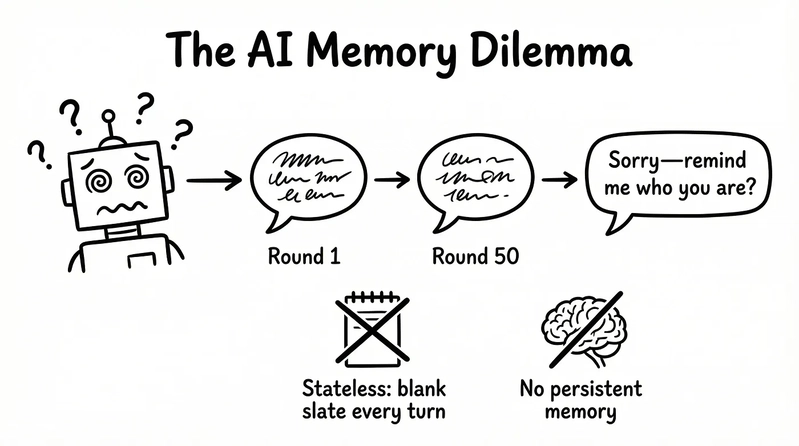
Stateless isn’t a feature. It’s the default bug.
That’s the part nobody puts on the landing page: large language models don’t continue anything on their own. Every turn is a fresh sheet of paper — unless you shovel history back in.
So the industry reached for two comforting reflexes:
Crank the context window — pack in everything that might matter. Longer feels safer.
Drop a MEMORY.md and paste it every turn — simple, auditable, easy to debug.
Both are great at small scale. Both fall apart at real scale.
Because context isn’t free. You pay three ways: slower, pricier, and muddier. Inference drags. Your token bill climbs linearly. Worst of all, as context grows, attention thins out in the middle — quality drops, contradictions creep in, and you’re not buying “memory.” You’re buying noise.
So the real question isn’t whether to remember. It’s this:
What shape should memory take before it enters the model — verbatim dump, or retrieve what matters?
This piece is about that engineering fork — and some numbers we saw hooking an open memory layer to OpenClaw.
Full context is like reciting your entire diary before every sentence
A lot of people hear “long-term memory” and think: store everything anyone ever said.
A better engineering definition is tighter:
Keep only facts that help future decisions — and that retrieval can amplify — and let stale stuff expire on purpose.
Human memory isn’t a bit-perfect disk image. We lose detail; we blur timelines; we still keep actionable residue — “no cilantro,” “last time we were blocked on that dependency.” Flip that around for AI: full retain + full inject often buys you less coherence and more contradiction and context pollution.
That’s why I keep coming back to three knobs:
Write path: what do you distill from chat into durable memory?
Read path: what do you retrieve — and how much — before the model sees it?
Lifecycle: how do old facts fade instead of squatting forever?
What should a “memory system” actually look like?
One sane pattern: a persistent memory layer outside the LLM — think PowerMem (Apache 2.0 from OceanBase) — that extracts salient facts from dialogue (dedupe, conflict update, merge related), recalls on demand, and forgets stale items with an explicit decay policy.
A few properties that actually matter in production:
Hybrid retrieval — vectors + full-text + graph-style links. Fuzzy intent and exact keywords need to hit. “Embedding-only search” ages poorly in real products.
Forgetting isn’t a bug — Ebbinghaus-style decay sounds like a psych meme; it’s really a capacity vs. signal-to-noise trade you’re engineering on purpose.
Multi-agent — private memory and shared memory across agents. Multi-agent isn’t “someday”; it’s now. Single-user, single-session assumptions break fast.
Multimodal — text, images, audio. Not for show — workflows are already messy.
If you list those as a feature matrix, it reads like marketing. In engineering terms, they answer one question: how do you put the smallest useful slice of memory in front of the model this turn?
The benchmark doesn’t care about your vibes: LOCOMO vs. “just paste everything”
On LOCOMO (long-dialogue memory benchmark; Maharana et al., ACL 2024), PowerMem vs. a full-context baseline isn’t a rounding error:
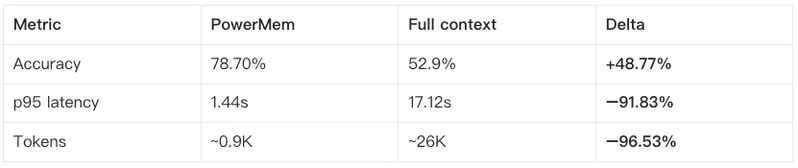
The point isn’t “pick a winner.” It’s that retrieval + extraction beats brute-force context on quality, latency, and cost at the same time — which feels backwards until you realize the information shape changed: from “replay the transcript” to structured, retrievable facts.
OpenClaw: the anti-pattern you can actually measure
Out of the box, OpenClaw can ship the entire MEMORY.md into system_prompt every turn, with no retrieval—and the file keeps growing.
That’s full-context thinking in a real toolchain: simple, transparent, explainable — right up until it starts eating you alive.
Same workload, total input tokens:
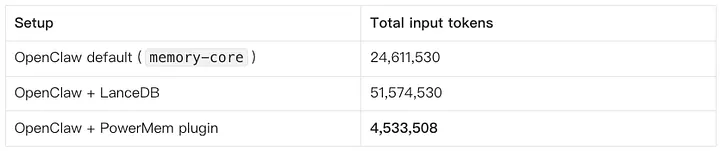
The PowerMem plugin lands around ~18% of the default — same ballpark as “stop reciting the encyclopedia before answering one question.”
The integration model is what you’d want if you designed it on purpose: retrieve before the session, inject only what’s relevant; extract after the session, persist durable facts — instead of mirroring the whole file into the prompt every time.
Make it run: OpenClaw + PowerMem (copy-paste path)
Pick one path: use ClawHub (step 2) or the manual server + JSON (step 3) — you don’t need both.
1 — OpenClaw
https://openclaw.ai/
2 — One-click via ClawHub (recommended)
Install skill: https://clawhub.ai/Teingi/install-powermem-memory
Plugin name: memory-powermem.
3 — Manual path (when you want your own server)
Install and run PowerMem:
pip install powermem
# from a directory with a configured .env
powermem-server --host 0.0.0.0 --port 8000
Install the OpenClaw plugin:
openclaw plugins install memory-powermem
Point OpenClaw at your server — edit ~/.openclaw/openclaw.json and set the memory slot to this plugin, for example:
{
  "plugins": {
    "slots": { "memory": "memory-powermem" },
    "entries": {
      "memory-powermem": {
        "enabled": true,
        "config": {
          "baseUrl": "http://localhost:8000",
          "autoCapture": true,
          "autoRecall": true,
          "inferOnAdd": true
        }
      }
    }
  }
}
Restart the OpenClaw Gateway, then sanity-check:
openclaw ltm health
If that’s green, you’ve swapped “paste the whole scroll every turn” for retrieve-then-inject + capture-after.
Two layers that don’t negotiate: operation plane + cognitive plane
If you’re going to run memory in production, you usually need both:
pmem CLI — humans and agents share the same front door: scriptable, automatable, boring in the good way.
Dashboard — distributions, health, “what did we actually memorize?” so humans can govern instead of guessing.
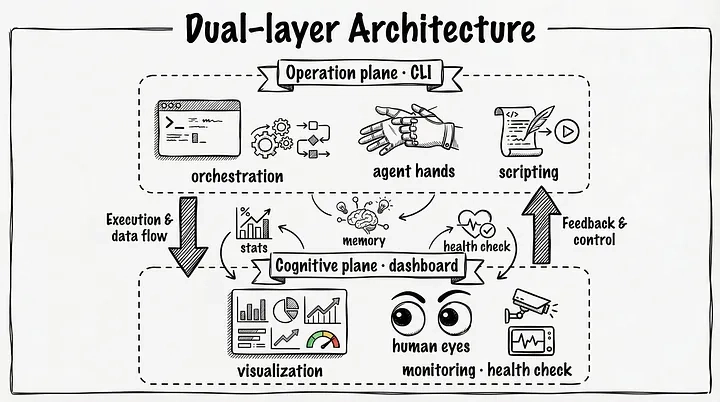
Agents need low-friction execution. Humans need explainability and ops judgment. Skip the operation plane and memory never ships. Skip the cognitive plane and you end up with vectors in a black box — and the only fix is nuke from orbit.
Quick local try:
pip install powermem
# or: uv add powermem
pmem --version
With powermem-server running, open the dashboard at http://localhost:8000/dashboard/.
What the open-source argument should actually be about
If you’re building agents, CLIs, or personal automation, move the debate past “do we keep a MEMORY.md?”
Is memory a document or a database?
Is injection append-only or retrieve-then-inject?
Do you have real decay, or do you pretend “never expires” means “always correct”?
Projects like PowerMem are less a billboard and more a reproducible lab bench—hybrid retrieval, extraction, decay, multi-agent, multimodal—trading context signal-to-noise for engineering you can argue about in issues instead of vibes.
If you take one line home, make it this:
Long-term memory isn’t about remembering more. It’s about recalling the right thing when it matters.
Further reading
PowerMem (Apache 2.0): https://github.com/oceanbase/powermem
OpenClaw: https://openclaw.ai/
LOCOMO (ACL 2024): https://aclanthology.org/2024.acl-long.747.pdf