






A practical guide
In the first part, I covered the two initial signals to diagnose that something is wrong:
- Latency
- Traffic
Those two alone explain a surprising number of production incidents. But they don't explain everything. Rising latency tells you a problem is developing. Traffic tells you what the system is dealing with.
I mentioned two more signals:
- Errors
- Saturation
These two tell you something more important - whether the system is approaching failure. And this is where monitoring becomes truly operational. I will cover those two signals in this blog. Let us start with Errors.
Errors - The most misunderstood signal
Many teams think error monitoring is simple. It is about counting failures. Raise an alert when they increase. In practice, error metrics are rarely that straightforward.
The first mistake teams make is treating all errors as equal. They are not. Some errors are expected and some errors are harmless. Others indicate an outage in progress. Monitoring must differ between them. Otherwise alerts become noise. And noisy alerts get ignored, which defeats the entire purpose. I have seen production systems where engineers simply muted error alerts because they fired every few hours.
Error rate is more important than error count
Raw error counts are misleading. What do you think - ten errors per minute might be catastrophic or irrelevant?
It depends on traffic. If you process:
- 100 requests per minute → 10 errors = disaster
- 100,000 requests per minute → 10 errors = background noise
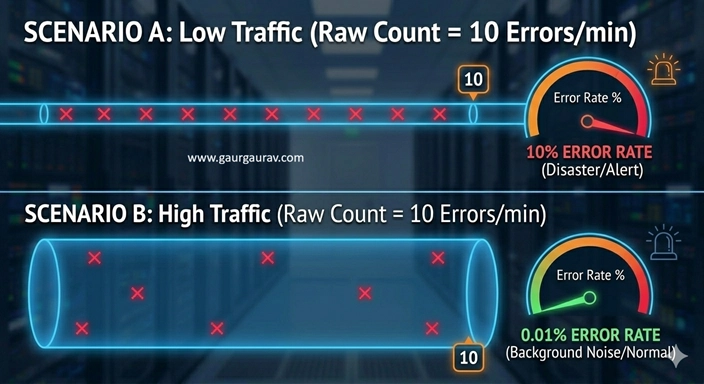
Error rate is what matters. A simple production alert looks like this:
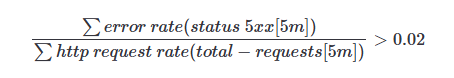
It means alert when:
Error rate > 2%
This works far better than static thresholds because it scales automatically with traffic.
4xx vs 5xx - Critical distinction
One of the most common monitoring mistakes is combining 4xx and 5xx errors. They represent completely different problems. Let me talk through them.
5xx errors
These indicate system failures:
- Exceptions
- Timeouts
- Dependency failures
- Resource exhaustion
5xx errors should almost always trigger alerts. They mean the system is failing users.
4xx errors
These usually indicate client behaviour:
- Invalid input
- Authentication failures
- Missing resources
Most of the time, 4xx errors should not page engineers. But they should still be monitored. Their spikes often reveal integration problems.
- Partner systems misbehaving
- Clients sending unexpected requests
- Sometimes bots discovering your APIs
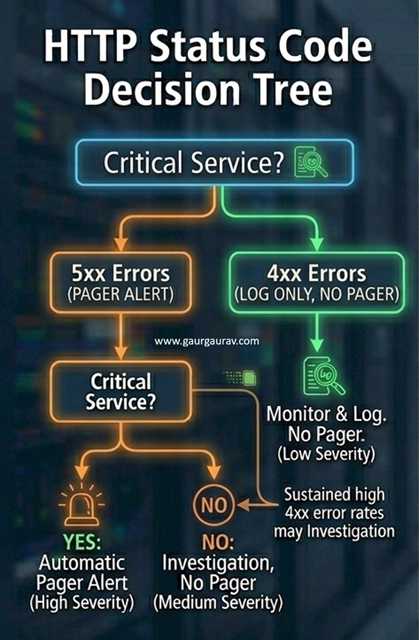
I once saw a system where 40% of traffic suddenly became 401 responses. Nothing was broken in my service. A client service had deployed a change with an incorrect token configuration. The service was healthy. The integration was not. Without separate 4xx monitoring we would never have noticed.
Error budget thinking
Once services mature, error monitoring becomes less about incidents and more about error budgets.
Instead of asking "Did we have errors?" You ask “Did we exceed acceptable failure levels?”
Example SLO:
- 99.9% success rate
That allows:
- 0.1% failure
Error budgets prevent overreaction to minor fluctuations. Without them, teams end up firefighting dashboards instead of protecting user experience. In most post-mortems, latency and errors are symptoms. Saturation is usually the cause. Let us move to the next indicator – saturation.
Saturation — Where failures actually begin
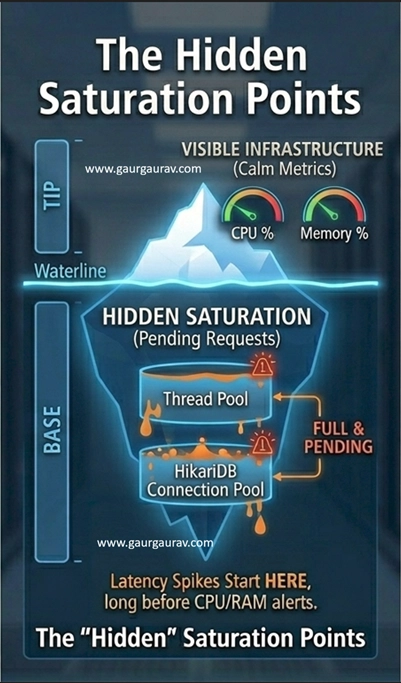
If latency is the early warning signal, saturation is the root cause signal. Most production outages start with a resource limit somewhere. I am not necessarily talking about CPU or memory. I am talking about less obvious resources like thread pools, connection pools, queue consumers, file descriptors, and rate limits.
These limits quietly fill up until requests start waiting and then timing out. Then they start failing. By the time error rates increase, saturation has usually been happening for a while.
CPU and Memory - Necessary but not enough
Infrastructure metrics still matter. They just don't tell the whole story.
Monitor:
- CPU utilization
- Memory usage
- Disk I/O
- Network throughput
Example:
rate(container\_cpu\_usage\_seconds\_total[1m])
and:
container\_memory\_usage\_bytes
The Metrics that break systems most often
As I mentioned in my previous blog, you need effective metrics. In this section I will list a few metrics that can prove useful.
Connection pool usage.
Monitor connection pool usage. When a connection pool fills up - requests queue internally, latency increases, timeouts appear, and errors follow.
In this scenario CPU can still be 30%. Memory can still be healthy. The service still looks "green." Except users are waiting seconds for responses.
Example — Monitoring a connection pool
Micrometer automatically exposes Hikari metrics:
hikaricp_connections_active
hikaricp_connections_idle
hikaricp_connections_pending
The critical one is:
hikaricp_connections_pending
If pending connections increase steadily, saturation is approaching and action is needed.
Kubernetes saturation signals
Container platforms introduce new saturation points. An important metric to monitor is:
kube_pod_container_status_restarts_total
Restarts indicate instability.
And:
container_cpu_cfs_throttled_seconds_total
CPU throttling causes latency spikes even when CPU usage looks normal. That one surprises a lot of teams.
Dependency Metrics — The missing visibility layer
Most services are only as reliable as their dependencies – databases, caches, APIs, queues, and third-party integrations.
When dependencies slow down, your service slows down. But if you only monitor your service, you won't see the cause. You only see the symptoms. Dependency metrics close that gap. Without them, incident investigations turn into guesswork.
Downstream Latency Metrics
Every external call should have a latency metric. Even if the dependency is "reliable." Especially then.
Simple example:
Timer.Sample sample = Timer.start(registry);

Response response = paymentClient.process(request);

sample.stop(
 registry.timer("payment.api.latency")
);
During incidents, this metric often points directly at the problem.
Dependency error metrics
Track dependency failures separately.
Example:
payment_api_errors_total
This helps answer:
Are we failing… or is the dependency failing?
That distinction saves time during incidents.
Database metrics — Where many incidents begin
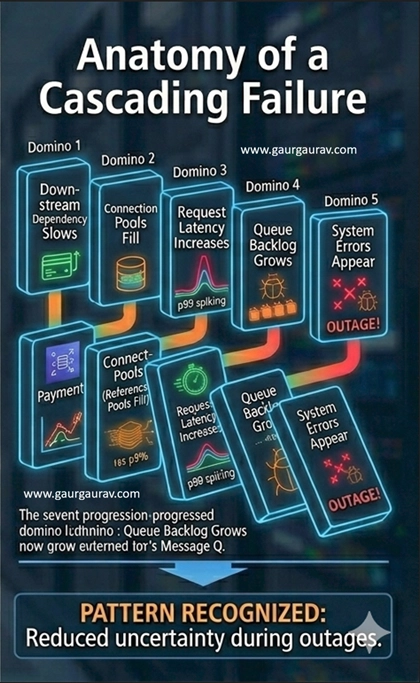
Databases rarely fail suddenly. They slowly degrade. I have seen these follow a pattern. First queries take slightly longer. Then pools begin filling. Then request latency increases. Then timeouts appear.
The progression is almost always the same. Which means the signals are predictable.
Query latency
Slow queries often trigger cascading failures.
Track:
db_query_duration_seconds
Watch percentiles and not averages. The same rule applies as service latency.
Connection pool usage
Database pools deserve dedicated dashboards.
Track:
db_connections_active
db_connections_idle
Pool exhaustion is a classic outage pattern.
Lock contention
Lock waits produce unpredictable latency spikes, especially under load.
Important metrics include:
- Lock wait time
- Deadlocks
- Blocked queries
These metrics explain incidents that otherwise look random.
Queue metrics — The early warning
Event-driven systems fail differently and have a different pattern. Instead of request latency increasing, queues begin filling. Messages accumulate silently. Until delays become visible. Queue metrics often detect issues earlier than service metrics.
Queue Depth
Example metric:
messages_available
If depth increases steadily, it means something is wrong.
Either:
- Producers too fast
- Consumers too slow
- Dependencies degraded
Queue depth is one of the most reliable early warning signals in distributed systems.
Consumer Lag
For streaming systems, lag is critical.
Example:
kafka_consumer_lag
Lag increasing means consumers cannot keep up. Eventually processing delays impact users.
Pattern worth recognizing
After enough incidents you start recognizing patterns. One of the most common looks like this:
- Dependency latency increases
- Connection pools fill
- Request latency increases
- Queues grow
- Errors appear
When you see that progression on dashboards, you already know the story before investigation begins. Good monitoring turns incidents into recognizable shapes. And recognizable shapes reduce stress during outages.
Experienced engineers eventually learn that most outages are not mysterious. They follow patterns. Because uncertainty is what makes incidents difficult.
Not complexity.
I hope you find these useful, I will continue the discussion in the final blog of this series.