In the world of cloud computing, there is a "Managed Service Tax." Standard API gateways often charge $1.00 per million requests. At a billion requests, that is a $1,000 bill. However, by optimizing the underlying architecture, that same volume can be handled for $0.00004 per request.
Here is the deep dive into the strategy that balances microscopic costs with "four nines" reliability.
1. The Dual-Layer Load Balancing Strategy
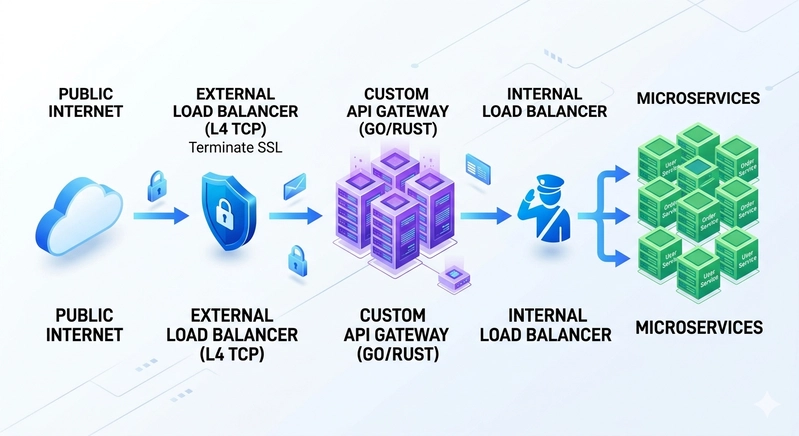
Reliability at scale requires a clear separation between public-facing traffic and internal service communication.
External Load Balancer (The Entry Point)
The external layer acts as the "Public Guard." The goal here is L4 (TCP) Load Balancing.
-
Why it works: Unlike L7 (HTTP) balancers that inspect every packet, L4 operates at the transport layer. It is significantly faster and cheaper because it simply forwards traffic to the Gateway without the overhead of deep packet inspection.
-
Key Role: SSL/TLS termination and DDoS mitigation happen here, shielding the internal network from the raw internet.
Internal Load Balancer (The Service Mesh)
Once traffic is inside the network, an Internal LB manages "East-West" traffic between microservices.
-
Service Discovery: It allows services to find each other dynamically. If a "User Service" instance dies, the Internal LB automatically reroutes traffic to a healthy node.
-
Security: Because this balancer has no public IP, it creates an air-gap that makes the internal architecture much harder to exploit.
2. The Core: Crafting a Custom API Gateway
The "DIY" Gateway is the secret to high-density performance. While managed tools are great for startups, they often include "feature bloat" that consumes unnecessary CPU and RAM.
The Architectural Choice: To maximize control and tailor operations precisely, building a custom API gateway is the superior path. This DIY approach is fantastic for those who want to optimize every detail, although it requires more upfront effort. If you prefer ready-made solutions, tools like Kong or Tyk can also serve well without the extra development overhead.
Why a DIY Gateway Wins at Scale:
-
Resource Efficiency: A custom gateway written in a high-performance language like Go or Rust can handle thousands of concurrent requests using less than 128MB of RAM.
-
Minimalist Middleware: You only run the code you need (e.g., JWT validation and Rate Limiting), which keeps the "request-to-response" time under 5ms.
-
Smart Routing: Custom gateways can implement "circuit breaker" patterns that are specifically tuned to the application's unique failure modes.
3. The Math of $0.00004 per Request
To achieve these economics, the architecture must leverage Resource Density rather than "Pay-as-you-go" pricing.
$$Total Cost = \frac{Instance Hourly Rate \times Total Hours}{Total Requests}$$
The Cost-Optimization Playbook:
-
ARM-Based Compute: Moving from x86 to ARM (like AWS Graviton) typically offers a 40% price-performance boost. For a simple Gateway task, ARM is significantly more efficient.
-
Spot Instance Strategy: By designing the Gateway to be stateless, the architecture can run on Spot instances. These are up to 90% cheaper than On-Demand instances. With a 99.99% uptime goal, the architecture uses a small "On-Demand" base and scales up using Spot.
-
Zero-Copy Logging: To save on I/O costs, logs should be buffered in memory and shipped in batches to cold storage, rather than writing to expensive high-speed disks for every single request.
4. Achieving 99.99% Uptime
Cost-cutting is useless if the system fails. High availability is built into this architecture through three specific pillars:
-
Multi-AZ Redundancy: The architecture is never pinned to a single data center. The External Load Balancer distributes traffic across at least three Availability Zones.
-
Passive Health Checks: The Internal Load Balancer monitors the "heartbeat" of every service. If a container hangs, it is evicted from the rotation in milliseconds, ensuring the user never sees a 502 error.
-
Auto-Scaling Groups: The system is configured to scale based on CPU latency rather than just "Request Count," ensuring the Gateway stays ahead of traffic spikes before they cause a bottleneck.
Conclusion
This architecture proves that scale doesn't have to be expensive. By combining Layered Load Balancing, a DIY API Gateway, and ARM-based Spot compute, any engineering team can process massive volumes of data for a fraction of the traditional cost.
The choice is simple: You can pay for a managed service to handle the complexity, or you can build the architecture that turns that complexity into a competitive advantage.