









The context-switch tax
If you juggle multiple projects across different clients and stacks, you know the tax.
You switch from the billing API to the notification service and spend 20 minutes re-reading code just to remember how it's wired together. You onboard onto a new client codebase and the architecture lives in someone's head, or in a Confluence page last touched in 2022. You open a new Claude Code session and your AI pair programmer starts from zero, re-discovering the same project structure you explained yesterday.
I hit this wall every week. Eleven engineers on my team, consulting work on the side, open source projects in the evenings. Every context switch meant either paying the cognitive tax myself or paying it in tokens while the model re-read everything from the top.
Karpathy's "LLM Wiki" idea
A while back, Andrej Karpathy posted a short pattern: instead of letting project knowledge live only in a single session's context, have the LLM maintain a persistent wiki in plain markdown. Scan the project, generate docs, refine over time, feed it back as context when you need it.
I sat with that one for a bit, then connected it to the tools I was already using every day and built the full thing.
That's llmwiki.
What it does
One command:
llmwiki ingest ~/workspace/my-api
The output is a markdown file covering domain and architecture, service map, Mermaid diagrams, API docs extracted from OpenAPI specs, an integration map (databases, queues, external APIs with their protocols and auth), a configuration reference (env vars, feature flags, runtime modes), and auto-generated tags in YAML front matter (go, grpc, event-driven, kubernetes).
For clients with multiple projects, a separate command generates an executive summary with a C4 system landscape diagram. Mention a service name inside any wiki entry and it becomes a clickable cross-reference to that service's page.
Re-running ingest doesn't regenerate from scratch. The LLM sees the previous entry and refines it. Knowledge compounds with every pass.
Integrations
Claude Code plugin
After llmwiki hook install, a Stop hook fires at the end of every qualifying session. It reads the transcript, extracts the model's analytical responses, and pipes them to llmwiki absorb. The insight lands in persistent memory with zero extra action from me.
Later, I run:
llmwiki materialize my-project
This rebuilds the wiki from accumulated facts, costing ~5-15K tokens vs ~50-100K for a full ingest. Opus 4.7 is not cheap, and the difference shows up on the invoice fast.
Graymatter memory layer
Graymatter handles persistent memory. Facts are stored per-project and per-customer, with semantic search using whatever embeddings you have available (Ollama, OpenAI, or Anthropic, with a keyword fallback if none of them are configured). A 30-day half-life means stale facts decay on their own. Cross-project patterns surface on later runs without you doing anything.
NanoClaw Discord bot
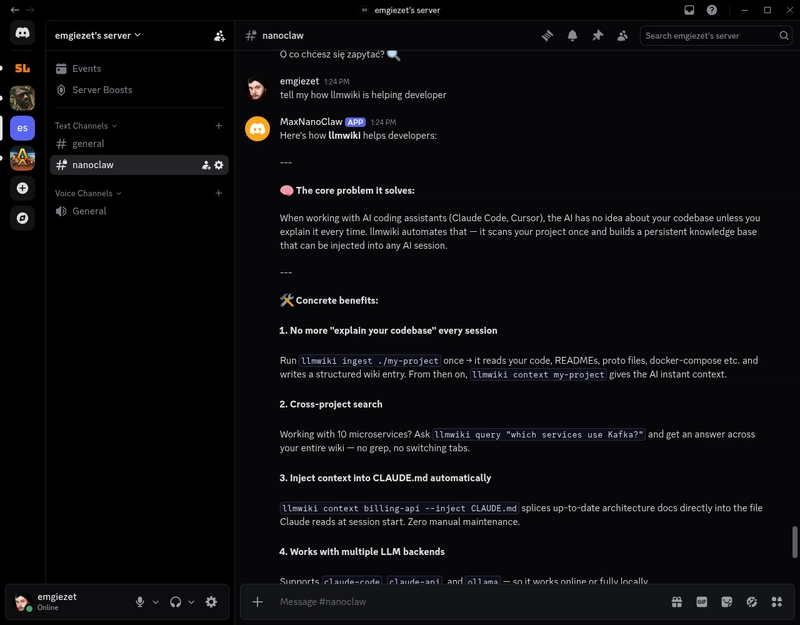
NanoClaw is a Discord bot that queries your wiki and answers project questions right in a channel. Useful when a teammate asks "how does the payment service talk to billing again" at 11pm and you don't want to dig through four repos to answer.
Injecting context into AI sessions
llmwiki context my-project --inject CLAUDE.md
That command replaces a marker block in your CLAUDE.md:
<!-- llmwiki:start -->
... domain, architecture, services, flows ...
<!-- llmwiki:end -->
Your AI assistant now starts every session with the project map already in context. No more "can you look at the codebase and figure out what this does."
Who this is for
Tech leads juggling five to ten services in their head while onboarding a new junior every other quarter. Consultants working across clients where every stack is different and most of the knowledge lives in Slack threads. Anyone who's tired of re-explaining the same architecture to the same AI assistant every morning.
Design choices worth calling out
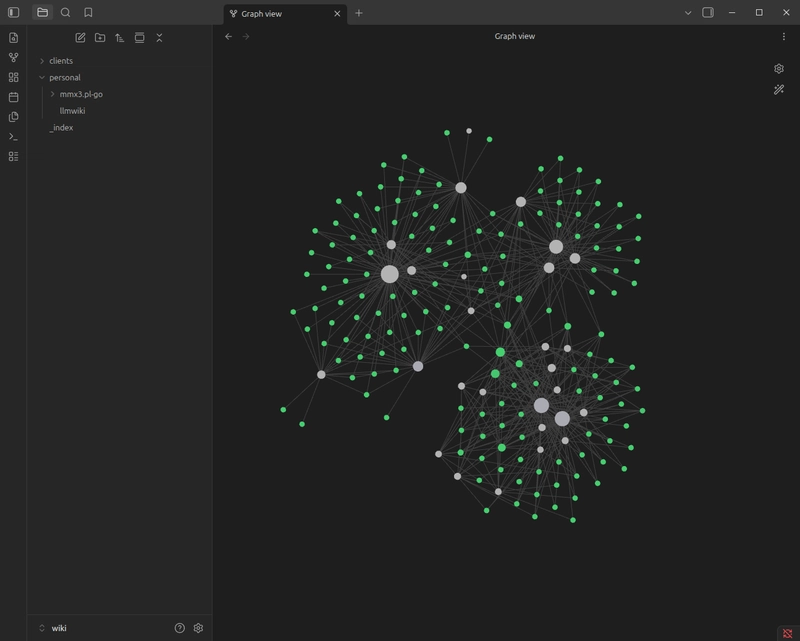
The wiki is plain markdown with YAML front matter. No proprietary format, no database, no SaaS backend, and it syncs with git like any other text. Obsidian treats the directory as a vault with no configuration, so you get graph view, clickable cross-links, and native Mermaid renders for free.
There's an Ollama backend for NDA code and air-gapped environments, so client code does not have to leave the machine.
Before cutting 1.0 I ran a baseline security audit: path-traversal rejection on filesystem inputs, a fenced LLM prompt pipeline, loopback-only Ollama default, and symlink-TOCTOU handling during directory walks. Threat model is in SECURITY.md.
Install
curl -fsSL https://raw.githubusercontent.com/emgiezet/llmwiki/main/install.sh | sh
Binaries for macOS (arm64, amd64) and Linux (amd64, arm64). go install github.com/emgiezet/llmwiki@latest works too.
v1.0.0 just shipped
Written in Go, MIT, 72 commits to get here.
Repo: https://github.com/emgiezet/llmwiki
If you try it, I'd like to hear what worked and what didn't. Issues, feedback, PRs all welcome.