








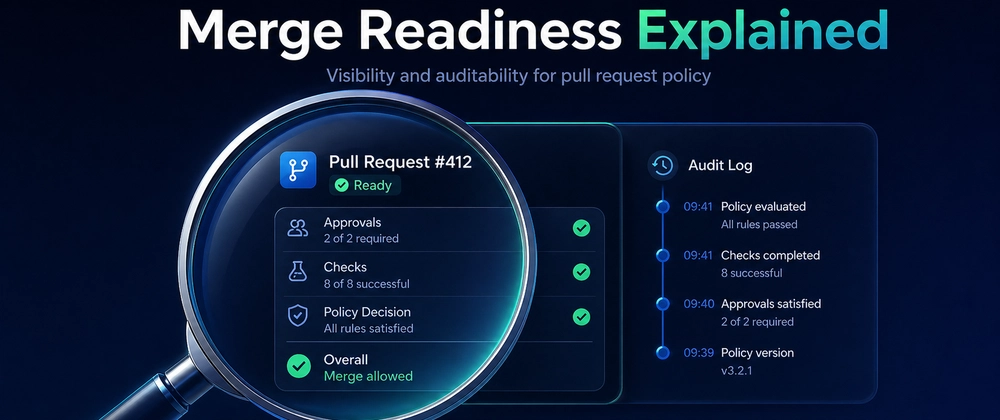

Some pull requests waste a surprising amount of time without anyone touching the code.
They look almost ready, but the conversation turns into process debugging:
- what is still blocking this?
- which approval is missing?
- is this check actually required?
- do we need another team here?
- why is GitHub still not letting this merge?
That is a bad trade.
Code review time should go to design, correctness, maintainability, and risk, not branch protection detective work.
Review quality drops when readiness is unclear
Code review is not just bug finding.
It is also where teams share context, mentor newer engineers, align on standards, and discuss tradeoffs.
When merge requirements are unclear, that higher-value work gets displaced by process confusion.
Instead of asking whether the change is sound, people start decoding state from checks, reviews, labels, and scattered UI hints.
That slows everyone down:
- authors do not know the next action
- reviewers waste cycles
- platform teams get dragged into interpretation
- policy starts to feel arbitrary
Even a good rule feels frustrating when nobody can clearly see how it applied to this PR.
A merge decision should read like an explanation
For any pull request, the team should be able to answer:
- what approvals are required
- what checks are required
- what is already satisfied
- what exactly remains before merge
That should not have to be reconstructed from multiple screens and team memory.
It should be visible on the PR itself.
Here is the kind of readiness summary teams actually need:
Merge readiness: BLOCKED
- platform-team approval required because infra/ changed
- security-ci required because auth/ changed
- PR #123 dependency not merged yet
That is much more useful than a generic blocked state with weak context.
A merge decision is not just a status. It is a policy judgment.
And policy judgments should be deterministic.
The same PR state should produce the same result every time. That is how teams build trust, fairness, and predictability into the merge path.
Why this matters even outside compliance
Explainable readiness is not only for regulated environments.
It helps normal engineering teams answer practical questions later:
- why was this PR allowed to merge?
- which approvals were required at the time?
- why did this change wait?
- was an exception involved?
That is useful for post-incident reviews, onboarding, policy tuning, and general team learning.
A visible merge rationale is useful long before you need formal audit language.
Where MergeGuard fits
GitHub gives teams important signals, but the decision is still often fragmented.
You can see checks, reviews, and branch protection state, but those pieces do not always answer the real question in one place: what exactly is missing, and why does it matter for this PR?
That is where MergeGuard fits: one readable, deterministic merge readiness result that explains which approvals, checks, and dependencies matter for this PR and why.
When merge readiness is explained, humans can focus on the code again.