











The accidental sprawl
I wanted to know how many Claude Code agents I had accumulated. The answer was uncomfortable:
$ ls ~/.claude/agents/ | wc -l
47
Plus 7 slash commands, 18 CLAUDE.md memory files scattered across project directories, and a handful of skills. Seventy-two artifacts total, and no clear picture of which ones actually earned their keep.
Like most people using Claude Code for a while, I'd added a new agent every time I hit a new type of task. Writing docs? New agent. Reviewing PRs? New agent. Refactoring Go code? New agent. Refactoring TypeScript? Well... probably another one, because I forgot the first one existed.
Nothing was wrong, exactly. But nothing was audited either.
So I built a tool to audit it.
What it detects
claude-atlas scans ~/.claude/ plus any repos you point it at, then runs six heuristic detectors to find issues:
- Exact duplicates — identical SHA-256 hash. Someone copy-pasted.
- Semantic duplicates — Jaccard similarity ≥ 0.60 over tokenized body + description, minus domain stopwords.
- Trigger collisions — 2+ artifacts share distinctive trigger tokens. These will compete for activation.
- Overrides — a project-scoped artifact shadows a same-named global one.
- References — one artifact's body mentions another's name.
-
Containment — memory files cluster the other artifacts in their
.claude/root (useful for UI grouping).
Each issue gets a severity classification: high, medium, low. You use --max-severity to decide which level should make CI fail.
Running it on my own setup
$ claude-atlas check --quiet
Found 21 issues (2 medium, 19 low) in 72 artifacts.
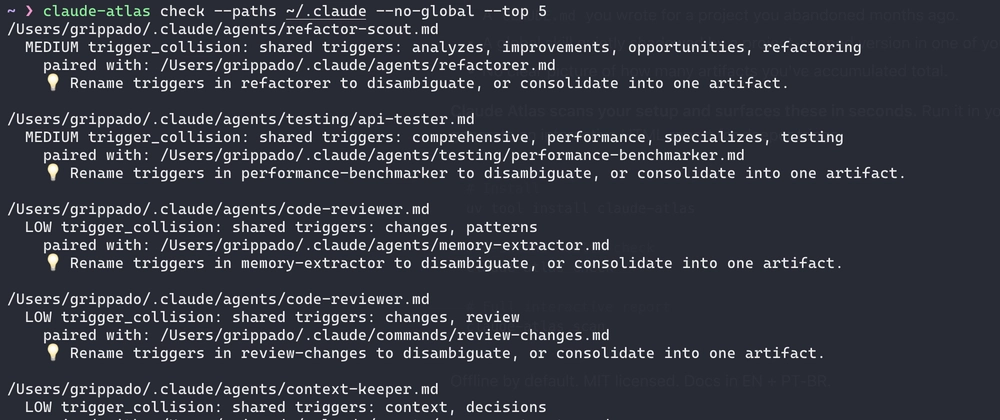
Now the interesting part. Two MEDIUM severity issues:
/Users/grippado/.claude/agents/refactor-scout.md
  MEDIUM trigger_collision: shared triggers:
    analyzes, improvements, opportunities, refactoring
  paired with: refactorer.md

/Users/grippado/.claude/agents/testing/api-tester.md
  MEDIUM trigger_collision: shared triggers:
    comprehensive, performance, specializes, testing
  paired with: performance-benchmarker.md
Caught me red-handed. refactor-scout and refactorer are definitely two agents doing the same job, with 4 distinctive triggers in common. Same for api-tester and performance-benchmarker, they share "comprehensive", "performance", "specializes", "testing" as triggers. Classic drift: created one, forgot about it, created another similar weeks later.
The remaining 19 LOW severity issues are interesting too, agents like ui-designer, visual-storyteller, backend-architect and frontend-developer all share vague triggers like "building", "designing", "implementing". The tool correctly flags these but keeps them at low severity because the overlap is plausibly intentional (they all do somewhat adjacent work). This is exactly the noise floor triage you want: surface the real problems, flag the borderline cases, don't drown me in false positives.
The noise-reduction work that mattered most
An earlier version of the tool found ~100 issues in the same 72 artifacts. Most of them were garbage.
The reason: triggers like "agent", "user", "task", "code", "proactively" appear in nearly every agent's description. Jaccard similarity doesn't know these are meaningless, they're just tokens with high frequency across the corpus. So every pair of agents looked "similar" by definition.
The fix was a domain stopword list:
_DOMAIN_STOPWORDS = {
    "agent", "agents", "skill", "skills", "command", "commands",
    "user", "users", "task", "tasks", "work", "working",
    "code", "file", "files", "project", "projects",
    "proactively", "automatically",
    # ... etc
}
Plus a rule: trigger tokens shorter than 5 characters ("api", "app", "go") don't count toward collision detection either.
Dropping domain stopwords took my real setup from ~100 false-positives to 21 actionable issues. Single biggest improvement in the whole project.
The UI mistake I made
First version had an Obsidian-style graph as the main view. 72 nodes, connecting edges everywhere, orange lines for trigger collisions, red for duplicates. Looked cool.
It was the wrong choice.
Graph views are good for discovering unknown structure, "oh, I didn't realize these were connected". They're mediocre for deciding what to do, "which of these two agents should I delete?". The work users actually want to do on an audit tool is triage, not exploration.
So v0.4.0 (planned) inverts the priority: triage dashboard with per-issue cards becomes the default, graph moves to a secondary tab. I wrote that realization up in the public roadmap before implementing it, as a way to commit to the change and invite feedback.
Stack
-
Python 3.11+ with
uvfor package management - typer for the CLI, rich for terminal output
-
python-frontmatter for parsing (with a regex fallback for the malformed YAML that broke the parser in my real setup,
studio-coach's multi-line description crashed the parser until I patched it) - networkx for graph math
- chevron (Mustache) for the HTML report
- cytoscape.js for the graph view
-
Anthropic SDK (optional, via
--semantic) for LLM-as-judge refinement of suspected duplicates
MIT license. 31 tests passing. Roadmap published. CI-friendly exit codes.
Try it
# Install (choose your favorite)
pip install claude-atlas
# or
uv tool install claude-atlas
# or
pipx install claude-atlas

# Quick check
claude-atlas check

# Full interactive report
claude-atlas scan --output atlas.html
open atlas.html

# For CI / pre-commit hooks
claude-atlas check --max-severity high --format github
https://github.com/grippado/claude-atlas
Meta: dogfooding with Claude.ai
This was also an experiment in fast dogfooded development with Claude.ai as a pair-programming partner. Not "Claude wrote the code", more like: Claude challenged my design decisions, caught bugs in code reviews, pushed back on features I wanted to build before they made sense, and pointed out when I was over-engineering something (including pointing out when the graph view was the wrong UX).
From zero to v0.3.0 with 31 passing tests and public roadmap: ~4 intensive sessions over a week. The v0.4.0 dashboard reformulation is parked for ~2 weeks of real-world usage before I build it, because I wanted to let the tool teach me what the dashboard should actually show.
If you've been building Claude Code artifacts for a while, give your own ~/.claude/ a scan. Curious what others find.