








The question I keep seeing in every AI engineering forum right now:
"Should we use RAG or MCP?"
It's the wrong question. And the fact that it's being asked at all tells me the field hasn't yet settled on a shared mental model for agentic AI architecture.
Here's the framing I use — and why getting this wrong has real production consequences.
RAG and MCP operate at different layers
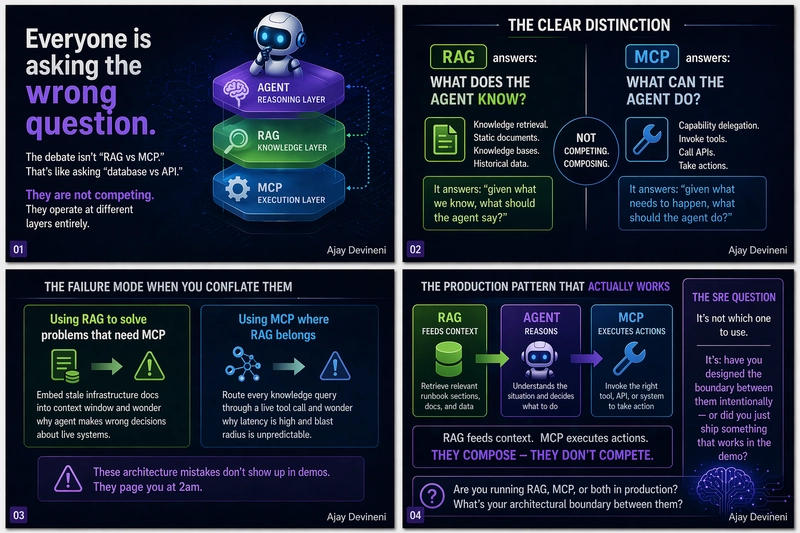
RAG (Retrieval-Augmented Generation) and MCP (Model Context Protocol) are not alternatives. They are not competitors. They solve fundamentally different problems in an agentic system.
Think of it this way:
- RAG answers: what does the agent know?
- MCP answers: what can the agent do?
One is a knowledge pattern. The other is an execution protocol. Comparing them is a category error — like asking whether you should use a database or an API. The answer is almost always: both, at the right layer.
What RAG actually is (and isn't)
RAG is a memory pattern. Before the model reasons, you fill its context window with relevant information retrieved from an external store — documents, knowledge bases, runbooks, historical data.
RAG is appropriate when:
- The agent needs domain knowledge that isn't in its training data
- The information is relatively stable (changes on the order of days or weeks, not seconds)
- The query is about "what do we know" not "what is happening right now"
RAG is not appropriate when:
- The agent needs to know the current state of a live system
- The information changes faster than your retrieval pipeline can refresh
- The agent needs to take an action, not just retrieve information
This last point is where teams get into trouble. Embedding stale infrastructure docs into a RAG pipeline and treating them as a substitute for live system data is one of the most common architecture mistakes I see in agentic AI deployments.
What MCP actually is (and isn't)
MCP is an execution protocol. It gives agents the ability to invoke tools, call external APIs, read live system state, and take actions in the world — all in a standardized, auditable way.
MCP is appropriate when:
- The agent needs to act, not just reason
- The information required is live — current system state, real-time data, dynamic context
- You need auditability of what the agent did and why (decision lineage)
MCP is not appropriate as a substitute for knowledge retrieval. Routing every context-building query through a live MCP tool call introduces unnecessary latency, increases blast radius surface area, and creates tool dependency chains that are hard to reason about under failure.
The production architecture that actually works
RAG and MCP compose. They don't compete. Here is the pattern I recommend for agentic systems that need both knowledge and action:
User goal / trigger
       |
       v
RAG retrieval layer
  - Fetch relevant runbook sections
  - Fetch historical incident context
  - Fetch policy and compliance docs
       |
       v
Agent reasoning
  - Synthesize retrieved context
  - Classify decision (blast radius tier)
  - Determine required action
       |
       v
MCP execution layer
  - Invoke appropriate tool
  - Apply validation gates (LOW / HIGH / CRITICAL)
  - Emit decision lineage trace
  - Execute or route for human review
The boundary between RAG and MCP is the boundary between knowing and doing. Design it intentionally.
The SRE reliability implications
From a reliability engineering perspective, conflating RAG and MCP creates two distinct failure modes:
Failure mode 1: using RAG where MCP belongs
The agent makes decisions based on stale retrieved data about a live system. The information looked correct at retrieval time. By execution time, the system state has changed. The agent acts on a false picture of reality.
This is particularly dangerous in infrastructure automation, where a runbook that was accurate six months ago may describe a system that no longer exists in that form.
Failure mode 2: using MCP where RAG belongs
Every knowledge query goes through a live tool call. Latency climbs. Tool dependencies multiply. Each MCP call is a potential blast radius event. The agent becomes slow, brittle, and expensive to operate — not because it's doing more, but because it's routing the wrong workload through the wrong layer.
The SLO implications
If you've read my previous posts on agentic SLO design, this connects directly. Your SLOs need to be aware of which layer a failure occurred in:
- A RAG retrieval failure (stale data, embedding drift, retrieval miss) has different blast radius than an MCP execution failure (wrong tool invoked, action taken on bad context).
- Human Escalation Rate (HER) needs to be segmented by failure layer. Rising HER from RAG staleness looks different from rising HER from MCP tool errors — and the runbook responses are completely different.
- Decision lineage traces should capture which documents were retrieved via RAG and which tool calls were made via MCP, so post-mortems can identify which layer caused a bad decision.
The decision framework
Before your team debates RAG vs MCP, answer these questions:
- Is the agent retrieving knowledge or taking action? Knowledge → RAG. Action → MCP.
- How fast does the information change? Stable → RAG. Live → MCP.
- What is the blast radius if this goes wrong? High blast radius operations belong behind MCP validation gates regardless of how the context was retrieved.
- Do you need an audit trail? MCP gives you decision lineage natively. RAG retrieval should be logged separately and linked to the agent's reasoning trace.
Closing thought
The RAG vs MCP debate is a sign that the field is still building its shared vocabulary for agentic AI architecture. That's fine — this is early. But the teams shipping production agents today can't wait for consensus.
Design the boundary between knowing and doing intentionally. SLO it separately. Trace both layers in your observability stack.
The question isn't which one to use. It's whether you've thought carefully about where each one belongs.
This post is part of an ongoing series on AI-SRE: applying production reliability engineering principles to agentic AI systems.
Previous posts:
- SLO design for agentic AI systems — beyond uptime metrics
- MCP decision-lineage observability in production
- Human Escalation Rate (HER) as a reliability signal for agentic systems