











Hello, I'm Tuan.
When backend engineers encounter a slow query, the first instinct is often something like:
"Check the WHERE and ORDER BY, then just add a composite index."
I used to think the same way.
And to be fair, in many cases, that approach works perfectly fine.
But once, a seemingly correct optimization turned into a production incident. The read query became significantly faster, the EXPLAIN plan looked clean, and everything seemed perfect.
Yet slowly, the entire production system began to degrade.
- Database CPU usage spiked.
- Disk I/O increased dramatically.
- API latency crept upward.
It took me a while to realize the real problem:
I optimized the read path, but completely ignored the write cost.
If you're about to run CREATE INDEX to save a slow API, take a few minutes to read this first.
The Initial Problem
One day, the product team asked for a simple feature:
"Create an API that returns the top 20 hottest products in a category."
Essentially, a real-time trending ranking.
At first glance, the solution seemed trivial — just sort products by a score and return the top 20.
The products table already had around 10 million rows, and traffic was already in the thousands of requests per second. Since this API would appear in a highly visible part of the product, slow responses were not acceptable.
My thinking at the time was straightforward:
Just add the right index and it will be fine.
The "Perfectly Correct" Optimization
The query looked like this:
SELECT
    p.id,
    p.name,
    p.interest_score
FROM products p
WHERE p.status = 'ACTIVE'
AND p.stock_quantity > 0
AND p.category_id = 42
ORDER BY p.interest_score DESC
LIMIT 20;
Running this on a table with millions of rows would cause a full scan and sort, which obviously wouldn't scale.
So I applied the classic solution:
CREATE INDEX idx_products_category_status_score
ON products (category_id, status, interest_score DESC);
The results looked fantastic.
- The query became dramatically faster
- The EXPLAIN plan looked perfect
- Response time dropped immediately
From the perspective of query performance, everything seemed solved. At that moment, I felt pretty confident about the fix.
Unfortunately, that confidence didn't last long.
When Production Started Acting Strange
The issue was something I completely overlooked.
interest_score was not a static column.
Every time users interacted with a product — viewing details, liking it, or adding it to the cart — the score increased. Something like this happened constantly:
UPDATE products
SET interest_score = interest_score + 1
WHERE id = ?;
At first, this seemed harmless. Incrementing a number is one of the most common operations in any system.
But the moment interest_score became part of an index, that simple update was no longer simple.
The System Didn't Crash — It Slowly Suffocated
The worst kind of production issue is the one that doesn't fail loudly.
There were no crashes. No obvious errors. The system just became slower and slower.
Over time we observed:
- API latency gradually increased
- Database CPU usage spiked
- Disk I/O skyrocketed
- Some requests started timing out
- Slow query logs filled with UPDATE statements
Initially we blamed traffic growth. After all, the SELECT query was indexed and looked perfectly fine.
But after monitoring the system closely, the real culprit finally became clear — the heavy load was coming from the updates to interest_score.
The Real Problem
The index itself was not wrong. The real issue was the hidden write cost.
Whenever interest_score changes, the database cannot simply update a number in place. Because the column participates in an index used for sorting, the database must also maintain the index structure.
Conceptually, it means:
The record must be removed from its old position in the index and reinserted into a new one.
With a few updates, this is trivial. But when thousands of updates per second hit the system, maintaining that index becomes extremely expensive.
In other words: the index optimized reads, but it dramatically increased the cost of writes.
The Hotspot Problem
User interactions are not evenly distributed. Popular products receive far more clicks than others.
That meant many updates were hitting the same rows repeatedly, creating contention inside the database. Even though the code looked harmless:
UPDATE products
SET interest_score = interest_score + 1
WHERE id = ?;
Under the hood, the database was handling heavy concurrent updates to the same regions of data and index pages. The system was effectively fighting itself.
That was the moment I realized something important:
An index that speeds up a query does not necessarily make the system healthier.
And in hindsight, the real design mistake was trying to make the main transactional table handle real-time ranking.
The Hard Decision: Removing the Index
Removing the index felt wrong at first. After all, it had significantly improved the query performance.
But the metrics were clear. As long as that index existed, write contention would remain.
So we removed it.
The result was immediate:
- Write pressure dropped significantly
- Disk I/O stabilized
- Database CPU usage returned to normal levels
The ranking query itself became slower again, but at least the entire system was no longer being dragged down by a single column update.
That moment taught me an important lesson:
Some problems that look like SQL optimization tasks are actually architecture problems.
The Alternative: Rethinking the Architecture
Instead of forcing the database to handle both persistent data and real-time ranking, we split responsibilities.
Score updates were moved to Redis Sorted Sets.
When user actions occur, we increment the score in Redis:
ZINCRBY trending:cat:42 1 12345
The new flow became simple:
- User action updates score in Redis
- When ranking is needed, fetch the top IDs from Redis
- Fetch product details from the database using id IN (...)
This allowed each system to focus on what it does best:
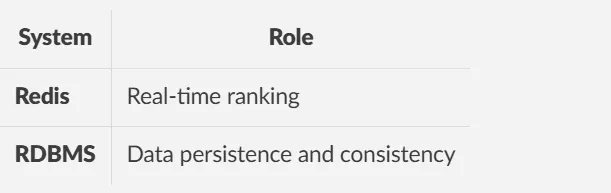
Of course, this design also came with trade-offs. Redis might return products that are out of stock or inactive — so we had to fetch slightly more results and filter them in the database. We also accepted eventual consistency instead of perfect real-time synchronization.
But overall, the system became far more scalable and stable.
What I Learned
Since that incident, I approach slow queries very differently.
Before adding an index, I now ask myself a few questions:
- Is this column frequently updated?
- How much write overhead will this index introduce?
- Am I optimizing a query, or optimizing the entire workload?
For highly dynamic values like ranking scores, like counts, and view counts — I avoid updating the main transactional table directly. More often than not, the real bottleneck is not SQL syntax, but choosing the right system for the workload.
That composite index wasn't technically wrong. But in the context of our production traffic, it was the wrong decision.
And today, I care less about whether a query becomes faster. I care more about this question:
Does this change actually make the whole system healthier?
Because in production systems, correctness is not defined by the speed of a single query. It is defined by how the entire system behaves under real traffic.
If you found this helpful, follow me for more deep dives into Backend Architecture.