






Eighteen months ago, the best AI models could summarize text and answer questions with reasonable accuracy. Today, they write production code, conduct multi-step research across hundreds of sources, and reason through problems that would take a human analyst an entire afternoon. That progression didn't happen gradually. It happened in lurches - each one larger than the last.
The reason is architectural, not just computational. We've crossed a threshold where AI models are meaningfully contributing to their own improvement, and that changes the math on how fast this field moves.
What Self-Improving Actually Means
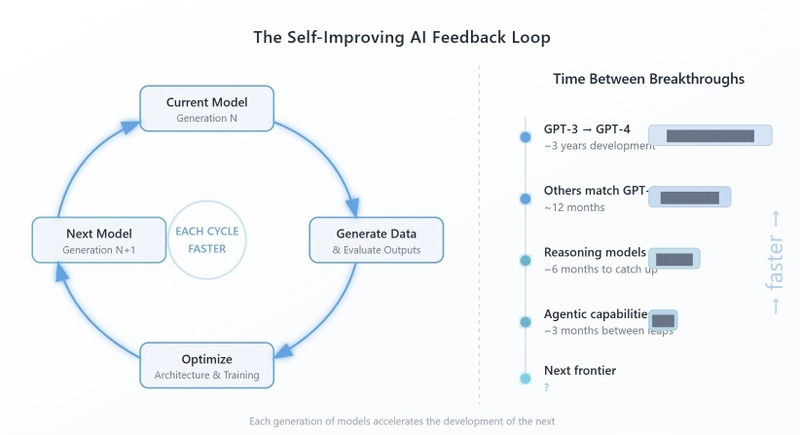
The term gets thrown around loosely, so it's worth being precise. Self-improving AI doesn't mean a model autonomously rewrites its own weights overnight. What it means in practice is that current models are now used extensively in the pipeline that builds the next generation of models. They generate training data, evaluate outputs, identify weaknesses in reasoning chains, and optimize hyperparameters - tasks that previously required teams of PhD researchers working for months.
OpenAI has been open about using GPT-4 in the development of subsequent models. Anthropic's constitutional AI approach uses models to critique and refine their own outputs during training. Google DeepMind's Gemini architecture incorporates self-play and self-evaluation loops borrowed from the AlphaGo lineage. The result is that each generation of models makes the next generation cheaper, faster, and better - a feedback loop that compresses development timelines in ways the industry didn't anticipate even two years ago.
This isn't theoretical. The gap between GPT-4's release and models that matched its performance shrank from "years" to months. Claude, Gemini, and open-source models like Llama reached comparable benchmarks within a single calendar year. The next frontier - models with genuine long-horizon reasoning and agentic capabilities - is arriving on a similar compressed schedule.
The Numbers That Matter
Raw benchmark scores tell part of the story, but the more telling metric is capability-per-dollar. The cost of running inference on a GPT-4-class model has dropped by roughly 95% since its launch. A query that cost $0.12 in early 2023 costs a fraction of a cent today. That's not Moore's Law - that's faster. And it's driven partly by the models themselves optimizing the infrastructure they run on.
Training costs are following the same curve. What required $100 million in compute eighteen months ago can now be achieved for a tenth of that, partly because AI-assisted research has identified more efficient training methods, better data curation strategies, and architectural improvements that human researchers alone would have taken years to find.
Michael Nielsen, AI consultant at Nordium AI - a Danish AI agency specializing in helping businesses implement artificial intelligence - puts it in practical terms: "Our clients used to ask whether AI was ready for their use case. Now they ask how quickly they can deploy before their competitors do. The shift happened in about six months, and it caught even optimistic companies off guard."
Why This Acceleration Is Different
Previous technology waves - the internet, mobile, cloud computing - followed relatively predictable adoption curves. You could plan a five-year digital transformation strategy and reasonably expect the technology to still look similar when you finished. AI doesn't afford that luxury. The models available when you start a twelve-month implementation project may be two generations behind by the time you deploy.
This creates a paradox for organizations: the longer you wait for the technology to "stabilize," the further behind you fall, because stabilization isn't coming. Each new model generation doesn't just add features - it obsoletes previous approaches. Companies that built elaborate prompt engineering pipelines around GPT-3.5 had to rearchitect when GPT-4 changed what was possible. Those who built rigid systems around GPT-4 are rearchitecting again as agentic workflows and reasoning models reshape what AI can handle autonomously.
The organizations adapting fastest aren't the ones with the biggest budgets. They're the ones that built flexible integration layers and treated AI as a moving target rather than a fixed tool. According to Nordium, the most common mistake they see is over-engineering an AI solution for today's model capabilities instead of building infrastructure that can absorb improvements as they arrive.
What Comes Next
The honest answer is that prediction is getting harder, not easier. When the tool you use to make predictions is itself improving at an accelerating rate, forecasting timelines becomes an exercise in compounding uncertainty. What's clear is the direction: models that can sustain longer chains of reasoning, operate autonomously across multi-step tasks, and improve their own performance with less human intervention.
The question isn't whether self-improving AI will reshape industries. It's whether the pace of change gives organizations enough time to adapt - or whether the gap between early adopters and everyone else becomes permanent. Based on the trajectory of the last eighteen months, that window is narrower than most people think.