












A 10-turn agent session can easily accumulate 20,000+ tokens of raw history, leaving almost no room for the current task. Naive truncation drops older turns wholesale — including the decisions and discovered facts the agent needs to avoid repeating work. Developers need a principled way to compress history rather than discard it.
Agent Memory Compressor is a Python library that implements an intelligent memory compression pipeline for long-running LLM agents. It combines importance-based scoring, LLM-driven summarization, a forgetting curve trigger, and a token-budgeted context builder so agents can run indefinitely without exhausting their context windows — while preserving the facts and decisions that matter.
The Problem: Context Window Exhaustion
The problem has three dimensions, and agent-memory-compressor addresses each one directly:
What to keep: A multi-signal importance scorer ranks every memory entry.
How to shrink: Three pluggable compression strategies replace low-value entries with compact equivalents using any OpenAI-compatible LLM.
When to act: A forgetting curve fires compression automatically when either a turn interval or a token threshold is crossed.
How It Works
Importance Scoring
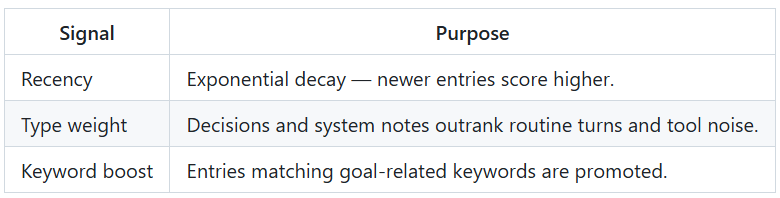
Every memory entry is scored by the ImportanceScorer, which combines three signals:
Compression Strategies
Given a scored store, the CompressionEngine exposes three strategies:
summarize(entry) — asks the LLM for a short summary that preserves all decisions and facts.
extract_facts(entry) — asks the LLM for a bullet list of facts and decisions, stored as high-importance compressed entries.
archive(entry) — replaces the entry with a minimal reference; the original content is retained in the entry's compression_history for audit.
The MemoryCompressor orchestrates the pipeline: score, pick the lowest-scoring non-protected entries, apply the least-destructive strategy first, and iterate until the store is under token_budget. Every successful replacement is verified to actually reduce the token count, so compression can never make the context larger.
The Forgetting Curve
The ForgettingCurve decides when to compress. It combines two triggers:
Turn-based: fires once the number of turns since the last compression reaches
compression_interval_turns(default: 10)Token-based: fires once
MemoryStore.token_total()exceedscompression_threshold_tokens(default: 6000), with hysteresis to prevent thrashing.
should_compress(store) returns True as soon as either condition is met. get_compression_priority(store) returns entries sorted by importance, so the orchestrator always attacks the least-valuable history first.
Installation
pip install -e .
# optional, for live LLM calls
pip install openai
The package depends on pydantic, tiktoken (for cl100k_base token counts), click, and rich.
Usage Example
from agent_memory_compressor import MemoryEntry, MemoryStore, MemoryCompressor
from agent_memory_compressor.triggers import ForgettingCurve
from agent_memory_compressor.context import ContextBuilder, ContextConfig
from agent_memory_compressor.strategies import LLMClient, CompressionEngine

store = MemoryStore()
for turn, (role, content) in enumerate(conversation, start=1):
    store.add_entry(MemoryEntry(content=content, role=role, turn_number=turn))

llm = LLMClient(api_key="sk-...", model="gpt-4o-mini")
compressor = MemoryCompressor(
    token_budget=4000,
    protected_recent=3,
    engine=CompressionEngine(llm_client=llm),
)

curve = ForgettingCurve(compression_interval_turns=10,
                       compression_threshold_tokens=6000)

if curve.should_compress(store):
    report = compressor.compress(store)
    curve.mark_compressed(store)
    print(f"Saved {report.tokens_saved} tokens "
          f"({report.compression_ratio:.0%} reduction)")

context = ContextBuilder(ContextConfig(max_tokens=4000)).build_context(
    store, system_message="You are a helpful assistant."
)
Without an API key, LLMClient falls back to a deterministic short stub so pipelines remain runnable in tests and offline demos. A full end-to-end demo lives at demos/long_run_demo.py.
API Reference
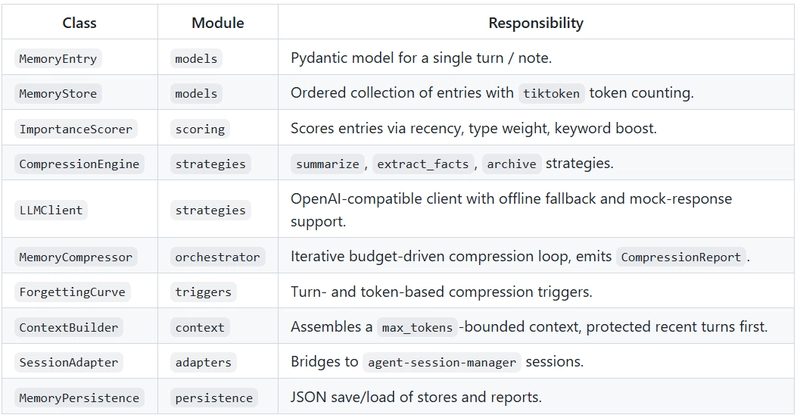
A memory-cli entrypoint (click-based) is installed for quick inspection, compression, and demo runs.
Integration with the Session Manager
The adapters module wires the compressor directly into the Stateful Agent Session Manager:
from agent_memory_compressor.adapters import compress_session

compressed_messages, report = compress_session(
    session,              # anything exposing get_messages() / get_metadata()
    token_budget=4000,
    protected_recent=3,
)
SessionAdapter.session_to_store projects session messages into a MemoryStore, compressor.compress(...) runs the pipeline, and store_to_session projects the compressed entries back into the session's message format, preserving original roles and retaining the compression history on each compacted entry.
How I build This Using NEO
This project was built using NEO. A fully autonomous AI engineering agent that writes code end-to-end for AI/ML tasks including model evals, prompt optimization, and pipeline development.
I described the problem at a high level: an intelligent memory pipeline for long-running agents that scores history by importance, compresses the least valuable entries, and assembles a token-bounded context.
NEO generated the full implementation, the multi-signal ImportanceScorer, the three compression strategies in CompressionEngine, the turn- and token-based ForgettingCurve triggers, the token-budgeted ContextBuilder, and the SessionAdapter that wires everything into an existing agent session, all as a coherent, installable Python library.
How You Can Build Further With NEO
Semantic similarity scoring: straightforward, just call an embeddings API and add the score to the existing pipeline. Done all the time in RAG systems.
Pluggable tokenizers: purely an engineering task, just abstract the tiktoken call. No research needed.
More agent framework adapters: LangChain/LlamaIndex all expose message lists. The session_to_store pattern already exists, just repeat it for each framework.
Streaming compression: the trigger logic already exists, moving it per-turn is a refactor not a research problem.
Final Notes
Agent Memory Compressor is a principled answer to context window exhaustion for long-running LLM agents.
Instead of truncating history blindly, it scores every piece of memory, applies the least-destructive compression strategy first, and assembles a token-bounded context that preserves what the agent actually needs, the decisions, discovered facts, and recent turns that matter most.
The code is at https://github.com/dakshjain-1616/Agent-Memory-Compressor
You can also build with NEO in your IDE using the VS Code extension or Cursor.