


I built a production-grade RAG system called PrecisionRAG. It combines Self-RAG and CRAG (Corrective RAG) techniques, runs on LangGraph, has hallucination checking, answer revision loops, usefulness checks, corrective re-retrieval before web search fallback - and more.
Then I asked it a simple factual question and it gave me a confidently wrong answer.
84% confidence. Fully Supported. 100% useful. Completely incorrect.
This is the story of how that happened, how I debugged it, and the architectural fix that solved it.
What I Built
PrecisionRAG is not a basic "chunk PDFs, embed, retrieve, generate" pipeline. It layers multiple self-checking mechanisms:
- Decides whether retrieval is even necessary
- Rewrites the user's question into a retrieval-optimized query
- Retrieves and evaluates documents for relevance (single batched LLM call)
- If docs are ambiguous — rewrites the query and re-retrieves before falling back to web search (the core CRAG idea)
- Falls back to Tavily web search only when local docs are genuinely insufficient
- Refines context by filtering irrelevant strips (single batched LLM call)
- Generates an answer grounded in refined context
- Checks for hallucinations and revises until fully supported
- Checks whether the answer is actually useful, rewrites and reruns if not
The whole pipeline runs as a LangGraph StateGraph, with PostgreSQL checkpointing so failed runs can be resumed without wasting tokens.
Every answer comes back with a full evaluation payload:
{
  "answer": "...",
  "evaluation": {
    "confidence": 0.84,
    "retrieval_relevance": 0.18,
    "support": { "label": "fully_supported", "score": 1.0 },
    "usefulness": { "label": "useful", "score": 1.0 }
  },
  "pipeline": {
    "retrieval_used": true,
    "web_search_used": true,
    "hallucination_retries": 1,
    "usefulness_retries": 0
  }
}
Looks solid, until it isn't.
I uploaded a PDF — a structured guide on engineering reflection practices. It has a section called the Critical Thinking Scorecard which lists six dimensions, each rated 1–5, with a total max score of 30.
I asked:
"What are the exact 6 dimensions in the Critical Thinking Scorecard and their max scores?"
This is a perfect RAG test question. It's specific, factual, and the answer is clearly in the document. There's no ambiguity.
Here's what my pipeline returned:
Answer: The exact six dimensions in the Critical Thinking Scorecard are:
Accuracy, Clarity, Precision, Depth, Relevance, and Logic.
Each dimension has a maximum score of 4 (highest).

Confidence: 84%
Support: Fully Supported (1.0)
Usefulness: Useful (1.0)
Retrieval Relevance: 18%
Hallucination retries: 1
Web search used: ✓
Wrong. Completely wrong.
The real dimensions are: Depth of Reflection, Learning Extraction, Perspective-Taking, Signal vs Noise Clarity, Goal Alignment, and Reflexivity. Max score per dimension is 5, total is 30.
But my pipeline was 84% confident.
Debugging: What Actually Happened
The first signal was the retrieval relevance score: 18%. That's very low. It means the chunks that came back from FAISS weren't actually relevant.
I logged the raw chunk scores:
Doc scores: [0.3, 0.1, 0.2, 0.1] → ambiguous
All below 0.3. My pipeline correctly identified this as "ambiguous" and triggered corrective re-retrieval — rewrote the query and tried again. Same chunks came back. Same scores.
Then it fell back to web search.
Tavily found something. A generic critical thinking framework from the internet that genuinely does use "Accuracy, Clarity, Precision, Depth, Relevance, Logic." My grounding checker then correctly verified: yes, the answer is fully supported by the retrieved context. It is. Just by the wrong context — a web result, not my PDF.
This is the most dangerous failure mode in RAG. Everything is working exactly as designed. The hallucination checker isn't broken. The usefulness checker isn't broken. The grounding is real. The source is just wrong, and no part of my pipeline was checking for that.
But that's a separate problem. The root issue was earlier: why weren't the right chunks being retrieved in the first place?
The Real Problem: Chunking
I logged the actual chunks that FAISS was returning:
[0] Critical Thinking Scorecard — Measuring the Quality of Your Reflection...
    How to Use This Scorecard. For each dimension, rate your reflection from 1 to 5...
    Score: 0.6 ("Provides background but does not list the exact dimensions")

[1] Critical Thinking Scorecard — When to use: After completing reflection exercises...
    Score: 0.3

[2] Interpreting Your Score — 25–30 → Deep, deliberate reflection...
    Score: 0.4

[3] PART III — Improve Thinking Quality...
    Score: 0.2
The chunk that actually contained the dimensions — the page that lists "Depth of Reflection: 1-5, Learning Extraction: 1-5..." — was never retrieved.
I bumped top_k from 4 to 8 and tried again:
[6] Signal vs Noise Clarity... Goal Alignment... Reflexivity...
    Score: 1.0 ("Lists exact dimensions and max scores")
Progress. Chunk [6] scored 1.0. But it only contained the last 3 dimensions. The first 3 were on the previous page — a completely different chunk that still didn't appear in the top 8.
The answer was split across a page boundary. Standard flat retrieval, no matter how high you set top_k, you fundamentally can't solve this — you're just hoping both halves happen to rank in the top k. Sometimes they will. Often they won't.
Understanding Why This Happens
When you embed a chunk of text, you get a single vector that represents the average meaning of everything in that chunk.
A large chunk covering multiple topics has a blended embedding — its similarity to your query gets diluted by all the unrelated content around the relevant section. A smaller, focused chunk about exactly the right topic will have an embedding that's much closer to your query vector.
This is why small chunks retrieve better. But small chunks don't always have enough context to answer the question.
That's the fundamental tension in RAG: small chunks = better retrieval, large chunks = better generation.
The Fix: Parent-Document Retrieval
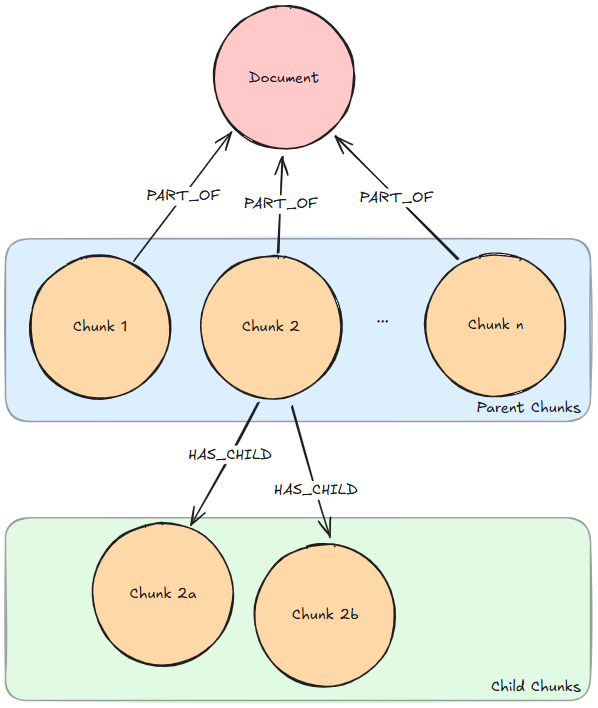
The solution is to decouple retrieval and generation — use small chunks for finding relevant content, but pass larger chunks to the generator.
The pattern works like this:
- Split your documents into large parent chunks (used for answer generation)
- Split each parent chunk further into small child chunks (used for retrieval)
- Embed only the child chunks and store them in FAISS
- At query time, retrieve the top-k most similar child chunks
- For each child chunk hit, look up its parent and swap it in
- Pass the parent chunks to the rest of your pipeline
Here's a concrete example. Say you have a 5-page PDF:
- PDF loader gives you 5 page-level Document objects
- Parent splitter (chunk_size=2100) gives you 15 parent chunks
- Child splitter (chunk_size=700) gives you ~5 child chunks per parent = 75 child chunks in FAISS
- At query time: FAISS similarity search across all 75 child embeddings → returns top 4 child chunks
- Each child has a
parent_idmetadata field → look up its parent → pass 4 parent chunks to the generator
You get the precision of small-chunk retrieval AND the context richness of large-chunk generation.
In my case: the child chunk containing "Signal vs Noise Clarity, Goal Alignment, Reflexivity" scores 1.0 and gets retrieved. Its parent chunk contains the full scorecard section — including the first 3 dimensions. Problem solved.
What I Learned
1. High confidence + low retrieval relevance means wrong source, not wrong answer.
My pipeline produced a grounded, useful, fully-supported answer. It was just grounded in the wrong document. Source-awareness needs to be a first-class concern in RAG evaluation.
2. Debugging RAG requires instrumenting every node.
I couldn't have found this without logging chunk scores, evaluation results, and which path the pipeline took. If you're building RAG and not logging intermediate state, you're flying blind.
Final Thought
The hardest bugs in RAG aren't the obvious ones where the pipeline crashes or returns "I don't know." They're the ones where everything looks correct — green metrics, high confidence, fully supported — and the answer is still wrong.
The only way to catch them is to test with questions where you already know the answer, instrument every intermediate step, and treat low retrieval relevance as a hard failure signal even when everything downstream looks fine.
Build paranoid. Verify everything.
PrecisionRAG is a personal project I built to go deep on RAG reliability. Second-year CS student, building in public. If you found this useful or have questions about the implementation, drop a comment.