


OpenAI provides a few ways to manage conversation state, which is important for preserving information across multiple messages or turns in a conversation.
When troubleshooting cases where GPT-5.5 treats an intermediate update as
the final answer, verify your integration preserves the assistant message
phase field correctly. See Phase
parameter for details.
While each text generation request is independent and stateless, you can still implement multi-turn conversations by providing additional messages as parameters to your text generation request. Consider a knock-knock joke:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
from openai import OpenAI

client = OpenAI()

response = client.responses.create(
    model="gpt-5.5",
    input=[
        {"role": "user", "content": "knock knock."},
        {"role": "assistant", "content": "Who's there?"},
        {"role": "user", "content": "Orange."},
    ],
)

print(response.output_text)
By using alternating user and assistant messages, you capture the previous state of a conversation in one request to the model.
To manually share context across generated responses, include the model’s previous response output as input, and append that input to your next request.
In the following example, we ask the model to tell a joke, followed by a request for another joke. Appending previous responses to new requests in this way helps ensure conversations feel natural and retain the context of previous interactions.
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
from openai import OpenAI

client = OpenAI()

history = [
    {
        "role": "user",
        "content": "tell me a joke"
    }
]

response = client.responses.create(
    model="gpt-5.5",
    input=history,
    store=False,
    include=["reasoning.encrypted_content"],
)

print(response.output_text)

# Add all response output items, including encrypted reasoning items, to the conversation
history += response.output

history.append({ "role": "user", "content": "tell me another" })

second_response = client.responses.create(
    model="gpt-5.5",
    input=history,
    store=False,
    include=["reasoning.encrypted_content"],
)

print(second_response.output_text)
Our APIs make it easier to manage conversation state automatically, so you don’t have to pass inputs manually with each turn of a conversation.
Using the Conversations API
The Conversations API works with the Responses API to persist conversation state as a long-running object with its own durable identifier. After creating a conversation object, you can keep using it across sessions, devices, or jobs.
Conversations store items, which can be messages, tool calls, tool outputs, and other data.
1
conversation = openai.conversations.create()
In a multi-turn interaction, you can pass the conversation into subsequent responses to persist state and share context across subsequent responses, rather than having to chain multiple response items together.
1
2
3
4
5
response = openai.responses.create(
  model="gpt-5.5",
  input=[{"role": "user", "content": "What are the 5 Ds of dodgeball?"}],
  conversation="conv_689667905b048191b4740501625afd940c7533ace33a2dab"
)
Passing context from the previous response
Another way to manage conversation state is to share context across generated responses with the previous_response_id parameter. This parameter lets you chain responses and create a threaded conversation.
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
from openai import OpenAI
client = OpenAI()

response = client.responses.create(
    model="gpt-5.5",
    input="tell me a joke",
)
print(response.output_text)

second_response = client.responses.create(
    model="gpt-5.5",
    previous_response_id=response.id,
    input=[{"role": "user", "content": "explain why this is funny."}],
)
print(second_response.output_text)
In the following example, we ask the model to tell a joke. Separately, we ask the model to explain why it’s funny, and the model has all necessary context to deliver a good response.
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
from openai import OpenAI
client = OpenAI()

response = client.responses.create(
    model="gpt-5.5",
    input="tell me a joke",
)
print(response.output_text)

second_response = client.responses.create(
    model="gpt-5.5",
    previous_response_id=response.id,
    input=[{"role": "user", "content": "explain why this is funny."}],
)
print(second_response.output_text)
previous_response_id in WebSocket mode
If you are using the Responses API WebSocket mode, continuation uses the same previous_response_id semantics as HTTP mode, but over a persistent socket with repeated response.create events.
The connection-local cache currently keeps the most recent previous response in memory for low-latency continuation. If an uncached ID cannot be resolved, send a new turn with previous_response_id set to null and pass full input context.
Data retention for model responses
Response objects are saved for 30 days by default. They can be viewed in the dashboard
logs page or
retrieved via the API.
You can disable this behavior by setting store to false
when creating a Response.
Conversation objects and items in them are not subject to the 30 day TTL. Any response attached to a conversation will have its items persisted with no 30 day TTL.
OpenAI does not use data sent via API to train our models without your explicit consent—learn more.
Even when using previous_response_id, all previous input tokens for responses in the chain are billed as input tokens in the API.
Managing the context window
Understanding context windows will help you successfully create threaded conversations and manage state across model interactions.
The context window is the maximum number of tokens that can be used in a single request. This max tokens number includes input, output, and reasoning tokens. To learn your model’s context window, see model details.
Managing context for text generation
As your inputs become more complex, or you include more turns in a conversation, you’ll need to consider both output token and context window limits. Model inputs and outputs are metered in tokens, which are parsed from inputs to analyze their content and intent and assembled to render logical outputs. Models have limits on token usage during the lifecycle of a text generation request.
- Output tokens are the tokens generated by a model in response to a prompt. Each model has different limits for output tokens. For example,
gpt-4o-2024-08-06can generate a maximum of 16,384 output tokens. - A context window describes the total tokens that can be used for both input and output tokens (and for some models, reasoning tokens). Compare the context window limits of our models. For example,
gpt-4o-2024-08-06has a total context window of 128k tokens.
If you create a very large prompt—often by including extra context, data, or examples for the model—you run the risk of exceeding the allocated context window for a model, which might result in truncated outputs.
Use the tokenizer tool, built with the tiktoken library, to see how many tokens are in a particular string of text.
For example, when making an API request to the Responses API with a reasoning enabled model, like the o1 model, the following token counts will apply toward the context window total:
- Input tokens (inputs you include in the
inputarray for the Responses API) - Output tokens (tokens generated in response to your prompt)
- Reasoning tokens (used by the model to plan a response)
Tokens generated in excess of the context window limit may be truncated in API responses.
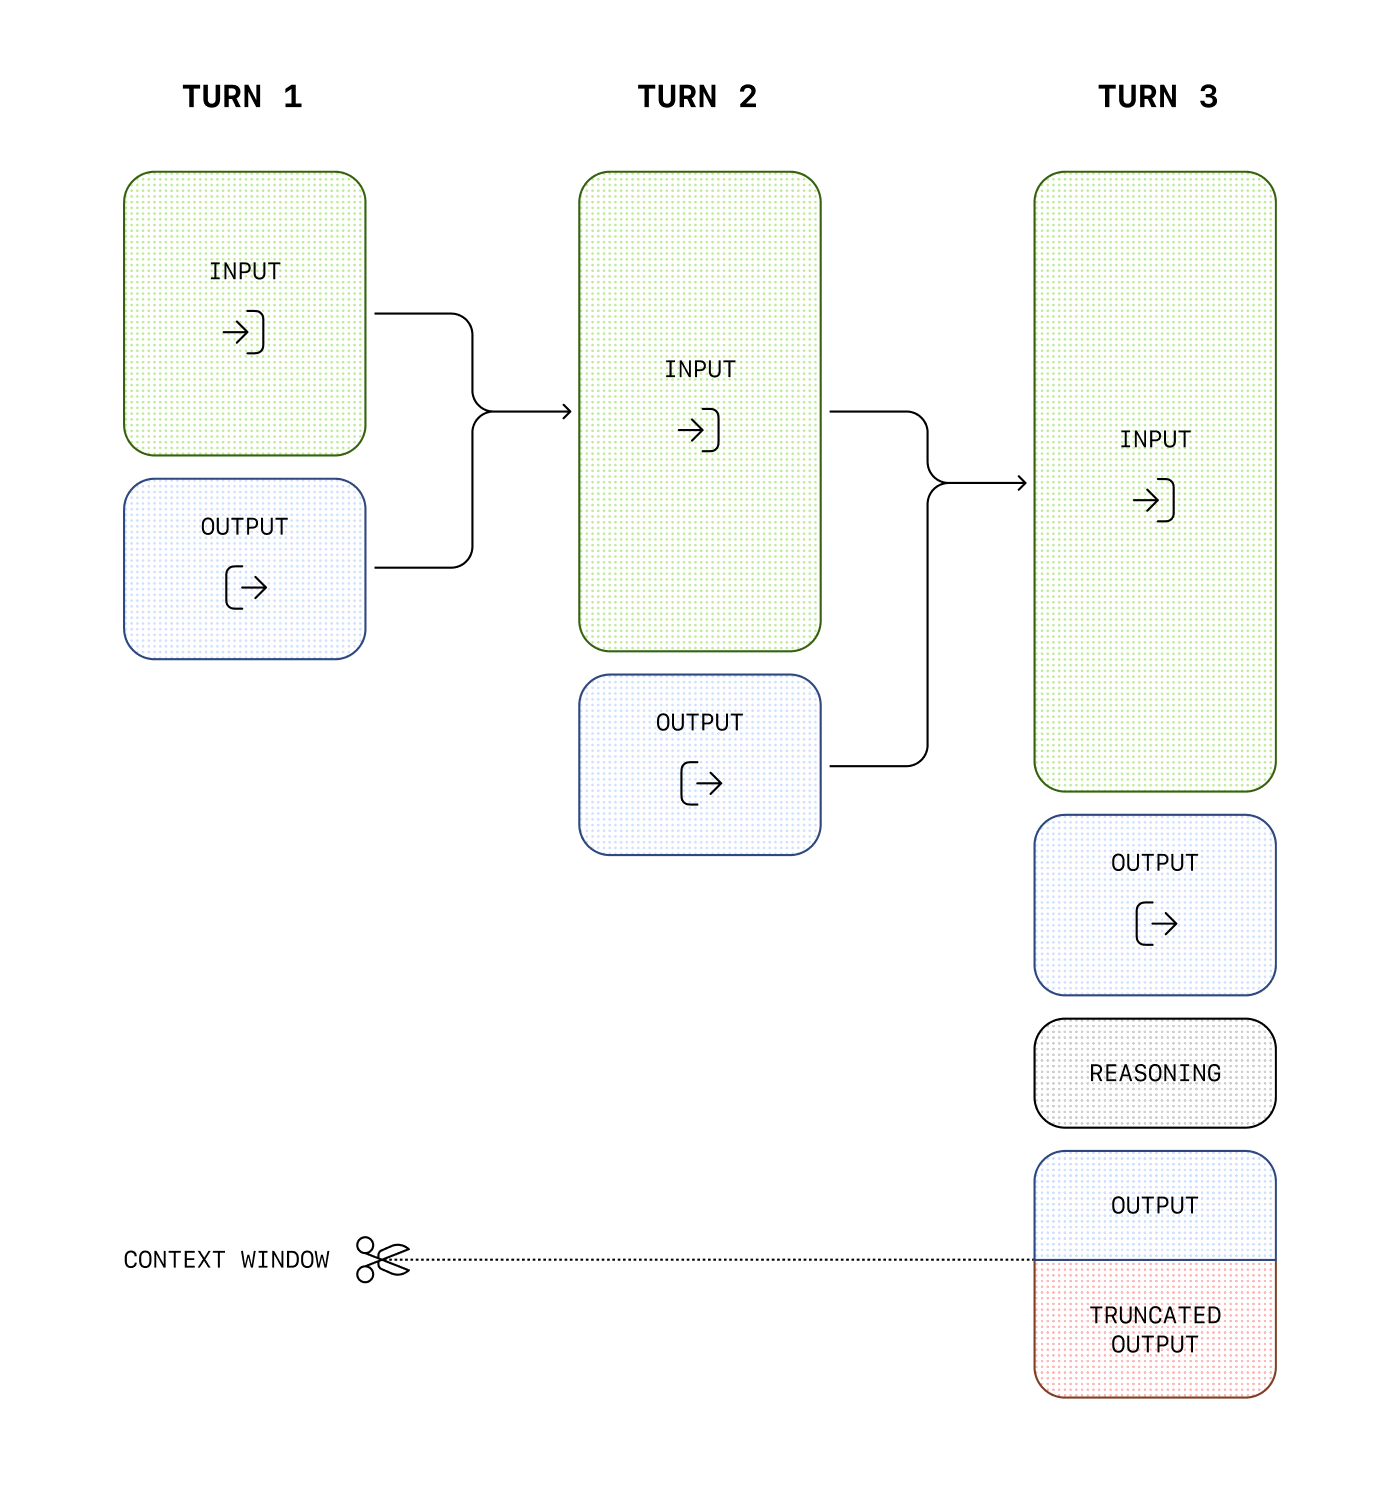
You can estimate the number of tokens your messages will use with the tokenizer tool.
Compaction
Detailed compaction guidance now lives in Compaction.
- For
/responseswithcontext_managementandcompact_threshold, see Server-side compaction. - For explicit compaction control, see
Standalone compact endpoint
and the
/responses/compactAPI reference.
For more specific examples and use cases, visit the OpenAI Cookbook, or learn more about using the APIs to extend model capabilities: