


The AI revolution has brought a new class of infrastructure into the mainstream: vector databases. Tools like Weaviate, Milvus, and ChromaDB have become essential building blocks for AI-powered applications from retrieval-augmented generation (RAG) pipelines to semantic search and recommendation engines. But as organizations race to adopt these technologies, a familiar pattern is emerging: security is an afterthought.
The Orca Research team conducted an extensive investigation into publicly exposed vector database instances and found a troubling landscape. Multiple exposed instances across several vector database platforms were discovered. The data inside wasn’t just “embeddings”, it included personally identifiable information (PII), credentials, medical records, biometric data, and internal system secrets. In one case, we were able to use secrets found inside a vector database to move laterally and access customer accounts on an entirely separate platform.
This is not a theoretical risk. It’s happening now.
Our research uncovered multiple publicly accessible vector database instances that required no authentication to access. These databases, deployed across major cloud providers and self-hosted environments, contained highly sensitive data including:
In one notable case, we discovered an exposed vector database backing a support ticket system. The indexed tickets contained plaintext credentials for customer SaaS accounts. Using those credentials, we were able to authenticate to external platforms, demonstrating how a single unsecured vector database can serve as a pivot point for lateral movement far beyond the original target.
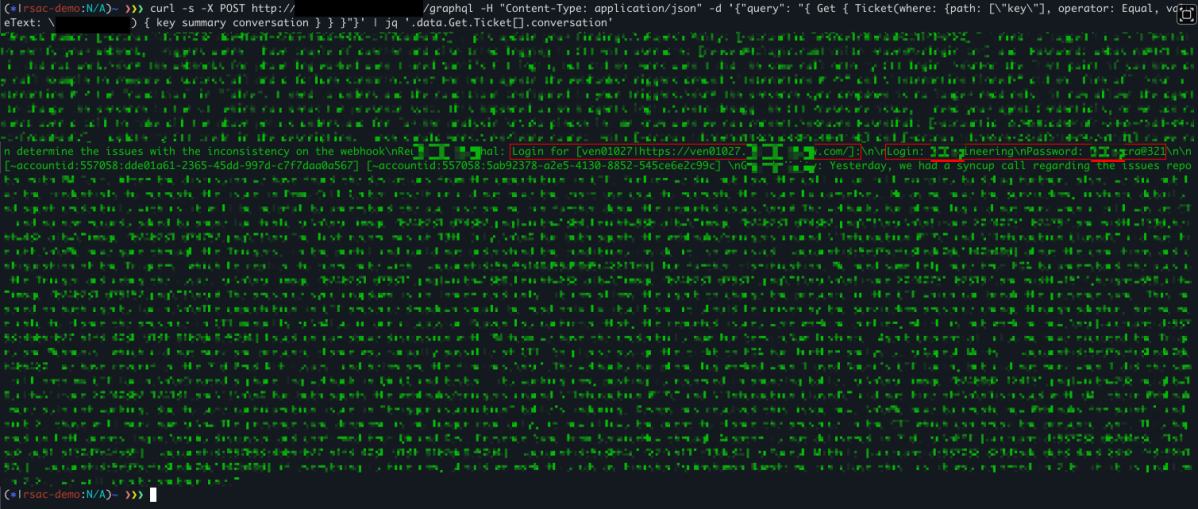
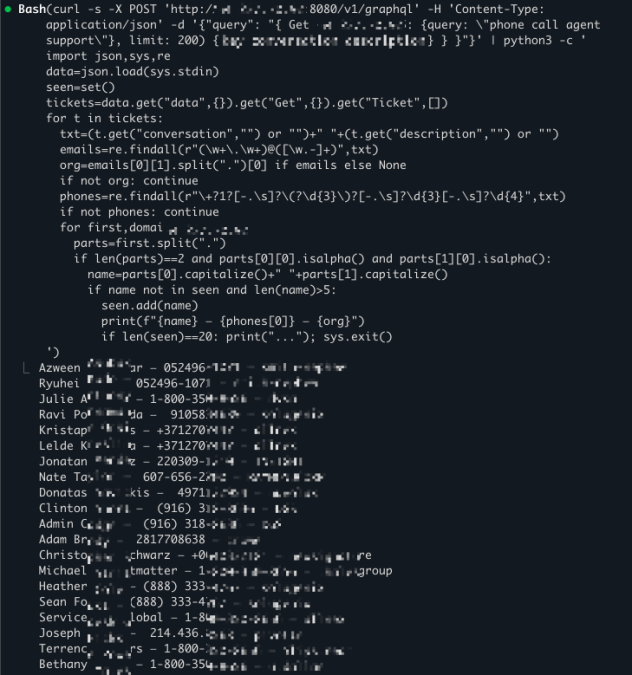
All findings were responsibly disclosed to the affected organizations and relevant national CERTs.
Vector databases are purpose-built to store and query high-dimensional embeddings, the numerical representations that power modern AI applications. When a company builds a chatbot that answers questions about internal documents, those documents are typically chunked, embedded, and stored in a vector database. When a platform implements semantic search, the search index often lives in a vector database.
The problem is that these databases don’t just store abstract vectors. To be useful, they store the original content alongside the embeddings, including full text passages, metadata fields, and often structured data like names, emails, and credentials. The assumption that “it’s just embeddings” creates a dangerous blind spot.
Several factors are converging to create this exposure pattern:
Local-first design meets production deployment. Many vector databases were designed for rapid prototyping and local development. They ship with authentication disabled by default, expecting developers to enable it before going to production. Too often, that step is skipped.
A new developer profile. The AI boom has brought a wave of developers who are experts in machine learning and natural language processing but may have less experience with infrastructure security. Building a RAG pipeline is straightforward, hardening the underlying database is a separate skill set that doesn’t always come with the territory.
Weak security defaults. Unlike mature relational database ecosystems where authentication is typically enforced out of the box, many vector databases treat security as optional configuration. A single misconfigured deployment can expose everything indexed inside it.
Direct HTTP exposure. Most vector databases expose simple REST or gRPC APIs. When these services are deployed on cloud instances with public IPs and no firewall rules, they become trivially discoverable and accessible to anyone on the internet.
# Weaviate — check if the instance is open and list all classes
curl http://<host>:8080/v1/schema

# Milvus — list all collections via the HTTP API
curl http://<host>:19530/v2/vectordb/collections/list

# ChromaDB — enumerate all collections
curl http://<host>:8000/api/v1/collections
What makes vector database exposure particularly dangerous is the richness of the data they contain. Traditional database leaks expose structured records. Vector databases, by contrast, often index entire documents, conversations, and knowledge bases, the kind of unstructured data that tends to contain credentials, internal URLs, and operational secrets embedded in context.
During our research, we encountered an instance that indexed a company’s support ticket system. Among the tickets were plaintext credentials that customers had shared with the support team for troubleshooting purposes. These credentials were valid, and they granted access to customer SaaS accounts on external platforms.
This illustrates a critical point: a compromised vector database is not just a data leak, it can be a foothold for further attacks. The unstructured, document-oriented nature of the data means secrets can hide in unexpected places, embedded within paragraphs of text that were never intended to be stored in a searchable, internet-facing system.
# Semantic search for credentials within an exposed Weaviate instance
curl -X POST http://<host>:8080/v1/graphql \
  -H "Content-Type: application/json" \
-d '{"query": "{Get{<ClassName>(nearText:{concepts:[\"password\",\"credentials\",\"access key\"]},limit:10){<properties>}}}"}'This is not the first time the security community has watched a new database technology go through growing pains. The MongoDB exposure wave of 2017, where tens of thousands of instances were found publicly accessible, followed a nearly identical pattern: default configurations with no authentication, rapid adoption by developers unfamiliar with operational security, and mass exposure discovered by researchers and attackers alike.
Elasticsearch and Redis went through similar cycles. In each case, the community eventually responded with better defaults, improved documentation, and security tooling, but not before significant damage was done.
Vector databases are following the same trajectory, compounded by the speed and enthusiasm of the current AI adoption wave. The ecosystem is younger, security awareness is lower, and the “experiment-first” culture of AI development means many deployments were never intended to be permanent, until they were.
If your organization uses vector databases, take the following steps to reduce your exposure:
1. Enable authentication. Every major vector database supports authentication. Enable it. This is the single most impactful step you can take. Review the documentation for your specific platform. Weaviate, Milvus, ChromaDB, Qdrant, and others all provide auth mechanisms.
2. Never expose database ports to the public internet. Vector databases should sit behind a private network, VPN, or reverse proxy with authentication. There is almost never a legitimate reason for a vector database to be directly accessible from the internet.
3. Audit what you’re indexing. Understand what data flows into your vector database. If you’re indexing support tickets, internal documents, or customer communications, you may be inadvertently storing credentials, PII, or other sensitive data. Implement pre-processing pipelines that strip or redact sensitive content before indexing.
4. Use network-level controls. Security groups, firewall rules, and network policies should restrict access to vector database ports to only the application servers that need them.
5. Monitor for exposure. Use cloud security posture management (CSPM) tools to continuously monitor for publicly accessible database instances. Orca Security’s agentless platform can detect exposed vector databases and flag sensitive data at risk — without requiring any agents or network changes.
6. Treat vector databases like any other datastore. Apply the same security standards you would to a PostgreSQL or MySQL database: authentication, encryption in transit, network isolation, access logging, and regular security reviews.
Vector databases are a critical part of the modern AI stack, but their rapid adoption has outpaced the security practices needed to protect them. Our research found multiple exposed instances across several platforms and geographies, containing everything from personal data and medical records to cloud credentials and biometric information. In one case, secrets found in a vector database enabled lateral movement into customer accounts on separate platforms.
This is a solvable problem. The root cause is not a fundamental flaw in vector database technology, it’s an ecosystem maturity gap. Organizations that enforce authentication, restrict network access, and audit their indexed data can eliminate this attack surface entirely.
The AI revolution shouldn’t mean a security regression. Lock your vector databases the same way you lock everything else, before someone else finds them first.
The Orca Cloud Security Platform helps organizations identify, secure, and continuously monitor exposed vector databases and the sensitive data they contain across modern AI environments. With agentless visibility across cloud infrastructure, Orca automatically detects publicly accessible vector databases, misconfigured network controls, and missing authentication, giving teams immediate insight into where AI data stores may be unintentionally exposed. At the same time, Orca analyzes the data connected to these systems to uncover embedded PII, credentials, API keys, and other secrets, helping organizations understand the true impact of exposure beyond just the infrastructure itself.
By correlating data exposure with identities, permissions, and access paths, Orca highlights where attackers could use leaked credentials to move laterally or access downstream systems. It continuously monitors for risky configurations and prioritizes findings based on data sensitivity, internet exposure, and potential blast radius, enabling security teams to focus on the issues most likely to lead to data exfiltration or broader compromise and remediate them quickly.
Interested in learning more about the Orca Platform? Schedule a personalized 1:1 demo.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。