


惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

D
DataBreaches.Net
OSCHINA 社区最新新闻
OSCHINA 社区最新新闻
Google DeepMind News
博客园 - 聂微东
Microsoft Azure Blog
V
Visual Studio Blog
IT之家
IT之家
博客园 - 【当耐特】
钛媒体:引领未来商业与生活新知
钛媒体:引领未来商业与生活新知
B
Blog
爱范儿
爱范儿
阮一峰的网络日志
阮一峰的网络日志
云风的 BLOG
云风的 BLOG
Vercel News
Vercel News
Cyber Security Advisories - MS-ISAC
H
Hackread – Cybersecurity News, Data Breaches, AI and More
H
Help Net Security
J
Java Code Geeks
aimingoo的专栏
aimingoo的专栏
freeCodeCamp Programming Tutorials: Python, JavaScript, Git & More
B
Blog RSS Feed
Blog — PlanetScale
Blog — PlanetScale
S
SegmentFault 最新的问题
Apple Machine Learning Research

Inside Nutrient

A guide to the invisible work behind documents Introducing Nutrient Documents for Salesforce: Native document generation and signing Document AI vs. traditional OCR: Choosing between OCR, AI, and hybrid pipelines PDF SDK compliance and security evaluation checklist for enterprise teams (2026) Invariant Corp replaces paper processes with Nutrient Workflow and scales without limits What is process mapping? A complete guide Nutrient vs. Conga Composer for Salesforce document generation (2026) Document routing: How to automate document distribution The CTO’s AI playbook: Why accountability architecture beats orchestration Compliance workflow automation: Why built-in compliance is table stakes Workflow diagrams: Examples, symbols, and how to build one that actually runs Digital forms: Replace paper forms with automated workflows Approval workflow software: How to automate approvals Why document-centric automation is different The CEO’s AI playbook: Why decision architecture beats model selection Nutrient SDK product updates for Q1 2026 PDF redaction verification: How to prove sensitive data is permanently removed What is a VPAT? The complete guide to accessibility conformance reports What is PDF/UA? The accessible PDF standard explained Salesforce eSignatures: Generate, sign, and track documents in one flow Online document viewer: Options, tradeoffs, and how to embed one Document viewer for web apps: React, Vue, Angular (2026) Best document viewers in 2026: A buyer’s guide How to edit a PDF in Python: Add text, images, and annotations Nutrient advances Workflow platform with agentic AI for enterprise-grade speed and consistency in document-heavy operations How to create a Salesforce quote template from opportunity data The business case for accessibility: Five ways it drives enterprise value Python PDF library comparison (2026): 7 libraries for developers Why your AI agent hallucinates PDF table data PDF.js limitations: When to upgrade to a commercial PDF SDK
Extract text from PDFs with Nutrient Document Web Service...
Hulya Masharipov · 2025-02-10 · via Inside Nutrient

Table of contents

    This tutorial walks you through creating a Zap that automatically extracts plain and structured text from PDFs using the Nutrient Document Web Services API. It’s perfect for digitizing paperwork, archiving content, or transforming scanned documents into searchable formats.
    Extract text from PDFs with Nutrient Document Web Services API on Zapier

    What is Zapier?

    Zapier(opens in a new tab) is an automation platform that connects your favorite apps and services with no code required. You can build “Zaps” to automate repetitive tasks by setting up triggers and actions between apps like Google Drive, Slack, Gmail, and more.

    In this tutorial, you’ll learn how to use Zapier to automatically extract plain and structured text from PDF documents using Nutrient DWS Processor API.

    What is Nutrient DWS Processor API?

    Nutrient Document Web Services API is a powerful platform for document automation. With your free account(opens in a new tab), you get 50 credits, which you can use to perform various document operations. Each tool (e.g. conversion, signing, flattening) consumes a different amount of credits depending on complexity.

    Nutrient offers more than 30 tools with the ability to:

    What you’ll need

    Step 1 — Trigger a new file in a Google Drive folder

    1. Select Google Drive as the trigger app.
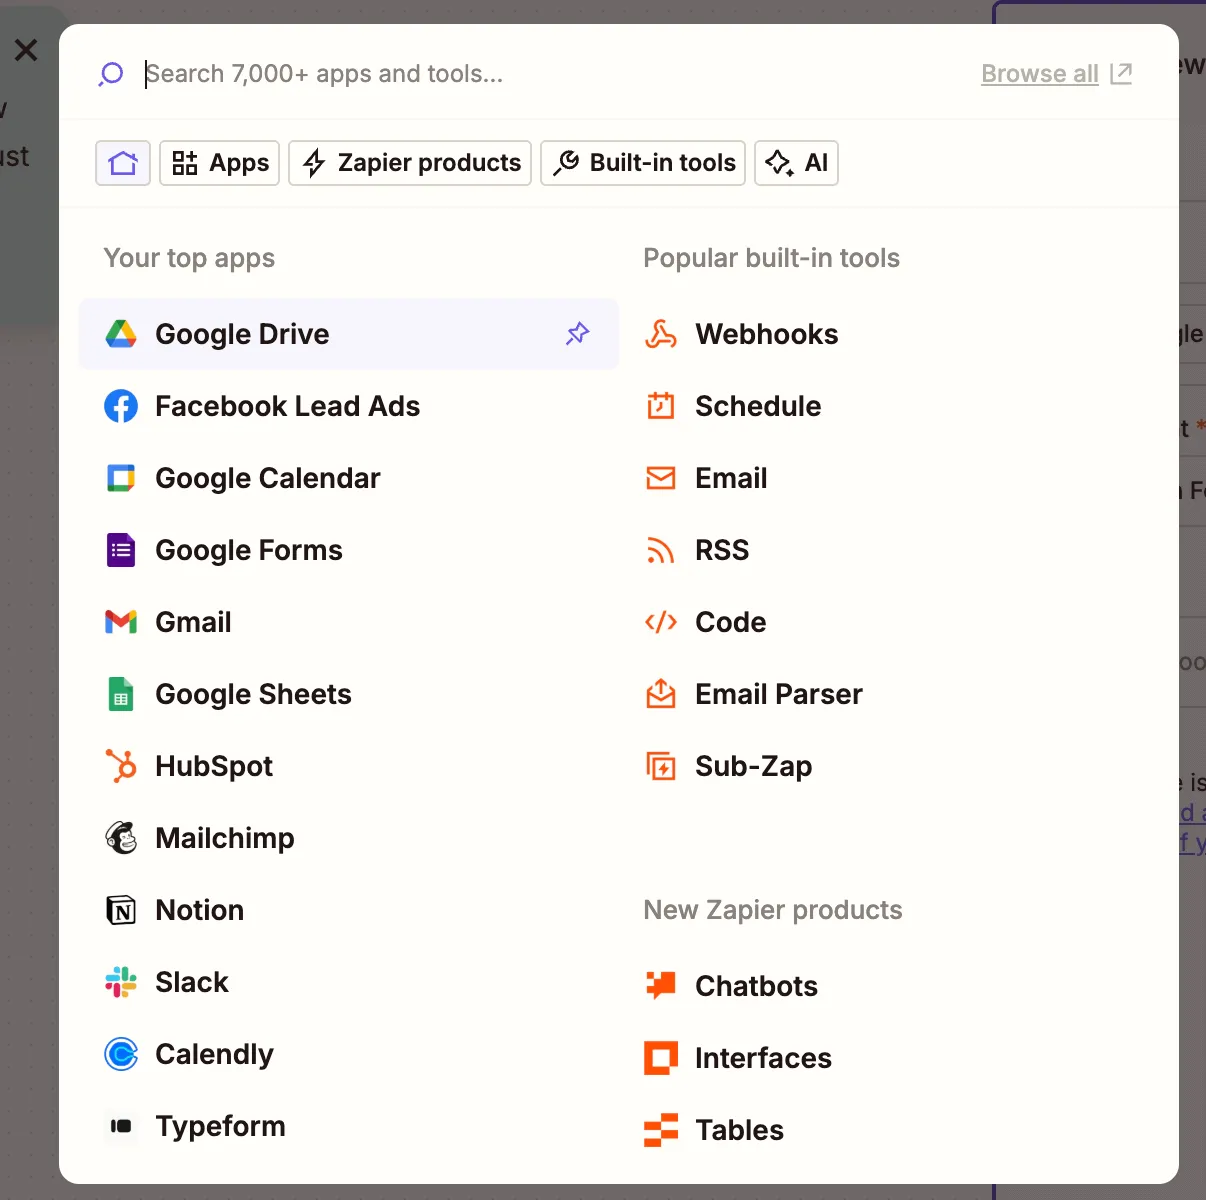
    Google Drive selected as trigger app in Zapier

    1. Choose the New File in Folder trigger event.
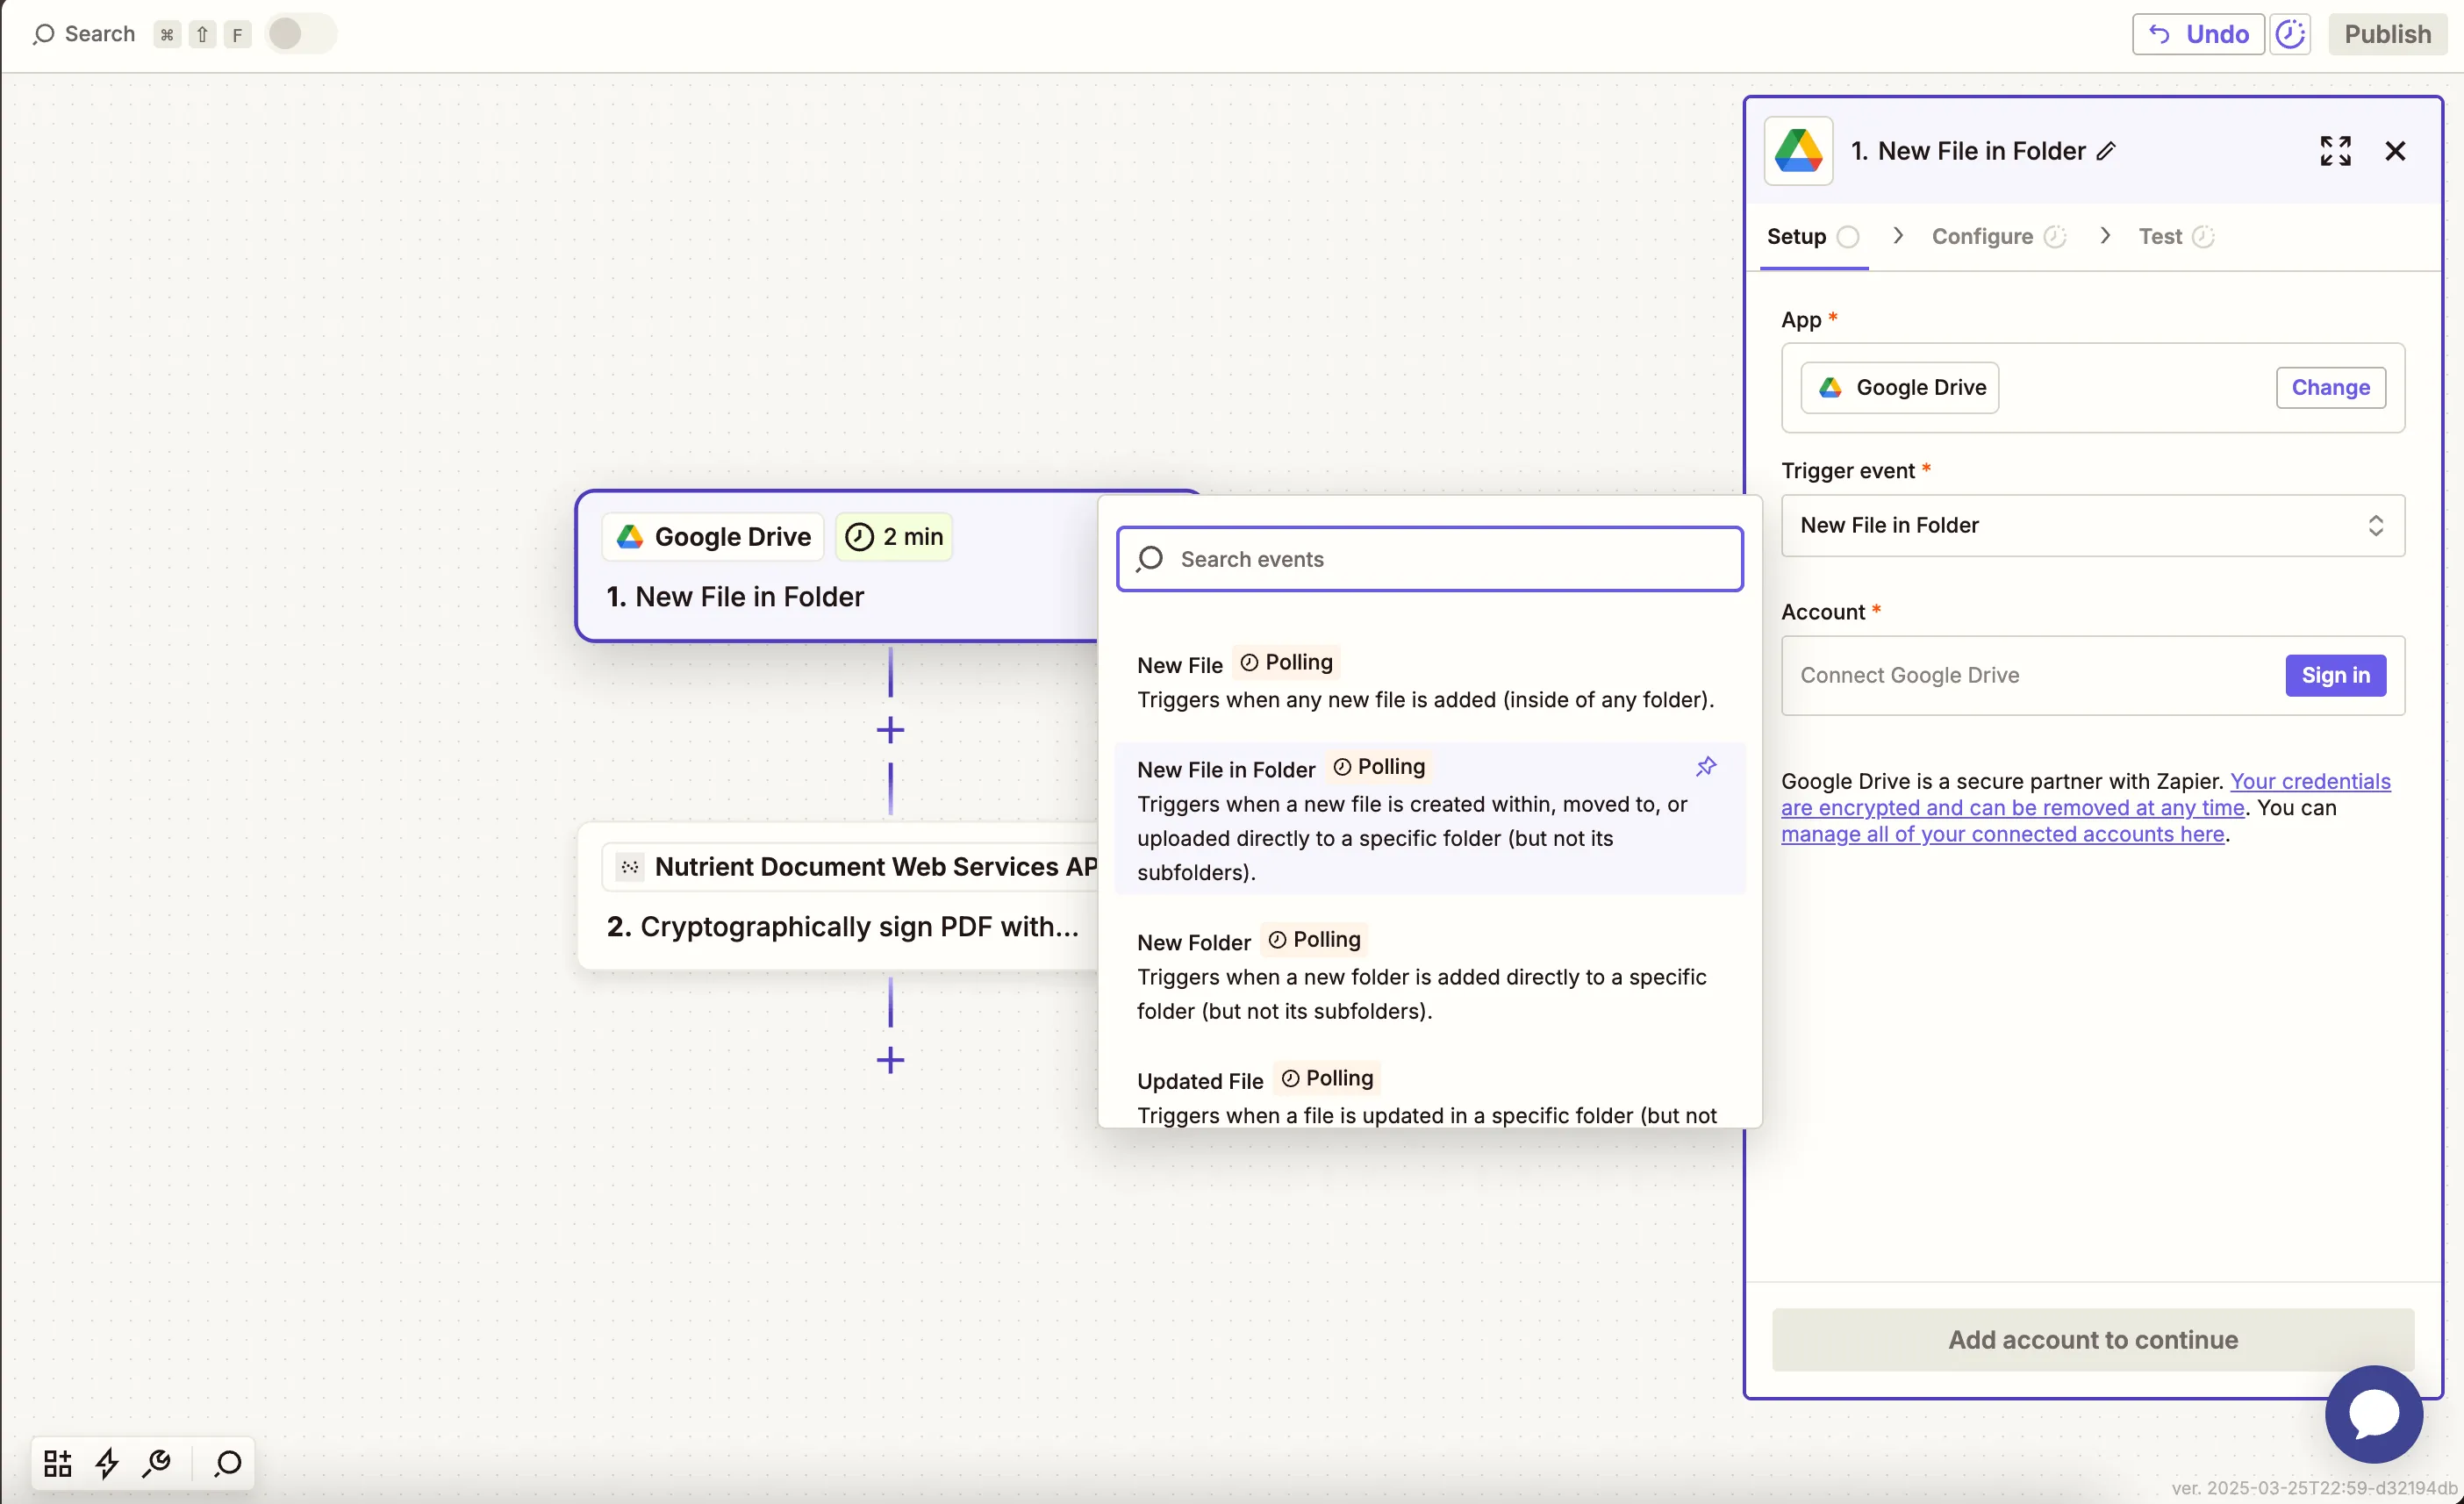
    Trigger set to 'New File in Folder'

    1. Connect your Google Drive account.
    2. Set up the trigger:
    • In the Drive field, select your Google Drive.
    • In the Folder field, select or create a folder (e.g. pdf-to-text).
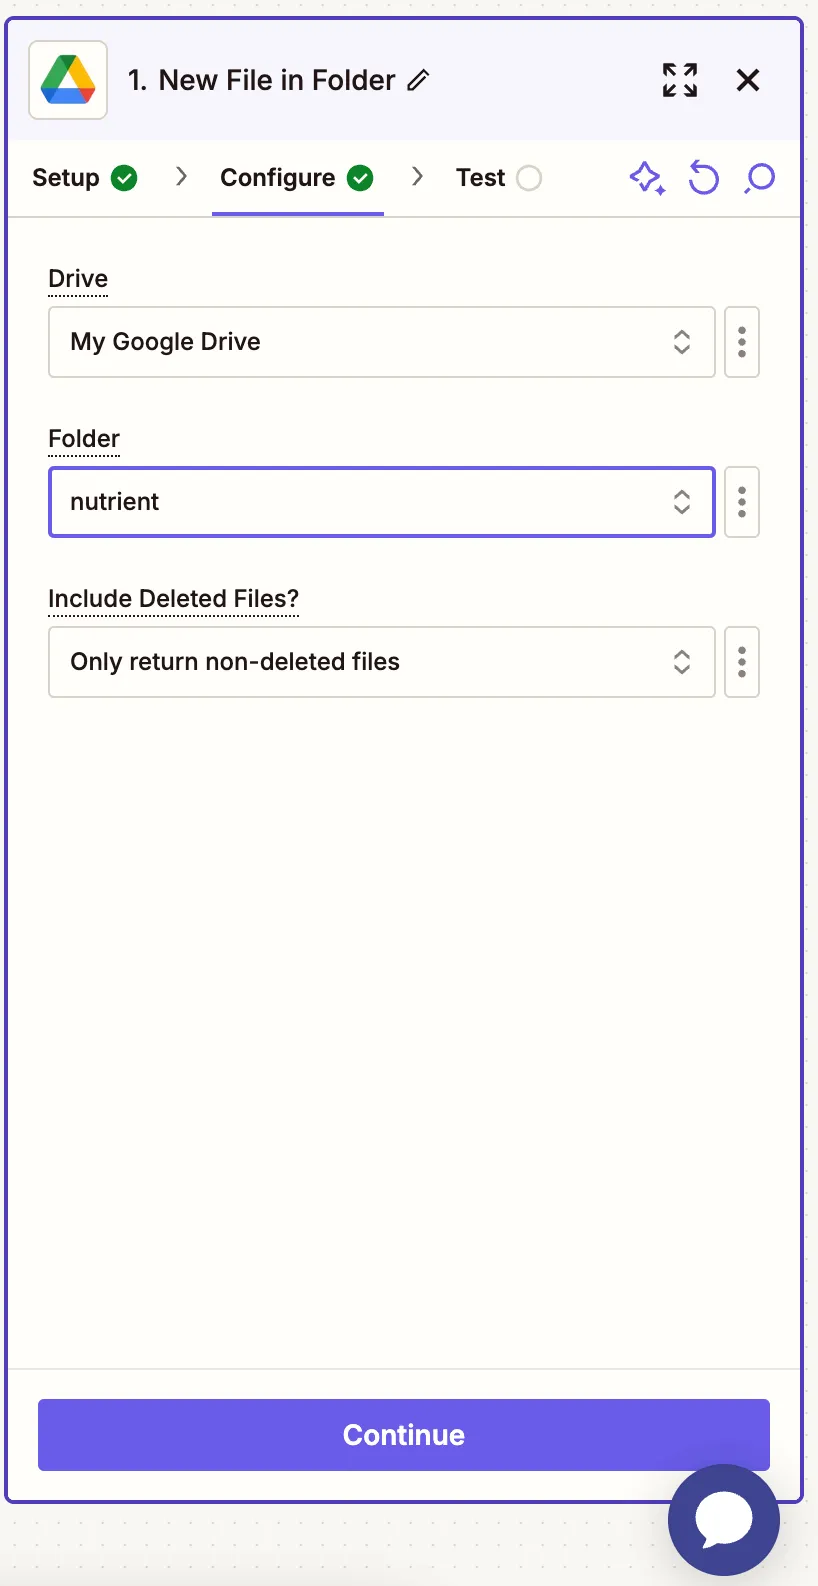
    Drive and folder selected for PDF upload monitoring

    1. Test this step with a sample PDF file.
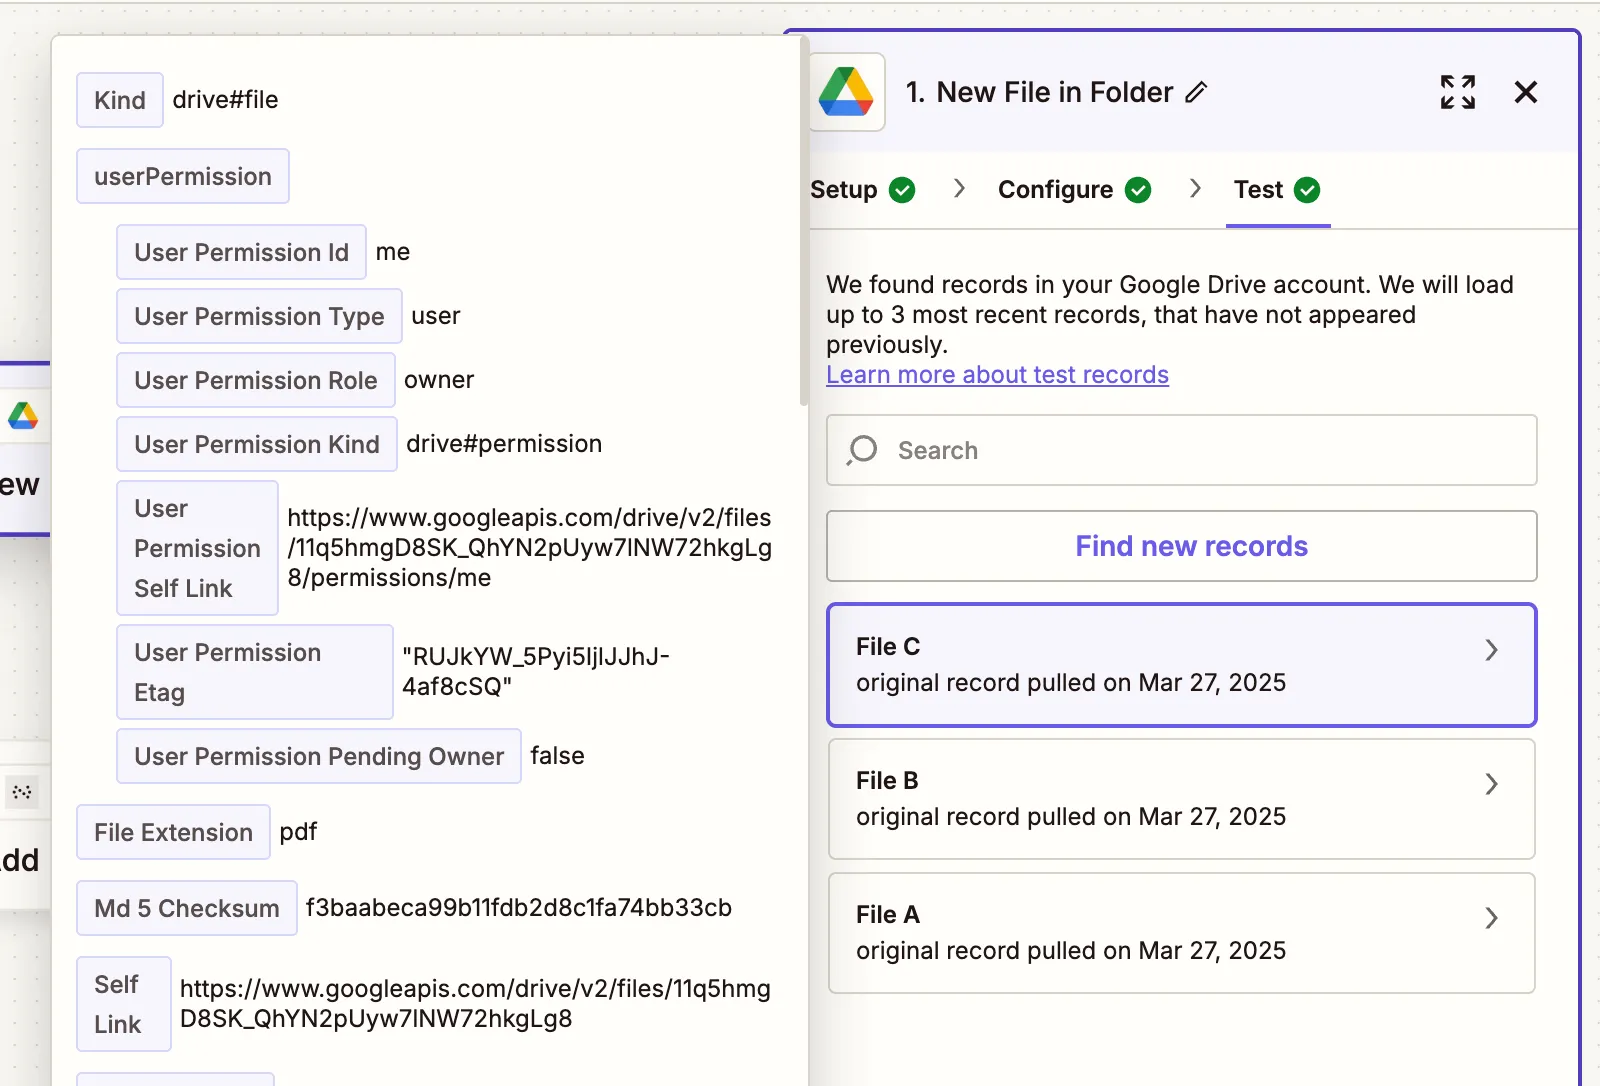
    Test result showing PDF found in Google Drive folder

    1. Select Nutrient Document Web Services API as your action app.
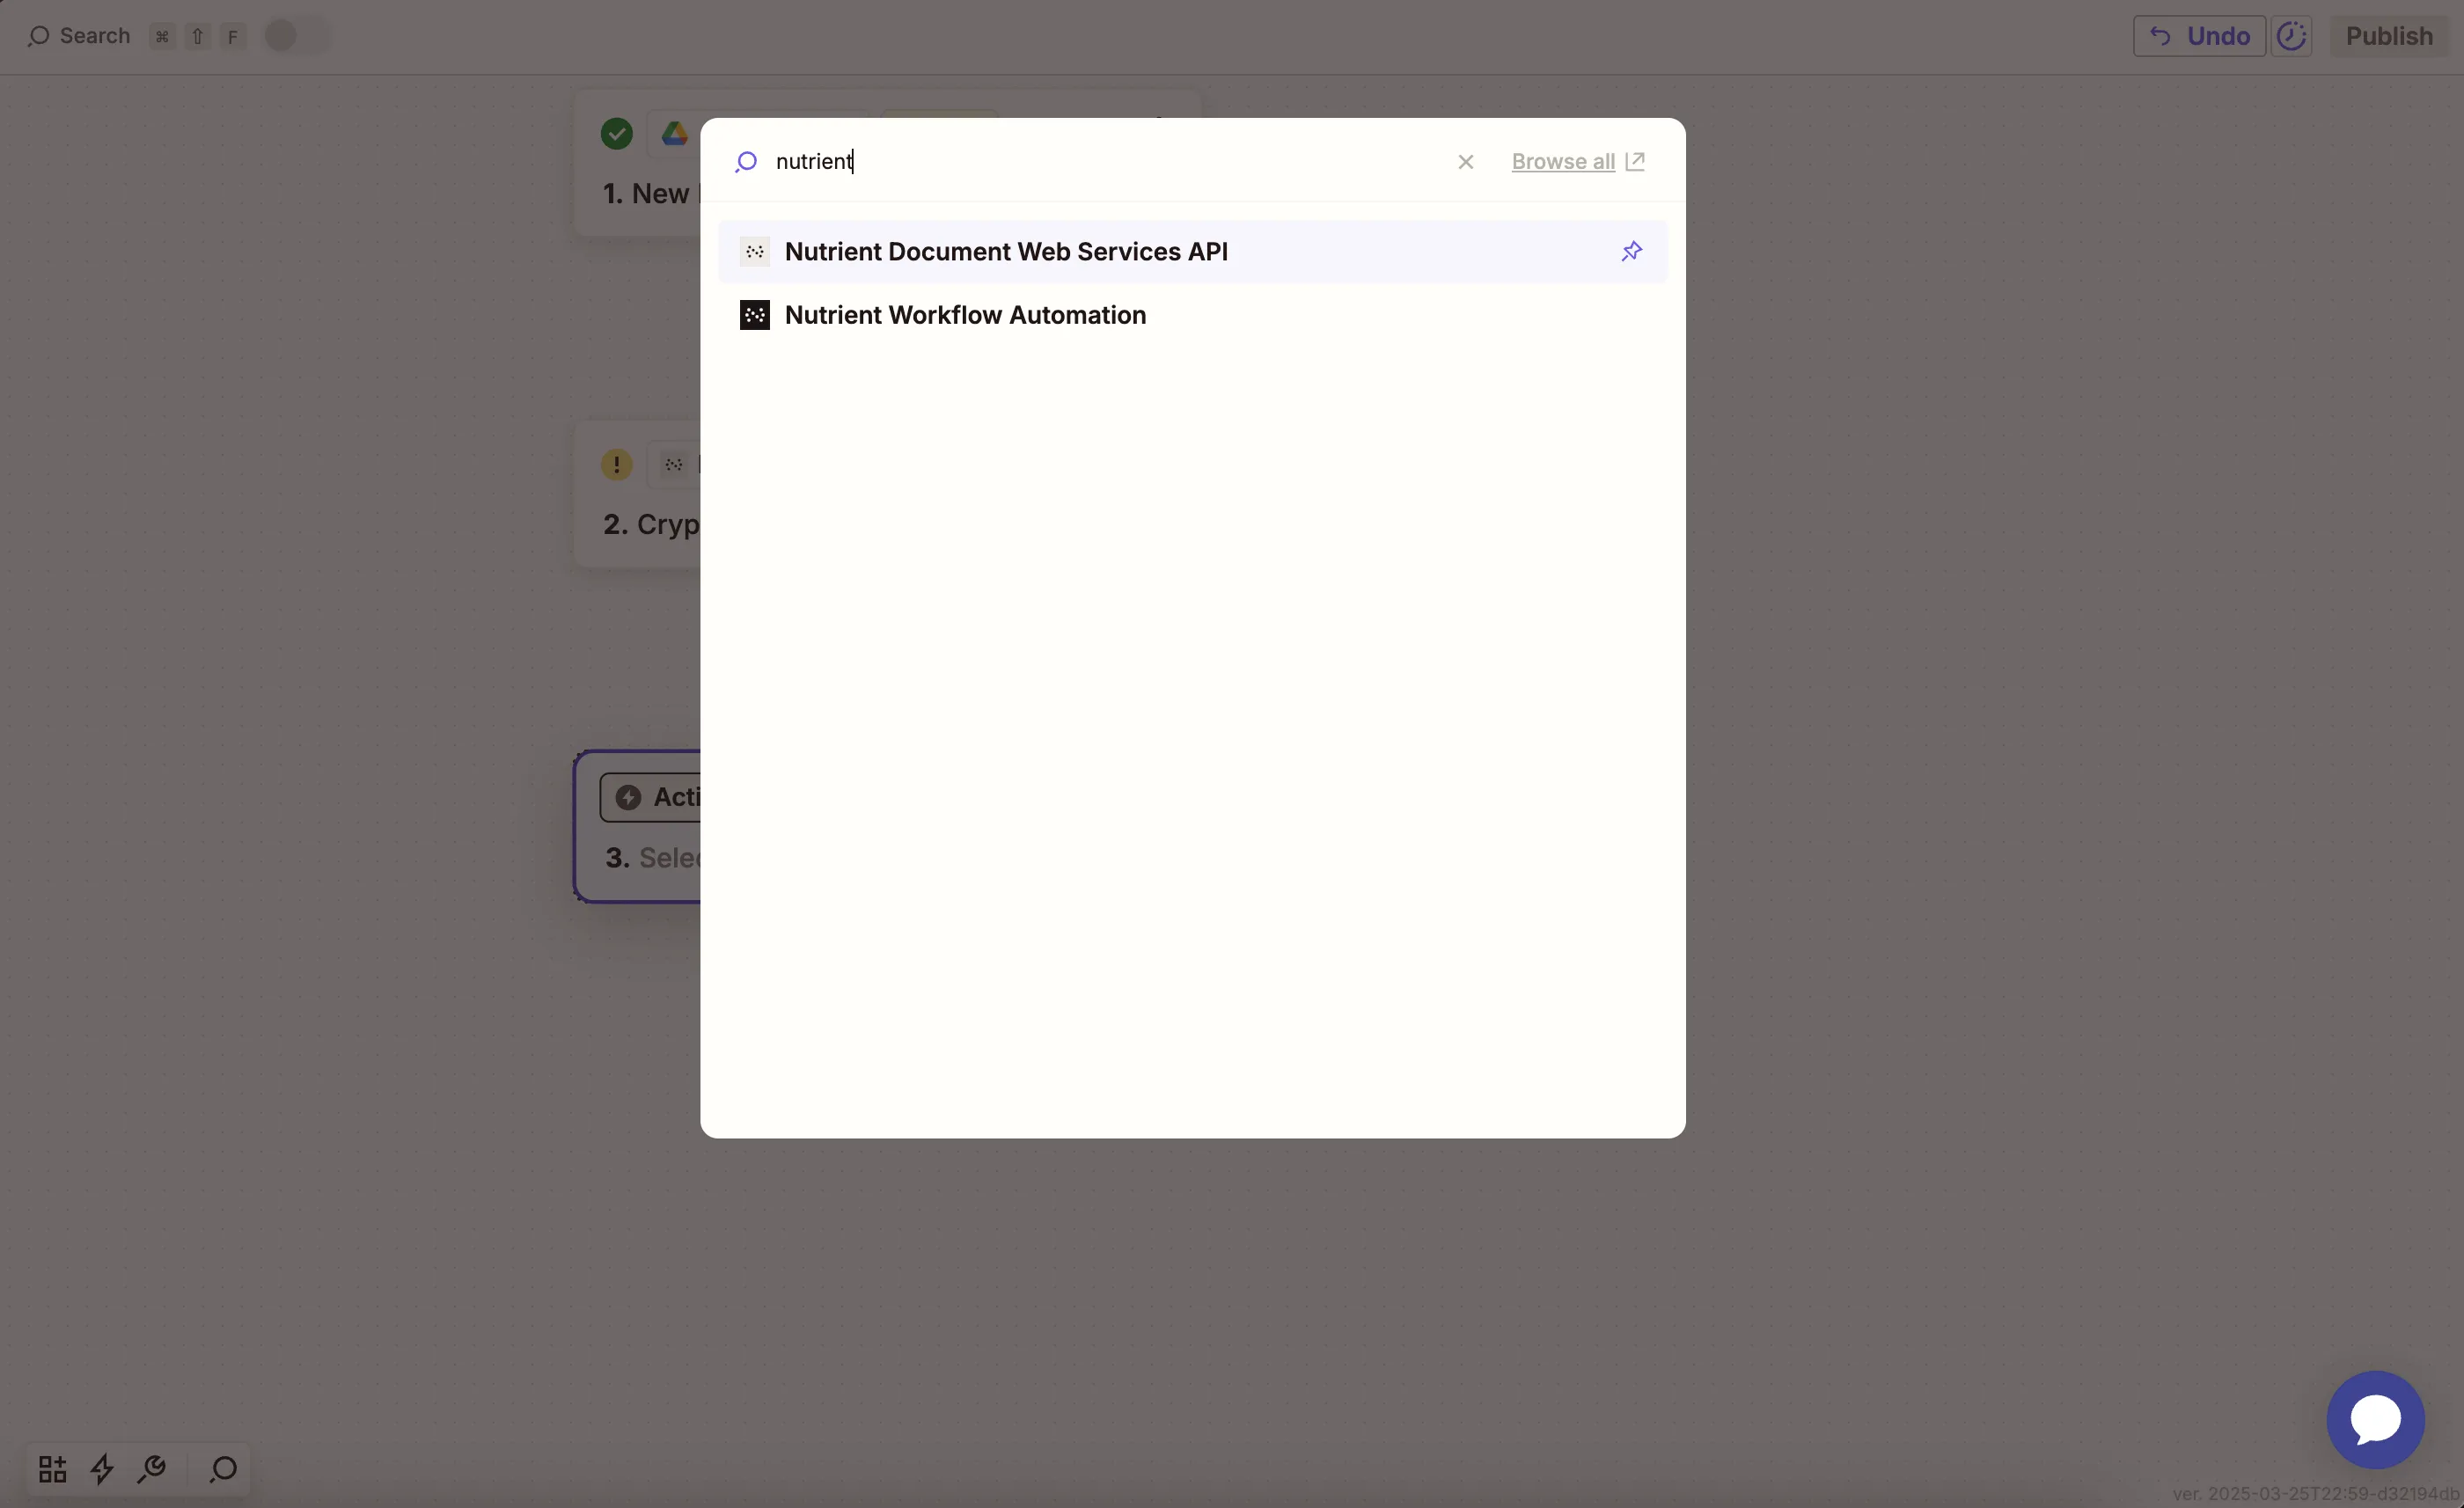
    Nutrient DWS Processor API selected as action app

    1. Choose the Extract Text From PDF action.
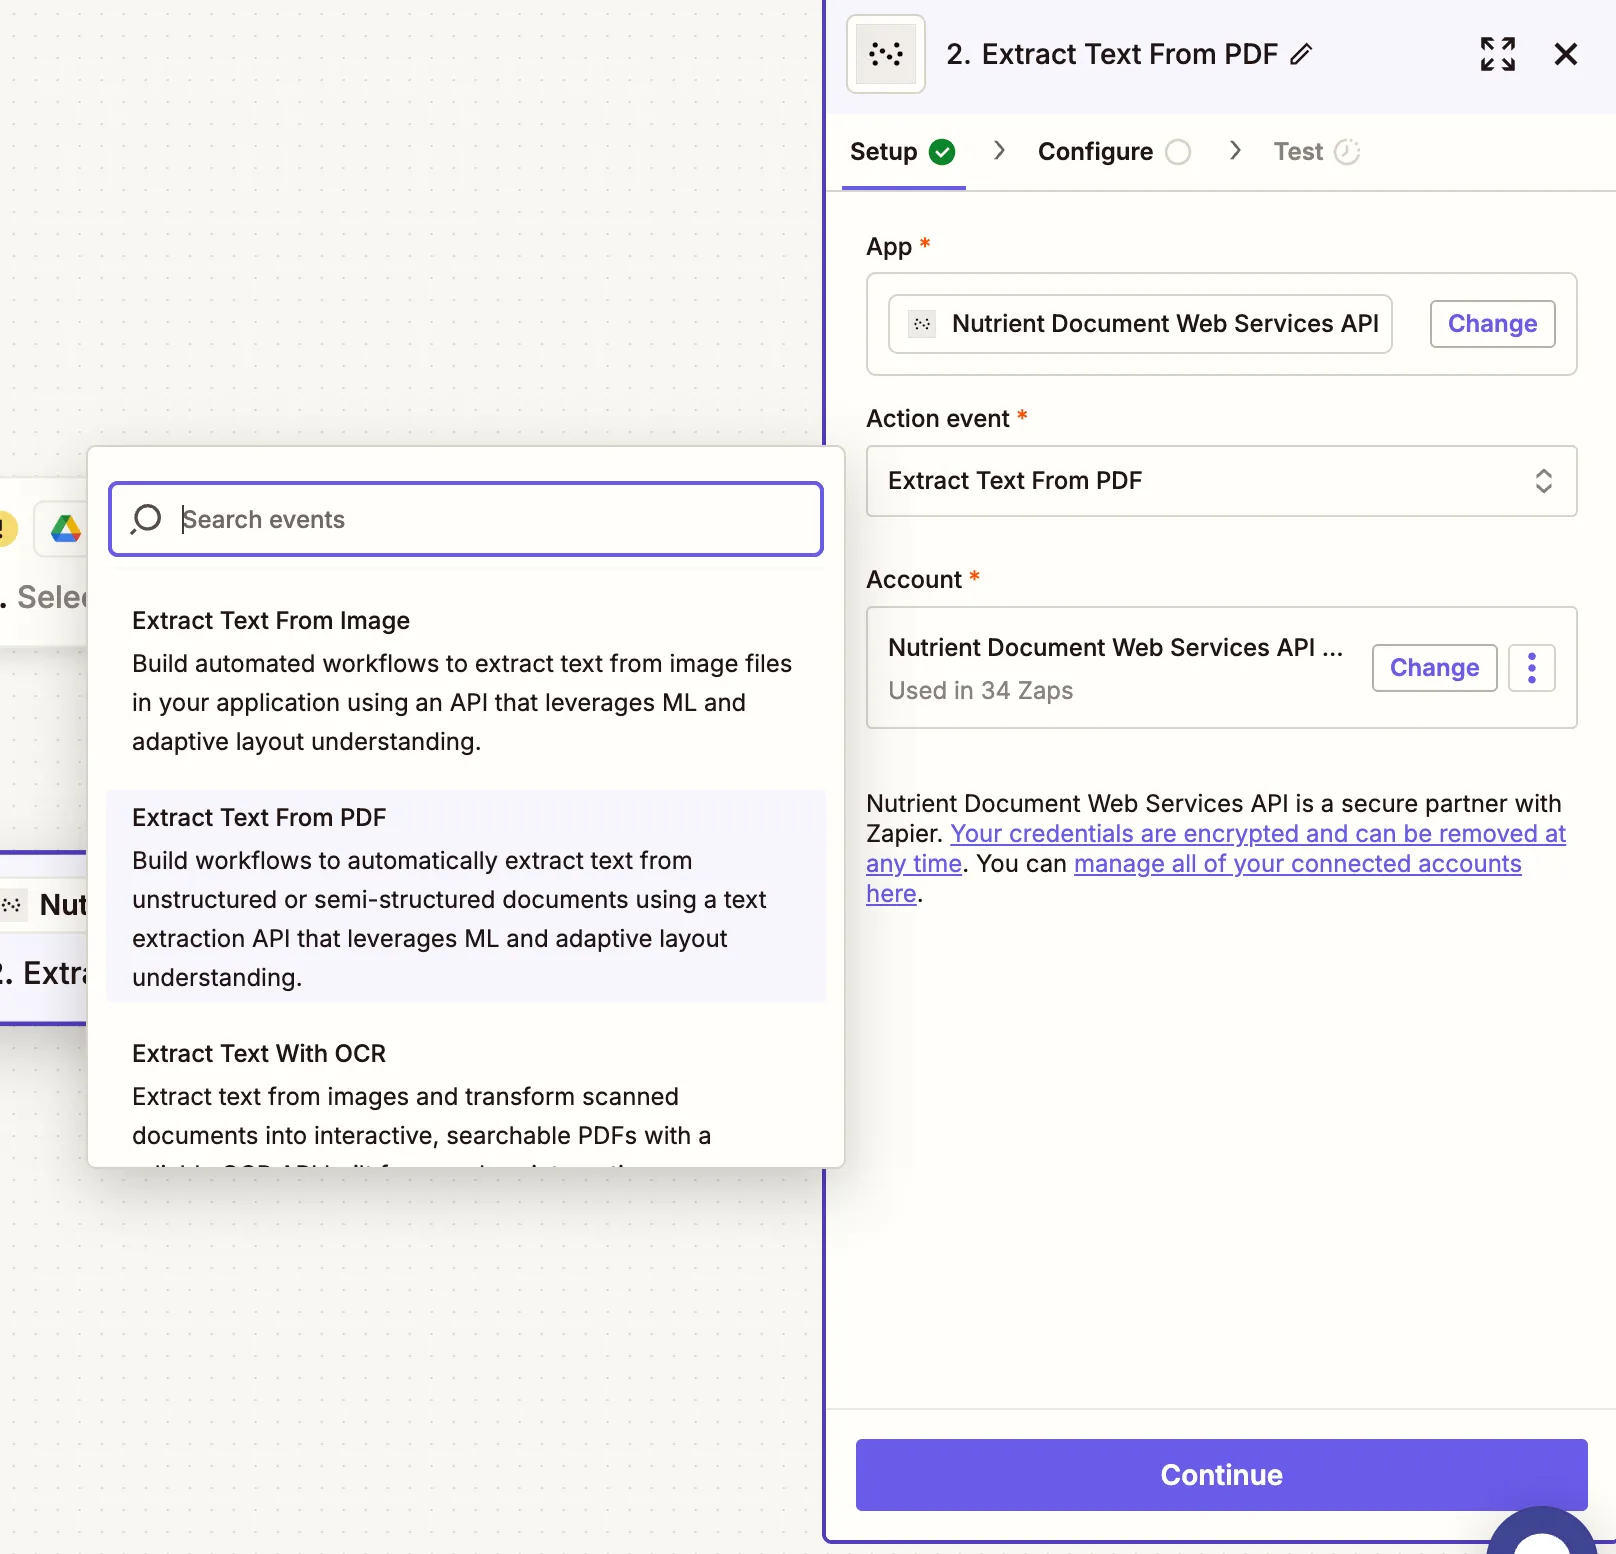
    Action dropdown showing 'Extract Text from PDF' selected

    1. Connect your Nutrient DWS Processor API account using your API key.
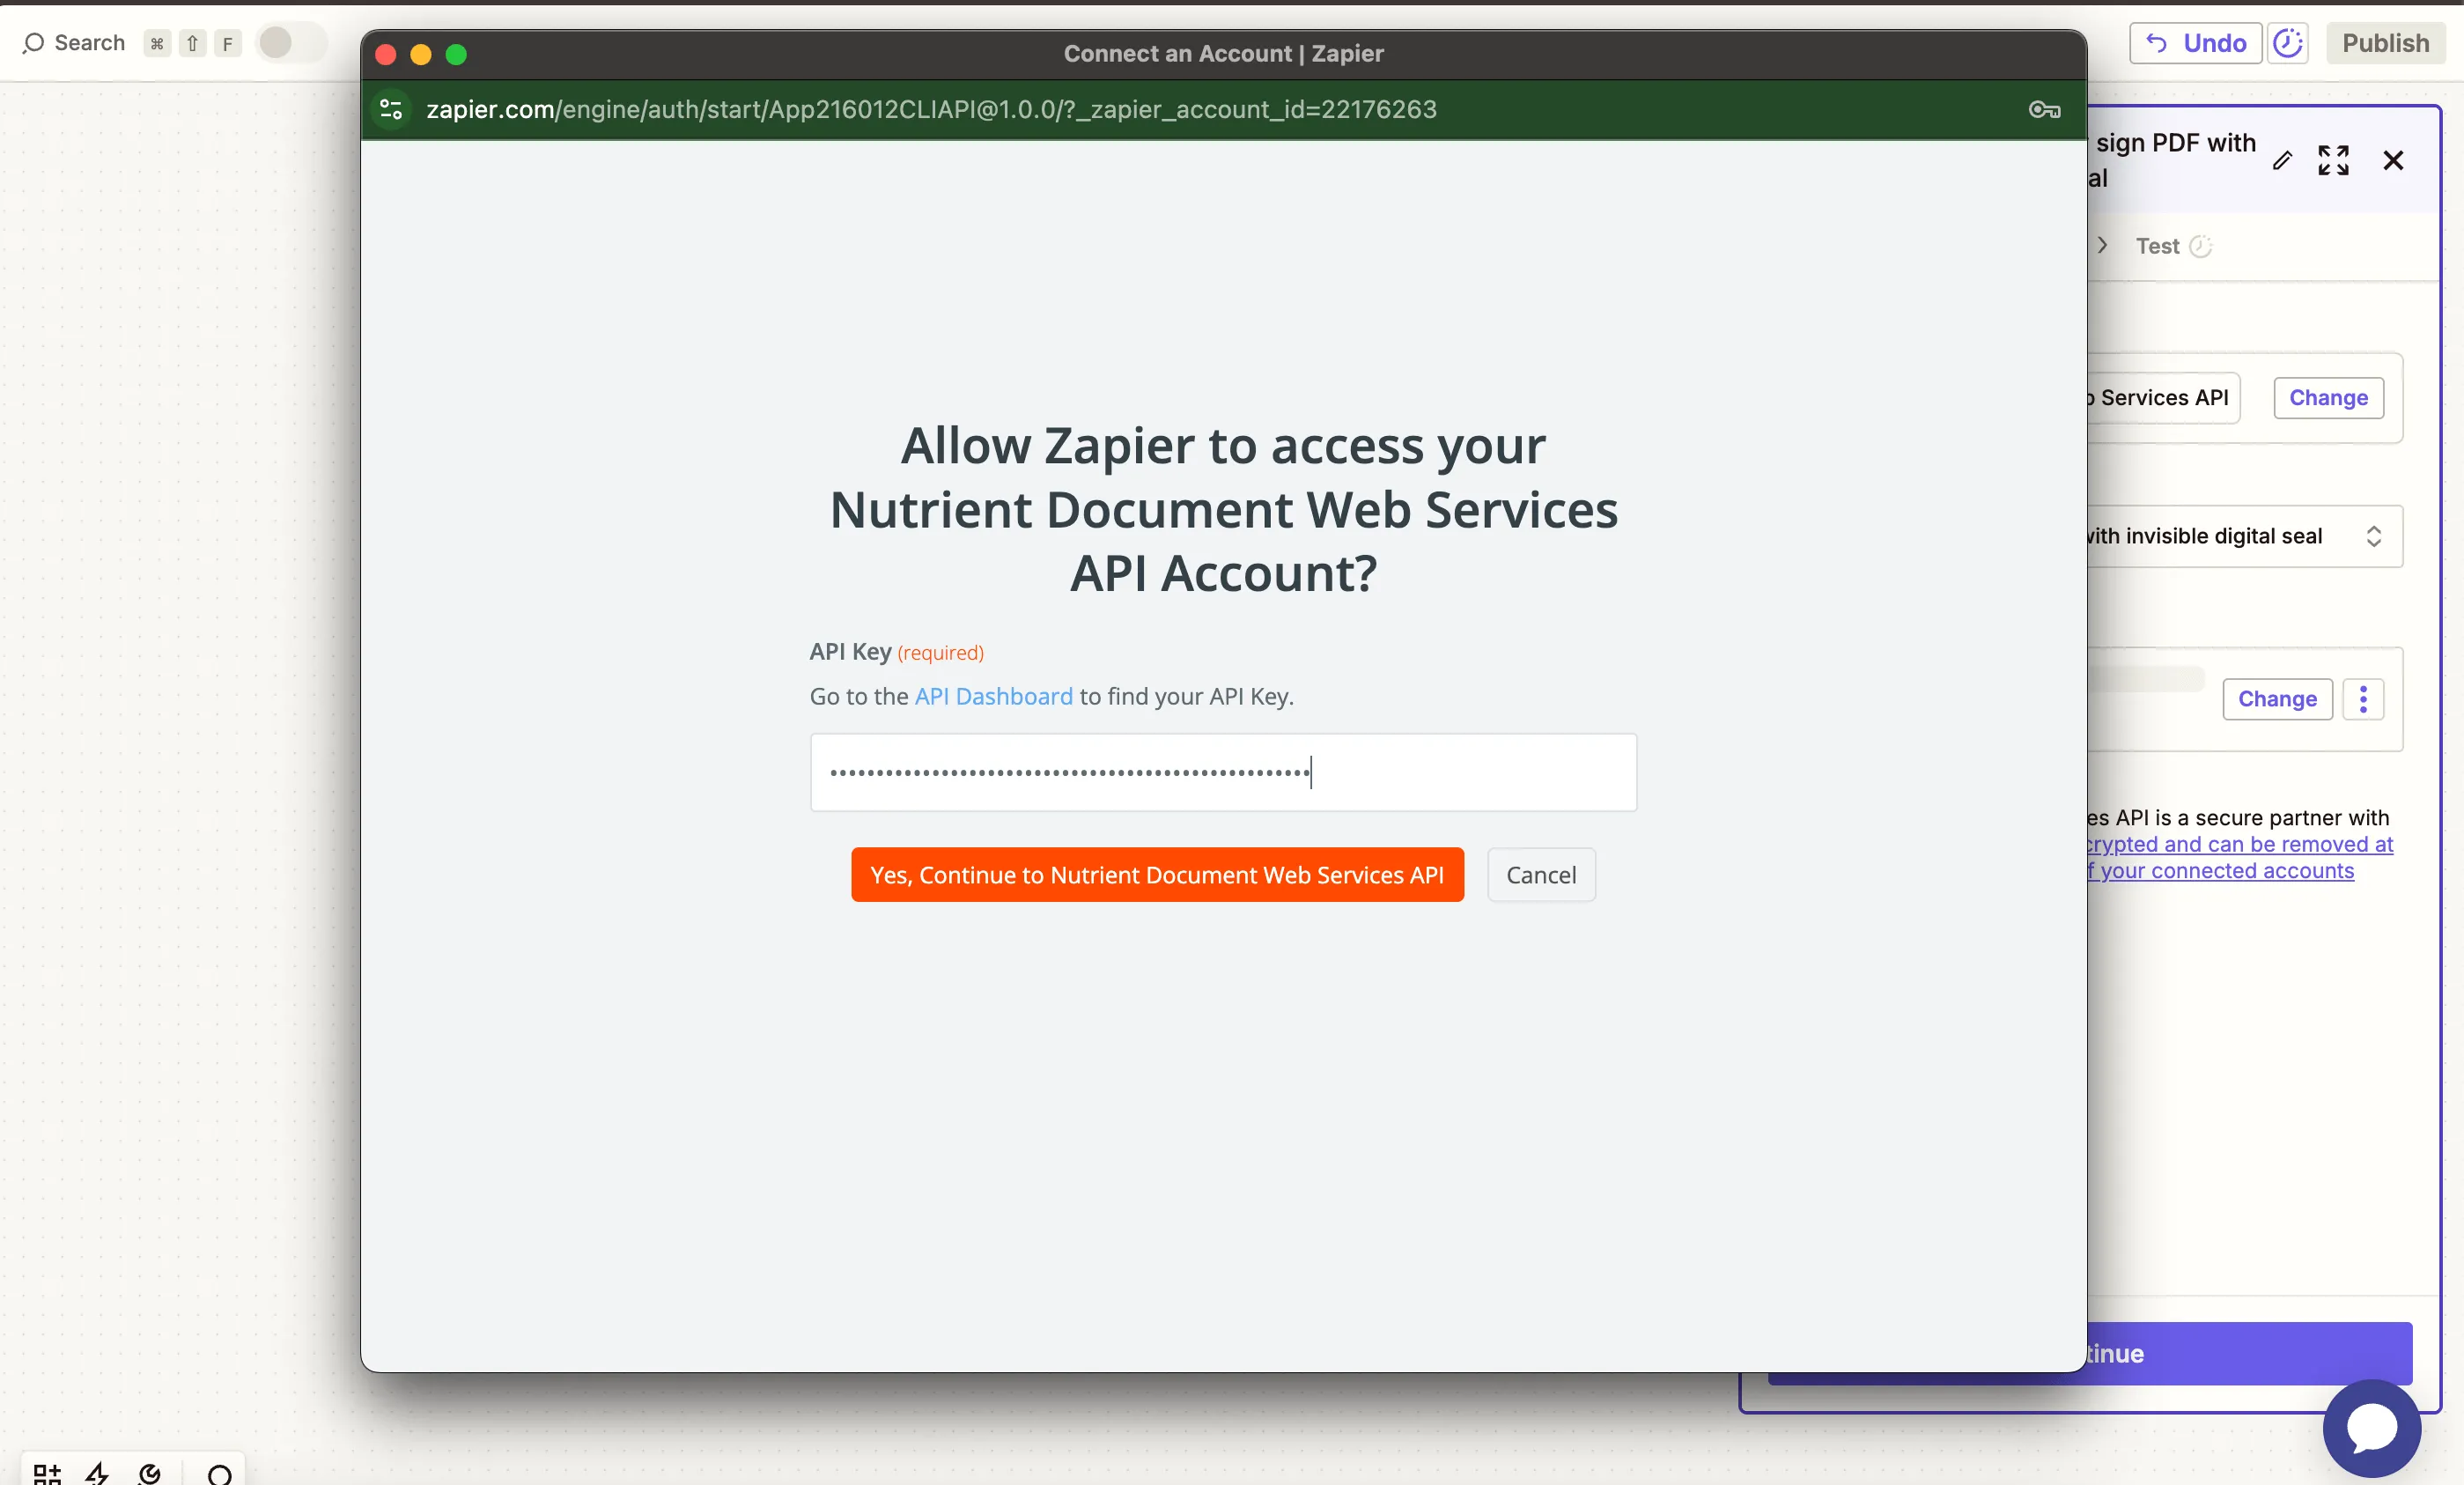
    Paste API key to connect Nutrient account

    You can find your key in the Nutrient dashboard(opens in a new tab).
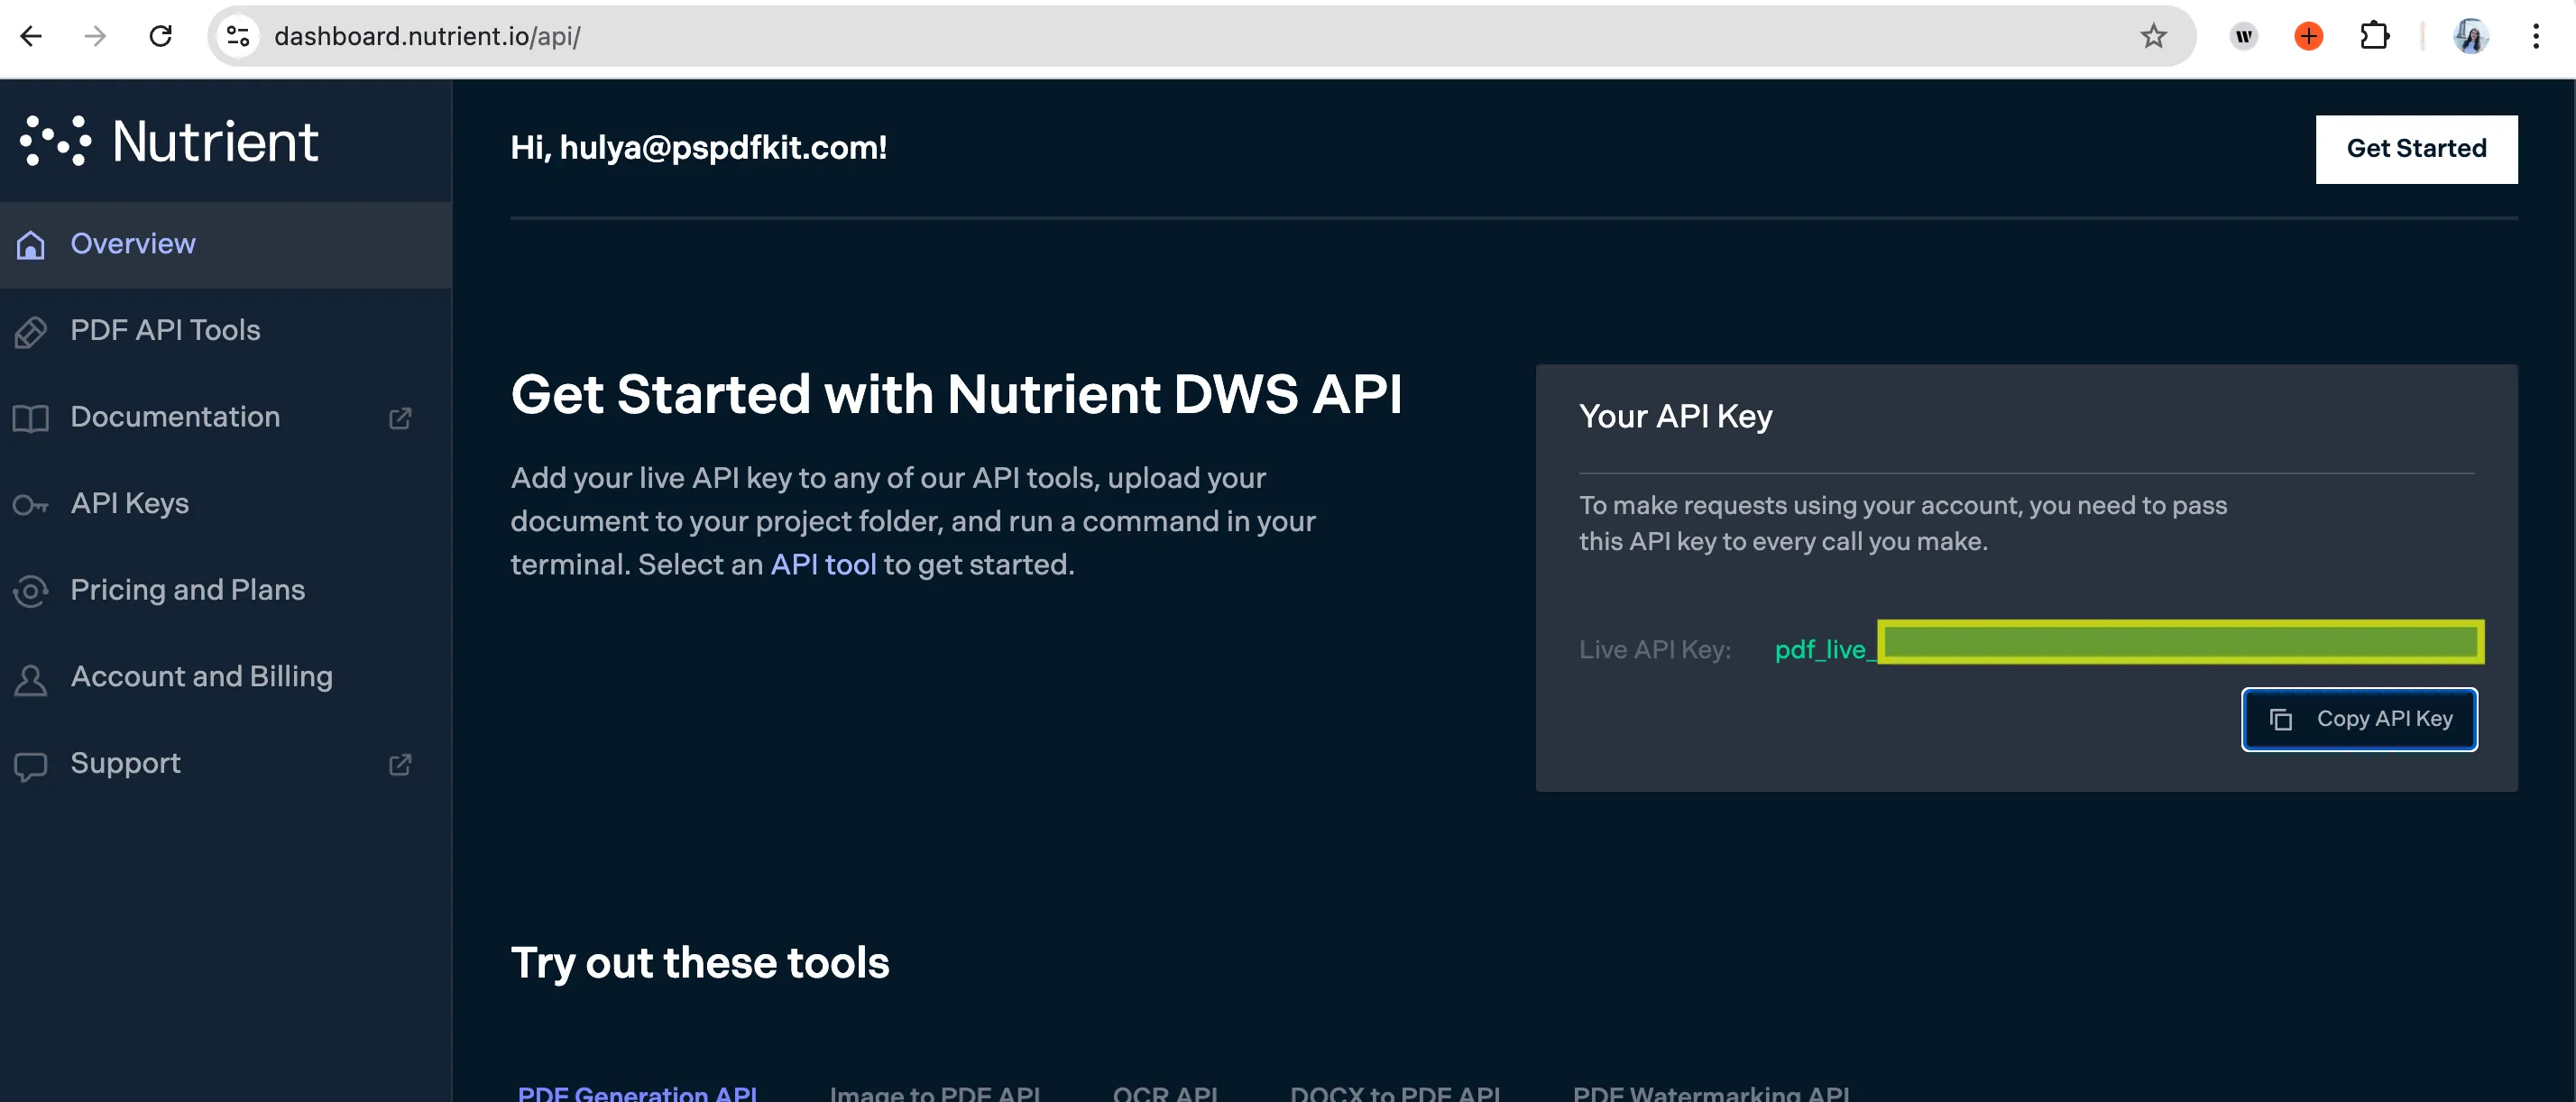
    Where to find your API key in the dashboard

    1. Configure the action:
      • PDF File URL — Use the output from step 1.
      • Output File Name — Optional — e.g. invoice-text.txt.
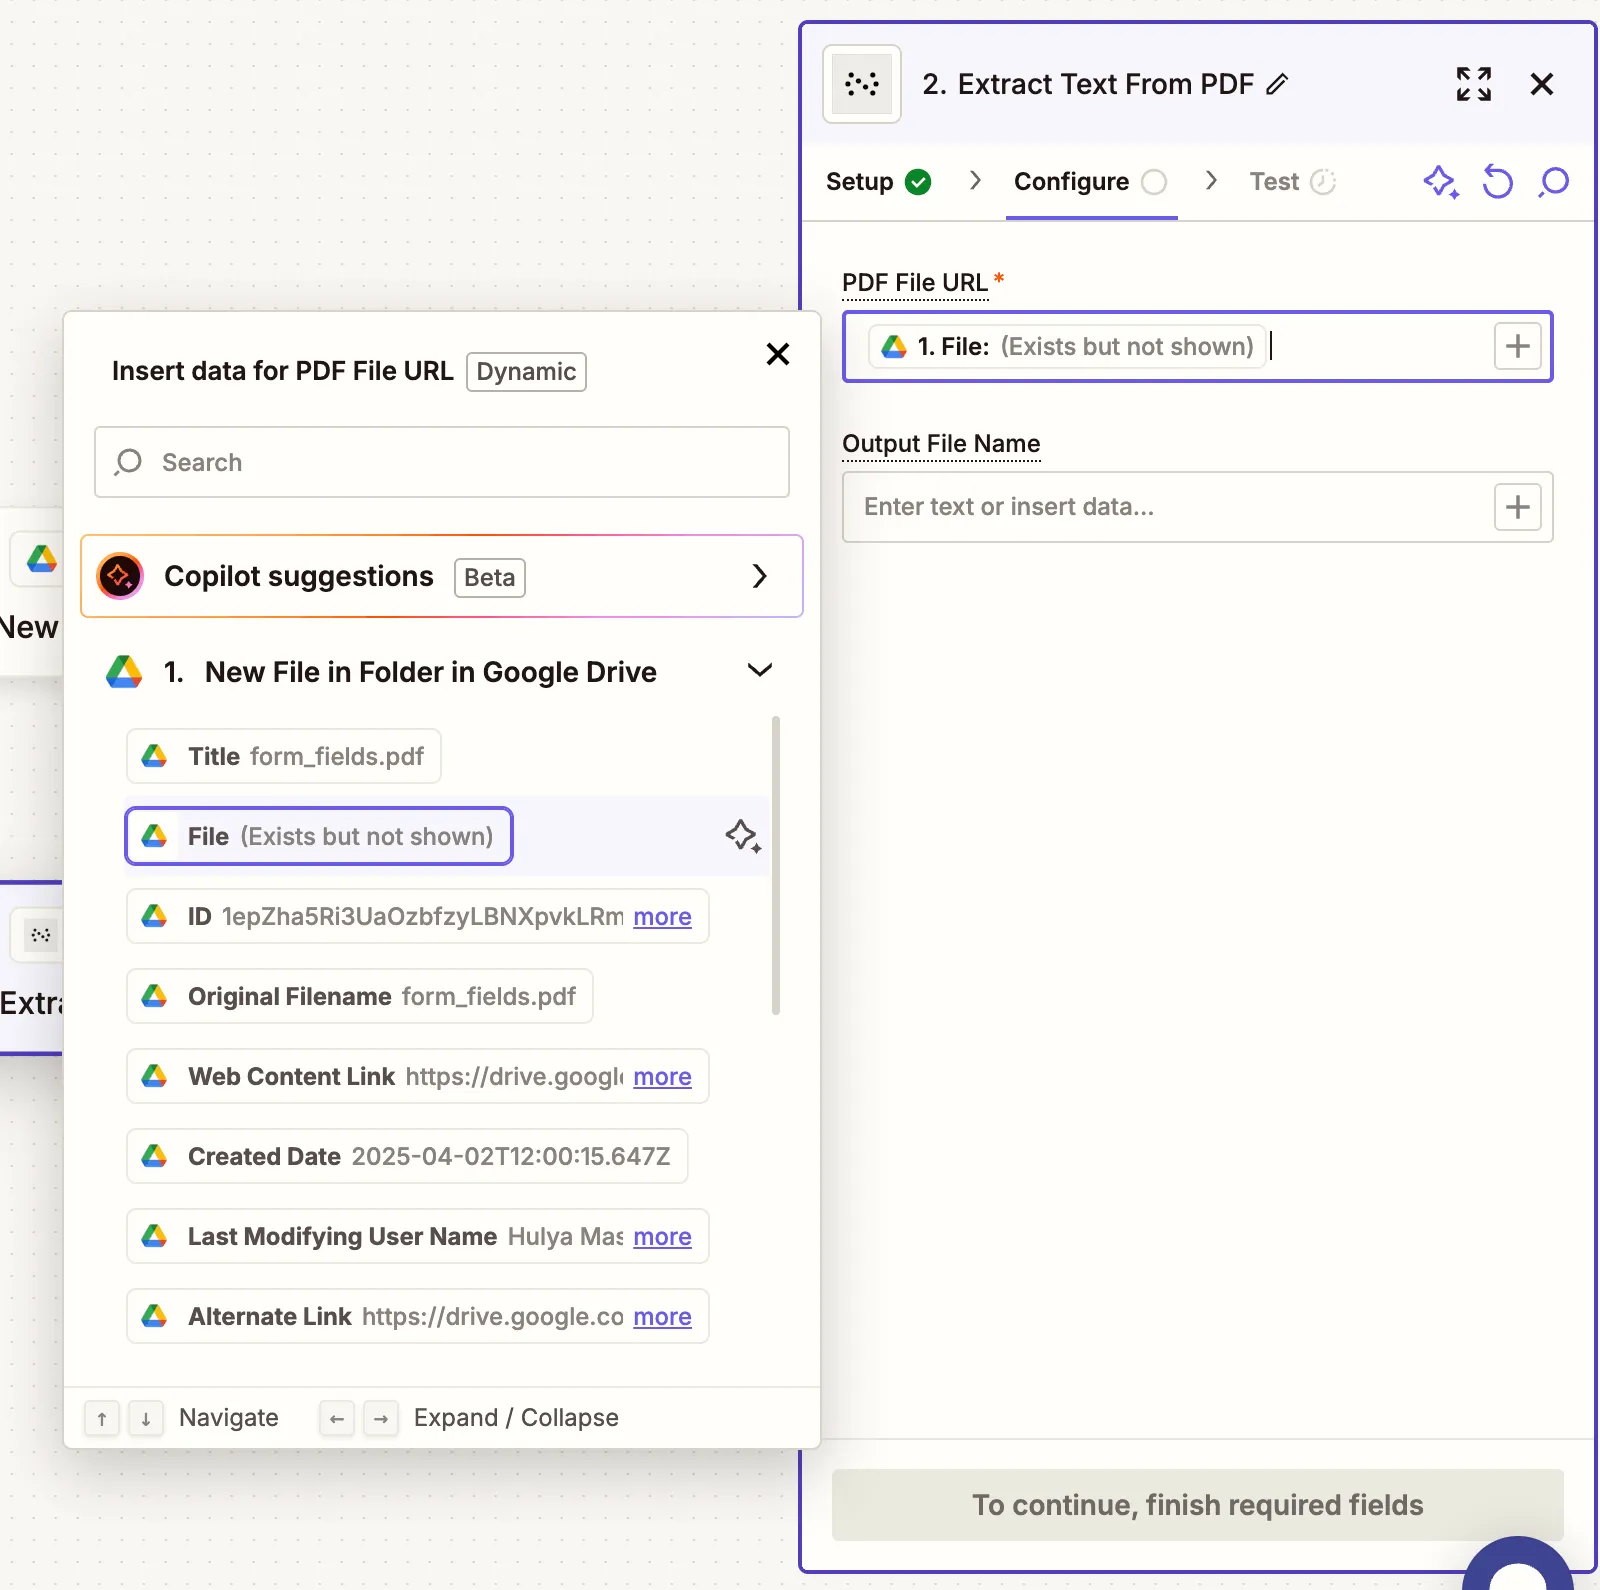
    Fields filled with PDF URL and output file name

    Make sure the file is publicly accessible or uploaded through a supported trigger like Google Drive.

    1. Run a test to ensure the extracted text is returned in structured JSON format.
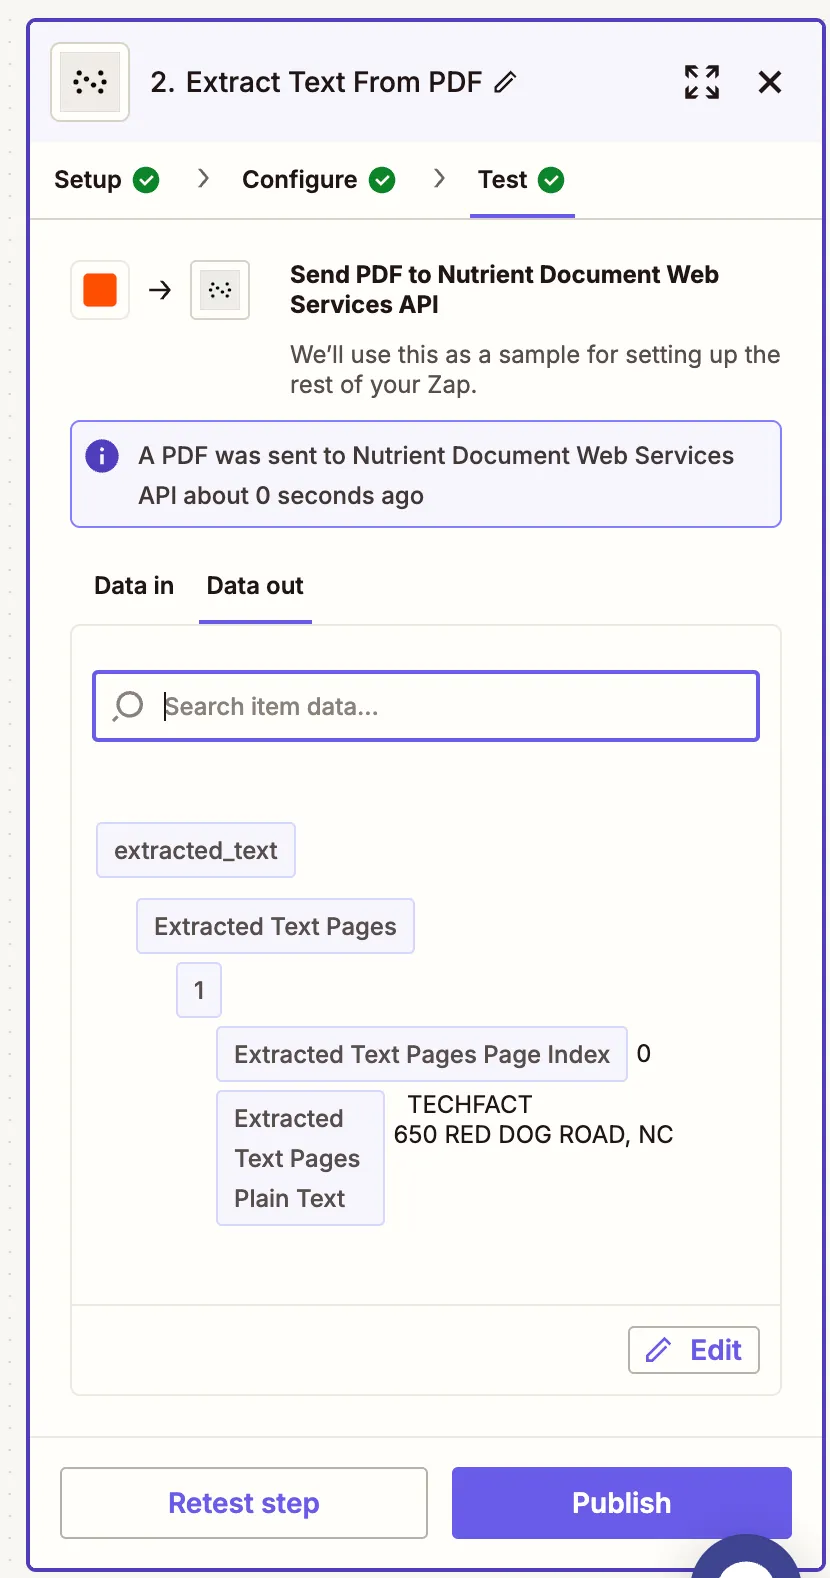
    Test result showing successfully extracted text

    1. Now, add another step by selecting Google Drive as the app and Upload File as the action event. Connect your Google Drive account if needed.
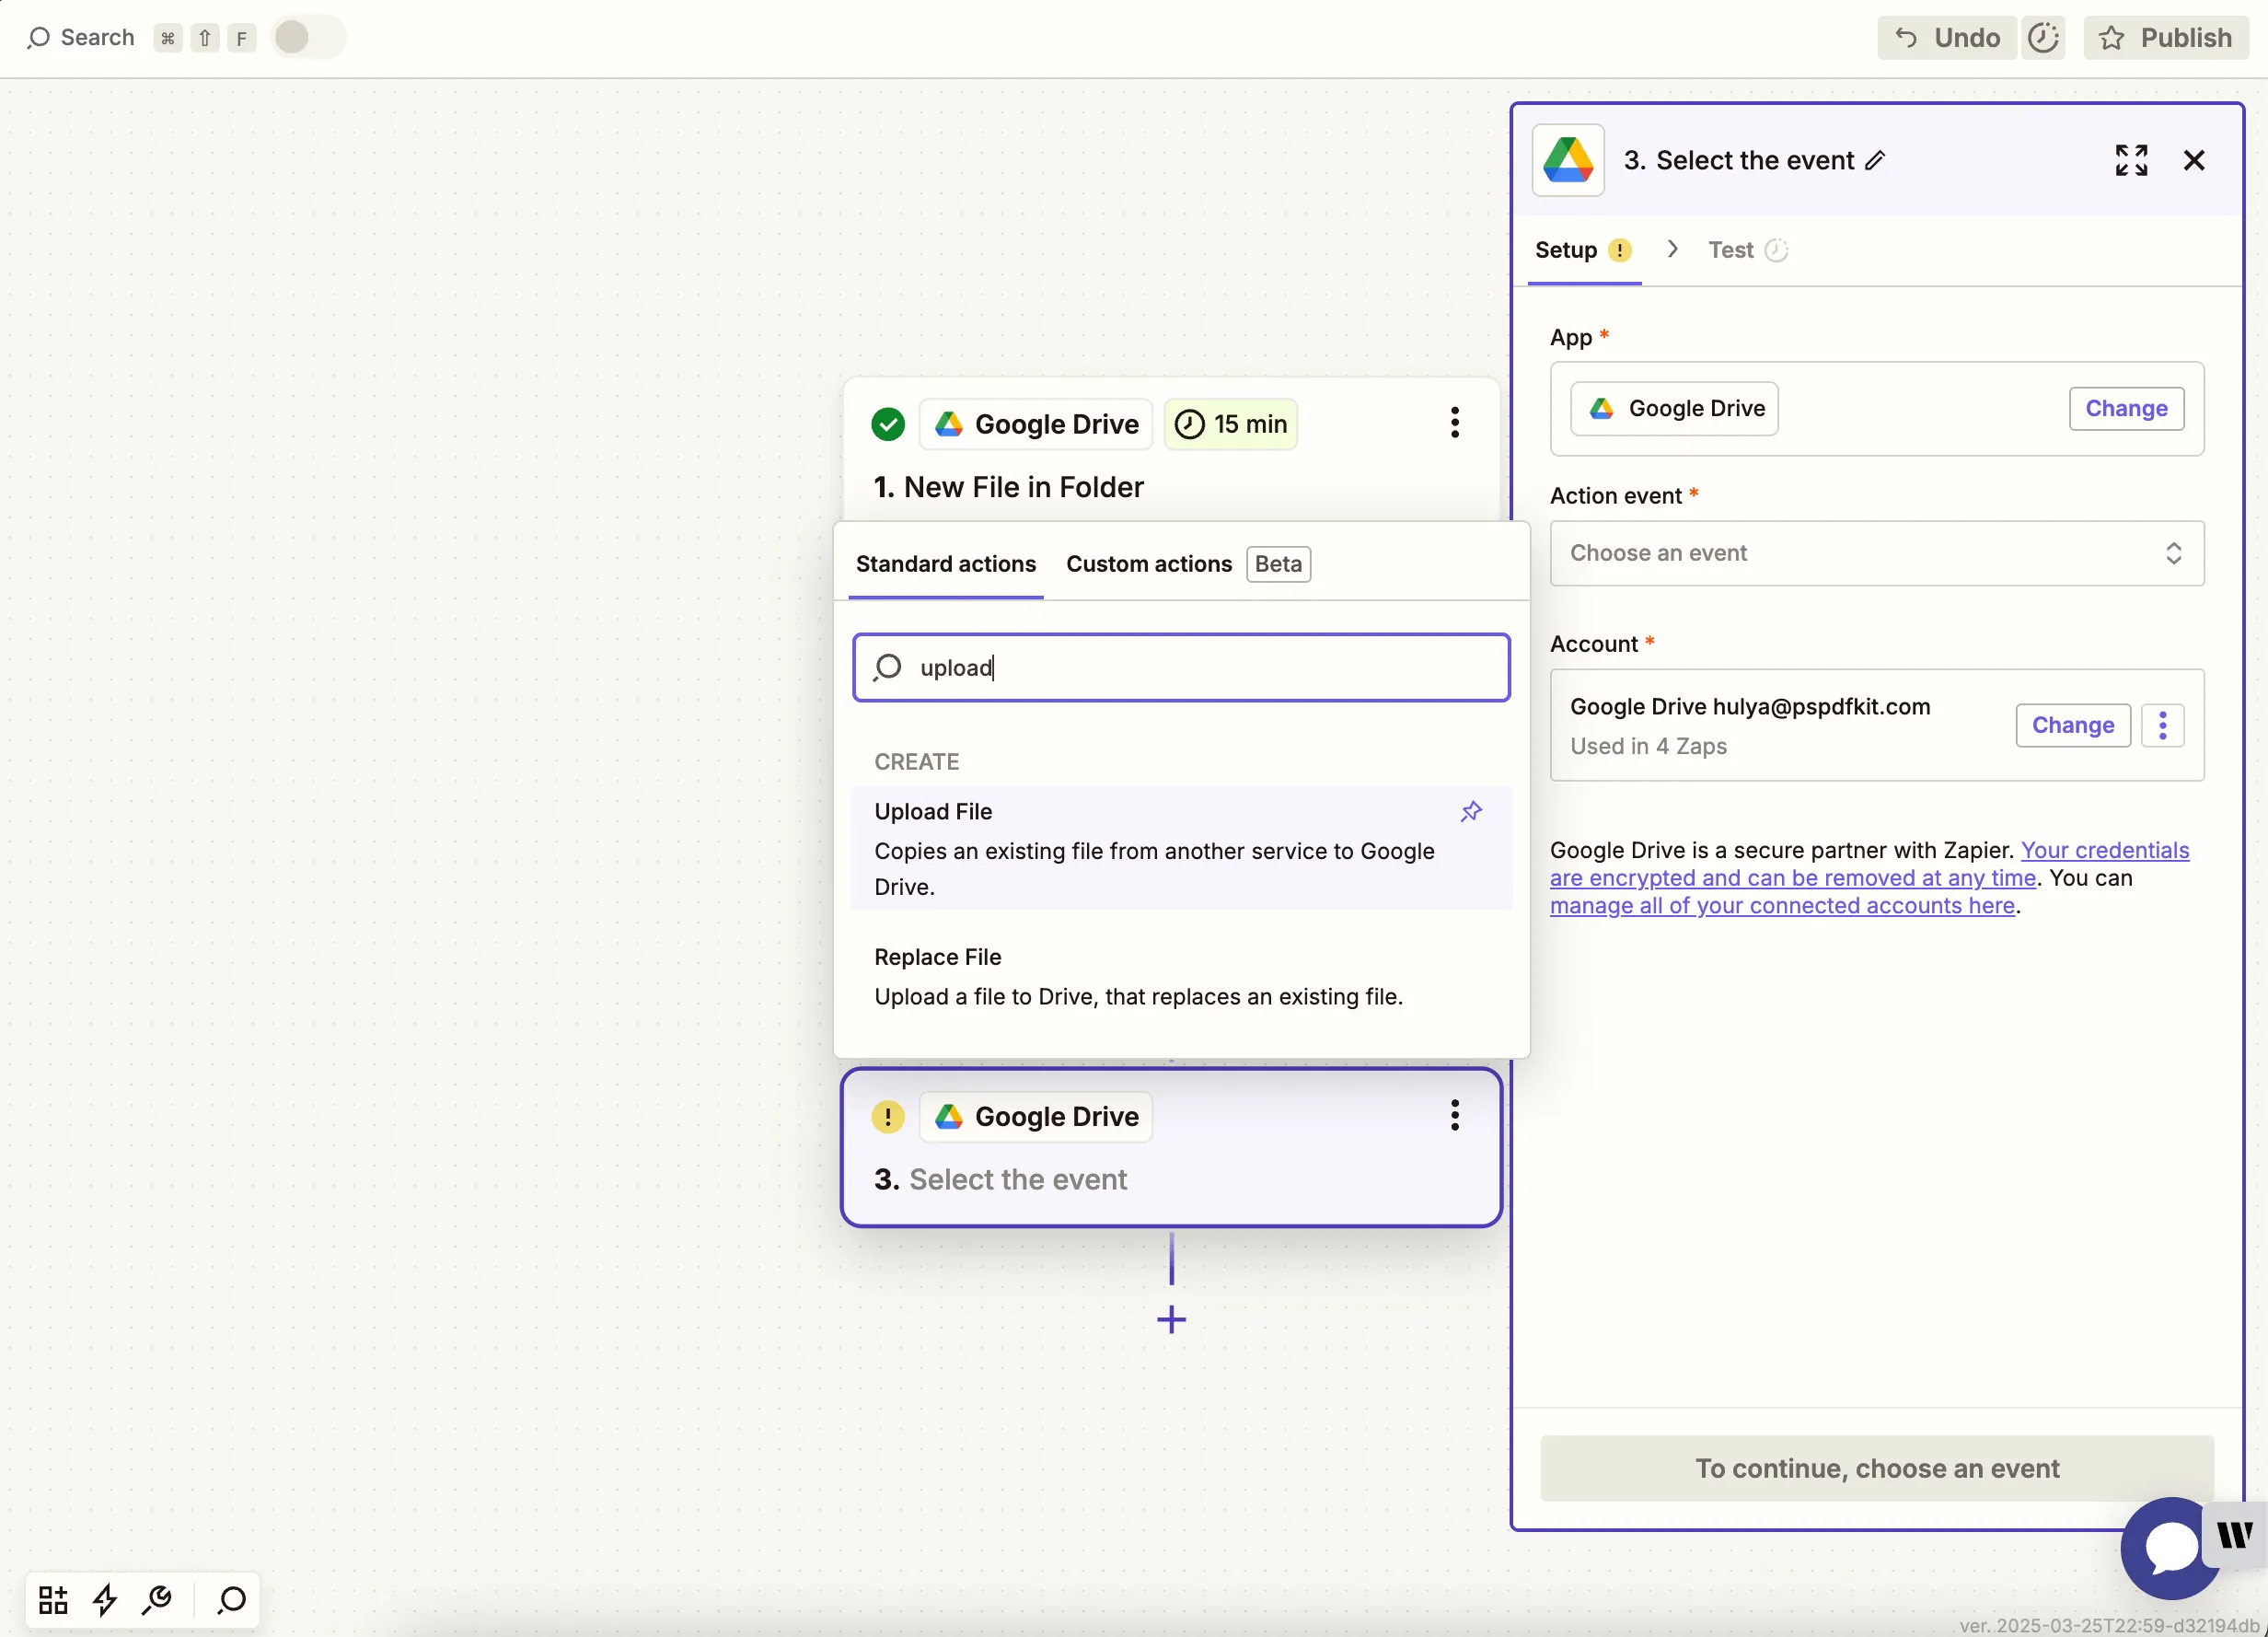
    Google Drive selected as output app for extracted text

    1. Choose your drive and output folder.
    2. In the File field, map the extracted JSON file or raw content.
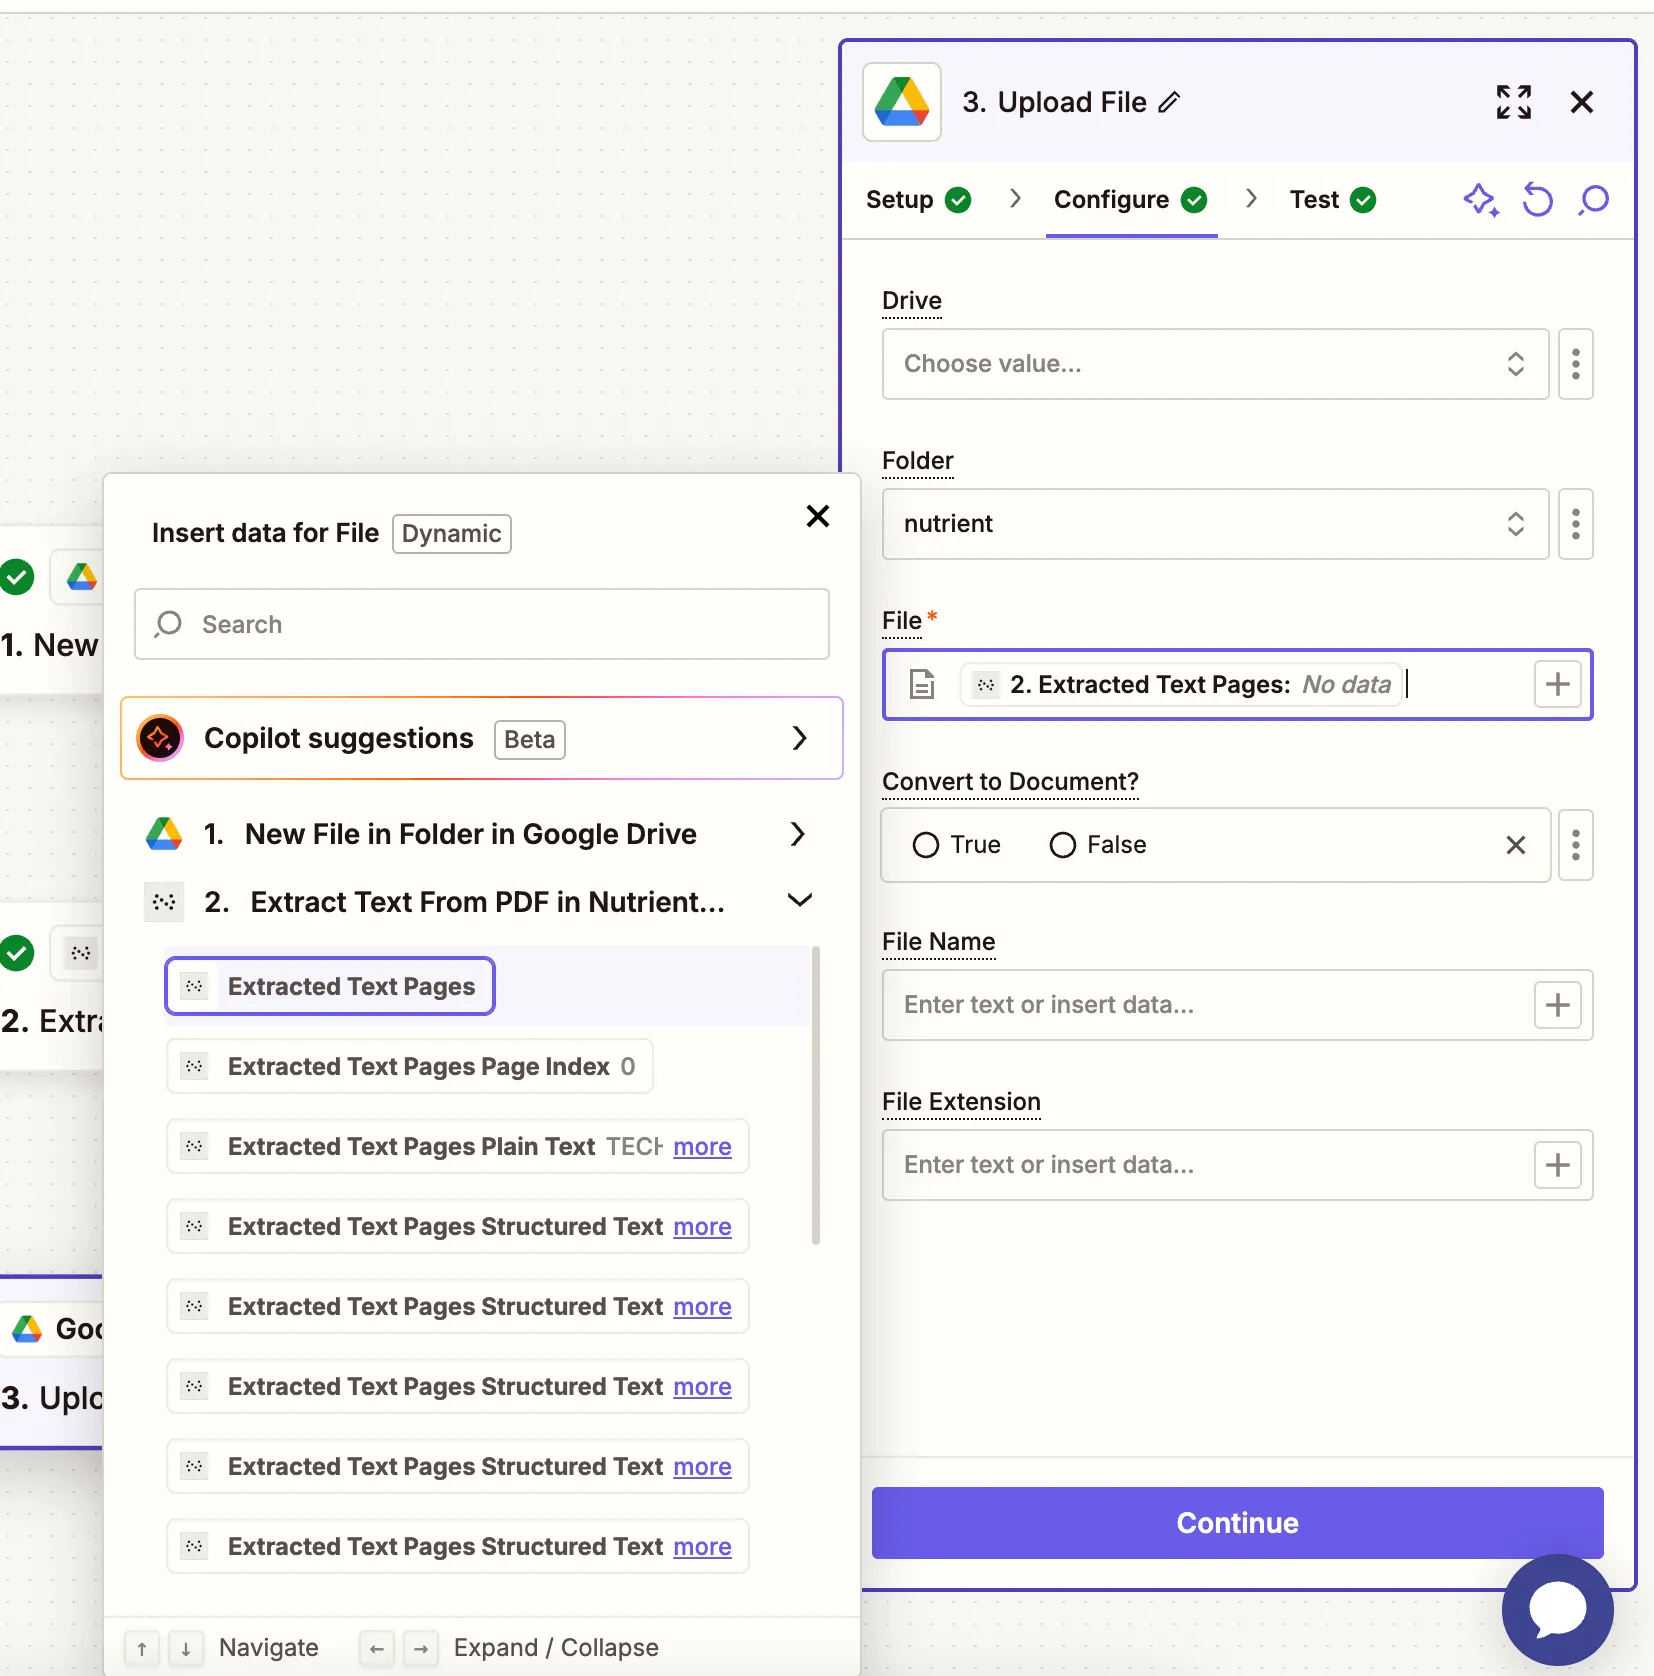
    Map extracted text as file upload to Google Drive

    1. Run a test to confirm the extracted file uploads properly.
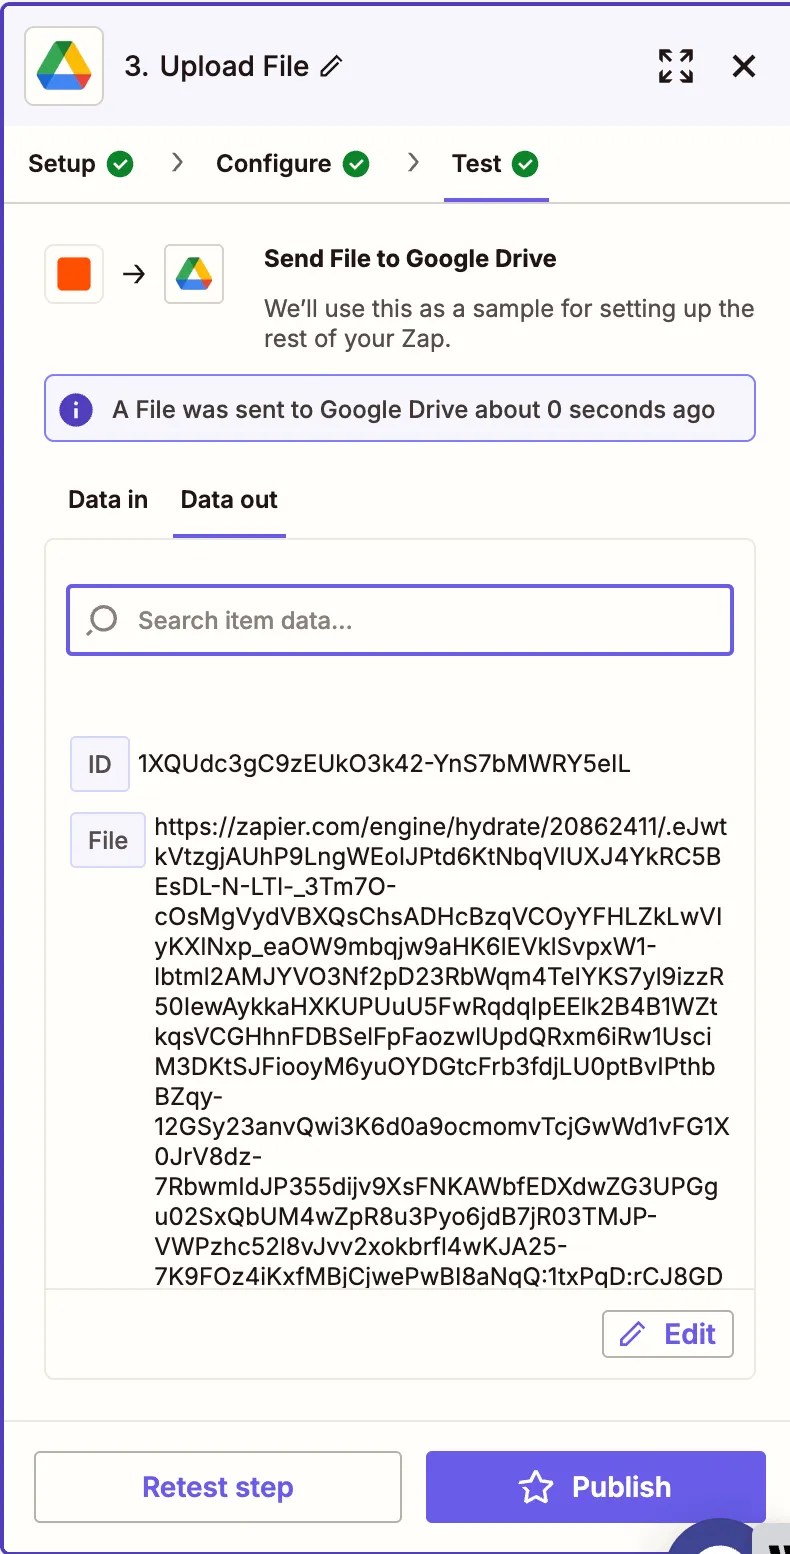
    Test confirming the extracted text was saved to Google Drive

    Conclusion

    With this Zap, you’ve automated the process of extracting plain and structured text from PDFs using Nutrient DWS Processor API(opens in a new tab). This workflow is ideal for indexing content, digitizing business records, or feeding content into CRMs and data pipelines.

    You can expand this flow with steps for table extraction, OCR scanning, or automatic uploading to Notion(opens in a new tab).

    Explore related topics

    Try for free Ready to get started?

    Related SDK articles

    Explore more