


TL;DR
The release of Nutrient DWS MCP Server(opens in a new tab) 0.0.4 adds PDF-to-HTML, Markdown, and PDF/UA conversion capabilities, injecting structure where it was previously lost, and enhancing accessibility to stay up to date and compliant with new regulations.
My first tests connecting Claude Code with Nutrient DWS MCP Server led me to create what might be the most interesting website known to mankind: the “US Tax Forms Browser” — every US citizen’s favorite tax forms, now beautifully rendered in HTML. But behind this tongue-in-cheek project lies something genuinely useful: Claude Code can now talk directly to powerful document processing tools, completely changing how we handle documents. No more API specifications locked up in the PDF format, no painful conversion scripts to extract key information for your application. Now it’s trivial and dynamic.
PDFs are everywhere in business and government. Tax forms, legal documents, reports, manuals — critical information trapped in a format designed for viewing, but not autonomously processing.
Here at Nutrient, we’ve been solving this problem for customers for years, and now we’re solving this problem for AI.
The challenges are real:
The latest release of Nutrient Document Web Services (DWS) MCP Server(opens in a new tab) introduces conversion capabilities that solve many of the unstructured issues mentioned above.
The new output formats unlock entirely new workflows:
This next section will show how this works in practice with a real-world example using Claude Code and Nutrient DWS MCP Server.
Get started with Nutrient DWS Processor API today and receive 50 free credits monthly! Perfect for watermark-free document processing targeting many use cases.
I was frustrated by the experience of browsing US tax forms. The challenge? All the official forms exist only as PDFs — requiring downloads and creating a poor experience on mobile devices and for LLMs that need to process the content.
Here’s how the new DWS MCP Server capabilities helped solve that in 20 minutes.
To set up DWS MCP Server with Claude Code, you’ll first need an API key from nutrient.io(opens in a new tab). Then, add the server to your project:
# Add DWS MCP Server to your Claude Code project.
claude mcp add dws-mcp-server -e NUTRIENT_DWS_API_KEY=<your-dws-api-key> -- npx -y @nutrient-sdk/dws-mcp-server --sandbox <your-project-dir>
Once configured, the MCP servers become available in Claude Code (/mcp command):
# MCP servers now available in Claude Code
1. dws-mcp-server ✓ connected
Now Nutrient DWS MCP Server can access any file within your project directory and send it off for processing.
With a folder full of tax form PDFs organized by category, converting them to HTML became trivial by simply asking Claude:
Please convert all the tax forms in the `irs-forms` directory to HTML.
Previously, I would’ve had to find a program or library to convert all these documents, and then write a script to do so. Now I just ask Claude Code to do it. And this isn’t just limited to forms; this could be documentation Claude Code needs access to, business logic that’s locked up in documents, and yes, it can OCR screenshots with code snippets!
You’ll see Claude Code making MCP calls to the DWS MCP Server for each file. And like magic, HTML appears:
⏺ dws-mcp-server:document_processor (MCP)(instructions:
{"parts":[{"file":"irs-forms/schedules/f1040s2.pdf"
}],"output":{"type":"html","layout":"reflow"}},
outputPath:
"converted-forms/schedules/f1040s2.html")
⎿ File processed successfully using build API and saved to: .../u
s-tax-forms/converted-forms/schedules/f1040s2.html
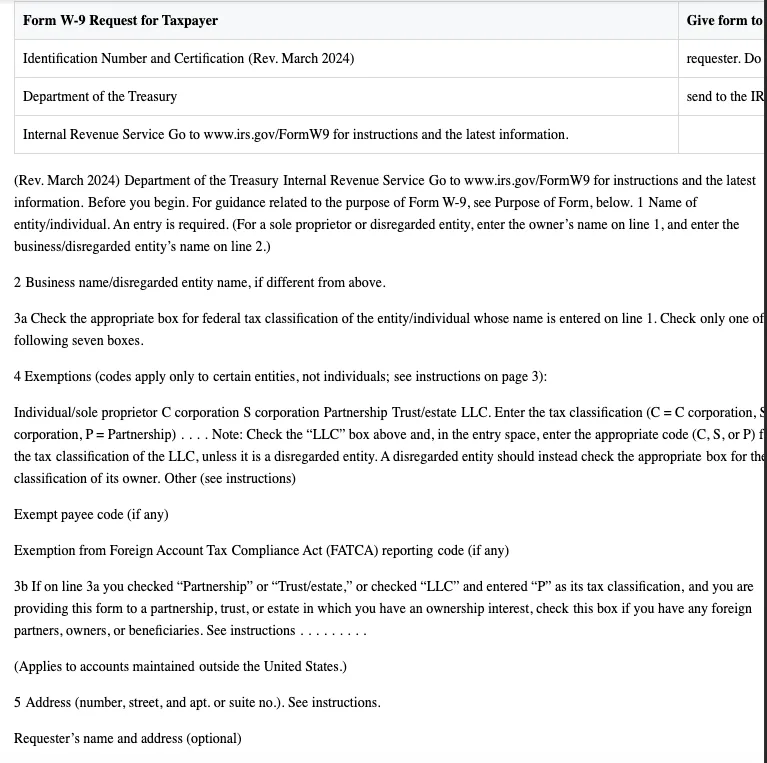
With HTML files ready to go, the final step was surprisingly straightforward. One more request to Claude Code:
Please can you take each converted HTML file and serve these as part of a small web application to allow users to better browse US tax forms. The landing page should display all the forms available in the applicable categories.
The result? A clean, organized interface where tax forms load instantly — forms organized by category, responsive design that actually responds, and navigation that makes sense. Twenty minutes from PDF folder to working web app.
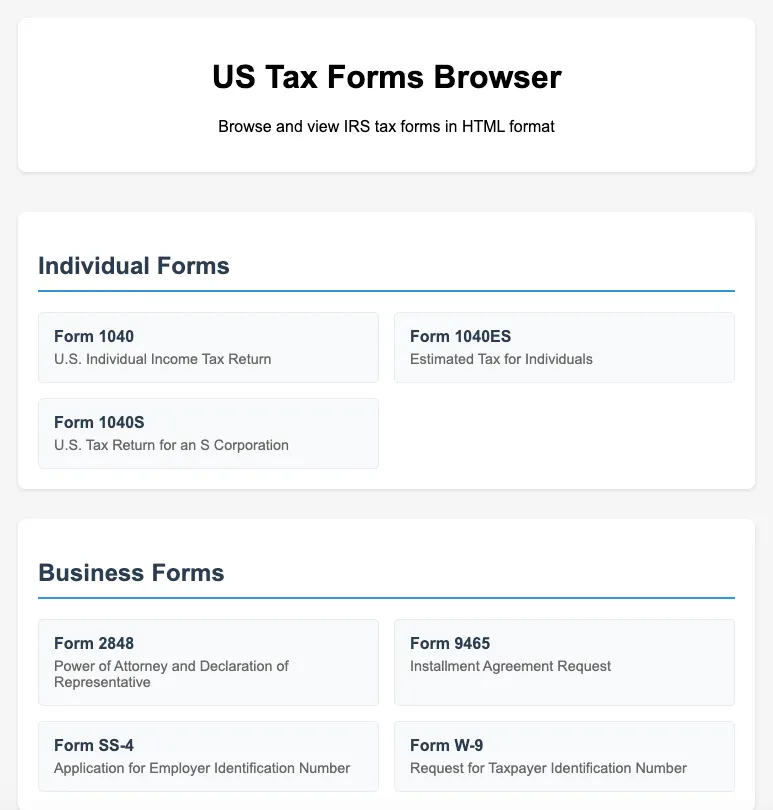
HTML solved this simple PDF viewing problem, but what about AI? LLMs struggle with PDFs — they can’t parse the structure, miss crucial formatting, and often hallucinate content. That’s where Markdown conversion comes in.
Say your company has years of technical documentation trapped in PDFs. API specs, architecture decisions, compliance documents — all locked away from your AI tools. With DWS MCP Server and Claude Code, you can drop those documents into your project and unlock that knowledge in a single command:
Please can you convert the PDFs in the `docs` directory to Markdown.
Suddenly, Claude Code (and any AI developer tool) can read your documentation as easily as your source code. No more copying and pasting from PDF viewers or other clients. No more OCR errors. Just clean, structured text that LLMs understand. Your specification documents become queryable. Your architectural decisions become searchable. Your business logic becomes accessible.
While I’ve focused on the developer experience here, the implications go far beyond coding workflows. The Model Context Protocol isn’t limited to Claude Code — it’s a universal standard. That means these same document processing capabilities work in Claude Desktop and any application that’s MCP compatible.
Your customer support team can convert product manuals. Legal departments can review and digitally sign contracts. And HR can extract resume information for additional processing. All it takes is natural language and DWS MCP Server.
For a deeper dive into all the capabilities — including advanced features like PDF merging, splitting, and watermarking — check out the original release blog post, where you’ll find a comprehensive video walkthrough.
Start using Nutrient DWS MCP Server to convert documents into HTML and Markdown — and give your LLMs the structured data they need. Whether you’re building AI apps, improving accessibility, or just tired of wrestling with PDFs, it’s time to upgrade your workflow. Get your API key and start building(opens in a new tab).
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。