


Table of contents
One of the key changes introduced in Muhimbi PDF Converter Services v11.0 is the inclusion of key-value pair (KVP) extraction from PDF documents. This feature takes advantage of AI, machine learning (ML), and advanced layout understanding to extract meaningful information from unstructured documents and images.
The Muhimbi Document Converter Diagnostics Tool, installed along the service, can help you discover these new features.
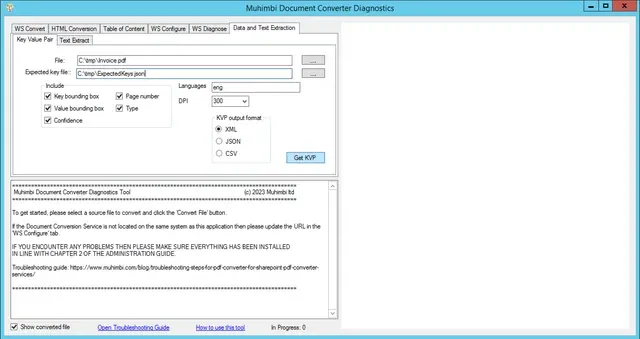
This post provides a simple example describing how to take advantage of this new feature programmatically.
Key-value pair extraction offers numerous benefits for businesses and developers:
Automated data extraction — Automate the tedious process of extracting data from documents, reducing manual labor and human error. Enhanced accuracy — Utilize AI PDF data extraction and ML technologies to ensure high accuracy in data extraction, even from complex and unstructured documents. Save time — Significantly speed up data processing times by automating extraction tasks that would otherwise take hours to complete manually. Versatile integration — Integrate with various applications and services, enhancing the functionality and efficiency of existing systems. Improved data handling — Ensure consistent and structured data output, making it easier to handle, analyze, and utilize extracted information.
This tutorial shows how to create a .NET Framework console application and extract key-value pairs from a PDF document.
- Download and install Muhimbi PDF Converter or Muhimbi PDF Converter Services from our website.
- Create a new Console Application project in Visual Studio called KVPExtraction. The actual version of the .NET Framework isn’t important, as Web Services are system-agnostic, meaning they can be used by client applications written in a wide variety of programming languages.
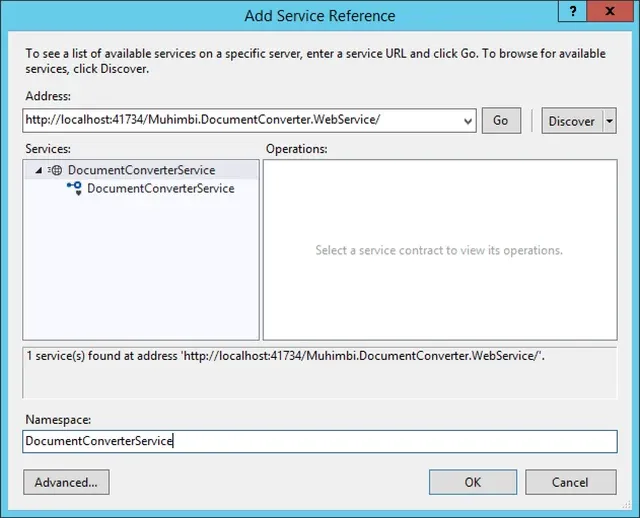
- In the Solution Explorer window, right-click the project and select Add > Service Reference. Set the Address field to
https://localhost:41734/Muhimbi.DocumentConverter.WebService/and click Go. Define your desired namespace (in this case,DocumentConverterService) and click OK. This will generate the required proxy classes to be able to work with the Web Service.
- In your
Program.csfile, add the following code:
using KVPExtraction.DocumentConverterService;
using System;
using System.IO;
using System.ServiceModel;
namespace KVPExtraction
{
class Program
{
// The URL where the Web Service is located. Amend host name if needed.
static string SERVICE_URL = "https://localhost:41734/Muhimbi.DocumentConverter.WebService/";
static void Main(string[] args)
{
DocumentConverterServiceClient client = null;
try
{
// Determine the source file and read it into a byte array.
string sourceFileName = null;
if (args.Length == 0)
{
// If nothing is specified then read the first PDF file from the current folder.
string[] sourceFiles = Directory.GetFiles(Directory.GetCurrentDirectory(), "*.pdf");
if (sourceFiles.Length > 0)
sourceFileName = sourceFiles[0];
else
{
Console.WriteLine("Please specify a document to extract key-value pairs from.");
Console.ReadKey();
return;
}
}
else
sourceFileName = args[0];
string expectedKeys = null;
if (args.Length > 1)
{
// The second argument is the expected keys file. Read its content.
expectedKeys = File.ReadAllText(args[1]);
}
else
{
// Uncomment the line below if you wish to use the following expected keys.
//expectedKeys = "[{\"expectedKey\":\"grand total\",\"synonyms\":[\"total\"]},{\"expectedKey\":\"invoice number\",\"synonyms\":[\"invoice no.\"]}]";
}
byte[] sourceFile = File.ReadAllBytes(sourceFileName);
// Open the service and configure the bindings.
client = OpenService(SERVICE_URL);
// Set the absolute minimum open options.
OpenOptions openOptions = new OpenOptions();
openOptions.OriginalFileName = Path.GetFileName(sourceFileName);
openOptions.FileExtension = Path.GetExtension(sourceFileName);
// Set the parameters for extracting key-value pairs.
KVPSettings kvpSettings = new KVPSettings()
{
// Specify whether or not the internal image should be automatically rotated.
AutoRotate = BooleanEnum.True,
// Only include results with a confidence higher than the threshold (in %).
ConfidenceThreshold = 50,
// Specify virtual resolution for retrieving data. Higher values will make the process more accurate but slower.
DPI = 300,
// Specify the expected keys or leave empty to resolve all pairs.
// Please note that extra information isn't included when `ExpectedKeys` is used.
ExpectedKeys = expectedKeys,
// Specify whether or not the confidence value for the extracted key-value pair should be included in the result.
IncludeConfidence = BooleanEnum.True,
// Specify whether or not the bounding box information for the key should be included.
IncludeKeyBoundingBox = BooleanEnum.True,
// Specify whether or not the page number the pair was found on should be included.
IncludePageNumber = BooleanEnum.True,
// Specify whether or not the type of the value should be included.
IncludeType = BooleanEnum.True,
// Specify whether or not the bounding box of the value should be included.
IncludeValueBoundingBox = BooleanEnum.True,
// Specify the desired output format (XML, JSON, or CSV).
KVPFormat = KVPOutputFormat.CSV,
// Specify the language used for OCR.
OCRLanguage = "eng",
// Specify the range of pages to search on.
PageRange = null,
// Specify whether or not extra symbols should be trimmed from values.
TrimSymbols = BooleanEnum.False
};
Console.WriteLine("Extracting key-value pairs.");
// Carry out the extraction.
byte[] result = client.ExtractKeyValuePairs(sourceFile, openOptions, kvpSettings);
if (result != null)
{
string destinationFileName = Path.GetFileNameWithoutExtension(sourceFileName) + "." + kvpSettings.KVPFormat;
using (FileStream fs = File.Create(destinationFileName))
{
fs.Write(result, 0, result.Length);
fs.Close();
}
Console.WriteLine("Result saved into " + destinationFileName);
}
else
{
Console.WriteLine("Nothing returned.");
}
Console.WriteLine("Finished.");
}
catch (FaultException<WebServiceFaultException> ex)
{
Console.WriteLine("FaultException occurred: ExceptionType: " +
ex.Detail.ExceptionType.ToString());
}
catch (Exception ex)
{
Console.WriteLine(ex.ToString());
}
finally
{
CloseService(client);
}
Console.ReadKey();
}
/// <summary>
/// Configure the bindings and endpoints and open the service using the specified address.
/// </summary>
/// <returns>An instance of the Web Service.</returns>
public static DocumentConverterServiceClient OpenService(string address)
{
DocumentConverterServiceClient client = null;
try
{
BasicHttpBinding binding = new BasicHttpBinding();
// Use standard Windows Security.
binding.Security.Mode = BasicHttpSecurityMode.TransportCredentialOnly;
binding.Security.Transport.ClientCredentialType =
HttpClientCredentialType.Windows;
// Increase the client Timeout to deal with (very) long running requests.
binding.SendTimeout = TimeSpan.FromMinutes(120);
binding.ReceiveTimeout = TimeSpan.FromMinutes(120);
// Set the maximum document size to 50MB.
binding.MaxReceivedMessageSize = 50 * 1024 * 1024;
binding.ReaderQuotas.MaxArrayLength = 50 * 1024 * 1024;
binding.ReaderQuotas.MaxStringContentLength = 50 * 1024 * 1024;
// Specify an identity (any identity) to get it past .net3.5 sp1.
EndpointIdentity epi = EndpointIdentity.CreateUpnIdentity("unknown");
EndpointAddress epa = new EndpointAddress(new Uri(address), epi);
client = new DocumentConverterServiceClient(binding, epa);
client.Open();
return client;
}
catch (Exception)
{
CloseService(client);
throw;
}
}
/// <summary>
/// Check if the client is open and then close it.
/// </summary>
/// <param name="client">The client to close.</param>
public static void CloseService(DocumentConverterServiceClient client)
{
if (client != null && client.State == CommunicationState.Opened)
client.Close();
}
}
}
Sample input
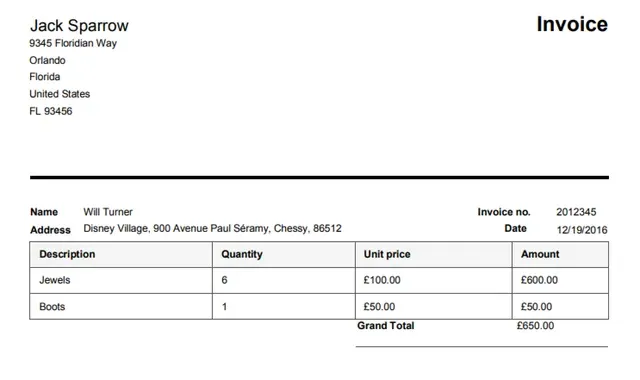
When the program above is executed on the PDF document and expected keys JSON below, it retrieves values for the expected keys and their synonyms.
PDF document
Here’s an example of how the PDF document looks.
Expected keys
Here are the expected keys:
[
{
"expectedKey": "grand total",
"synonyms": ["total"]
},
{
"expectedKey": "invoice number",
"synonyms": ["invoice no."]
}
]
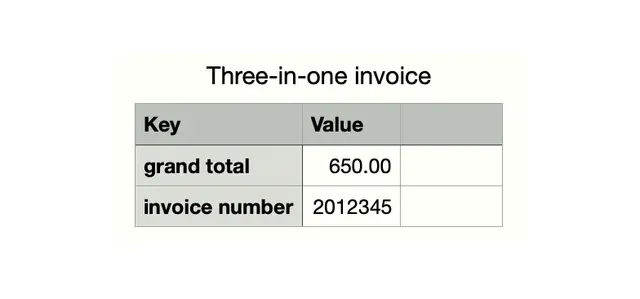
Sample output
Note: The expectedKey property from the JSON above is used as the key property in the output.
Conclusion
By leveraging Muhimbi PDF Converter Services’ new key-value pair extraction feature, you can streamline data extraction processes, reduce manual labor, and ensure high accuracy and consistency in your data handling workflows. Whether you’re processing invoices, forms, or any other documents, this feature can greatly enhance your document management system’s efficiency and effectiveness.