







Autobahn DX allows users to set up and customize workflows with ease and run them automatically. It also works well when processing large volumes of documents.
This guide details how to create automated PDF OCR workflows with Autobahn DX.
1. Set up a new job.
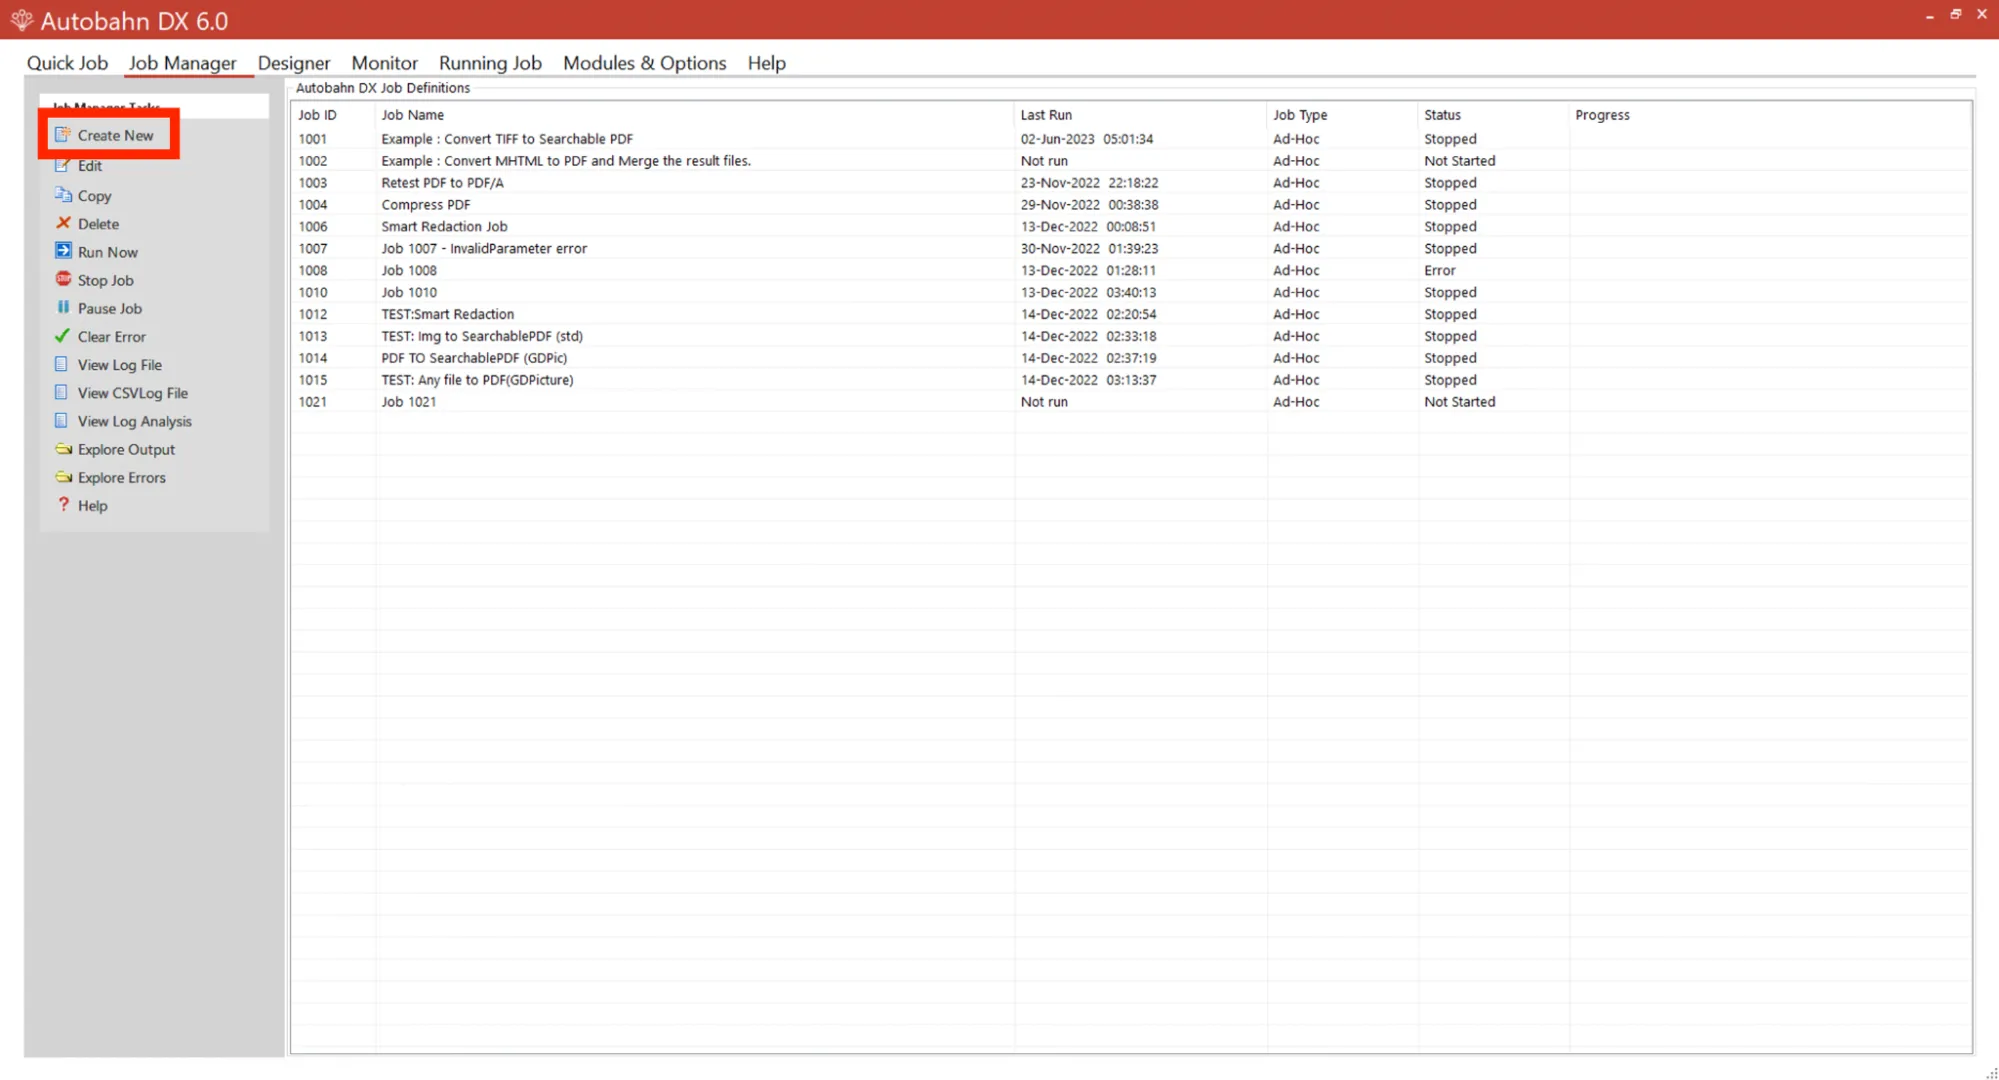
Click Create New. Fill in the Source Folder and Destination Folder fields by clicking the magnifying glass to the right of these fields. The source (input) folder is where all the files you want to process should go. The destination (output) folder is where all the processed files will end up.
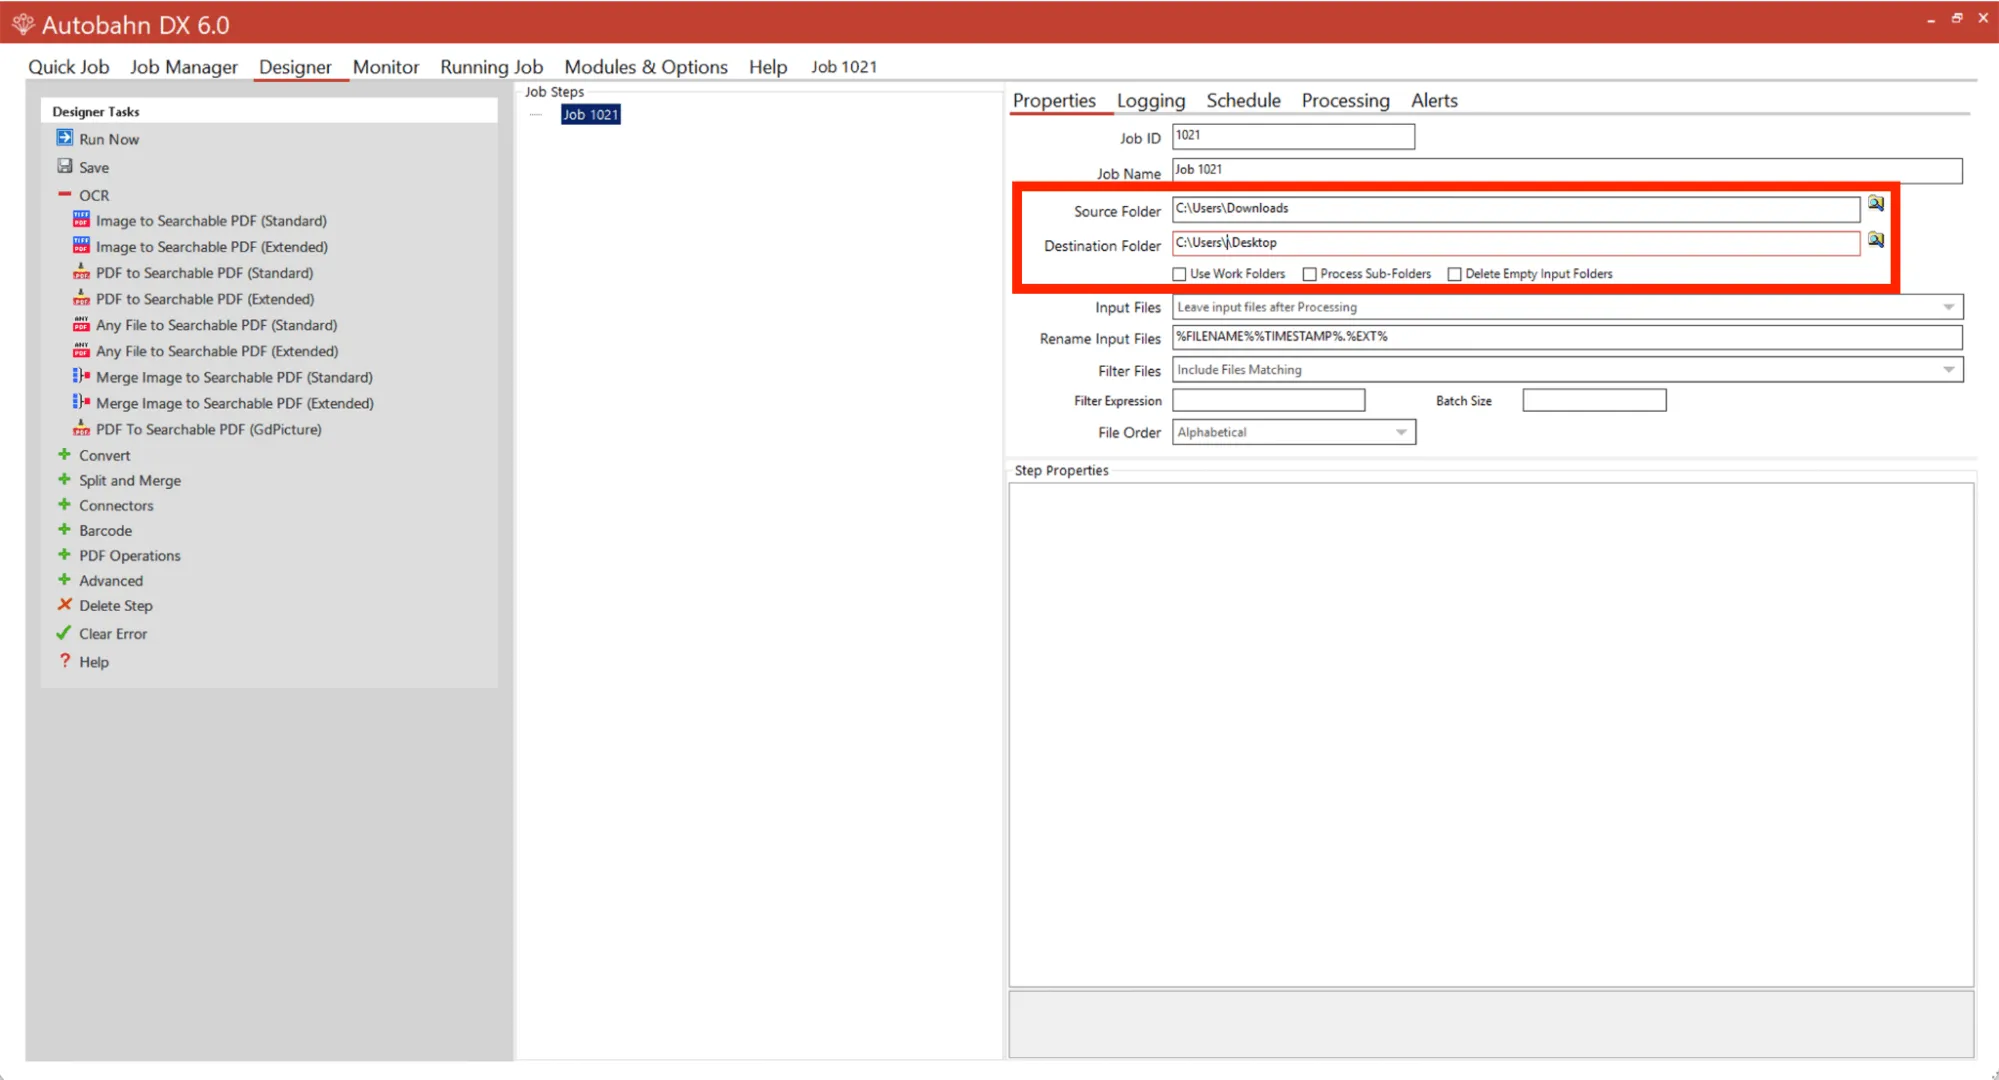
2. Select OCR to process your files.
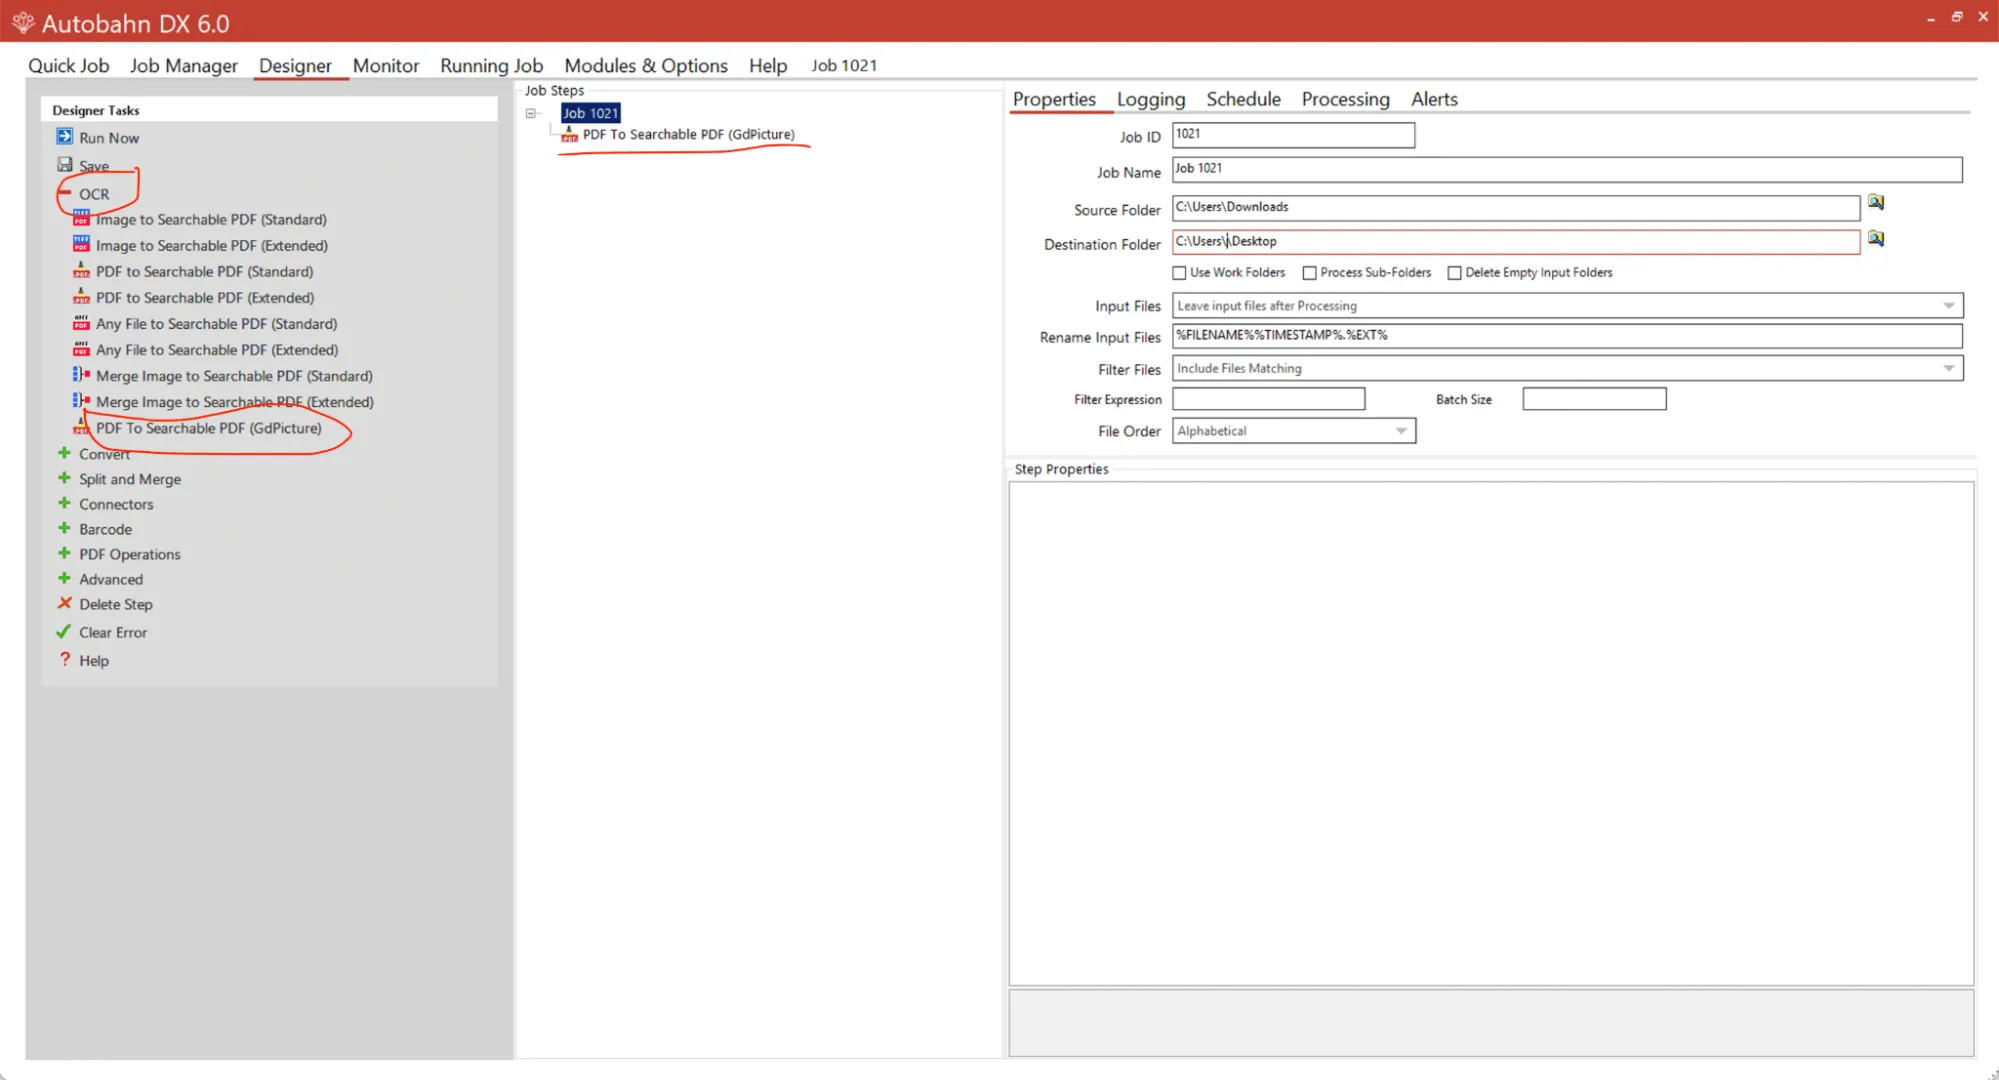
Under OCR , select PDF To Searchable PDF (GdPicture). This step uses the GdPicture engine, which is faster than the other OCR options, as it processes pages simultaneously with multithreading.
3. Choose the number of threads.
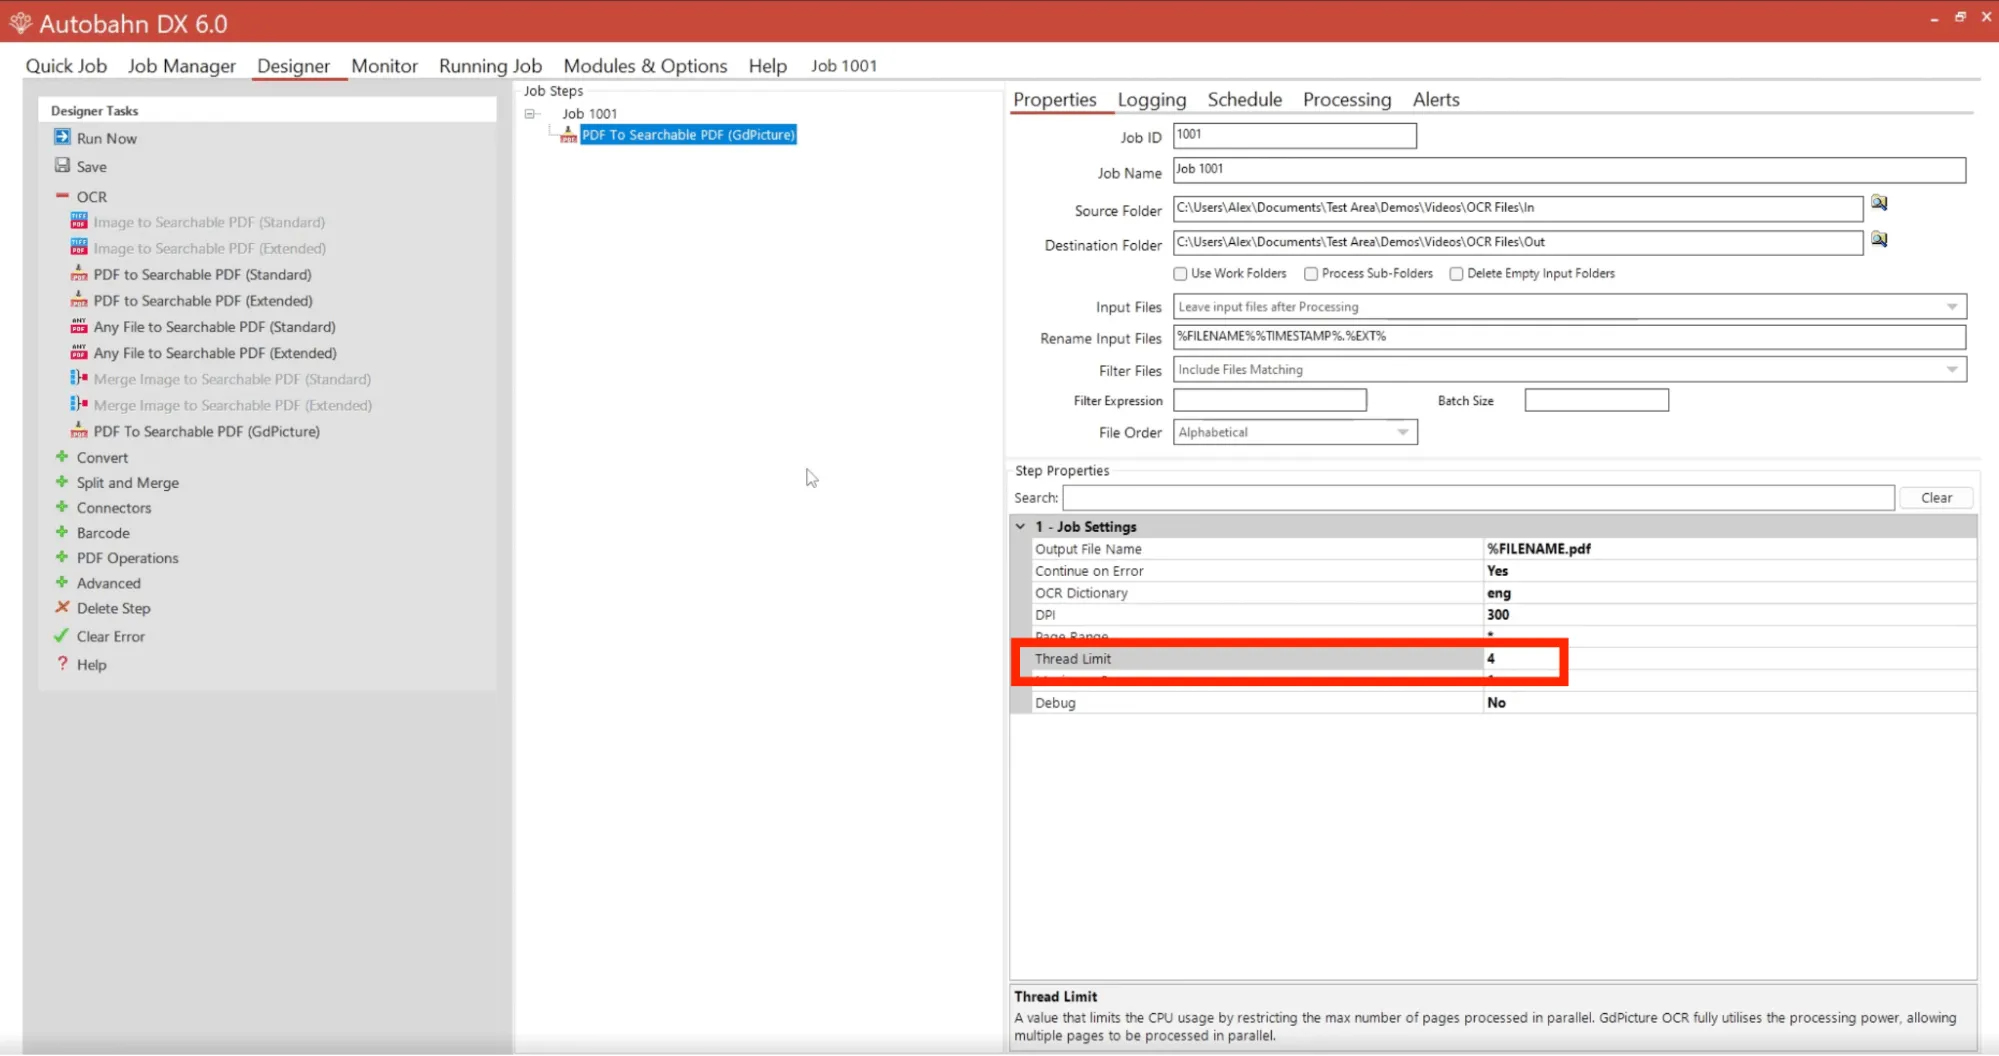
As OCR is a CPU-intensive process, you can choose the amount of threads to use by specifying the number in the Thread Limit field.
4. Save the job and return to the Job Manager.
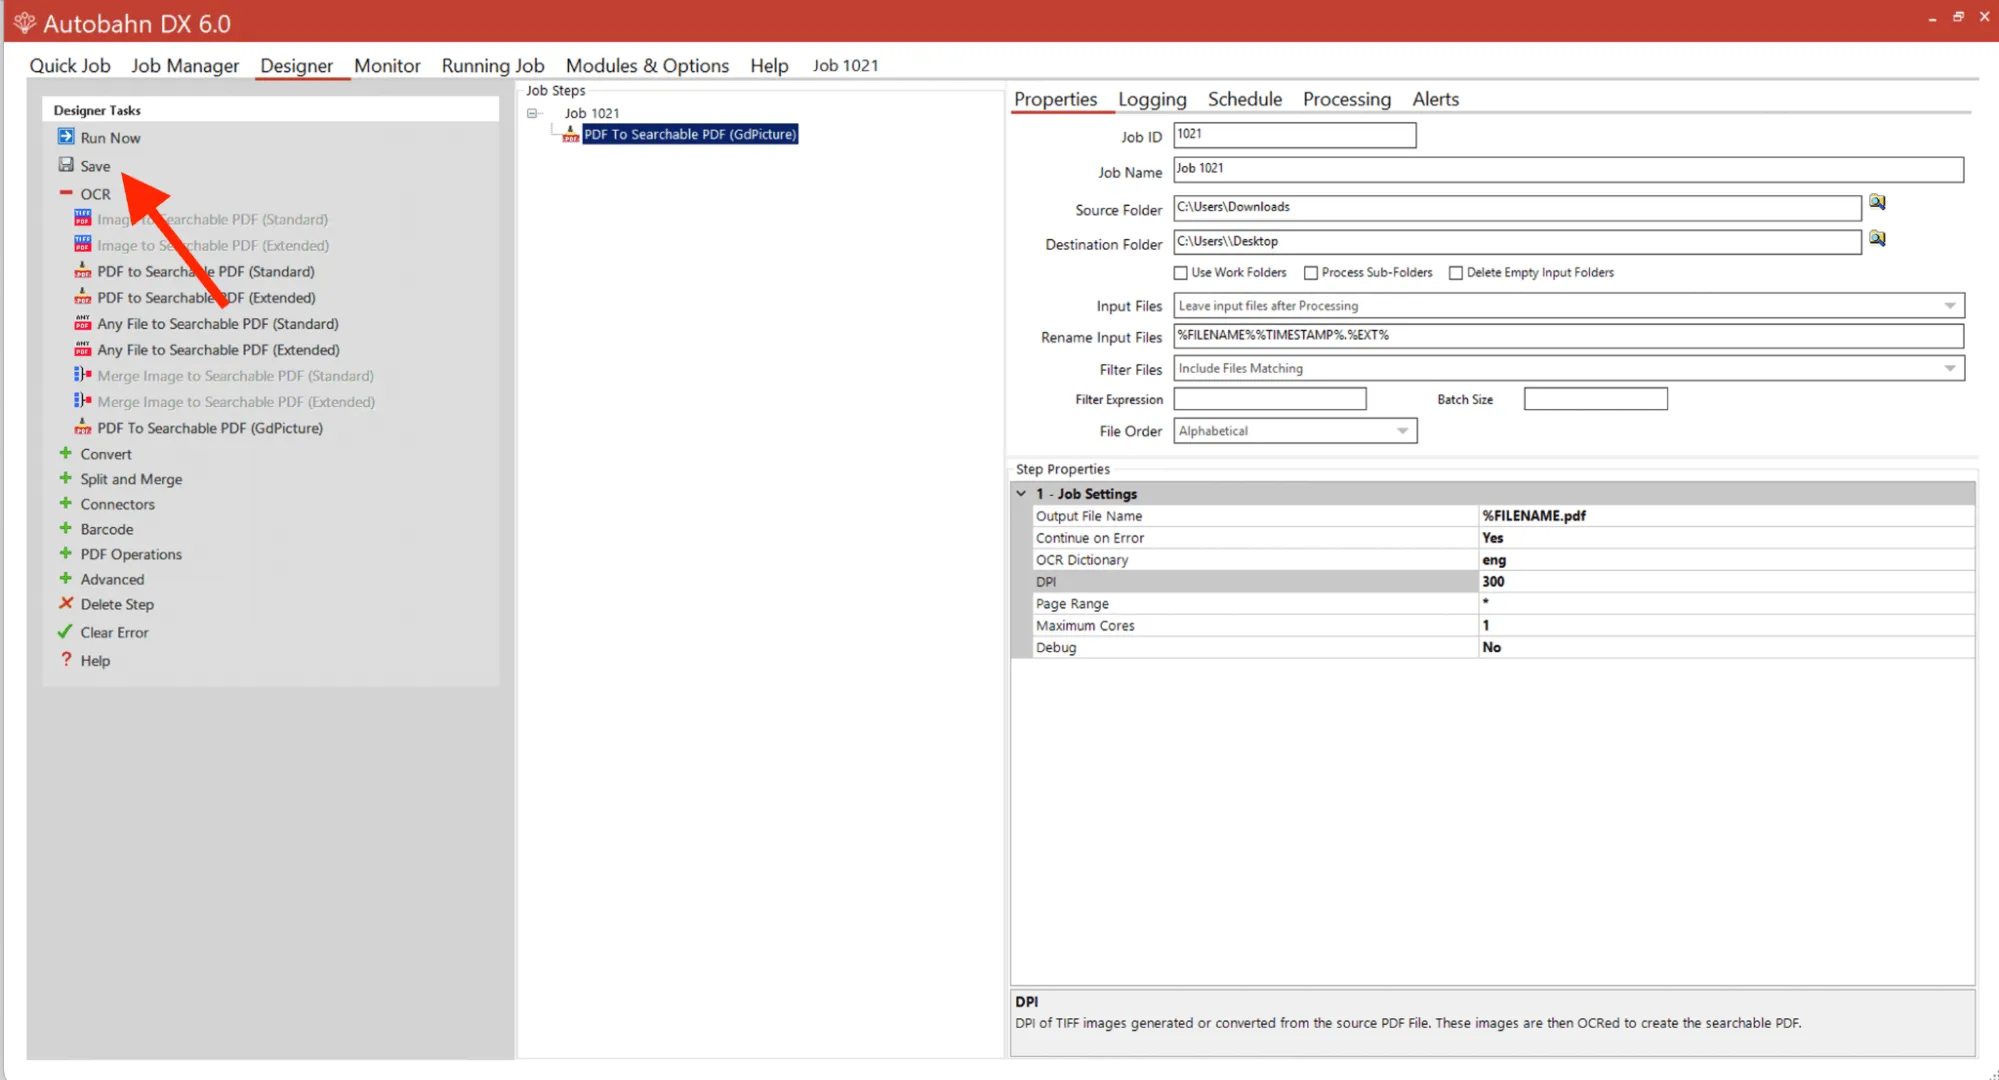
5. Schedule the job to run automatically.
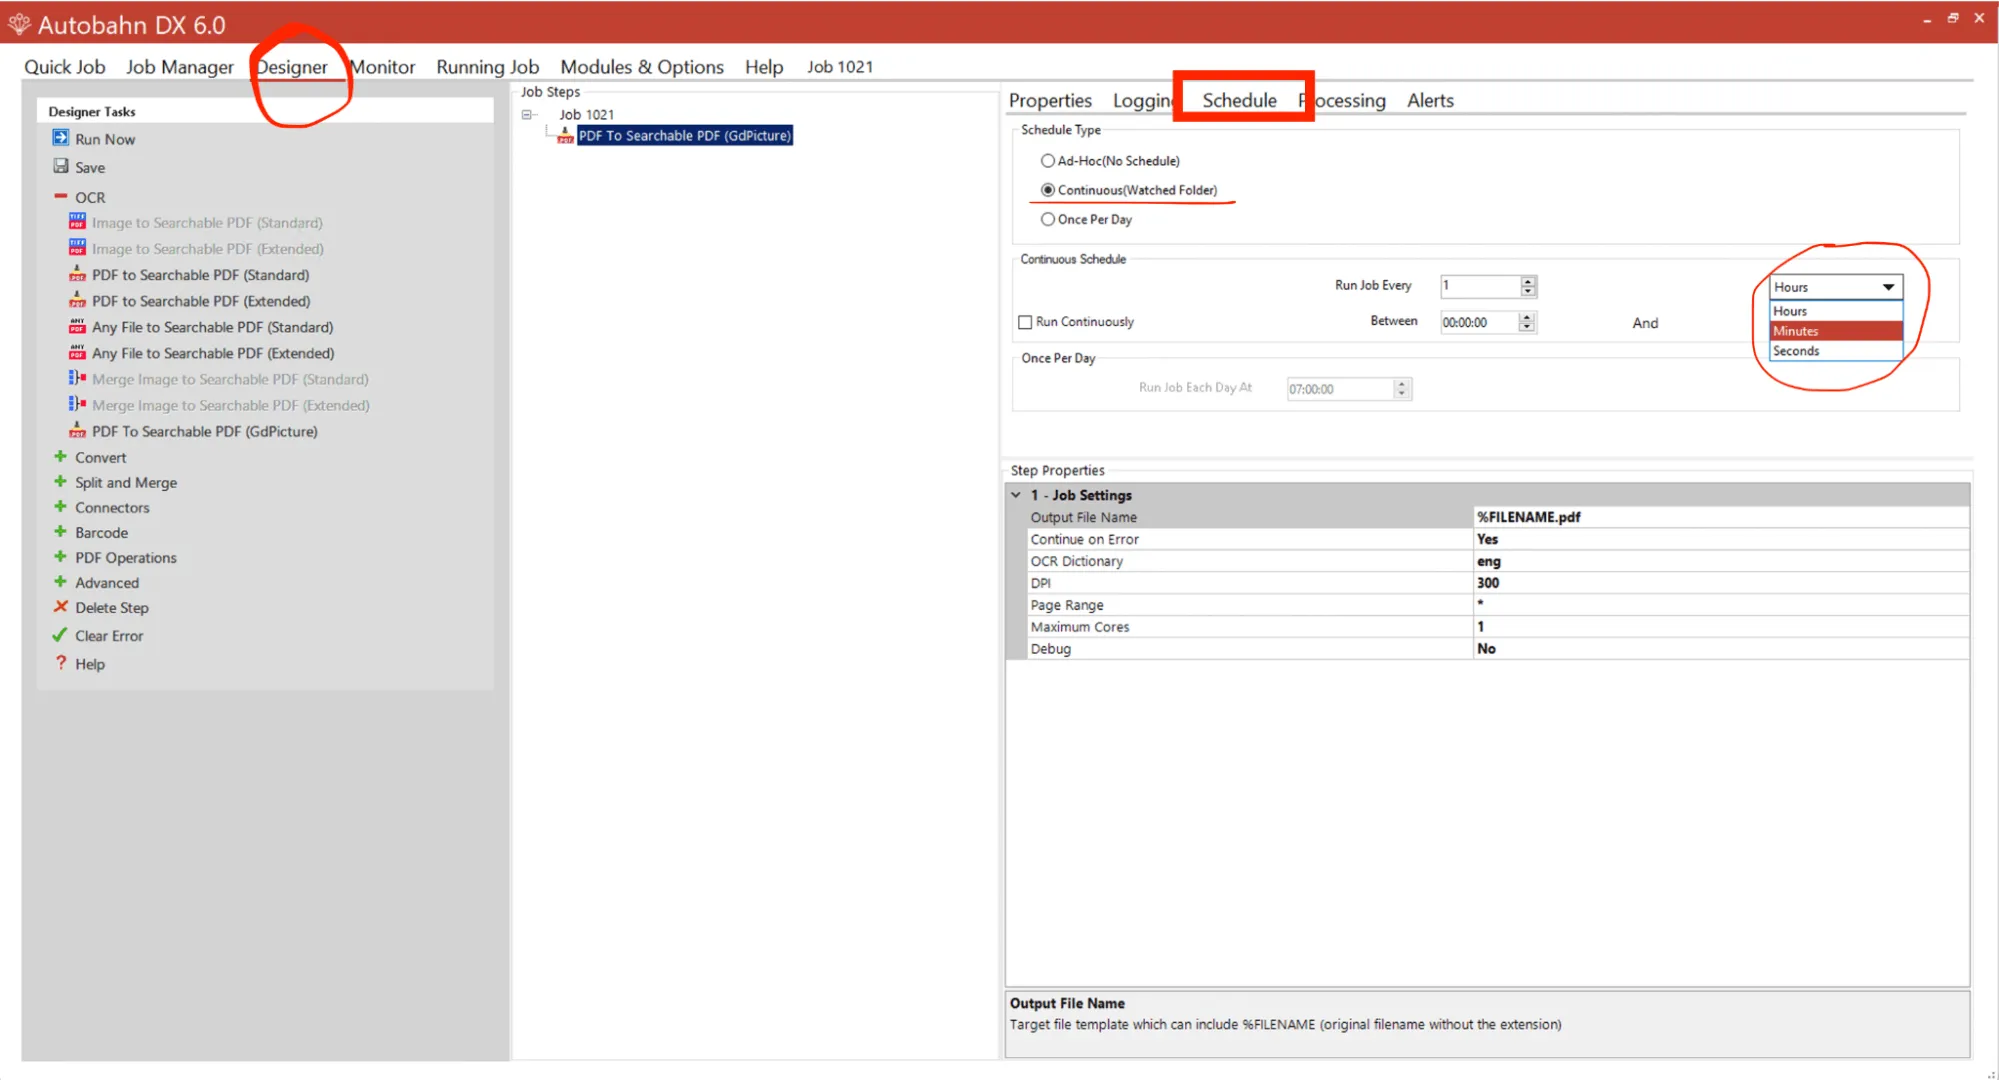
Select Designer , and then click the Schedule tab. You can choose the Once Per Day option and run jobs out of hours. Or, you can choose the Continuous (Watched Folder) option and set the job to run every minute. If you work with multiple jobs, you should stagger the times that they run.
6. Set the input files to move to an archive.
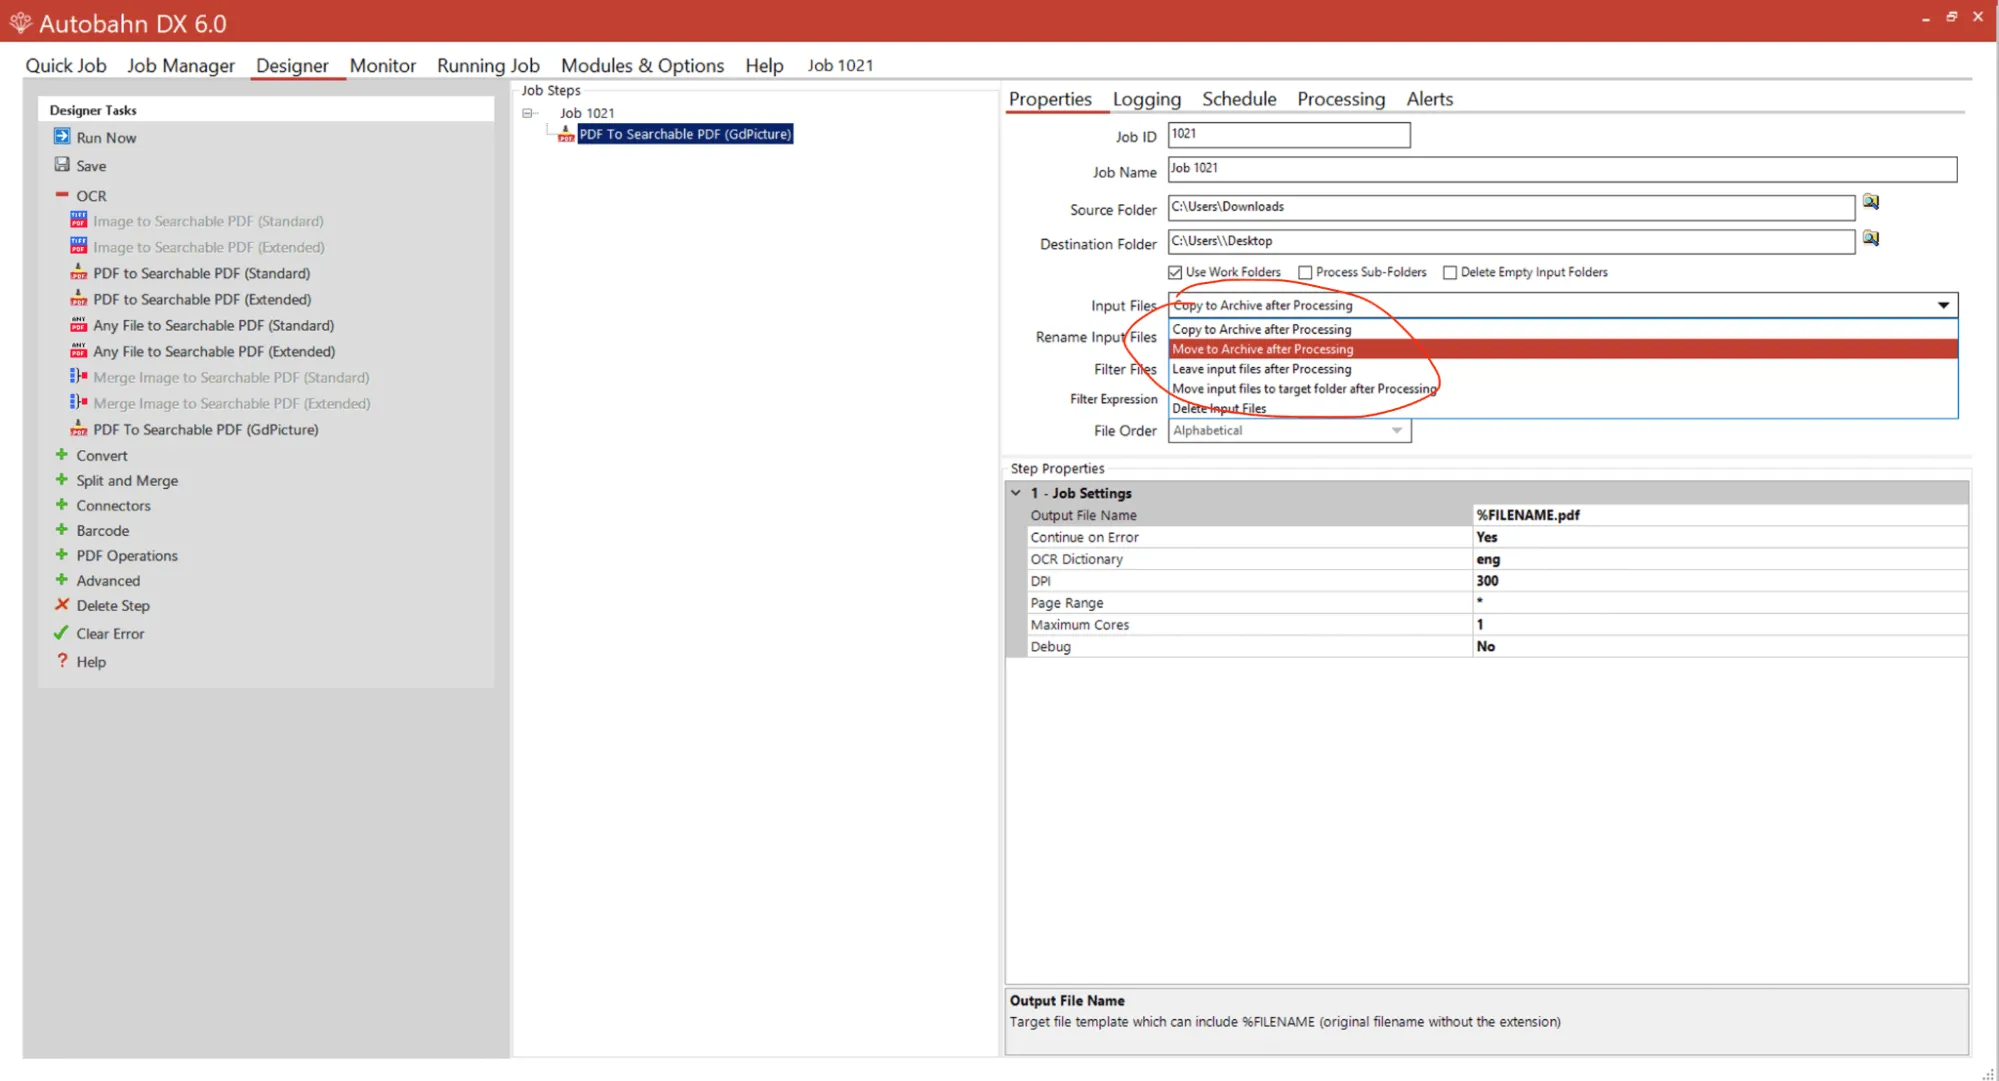
After processing, you’ll be prompted to enable the work folder, which is an intermediary folder between the source folder and the destination folder. If you leave the files in the same input folder with a continuous job, they’ll be continually reprocessed. Change the default settings in the Input Files field to Move to Archive after Processing.
7. Set a document count limit.
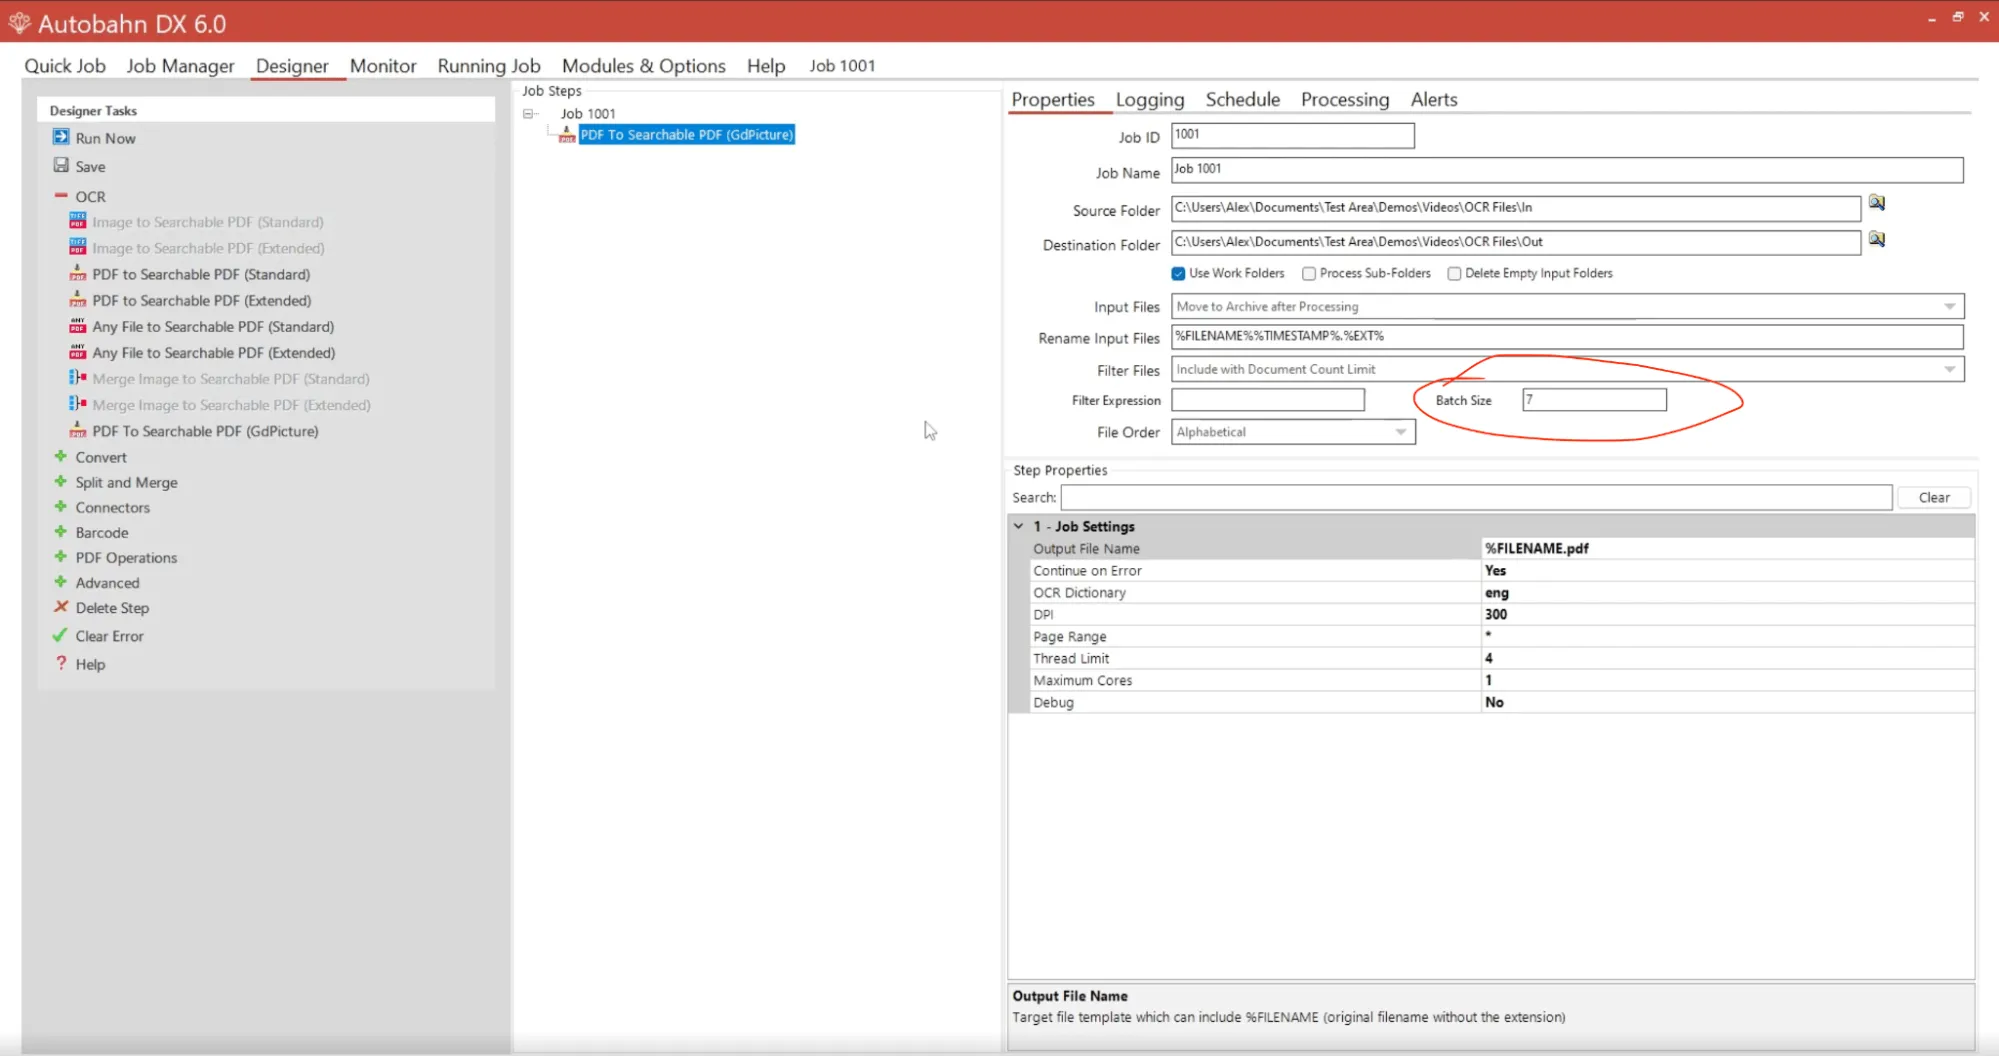
Finally, set a document count limit. The example above sets a batch size of seven. That means that for each run, every minute, seven files will be chosen out of the total number of files that are in the input folder, and they will be run through first.
This is useful for very large volumes where you have thousands of documents and you want some output files to be available earlier than when every file has been processed.
8. Save the job settings.
Click Save and go to the Job Manager tab. Because it’s continuous, it will have already started running through the files. Once the job is run, the status will change. If it tries to run when there are no files in the output folder, it will immediately go back on, stand by, and try and run the next minute to see if any files have been added to the target folder.
After the job is finished, go to the output folder and check the processed files. Now all these PDF files are OCRed and fully searchable.
If you want to try these steps yourself, download the free trial of Autobahn and make your documents searchable. Or, if you prefer to see these steps in action, check out our video tutorial below.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。