


Structs and classes are a fundamental part of C++ and are used to group related data together. This article will look at one aspect of them that’s often overlooked: memory padding. Understanding how data is laid out in memory can help you write more efficient code and optimize the performance of your programs.
Because padding and memory layout is the same between structs and classes, this post will use the term struct, but everything that applies to structs also applies to classes.
A struct is a user-defined data type that allows you to combine data into one group. It looks like this:
struct name {
std::string first_name;
std::string last_name;
};
The example above defines a struct called name that contains two members: first_name and last_name. The members of a struct can be of any data type, including other structs or classes. For example, you can use the struct like this:
// A method that prints out the members of the struct.
void print_name(const name& name) {
std::cout << "First name: " << name.first_name << std::endl;
std::cout << "Last name: " << name.last_name << std::endl;
}
int main(int argc, char **argv) {
// Create an instance of the struct and initialize its members.
name my_name{.first_name = "Patrik", .last_name = "Weiskircher"};
// Call a method with the struct as an argument.
print_name(my_name);
}
There are many ways to initialize and pass a struct around (this post uses C++20’s designated initializers(opens in a new tab)), but that’s not the focus of this article. You can find more information about structs in the C++ documentation(opens in a new tab).
Data is stored in memory. For example, a uint32_t will take up four bytes in memory. How this is stored is dependent on many rules(opens in a new tab). We won’t be going too much into detail here — this could be the topic of many blog posts. But one thing that’s important to know about is padding.
In structs, padding is the space that’s added between the members to allow efficient access to the data by the CPU. Here’s an example:
struct my_second_struct {
// bool == 1 byte
bool first_flag;
// bool == 1 byte
bool second_flag;
// uint32_t == 4 bytes
uint32_t first_value;
};
The struct above has two Booleans and one 32-bit integer. Together, they take up six bytes. But if padding and memory layout in structs were this easy, we wouldn’t need to read a blog post about it. Let’s see how big this struct really is:
#include <iostream>
#include <cstdint>
struct my_second_struct {
bool first_flag;
bool second_flag;
uint32_t first_value;
};
int main(int argc, char **argv) {
std::cout << sizeof(my_second_struct) << std::endl;
}
Put this in a file and compile it. On my Apple silicon Mac, it looks like this:
$ clang++ -o padding padding.cpp
$ ./padding
8
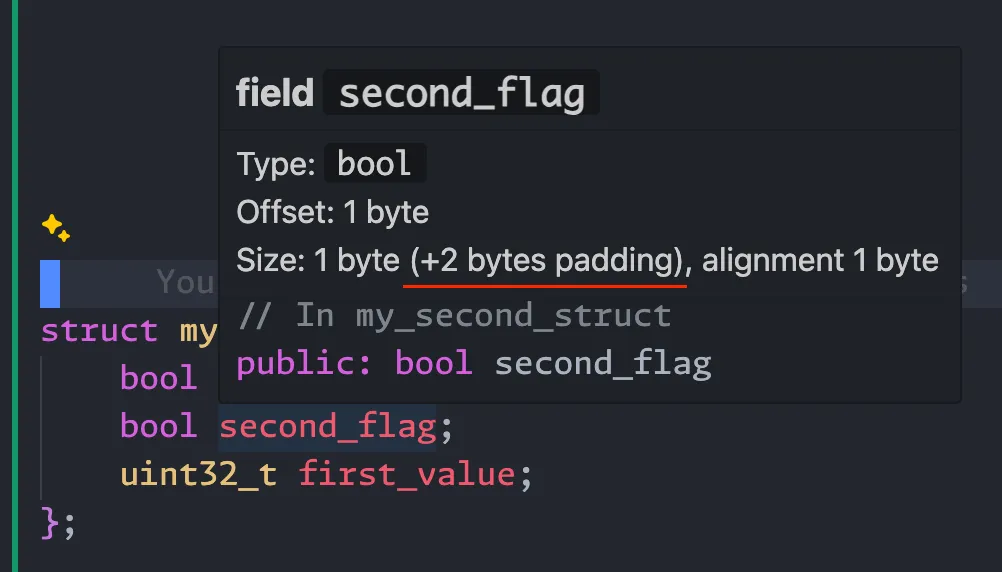
The result is eight bytes. Why’s that? The CPU likes to read data in chunks of certain sizes — for example, four bytes. To make access as efficient as possible, the compiler adds padding between the members. In this case, the compiler adds two bytes of padding after the two Boolean members to make sure that the 32-bit integer is properly aligned.
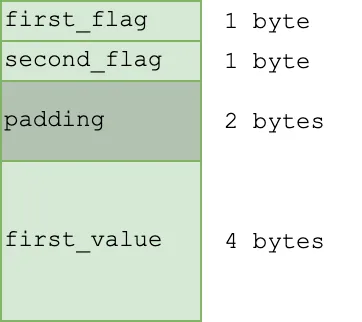
This can also be seen with the clangd plugin(opens in a new tab) in Visual Studio Code.
Padding is important to understand because it can affect the size of your data structures and how they’re laid out in memory. This can have an impact on the performance of your program, especially if you’re working with large data structures or need to optimize memory usage.
As an example, say you’re tasked with adding another Boolean to the struct above. Let’s call it bool very_very_important. You now have to decide where to add it. I personally like to add things at the bottom unless they’re related. That would result in this:
struct my_third_struct {
bool first_flag;
bool second_flag;
uint32_t first_value;
bool very_very_important;
};
How big is the struct now? Let’s look using Visual Studio Code again.
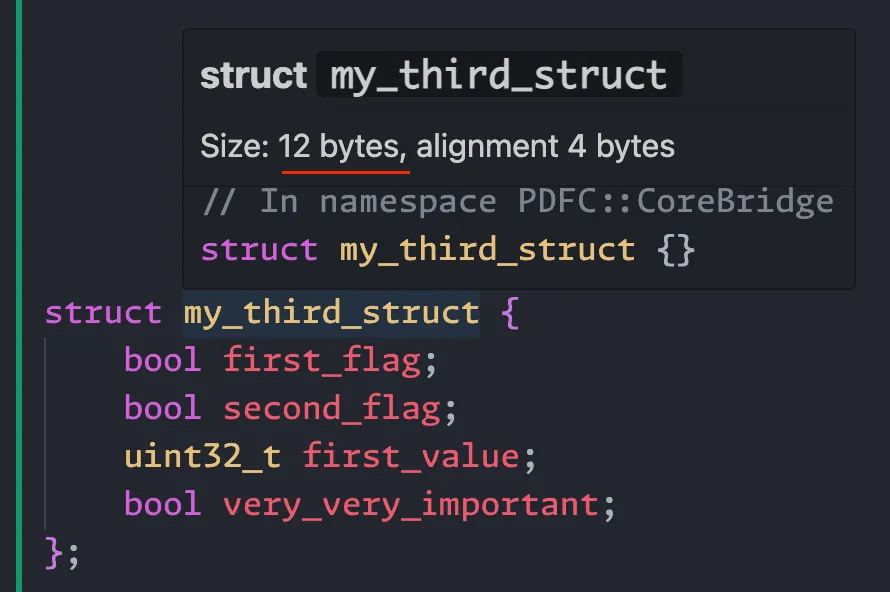
It’s now 12 bytes! The compiler added three bytes of padding after the very_very_important member to make sure the whole struct is properly aligned. Now imagine this struct is used in an array with 1 million elements. That’s 3 million bytes of wasted memory!
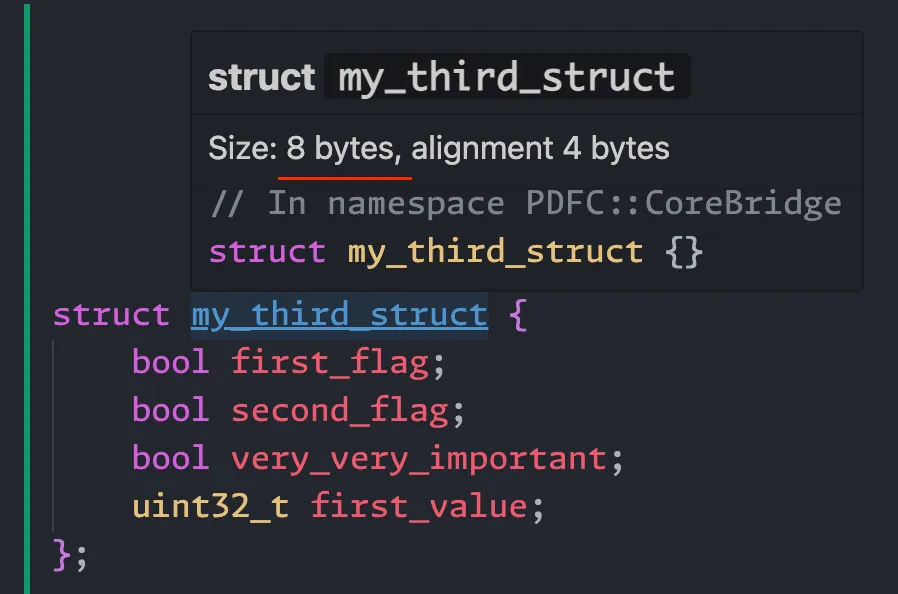
But there’s a better way:
struct my_third_struct {
bool first_flag;
bool second_flag;
bool very_very_important;
uint32_t first_value;
};
If you add the Boolean to the other Booleans — where there’s already padding — you get a new Boolean for free.
Understanding how data is laid out in memory can help you write more efficient code and optimize the performance of your programs. By being aware of padding and how it affects the size and layout of your data structures, you can make better decisions about how to organize your data and improve the performance of your programs.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。