


Our previous research on logit-gap steering demonstrated that the safety guardrails of an aligned LLM can be bypassed by closing a measurable gap in the model's output scores. That work answered the question of how an attacker bypasses alignment. A natural follow-up question is where inside the model the alignment lives in the first place — and how concentrated or how diffuse that defense actually is. The answer matters because it tells defenders whether safety is a thick perimeter or a thin layer of paint.
Modern LLMs are aligned through reinforcement learning from human feedback (RLHF), a training stage that pushes the model toward refusing harmful prompts and complying with safe ones. Until now, no method has been able to point to the specific pieces of the network that carry that learned behavior cheaply enough to run on every model an enterprise deploys. Our new academic research presents a method that does exactly that, and it produces a result that should change how the industry talks about LLM safety.
Our research introduces a method called perturbation probing. With only two forward passes per prompt and a significantly lower computational cost, it identifies the small set of feed-forward neurons inside an aligned LLM that are causally responsible for a targeted behavior, such as refusing harmful requests.
The headline finding is striking. On open-source LLM Qwen3-4B, just 50 neurons out of 350,208 — about 0.014% of the model's feed-forward neurons — control the safety refusal template. Removing those 50 neurons changes the response format on 80% of 520 standard harmful-prompt benchmarks. The result was replicated on 200 prompts of a second standard benchmark. On a smaller model, Qwen3.5-2B, just 20 neurons were enough to stop the LLM from falsely agreeing with users in multi-turn conversations, dropping that behavior from 36.7% to 0% across 30 questions.
This concentration matters because it demonstrates that an aligned LLM's refusal behavior does not live in a robust, distributed defense. It lives in a thin template layer — a tiny fraction of the network that an attacker who can manipulate internals could disable, and that even a normal optimization run could shift. Relying on this thin layer alone is the LLM analog of relying on a single perimeter firewall: structurally insufficient. True AI safety demands a defense-in-depth strategy, with external content filters and runtime guardrails layered on top of whatever the base model was trained to do.
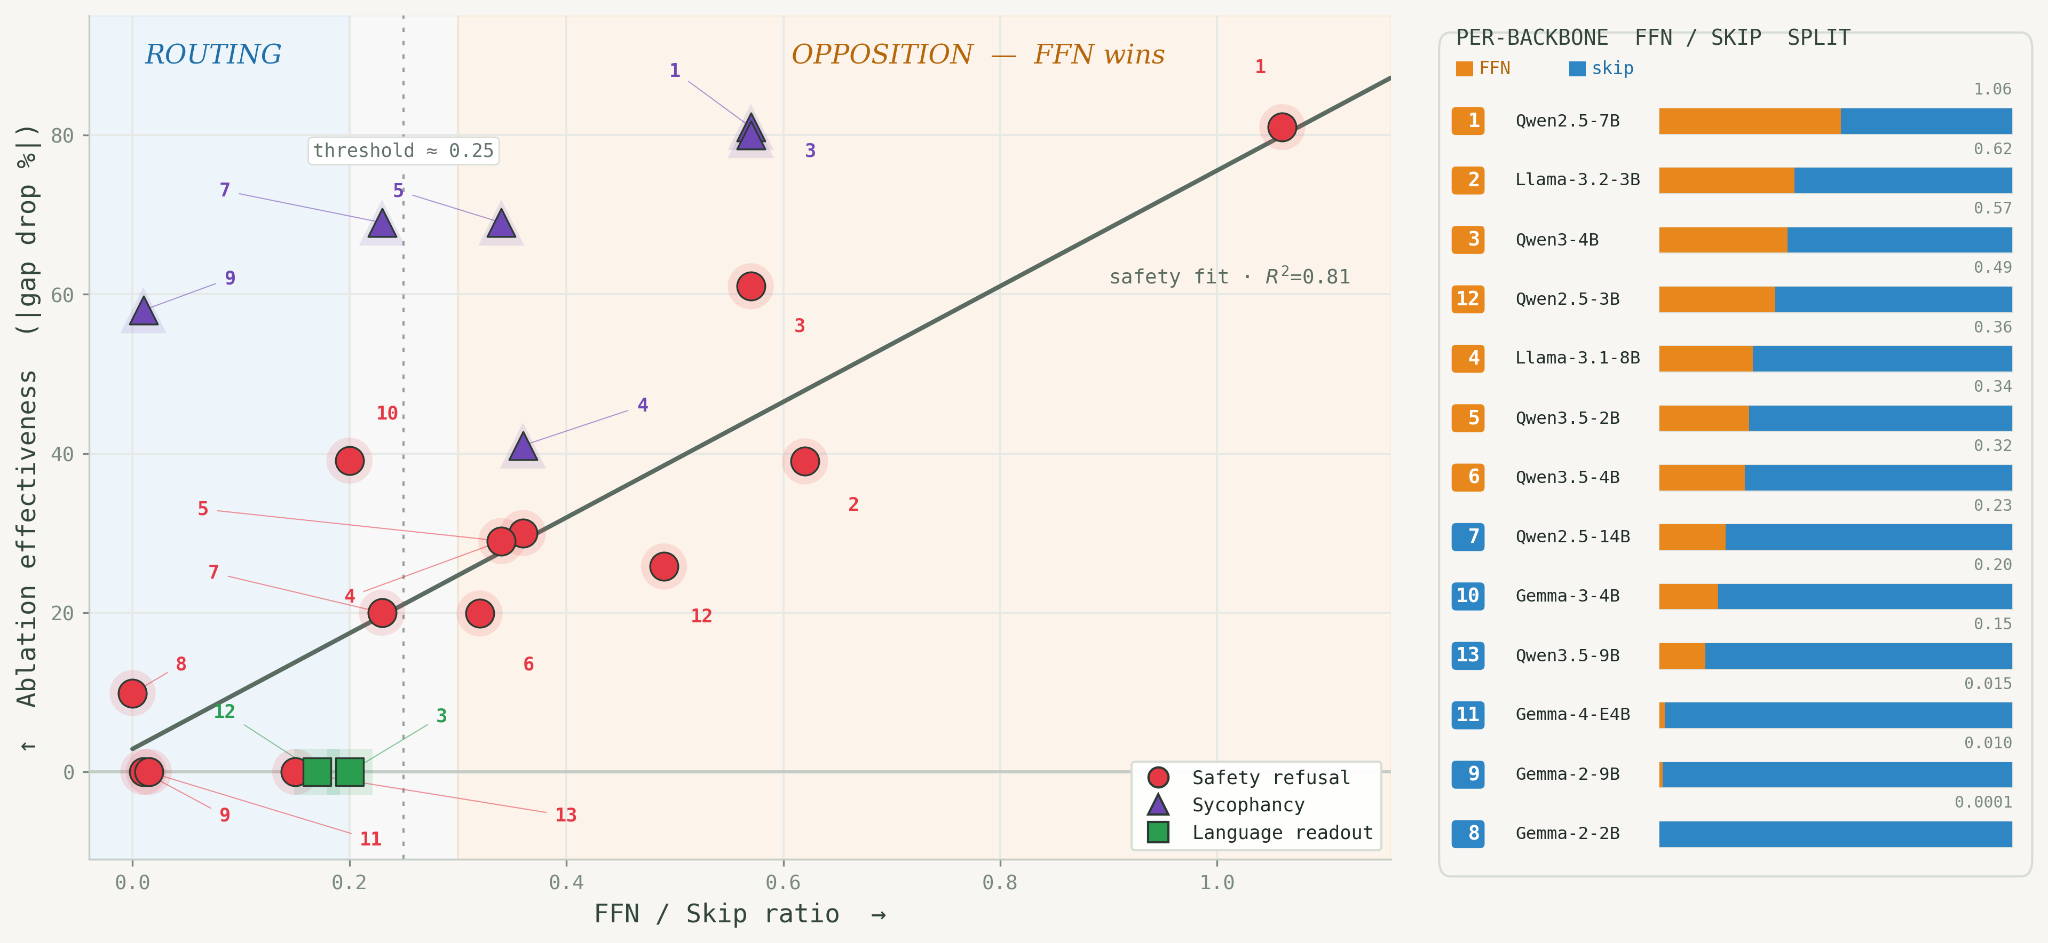
Beyond identifying the neurons, the same computation produces a diagnostic we call the FFN/Skip ratio: a single number, computable in seconds per model, that predicts whether a model's safety circuit can be easily steered with minimal modifications. Across the 13 models tested, this ratio explained 81% of the variance in how vulnerable each model's safety behavior was to a small targeted change. That makes it a candidate for a quantitative safety fragility score, a metric that allows security teams to compare models on alignment robustness without running adversarial red-team campaigns first.
Figure 1 displays these tests below. The horizontal axis measures how much a model routes decisions through a narrow internal pathway, and the vertical axis measures how much the model’s safety behavior changed when we disabled just 50 neurons. Models track the diagonal closely, which is why one number can predict the other.
We hope that perturbation probing will serve two roles for the AI security community. First, as a pre-deployment diagnostic. Security teams can measure how much of a model's safety rests on a thin, easily removed layer before they put that model in production. In our experiments, amplifying just 10 identified neurons on a small model improved factual self-correction from 52% to 88% on 200 TruthfulQA prompts without any retraining. The same toolkit that exposes fragility can also be used to repair it.
We are sharing this research to empower the broader AI and security community to build LLMs whose safety properties can be measured, audited and reinforced, not merely asserted. We urge researchers to read the full paper on arXiv, “Perturbation Probing: A Two-Pass-per-Prompt Diagnostic for FFN Behavioral Circuits in Aligned LLMs.” We also recommend integrating fragility diagnostics into your own evaluation pipelines.
For organizations deploying LLMs today, Prisma AIRS Runtime Security provides the external content filters and inline guardrails that a thin template layer alone cannot. Unit 42's AI Security Assessment helps identify where AI adoption introduces governance and exposure risk. Together, they deliver the defense-in-depth posture that this research shows is necessary.
We used publicly available open-weight models under their respective licenses for local mechanistic and safety evaluation. The study reports aggregate rates, model-internal measurements, and non-operational summaries only. We do not release harmful generations, executable attack artifacts, jailbreak prompts or instructions that facilitate misuse. For models governed by acceptable-use or prohibited-use policies, experiments are framed as defensive safety evaluation and robustness measurement.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。