


Our new versions of the Gemma 4 family are optimized with Quantization-Aware Training (QAT) to dramatically reduce memory requirements and maximize on-device performance.

Omar Sanseviero
Member of Technical Staff, Google DeepMind
Your browser does not support the audio element.
Listen to article
This content is generated by Google AI. Generative AI is experimental
[[duration]] minutes
Since releasing Gemma 4 two months ago, we've been continuously working to expand its capabilities. First, we introduced Multi-Token Prediction (MTP) to accelerate inference, and just a couple of days ago, we released a 12B model to bridge the gap between our E4B and 26B MOE models.
Today, we are releasing new checkpoints optimized with Quantization-Aware Training (QAT) to make Gemma 4 even more efficient, so you can run models locally on everyday edge devices and consumer GPUs.
By simulating quantization during training, QAT minimizes quality loss when the model is compressed. This release includes QAT checkpoints for the popular Q4_0 quantization format as well as a novel quantization format specialized for mobile use cases. Using this mobile format, we’ve reduced the memory footprint of Gemma 4 E2B to 1GB. Together, these dramatically reduce memory requirements while preserving the capabilities and quality you expect from Gemma 4.
Keeping model quality while making them smaller
Quantization is a key technology to run models on consumer hardware by reducing their memory footprint while also accelerating decode speed. However, standard Post-Training Quantization (PTQ) often leads to performance degradation. Instead of simply quantizing the model after training, QAT integrates the quantization process directly into training. While PTQ is already effective at preserving quality, our QAT results yield even higher overall quality compared to standard PTQ baselines.
We applied this QAT recipe to the popular Q4_0 format to maximize performance for all the models. For the edge models (E2B and E4B), we rethought how we approach quantization with a special mobile-specialized quantization schema.
Saving on VRAM and Storage
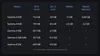
Below are the approximate memory requirements indicating how much VRAM is required to load the models:
Optimizing for mobile devices under the hood
Standard compression formats are often hard for mobile processors to run efficiently. To ensure Gemma 4 performs smoothly on mobile, we engineered a custom mobile-quantization schema designed for edge hardware:
- Static activations: Normally, models waste processing power calculating how to scale data on the fly. We pre-calculate these settings during training, which reduces workload on mobile chips and makes responses faster.
- Channel-wise quantization: We structured the compressed data to fit the design of mobile accelerators. This allows the phone to run calculations natively without needing slow workarounds.
- Targeted 2-bit quantization: We heavily compressed (to 2-bit) the specific parts of the model that generate tokens, while keeping the core reasoning layers at higher precision. This saves storage without making the model less smart.
- Embedding and KV cache optimization: We focused compression on the model’s vocabulary list and its short-term memory. This drastically reduces the active memory footprint, letting you have long chats without running out of space.
Because our audio and vision encoders are not needed in many use cases, you can optimize your memory footprint even further by deploying only the modalities you need. For example, the Gemma 4 E2B text-only model (without Per-Layer Embeddings) requires less than 1 GB of memory.
Get started today
To make those models easily usable with your preferred workflow, we’ve partnered with popular developer tools across the ecosystem to seamlessly support the Gemma 4 QAT checkpoints starting today:
- Download the weights: Access the Q4_0 and mobile model weights right now on Hugging Face. We've tailored the formats to fit your workflow: GGUF formats are ready for use with llama.cpp, and compressed tensors are provided for vLLM. For everything else, we share unquantized checkpoints that can be converted and quantized into formats supporting Q4_0.
- Integrate & learn: Explore our documentation to learn how to best deploy the QAT checkpoints.
- Try on your desktop: Easily download, manage, and run Gemma 4 QAT models locally on your desktop using user-friendly interfaces like llama.cpp, Ollama and LM Studio.
- Deploy on-device: Use Google's lightweight LiteRT-LM runtime for optimized edge deployment or run the models directly on the web with Transformers.js
- Use your favorite development tools: Serve larger models efficiently with SGLang and vLLM, optimize for Apple Silicon with MLX. Use the MTP QAT checkpoints to preserve the speedup of MTP while quantizing the models. Fine-tune weights directly using Hugging Face Transformers and Unsloth.
We can't wait to see what you build with Gemma 4 running locally!