


The culmination of a decade of development, TPU 8t and TPU 8i are custom-engineered to power the next generation of supercomputing with efficiency and scale.
General summary
Google is launching its eighth-generation Tensor Processor Units, featuring two specialized chips: the TPU 8t for massive model training and the TPU 8i for high-speed inference. These chips are purpose-built to handle the complex, iterative demands of AI agents while delivering significant gains in power efficiency and performance. You can request more information now to prepare for their general availability later this year.
Summaries were generated by Google AI. Generative AI is experimental.
Bullet points
- Google’s new eighth generation TPUs, TPU 8t and 8i, power the next era of AI.
- The TPU 8t is a training powerhouse built to speed up complex model development.
- The TPU 8i specializes in low-latency inference to support fast, collaborative AI agents.
- Both chips use custom hardware to deliver better performance and energy efficiency than before.
- These new systems will be available later this year to help scale your AI workloads.
Summaries were generated by Google AI. Generative AI is experimental.
Basic explainer
Google just announced its eighth generation of custom AI chips, the TPU 8t and TPU 8i. These chips are built to handle the heavy lifting required for training massive AI models and running complex AI agents. By specializing each chip for either training or performance, Google makes AI faster and more energy-efficient. This new hardware helps developers build smarter tools that can reason and solve problems more effectively.
Summaries were generated by Google AI. Generative AI is experimental.
Explore other styles:

Your browser does not support the audio element.
Listen to article
This content is generated by Google AI. Generative AI is experimental
[[duration]] minutes
Today at Google Cloud Next, we are introducing the eighth generation of Google's custom Tensor Processor Unit (TPU), coming soon with two distinct, purpose-built architectures for training and inference: TPU 8t and TPU 8i. These two chips are designed to power our custom-built supercomputers, to drive everything from cutting-edge model training and agent development, to massive inference workloads. TPUs have been powering leading foundation models, including Gemini, for years. These 8th generation TPUs together will deliver scale, efficiency and capabilities across training, serving and agentic workloads.
In this age of AI agents, models must reason through problems, execute multi-step workflows and learn from their own actions in continuous loops. This places a new set of demands on infrastructure, and TPU 8t and TPU 8i were designed in partnership with Google DeepMind to take on the most demanding AI workloads and adapt to evolving model architectures at scale.
TPUs set the standard for a number of ML supercomputing components including custom numerics, liquid cooling, custom interconnects and more, and our eighth generation TPUs are the culmination of more than a decade of development. The key insight behind the original TPU design continues to hold today: by customizing and co-designing silicon with hardware, networking and software, including model architecture and application requirements, we can deliver dramatically more power efficiency and absolute performance.
We are thrilled to see how a decade of innovation translates into real-world breakthroughs. Today, pioneering organizations like Citadel Securities are pushing the boundaries of what's possible, choosing TPUs to power their cutting-edge AI workloads:
Two chips to meet the moment
Hardware development cycles are much longer than software. With each generation of TPUs, we need to consider what technologies and demands will exist by the time they are brought to market. Several years ago, we anticipated rising demand for inference from customers as frontier AI models are deployed in production and at scale. And with the rise of AI agents, we determined the community would benefit from chips individually specialized to the needs of training and serving.
TPU 8t shines at massive, compute-intensive training workloads designed with larger compute throughput and more scale-up bandwidth. TPU 8i is designed with more memory bandwidth to serve the most latency-sensitive inference workloads, which is critical because interactions between agents at scale magnify even small inefficiencies.
Importantly, both chips can run various workloads, but specialization unlocks significant efficiencies and gains.
TPU 8t: The training powerhouse
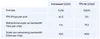
TPU 8t is built to reduce the frontier model development cycle from months to weeks. By balancing the highest possible compute throughput, shared memory and interchip bandwidth with the best possible power efficiency and productive compute time, we have crafted a system that delivers nearly 3x the compute performance per pod over the previous generation, enabling faster innovation to ensure our customers continue to set the pace for the industry.
- Massive scale: A single TPU 8t superpod now scales to 9,600 chips and two petabytes of shared high bandwidth memory, with double the interchip bandwidth of the previous generation. This architecture delivers 121 ExaFlops of compute and allows the most complex models to leverage a single, massive pool of memory.
- Maximum utilization: By also integrating 10x faster storage access, combined with TPUDirect to pull data directly into the TPU, TPU 8t helps ensure maximum utilization of the end-to-end system.
- Near-linear scaling: Our new Virgo Network, combined with JAX and our Pathways software, means TPU 8t can provide near-linear scaling for up to a million chips in a single logical cluster.
In addition to raw performance, TPU 8t is engineered to target over 97% “goodput” — a measure of useful, productive compute time — through a comprehensive set of Reliability, Availability and Serviceability (RAS) capabilities. These include real-time telemetry across tens of thousands of chips, automatic detection and rerouting around faulty ICI links without interrupting a job, and Optical Circuit Switching (OCS) that reconfigures hardware around failures with no human intervention.
Every hardware failure, network stall or checkpoint restart is time the cluster is not training, and at frontier training scale, every percentage point can translate into days of active training time.
TPU 8i: The reasoning engine
In the agentic era, users expect to be able to ask questions, delegate tasks and get outcomes. TPU 8i is designed to handle the intricate, collaborative, iterative work of many specialized agents, often “swarming” together in complex flows to deliver solutions and insights for the most challenging tasks. We redesigned the stack to eliminate the “waiting room” effect through four key innovations:
- Breaking the “memory wall”: To stop processors from sitting idle, TPU 8i pairs 288 GB of high-bandwidth memory with 384 MB of on-chip SRAM — 3x more than the previous generation — keeping a model's active working set entirely on-chip.
- Axion-powered efficiency: We doubled the physical CPU hosts per server, moving to our custom Axion Arm-based CPUs. By using a non-uniform memory architecture (NUMA) for isolation, we have optimized the full system for superior performance.
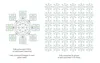
- Scaling MoE models: For modern Mixture of Expert (MoE) models, we doubled the Interconnect (ICI) bandwidth to 19.2 Tb/s. Our new Boardfly architecture reduces the maximum network diameter by more than 50%, ensuring the system works as one cohesive, low-latency unit.
- Eliminating lag: Our new on-chip Collectives Acceleration Engine (CAE) offloads global operations, reducing on-chip latency by up to 5x, minimizing lag.
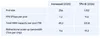
These innovations deliver 80% better performance-per-dollar compared to the previous generation, enabling businesses to serve nearly twice the customer volume at the same cost.
TPU 8i hierarchical Boardfly topology building up from a building block of four fully connected chips into a fully connected group of eight boards, with 36 of such groups fully connected into a TPU 8i pod
Co-designed for Gemini, open for everyone
This eighth generation TPU is also the latest expression of our co-design philosophy, where every spec is built to solve AI’s biggest hurdles.
- Boardfly topology was designed specifically for the communication demands of today's most capable reasoning models.
- SRAM capacity in TPU 8i was sized for the KV cache footprint of reasoning models at production scale.
- Virgo Network fabric's bandwidth targets were derived from the parallelism requirements of trillion-parameter training.
And for the first time, both chips run on Google’s own Axion ARM-based CPU host, allowing us to optimize the full system, not just the chip, for performance and efficiency.
Both platforms support native JAX, MaxText, PyTorch, SGLang and vLLM — the frameworks developers already use — and offer bare metal access, giving customers direct hardware access without the overhead of virtualization. Open-source contributions including MaxText reference implementations and Tunix for reinforcement learning support turn key paths between capability and production deployment.
Designing for power efficiency at scale
In today’s data centers, power, not just chip supply, is a binding constraint. To solve this, we have optimized efficiency across the entire stack, with integrated power management that dynamically adjusts the power draw based on real-time demand. TPU 8t and TPU 8i deliver up to two times better performance-per-watt over the previous generation, Ironwood.
But efficiency at Google is not just a chip-level metric; it’s also a system-level commitment that runs from silicon to the data center. For example, we integrate network connectivity with compute on the same chip, significantly reducing the power costs of moving data across the TPU pod. Even our data centers are co-designed with our TPUs. We innovated across hardware and software to enable our data centers to deliver six times more computing power per unit of electricity than they did just five years ago.
TPU 8t and TPU 8i continue that trajectory. Both are supported by our fourth-generation liquid cooling technology that sustains performance densities air cooling cannot. By owning the full stack, from Axion host to accelerator, we can optimize system-level energy efficiency in ways that simply cannot be achieved when the host and chip are designed independently.
Google Cloud’s fourth generation cooling distribution unit

Infrastructure for the agentic era
Every major computing transition has required infrastructure breakthroughs, and the agentic era is no different. Infrastructure must evolve to meet the demands of autonomous agents operating in continuous loops of reasoning, planning, execution and learning.
TPU 8t and TPU 8i are our answer to this challenge: two specialized architectures built to redefine what is possible in AI, from building the most capable AI models, to swarms of agents perfectly orchestrated, to managing the most complex reasoning tasks. Both chips will be generally available later this year, and can be used as part of Google’s AI Hypercomputer, which brings together purpose-built hardware (compute, storage, networking), open software (frameworks, inference engines), and flexible consumption (orchestration, cluster management and delivery models) into a unified stack.
Agentic computing will redefine what is possible. We are thrilled to announce the latest incarnation of our relentless innovation to power this transformation, TPU 8i and 8t. Interested customers can request more information.
Done. Just one step more.
Check your inbox to confirm your subscription.
You are already subscribed to our newsletter.
You can also subscribe with a