







Metehan Yesilyurt, an international SEO consultant, had been working with Common Crawl datasets for seven months when he started asking a question that many in the industry have asked before but have been avoiding: "What about the training data?"
As Metehan put it in his recent research:
"Are there reasons why certain domains get recommended so frequently? How can we even find the answer to this?"
The answer, it turns out, was in our monthly Web Graph releases.
Every month, Common Crawl publishes Web Graph Data alongside the main crawl archives. The Web Graph releases can be browsed on our new Web Graph Index page, with links to each release and statistics for each. Even more statistics can be found on our cc-webgraph-statistics page.
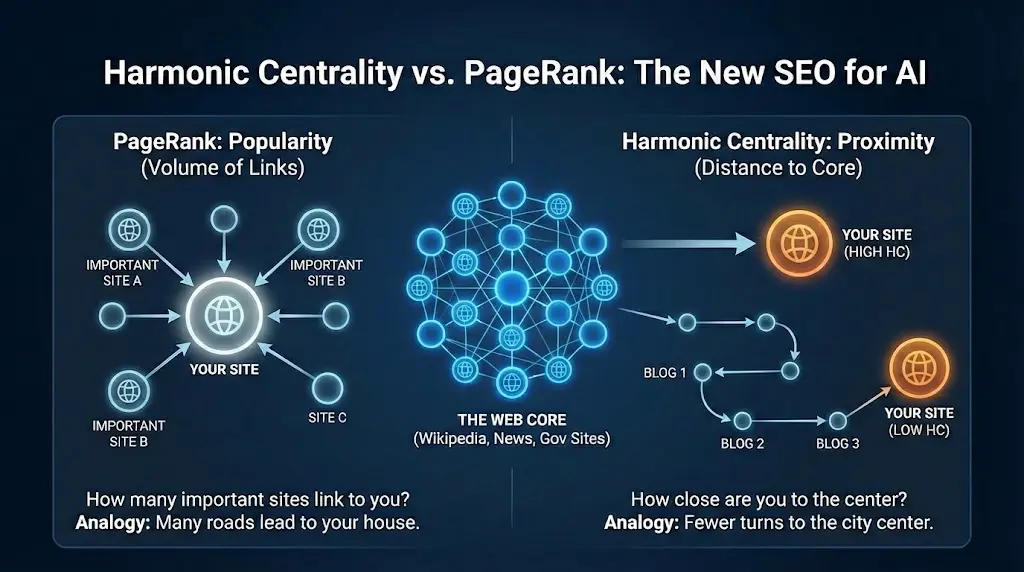
The Web Graph dataset includes two key authority metrics computed across billions of links:
Harmonic Centrality (HC): Measures how "close" a domain is to all other domains in the Web Graph. A domain with strong HC can reach many other domains through fewer link hops. It identifies central hubs in the web's link structure.
PageRank: Measures a domain's authority based on the quality and quantity of links pointing to it. Domains linked by other high-authority sites receive higher scores.
These metrics have been available in our public releases for years, and Common Crawl’s crawler (CCBot) has been using these metrics to guide its crawling choices.
What's new is how the SEO community is now applying them to understand AI visibility.
Metehan built a free tool at webgraph.metehan.ai that makes our Web Graph data accessible to SEOs. The tool indexes approximately 18 million domains across five time periods from 2023 to 2025, allowing practitioners to:
The full Common Crawl Web Graph currently contains around 607 million domain records across all datasets, with each monthly release covering 94 to 163 million domains. Metehan's tool indexes the top 10 million per time period for practical lookup speeds.
You can also verify whether your site is being crawled by Common Crawl directly. The Common Crawl Index Server at index.commoncrawl.org lets you search any URL pattern against their crawl archives. Simply select a crawl period (archives go back years, with the most recent being CC-MAIN-2025-51), enter your domain, and see exactly which pages have been captured. This is a quick way to confirm your content is making it into the dataset that feeds AI training pipelines.
The Mozilla Foundation's 2024 report “Training Data for the Price of a Sandwich” confirmed what many suspected: 64% of the 47 LLMs analyzed used at least one filtered version of Common Crawl data. For GPT-3, over 80% of training tokens came from filtered Common Crawl data.
Here's the connection that SEOs are making: Common Crawl uses Harmonic Centrality to determine crawl priority. Sites with higher HC scores are crawled more frequently. More frequent crawling means more appearances in monthly archives. More appearances in archives means greater representation in AI training data.
As Metehan's research notes:
"If Common Crawl prioritizes crawling high-HC domains, these domains appear more frequently in training data. Does this create a baseline familiarity in LLMs with certain sources?"
The domains that rank highest in our Web Graph (Facebook, Google, YouTube, Wikipedia) are also among the most frequently cited by LLMs. The question is whether this correlation stems from:
Brie Moreau of White Light Digital Marketing has been running citation analysis studies with DataForSEO, processing over 2 million citations. His preliminary findings reveal several notable patterns:
The research shows a clear relationship between traditional Google rankings and LLM citation probability. Sites ranking in position 1 on Google have roughly a 46-48% probability of being cited by AI, dropping to around 37% at position 2. The probability continues to decline as traditional rank decreases, falling to approximately 19-20% by position 10.
Perhaps more interesting is what the data reveals about content types. Across 177 million sources analyzed, comparative listicles dominate AI citations at 32.5% of all citations. This suggests LLMs have a strong preference for content that compares options or presents information in list format. Blogs and opinion pieces account for another 9.91%, while commercial/store pages represent just 4.73%.
The study also examined co-citation patterns, analyzing 3,000 citations and identifying over 120 co-citation relationships. This co-citation analysis is significant because ChatGPT's web mode uses Reciprocal Rank Fusion (RRF) to blend results from multiple sub-queries. Sites that appear together across multiple search result lists have higher chances of making it into the final citation pool.
Moreau's correlation matrix examining factors like content word count, readability indices, page speed metrics, and social signals is still being refined, with full results expected to be published soon.
SEOs are using our Web Graph data in several ways:
Benchmarking: Comparing their domain's CC authority against competitors to identify gaps that content alone may not solve.
Trend Analysis: Tracking HC and PageRank changes over time to understand how link building efforts affect their position in the crawl priority queue.
Link Strategy: Evaluating potential link sources not just for traditional SEO value, but for their position in the web's interconnected core.
As I wrote in our "From SEO to AIO" post: traditional link building focused on accumulating backlinks. For AI visibility, the topology of your backlink profile may matter as much as the volume. A single link from a site deeply embedded in the web's core could do more for your Harmonic Centrality than dozens of links from isolated sites.
What we're seeing is the SEO community adapting to a fundamental shift in how discovery works. The old model was "index and rank." The new model is "train and retrieve."
In this new paradigm, being in the crawl becomes a prerequisite for being in the model. Our Web Graph Data provides one lens into crawl prioritization that practitioners can actually measure and track.
We're encouraged to see researchers like Metehan building tools that make our data more accessible. The questions being asked about training data composition, authority signals, and AI visibility deserve further investigation.
As the connection between training data presence and AI visibility becomes clearer, I expect Harmonic Centrality will move from a niche metric to a standard feature in the SEO toolkit. It wouldn't surprise me to see platforms like SEMrush, Ahrefs, Profound, and LLMrefs integrate Harmonic Centrality data into their products in the near future. When optimizing for AI becomes as routine as optimizing for Google, understanding your position in the web's link topology will be table stakes.
Stephen Burns is the Web Intelligence Lead at Common Crawl Foundation, the nonprofit that provides open web data to AI researchers and companies worldwide. He also works in enterprise SEO/GEO at Intuit. When he's not obsessing over link graphs, he can be found motorcycling to some remote area or at an SEO conference somewhere.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。