



惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

Martin Fowler
Martin Fowler
Jina AI
Jina AI
J
Java Code Geeks
Microsoft Security Blog
Recent Announcements
I
InfoQ
L
LangChain Blog
The Cloudflare Blog
IT之家
IT之家
博客园 - 叶小钗
Apple Machine Learning Research
B
Blog
A
About on SuperTechFans
Cyber Security Advisories - MS-ISAC
Last Week in AI
Last Week in AI
Blog — PlanetScale
Blog — PlanetScale
罗磊的独立博客
云风的 BLOG
云风的 BLOG
Microsoft Azure Blog
Engineering at Meta
Engineering at Meta
F
Fortinet All Blogs
博客园 - 聂微东
美团技术团队
博客园_首页

Common Crawl

Common Crawl - Blog - Introducing the AI Visibility Audit Common Crawl - Blog - Host- and Domain-Level Web Graphs March, April, and May 2026 Common Crawl - Blog - May 2026 Crawl Archive Now Available Common Crawl - Blog - April 2026 Crawl Archive Now Available in a Hugging Face Storage Bucket Common Crawl - Blog - You can now build directly on Common Crawl from the browser Common Crawl - Blog - Host- and Domain-Level Web Graphs February, March, and April 2026 Common Crawl - Blog - April 2026 Crawl Archive Now Available Common Crawl - Blog - April 2026 Common Crawl Newsletter Common Crawl - Blog - Announcing a Change to Common Crawl Dataset Size Reporting Common Crawl - Blog - Host- and Domain-Level Web Graphs January, February, and March 2026 Common Crawl - Blog - March 2026 Crawl Archive Now Available Common Crawl - Blog - IPv6 Adoption Across the Top 100K Web Hosts Common Crawl - Blog - Web Graph Statistics Gets a Proper Upgrade Common Crawl - Blog - Measuring Web Accessibility from Crawl Archives Common Crawl - Blog - Announcing the Whirlwind Tour of Common Crawl's Datasets Using Java Common Crawl - Blog - Host- and Domain-Level Web Graphs December 2025 and January/February 2026 Common Crawl - Blog - Introducing the New Examples & Resources Browser Common Crawl - Blog - February 2026 Crawl Archive Now Available Common Crawl - Blog - AI Plumbers at FOSDEM’26 Common Crawl - Blog - CC-Citations: A Visualization of Research Papers Referencing Common Crawl Common Crawl - Blog - CommonLID: Re-evaluating State-of-the-Art Language Identification Performance on Web Data Common Crawl - Blog - Host- and Domain-Level Web Graphs November/December 2025 and January 2026 Common Crawl - Blog - January 2026 Crawl Archive Now Available Common Crawl - Blog - Web Archives for Social Sciences Datathon, Bristol Common Crawl - Blog - How SEOs Are Using Common Crawl's Web Graph Data for AI Ranking Signals Common Crawl - Blog - GneissWeb Annotations Examples Common Crawl - Blog - Common Crawl at the Mozilla Festival 2025 Common Crawl - Blog - Host- and Domain-Level Web Graphs October, November, December 2025 Common Crawl - Blog - December 2025 Crawl Archive Now Available Common Crawl - Blog - A Sampling of 2025 Research Referencing Common Crawl
Common Crawl - Blog - October/November 2025 Newsletter
2025-11-03 · via Common Crawl

Table of Contents

Event Highlights

Web Languages

GneissWeb Annotations

SEO to AIO

Common Crawl Opt-out Registry

IETF 124 Montréal

Event Highlights

Common Crawl recently presented a seminar at the Stanford Institute for Human-Centered Artificial Intelligence (HAI) entitled “Preserving Humanity's Knowledge and Making it Accessible: Addressing Challenges of Public Web Data”. For highlights and slides, see our blog post.

The WMDQS team at COLM: Sebastian Nagel, Pedro Ortiz Suarez, Laurie Burchell, Thom Vaughan, and Malte Ostendorff

The Common Crawl team attended the 2nd Conference on Language Modeling in Montréal, organizing the first Workshop on Multilingual Data Quality Signals (WMDQS) workshop, giving invited talks, and strengthening links with the research community.  For more details and papers featuring Common Crawl, see our blog post.
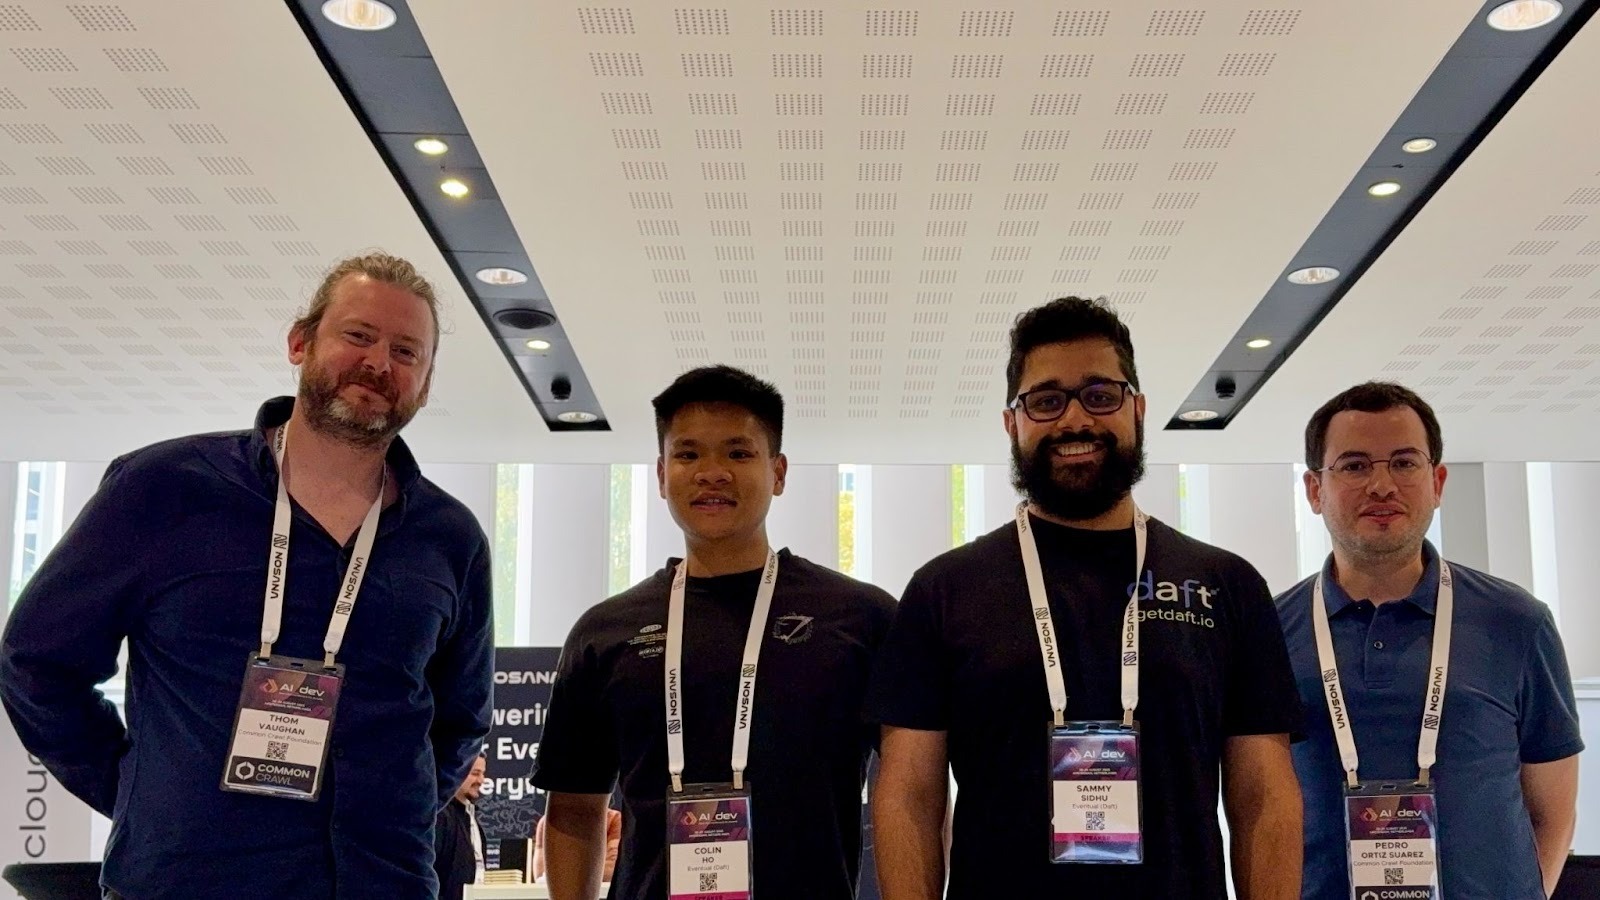
Left-to-right: Thom Vaughan, Colin Ho, Sammy Sidhu, and Pedro Ortiz Suarez, at AI_dev in Amsterdam.

In late August our team attended the Linux Foundation’s AI_dev event in Amsterdam. We caught up with many familiar faces and made friends with plenty of new ones and heard from people working in the AI world who use our data regularly.  For more on this event, see our trip report.

Web Languages

Web Languages, our public GitHub repository containing Markdown files for languages, asks native/proficient speakers to add URLs in the categories: news, culture and history, government, political parties, other, and informative links in English.  Web Languages now has 5.535 URLs in 193 languages, thanks to community contributions.  We are currently looking for native speakers to review contributions for 42 languages, as well as contributions for other languages.

GneissWeb Annotations

Common Crawl has added IBM’s GneissWeb quality and category annotations to its web dataset, enabling users to filter high-quality content and explore topics like medicine, education, and technology.  For more details, see our blog post.
SEO to AIO

We have published a new post titled From SEO to AIO: Why Your Content Needs to Exist in AI Training Data, which is a follow-up to our post earlier this year on AI Optimization.

Common Crawl Opt-out Registry

Publishers have been sending Common Crawl legal opt-out requests. In the interest of transparency and to better serve our ecosystem, we are publishing the full opt-out list for every legal request we have received.  For more details, please see our announcement post.

IETF 124 Montréal

This week Common Crawl will be represented at IETF 124 in Montréal, covering the AI Preferences and Web Bot Auth working groups, and presenting at the Measurement and Analysis for Protocols research group. We are excited to contribute to these conversations that shape the open standards which govern the web, and the future of access to online content. Our mission to provide open web data at large scale is aligned with the IETF’s goals of transparency, interoperability, and public benefit.

If you’re attending IETF 124 and would like to chat about web-scale data, open measurement, or responsible crawling, please get in touch, we’d love to meet.