


惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

腾讯CDC
IT之家
IT之家
有赞技术团队
有赞技术团队
WordPress大学
WordPress大学
Apple Machine Learning Research
OSCHINA 社区最新新闻
OSCHINA 社区最新新闻
人人都是产品经理
人人都是产品经理
The Cloudflare Blog
钛媒体:引领未来商业与生活新知
钛媒体:引领未来商业与生活新知
freeCodeCamp Programming Tutorials: Python, JavaScript, Git & More
博客园 - 【当耐特】
V
V2EX
Last Week in AI
Last Week in AI
H
Help Net Security
The GitHub Blog
The GitHub Blog
S
SegmentFault 最新的问题
F
Fortinet All Blogs
I
InfoQ
宝玉的分享
宝玉的分享
A
About on SuperTechFans
MongoDB | Blog
MongoDB | Blog
Microsoft Azure Blog
Blog — PlanetScale
Blog — PlanetScale
B
Blog

Common Crawl

Common Crawl - Blog - Introducing the AI Visibility Audit Common Crawl - Blog - Host- and Domain-Level Web Graphs March, April, and May 2026 Common Crawl - Blog - May 2026 Crawl Archive Now Available Common Crawl - Blog - April 2026 Crawl Archive Now Available in a Hugging Face Storage Bucket Common Crawl - Blog - You can now build directly on Common Crawl from the browser Common Crawl - Blog - Host- and Domain-Level Web Graphs February, March, and April 2026 Common Crawl - Blog - April 2026 Crawl Archive Now Available Common Crawl - Blog - April 2026 Common Crawl Newsletter Common Crawl - Blog - Announcing a Change to Common Crawl Dataset Size Reporting Common Crawl - Blog - Host- and Domain-Level Web Graphs January, February, and March 2026 Common Crawl - Blog - March 2026 Crawl Archive Now Available Common Crawl - Blog - IPv6 Adoption Across the Top 100K Web Hosts Common Crawl - Blog - Web Graph Statistics Gets a Proper Upgrade Common Crawl - Blog - Measuring Web Accessibility from Crawl Archives Common Crawl - Blog - Announcing the Whirlwind Tour of Common Crawl's Datasets Using Java Common Crawl - Blog - Host- and Domain-Level Web Graphs December 2025 and January/February 2026 Common Crawl - Blog - Introducing the New Examples & Resources Browser Common Crawl - Blog - February 2026 Crawl Archive Now Available Common Crawl - Blog - AI Plumbers at FOSDEM’26 Common Crawl - Blog - CC-Citations: A Visualization of Research Papers Referencing Common Crawl Common Crawl - Blog - CommonLID: Re-evaluating State-of-the-Art Language Identification Performance on Web Data Common Crawl - Blog - Host- and Domain-Level Web Graphs November/December 2025 and January 2026 Common Crawl - Blog - January 2026 Crawl Archive Now Available Common Crawl - Blog - Web Archives for Social Sciences Datathon, Bristol Common Crawl - Blog - How SEOs Are Using Common Crawl's Web Graph Data for AI Ranking Signals Common Crawl - Blog - GneissWeb Annotations Examples Common Crawl - Blog - Host- and Domain-Level Web Graphs October, November, December 2025 Common Crawl - Blog - December 2025 Crawl Archive Now Available Common Crawl - Blog - A Sampling of 2025 Research Referencing Common Crawl Common Crawl - Blog - Host- and Domain-Level Web Graphs September, October, and November 2025
Common Crawl - Blog - Common Crawl at the Mozilla Festiva...
2026-01-05 · via Common Crawl

On the 6th of November Pedro attended Mozfest Day 0, an informal workshop organized by Mozilla where attendees had the opportunity to discuss how data sharing and access can be improved, in particular for builders of open source and public AI systems.

The workshop also considered the idea of public AI and how it can be brought “from the lab to the people and the market”. The focus on data as a major bottleneck for open source AI development, due to lack of useful and usable data, and legal uncertainty related to using data for AI development was discussed.

There was also interest in how to govern data that is being generated and used at the deployment phase (inference time). The objective of this workshop was to learn from the experiences of practitioners in this space, those who collect, process, and use data with the open principles and the public interest in mind, but also to chart pathways to better access to data for public AI builders.

BSC visit and ALIA Public AI Forum

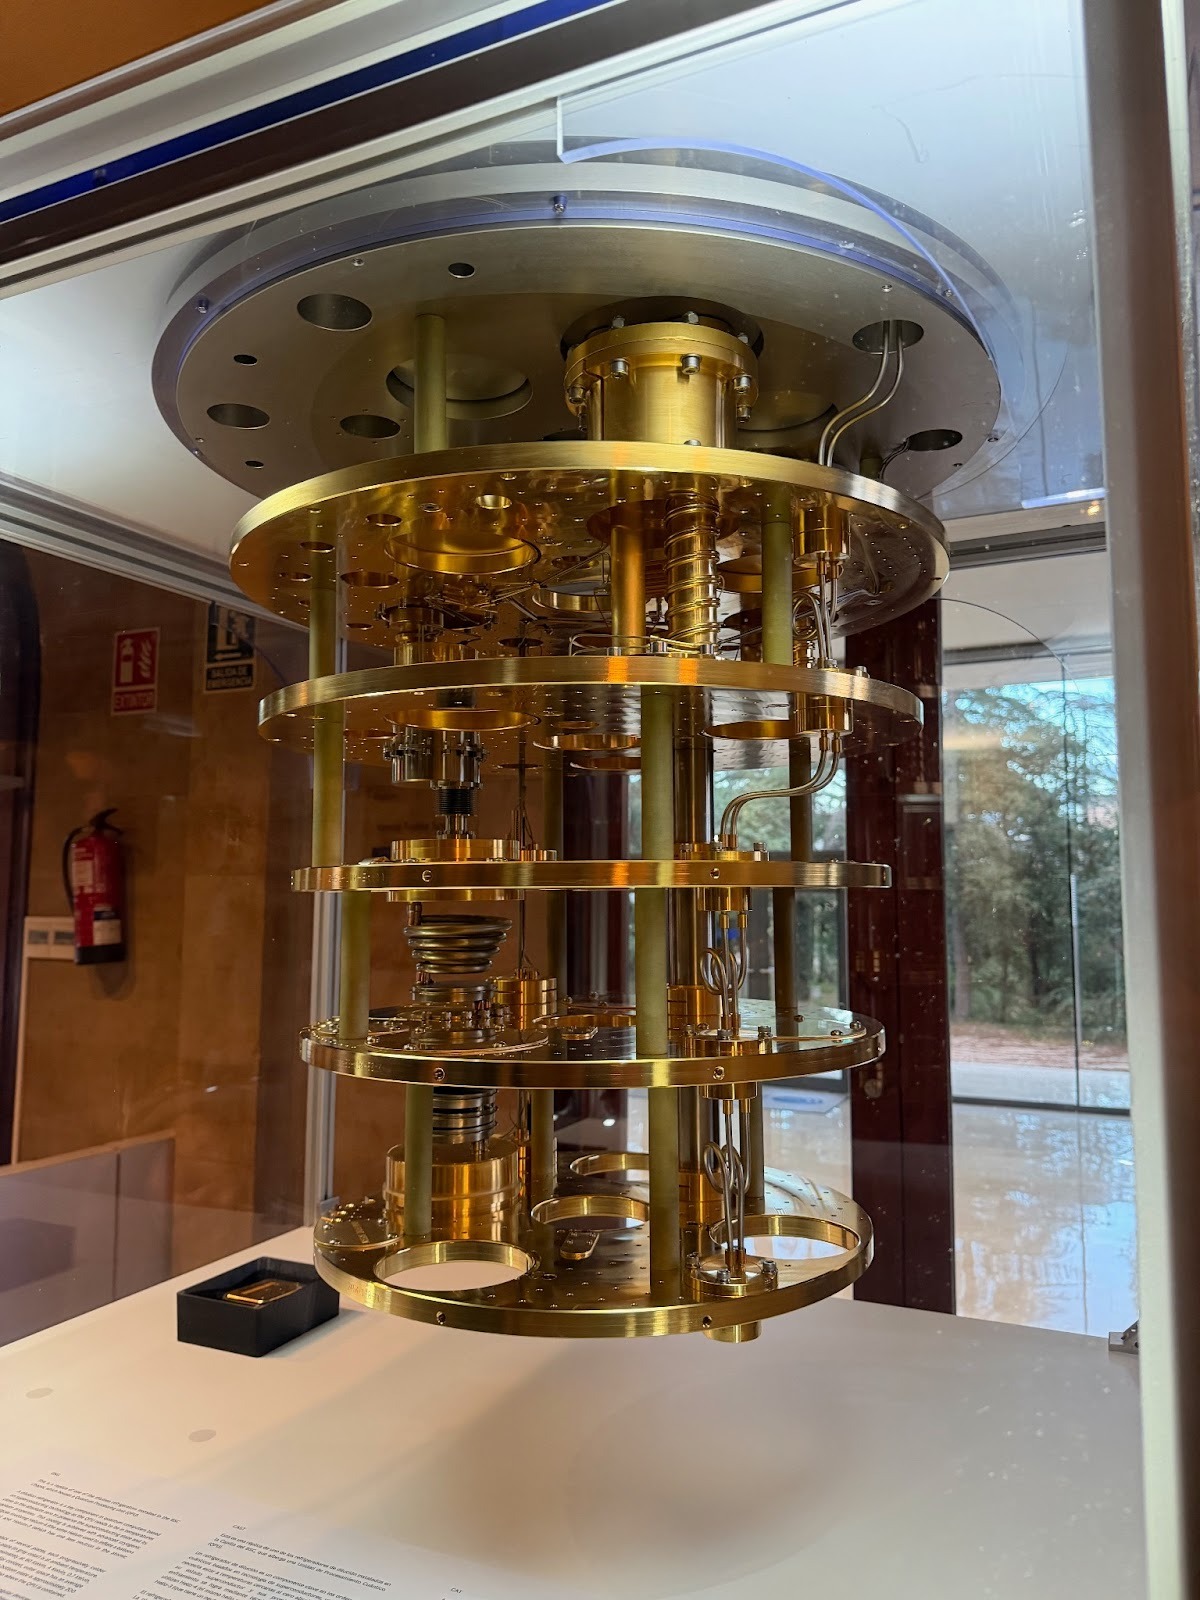
After the initial workshop, attendants were invited for a tour of Barcelona Supercomputing Center (BSC), where we visited their supercomputers, quantum computers as well as the historical decommissioned infrastructure that has been used throughout the years.
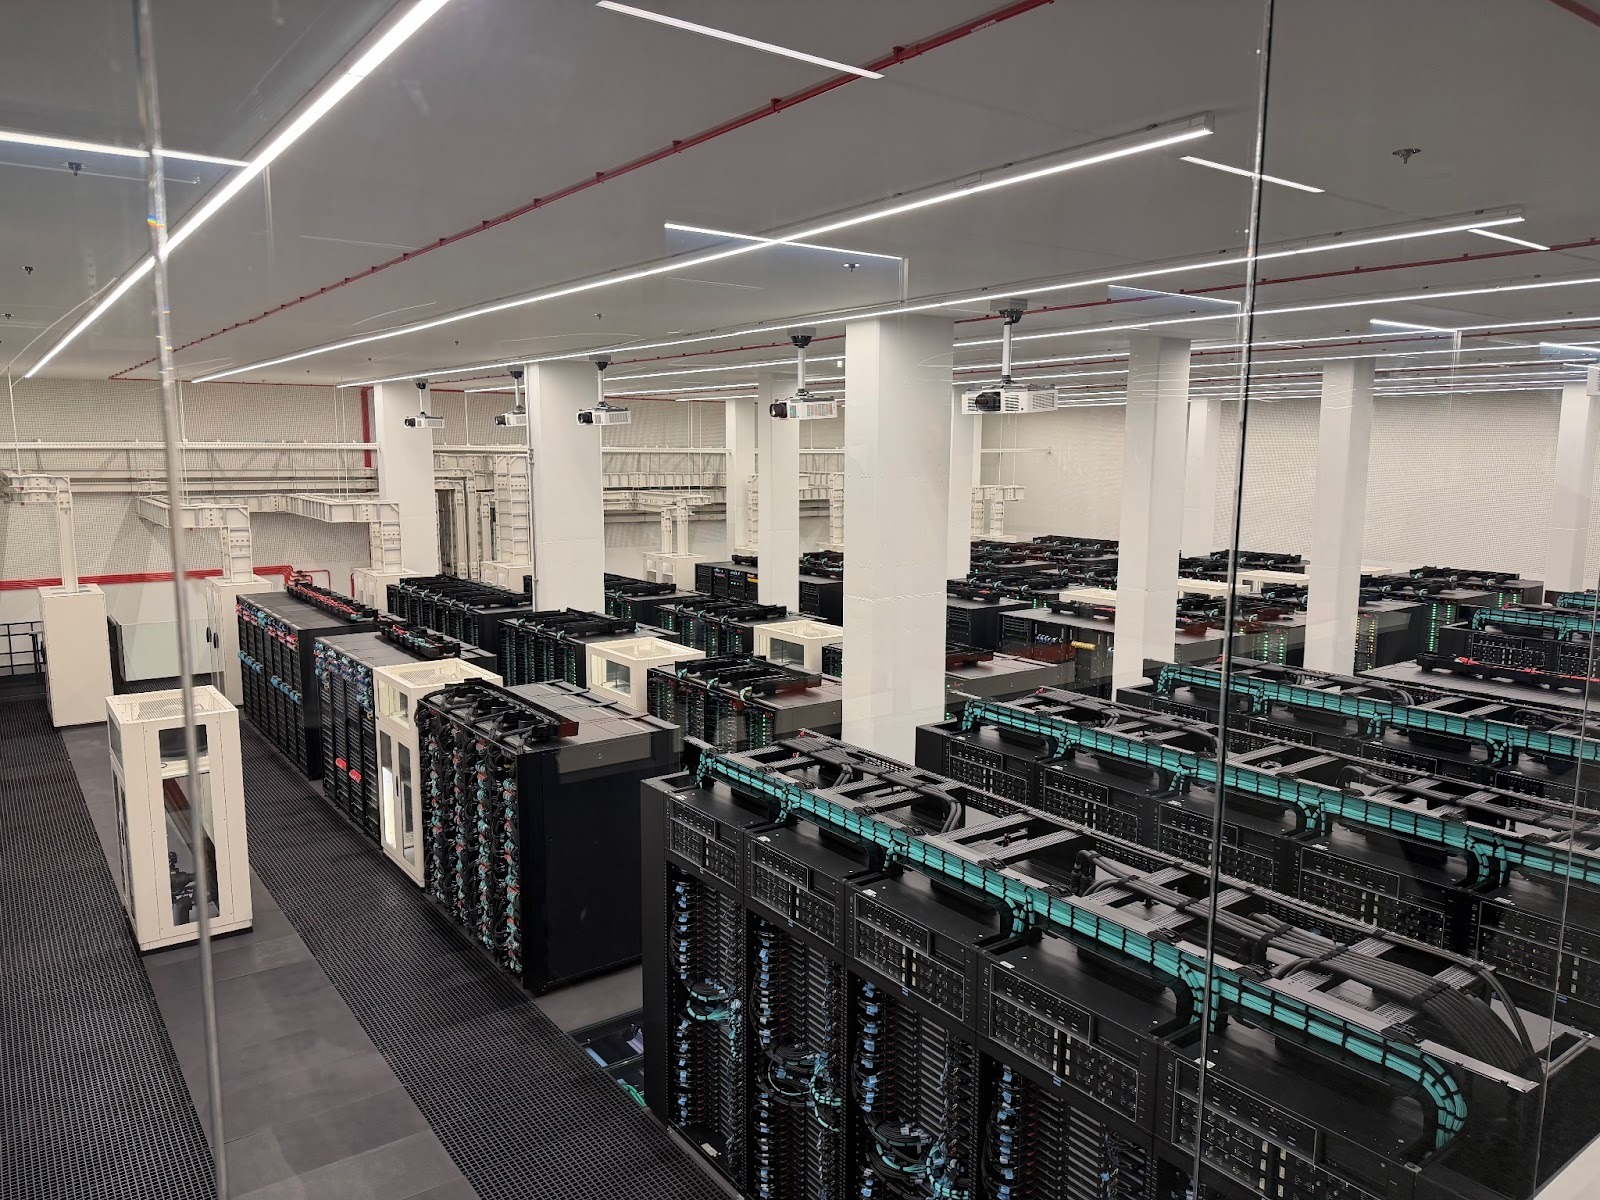
A photo of the server racks of Marenostrum 5, a pre-exascale EuroHPC supercomputer hosted at BSC where the ALIA models have been trained

Marenostrum 5, a pre-exascale EuroHPC supercomputer hosted at BSC where the ALIA models have been trained

A photo of a replica of a Quantum computer hosted at BSC, mainly the cooling system is featured in the photo

A replica of a Quantum computer hosted at BSC

Pedro then attended the ALIA Public AI Forum where we had interventions from BSC and Public AI, explaining the ALIA Project for the development of AI models in Spain for all its co-official languages. The intervention from Public AI also explained the collaboration between them and their efforts in the public AI sector globally.

Common Crawl Foundation at The Mozilla Festival 2025

During the first Mozilla Festival day Pedro had the pleasure of being part of The AI Data Real Talk Panel, which included panelists from many public and private organizations as well as non-profits from a wide range of backgrounds and all over the world.

This panel, which was moderated by EM Lewis-Jong explored data sovereignty, openness, and equity, allowing panelists to talk about actual case studies that represent those values and what it really takes to build datasets for fair, representative systems.

The panelists also explored questions regarding underrepresented and underserved languages in AI, such as the consequences for linguistic communities for their languages to be underrepresented and sometimes misrepresented, what different communities care about when sharing their data and how they can govern and manage the data they share with different actors.

Panelists shared different projects they have in this particular space, in particular Pedro discussed Common Crawl Foundation’s Language Initiatives, took suggestions and addressed concerns from the other panelists and the audience, and learned about the other panelists’ projects.

Participating in such a diverse session at the Mozilla Festival, with panelists often expressing opposing ideas, was a great opportunity to learn and spark constructive and respectful conversations in a space where we’re still building frameworks to ethically and equitably answer the concerns of underrepresented and underserved linguistic communities in the context of emerging AI technologies.