


AMD, Intel, Nvidia, Arm, and Qualcomm are all selling datacenter CPUs into the AI buildout. The previous piece mapped them across five sockets orbiting the GPU and ranked those sockets by value: coherent host, standard host, thinker, doer, traditional cloud.

The coherent host is the most valuable. The traditional cloud CPU is the least.
Many readers asked if it matters whether the CPU is x86 or Arm.
Honestly, not as much as made out to be. But let’s go socket by socket.
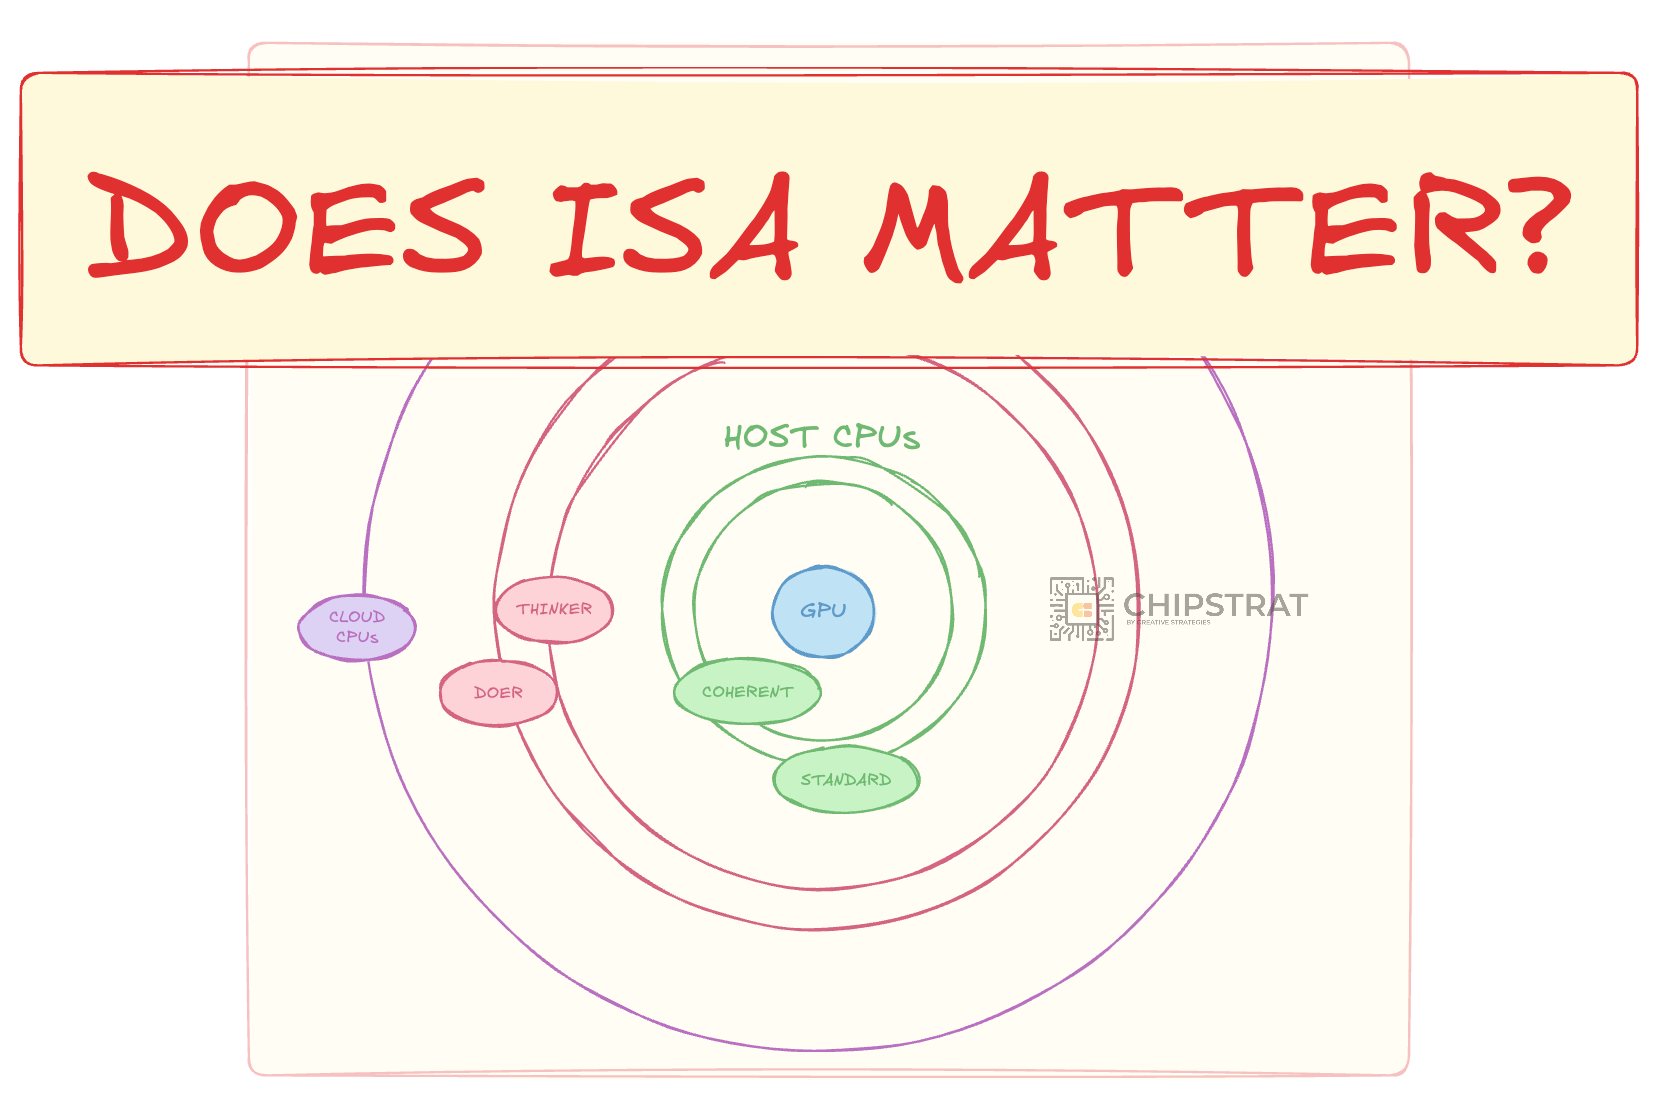
The ISA is the language a CPU speaks. Software gets compiled into that language, and a chip can only run code written for its dialect.
x86 has been the server default for decades. Yet Arm has been gaining in servers, first slowly, then quickly as Graviton, Axion, and Cobalt took hold in cloud, and now inside AI infrastructure as hyperscalers build Arm into their GPU server stacks.
Naturally, everyone asks which ISA is “better” for agentic AI; they’re both just fine.
The more interesting question at each socket is whether the software running there cares which ISA it runs on? Specifically, is the ISA a “moat” at any of the agentic sockets? Let’s see:
The coherent host’s moat is the coherent link to the GPU, not its ISA.
NVLink-C2C connects Nvidia’s Grace CPU to the Blackwell GPU at 900 GB/s, providing a shared address space in which the GPU reads CPU DRAM as if it were local. Vera doubles that to 1.8 TB/s with Rubin. Infinity Fabric ties AMD’s EPYC to the Instinct MI455X at comparable bandwidth. The coherent link is what makes this socket valuable. It’s what no other CPU can replicate without a bilateral design agreement with the GPU vendor... like NVLink Fusion...
Before Grace, Nvidia GPU servers shipped with standard x86 hosts (Intel Xeon or AMD EPYC) connected over PCIe. Grace Hopper (2023) was Nvidia’s first coherent superchip: Grace CPU (Arm, Neoverse V2) connected to the Hopper GPU via NVLink-C2C at 900 GB/s — and Nvidia’s first deployment of the full datacenter CUDA stack on an Arm server CPU. CUDA already ran on Arm through the Jetson embedded line, but this was the server-grade debut.
Grace Blackwell carried that forward; Vera Rubin extends it with a custom Arm CPU (88 Nvidia-designed cores) at 1.8 TB/s to Rubin.
So clearly, ISA isn’t a differentiator for the 800-lb gorilla. Host software runs on either.
What about AMD? ROCm is effectively x86-native. AMD’s coherent platform is built around EPYC, so an Arm port has naturally never been a priority.
The main takeaway is that the ISA is baked into the accelerator platform choice.
NVLink Fusion is Nvidia’s move to open the coherent-host socket to third-party CPUs. Previously, the only CPU that could claim a coherent seat on Nvidia’s backend was the one Nvidia built (Grace/Vera). NVLink Fusion allows other vendors to couple their processors to Blackwell GPUs over the same high-bandwidth coherent link Grace uses. Note that no NVLink Fusion product has actually shipped yet, these are simply announced partnerships. But the partner list includes Qualcomm (Arm), Fujitsu, Intel (x86), and SiFive (RISC-V).
If and when these ship, the coherent-host socket will be accessible to any ISA, so the moat is most definitely not the ISA. RISC-V even... although lots of software porting required.
The standard host’s job is to keep the GPU fed: tokenize inputs, batch requests, stage data over PCIe, manage memory. The CPU needs to work as fast as possible and also move a lot of data. PCIe can become a bottleneck here… hence the coherent host.
The hyperscalers started with x86 standard hosts paired with their XPUs, but that has moved toward Arm. AWS pairs Graviton with Trainium. Google pairs Axion with its gen 8 TPUs.
The feed-the-XPU stack runs on x86 or Arm interchangeably; ISA is not the moat.
Note that there is still an x86 standard-host business in smaller deployments, specifically enterprises and small neoclouds running DGX, Instinct MI355X, RTX Pro 6000 servers, and so on.
In these setups, the host often runs double duty with GPU feeding and application-tier workloads on the same box. That brings legacy x86 software dependencies back into the picture, and ISA does matter. Lower volume, but will grow.
Takeaway: if the host is doing double duty as application processor, then ISA matters. Otherwise, nope.
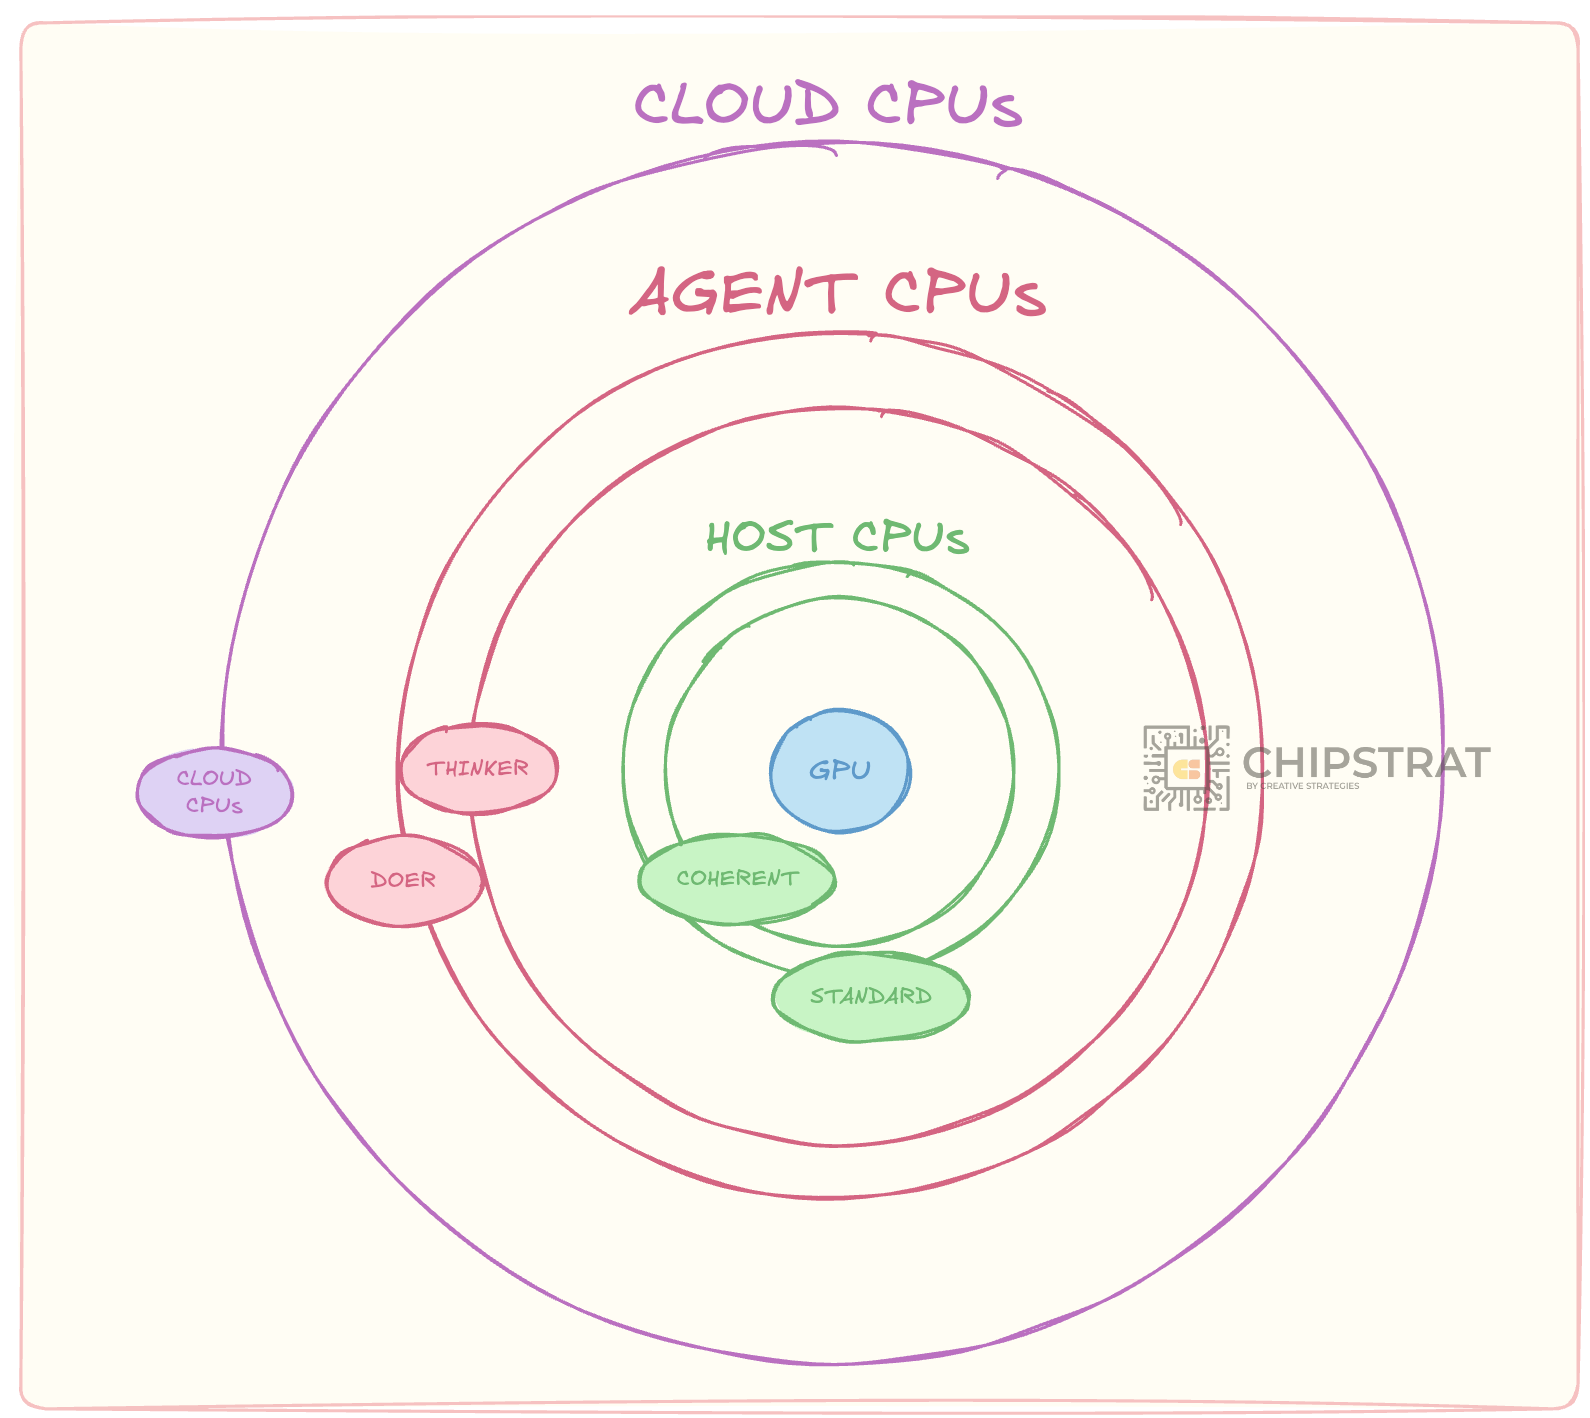
The two orbits closest to the GPU give the same answer: ISA does not matter there. The three that remain do not all agree. One has a real x86 lock-in story. One has a wrinkle. One… not so much.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。