











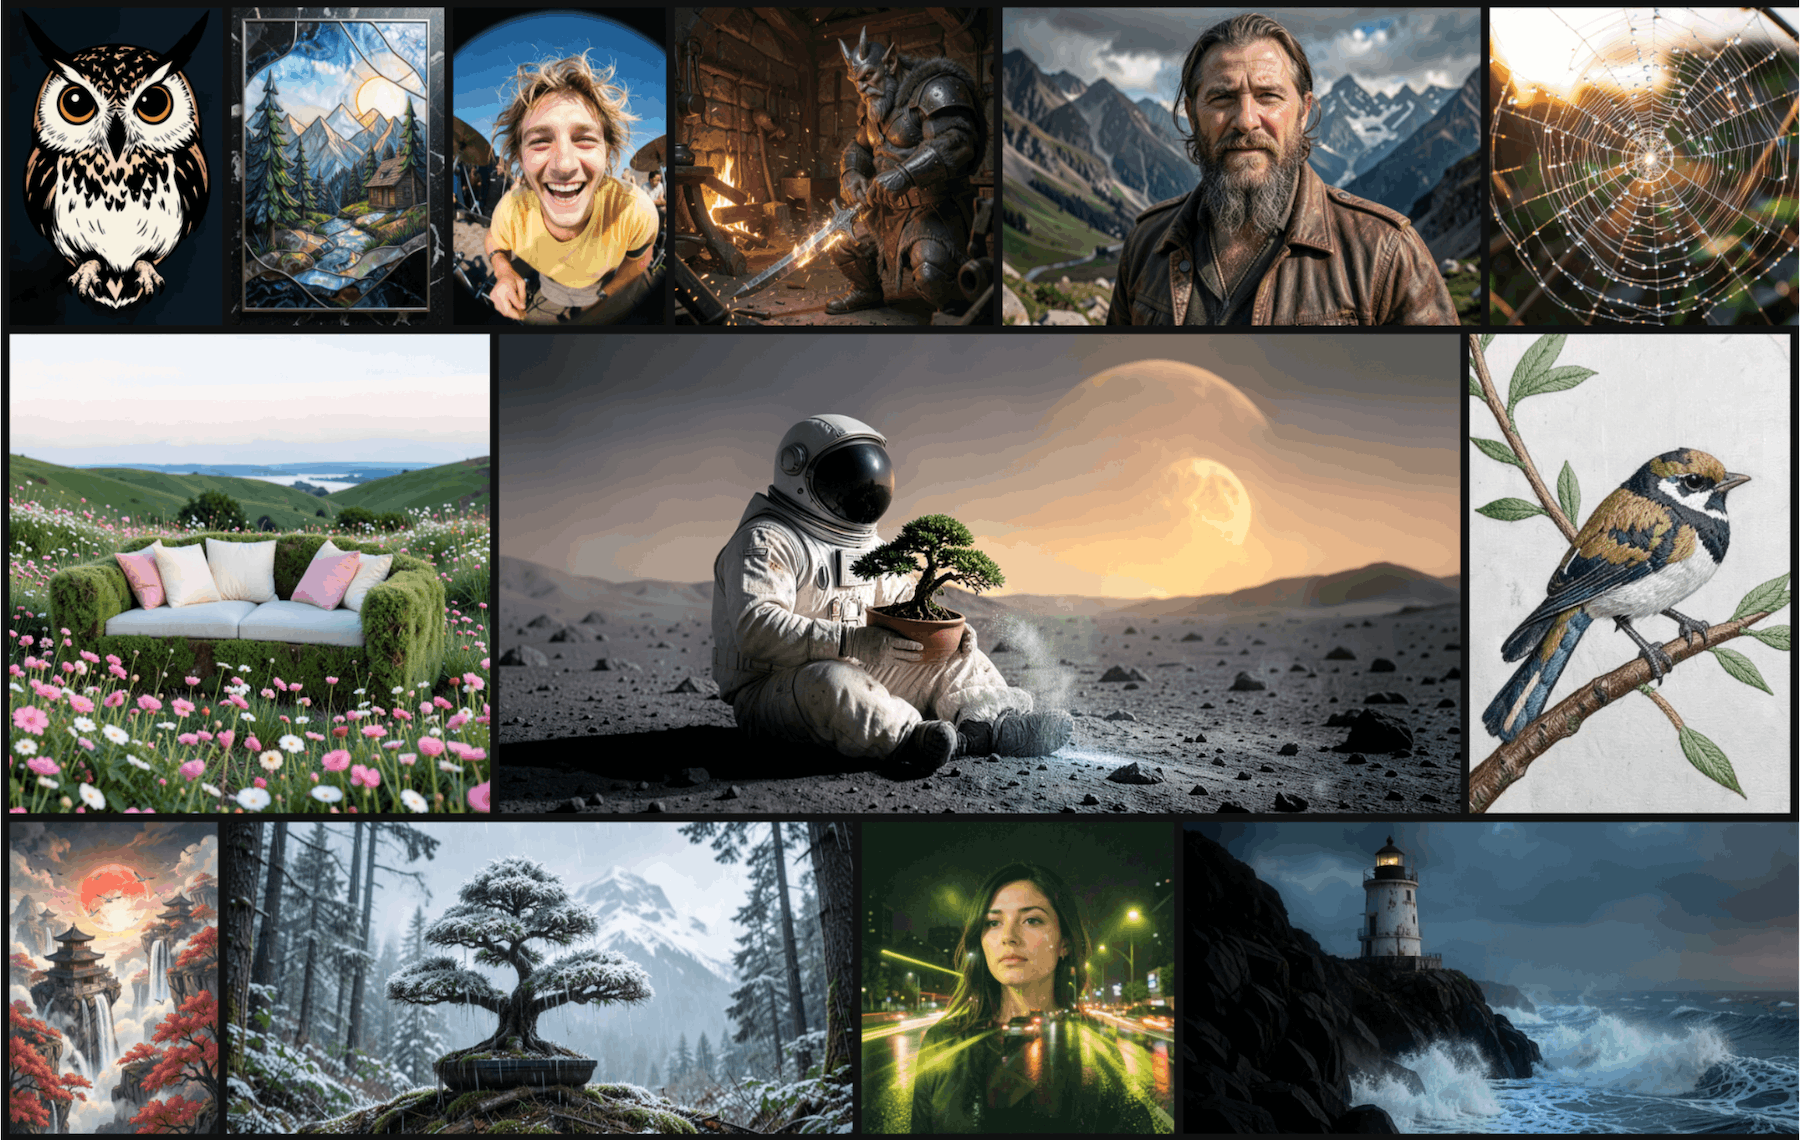
Today we’re releasing Bonsai Image 4B, a family of compact image-generation models designed to run high-quality diffusion inference on local hardware: from laptops to phones.
Bonsai Image 4B comes in two variants:
The result is a new deployment regime for image generation: capable outputs, open weights, and practical local inference on devices that were previously out of reach for this class of model. To our knowledge, Bonsai Image 4B is the first image model in its parameter class to run directly on an iPhone.

Local image generation starts with a hard constraint: the model has to fit within the device’s memory budget.
For a 4B-class image model, the diffusion transformer is the largest part of the model and the part that runs repeatedly during generation. Each denoising step invokes the transformer again, so transformer size directly shapes memory pressure, bandwidth demand, and local inference speed.
Bonsai Image 4B is built from the FLUX.2 Klein 4B. It keeps the architecture intact but changes how the transformer weights are represented. By moving those weights into binary and ternary form, Bonsai reduces the part of the image pipeline that matters most for local deployment.
Table I: Diffusion transformer footprint for models.
The binary layers provide roughly a 14x reduction relative to full-precision transformer weights. A small set of precision-sensitive supporting tensors (~5%), called the projection layers, remains in FP16 so the final 1-bit Bonsai Image 4B transformer is 0.93 GB: an 8.3x reduction from the 7.75 GB full-precision FLUX.2 Klein 4B.
The ternary variant follows the same structure. Its ternary layers provide roughly a 10x reduction and the final Ternary Bonsai Image 4B transformer is 1.21 GB, a 6.4x reduction from the full-precision transformer. It is slightly larger than the 1-bit model, but the additional zero state improves visual quality and prompt fidelity.
Including the compressed text encoder and FP16 VAE, the Apple Silicon deployment payload is 3.42 GB for 1-bit Bonsai Image 4B and 3.88 GB for Ternary Bonsai Image 4B. For comparison, the full precision FLUX.2 Klein 4B requires a deployment payload of 15.97 GB. Since, at runtime, the text encoder is offloaded after prompt encoding, the mean memory usage is smaller than the total payload. When generating a 512x512 image, the mean-active memory is 1.5 GB and 1.96 GB, for the binary and ternary models, compared to 11.74 GB for the original FLUX.2 Klein 4B (a reduction of 7.8x and 6.0x, respectively). For a 1024x1024 image, the mean-active memory is 1.95 GB and 2.38 GB, for the binary and ternary models, compared to 14.39 GB for the original FLUX.2 Klein 4B (a reduction of 7.4x and 6.0x, respectively).
This reduction in memory footprint changes where the model can run. Our deployment stack supports Apple Silicon iPhones, iPads and Macs and CUDA GPUs, using MLX low-bit paths on Apple hardware and Gemlite low-bit GEMM kernels on CUDA. On iPhone 17 Pro Max, the full-precision FLUX.2 Klein 4B pipeline does not fit within the device memory budget, while both Bonsai Image variants run on-device.
Video I: Image generation on Bonsai Studio
In practice, Bonsai Image 4B generates a 512x512 image in 9.4 seconds on an iPhone 17 Pro Max and about 6 seconds on Mac M4 Pro. On Mac M4 Pro, Bonsai Image 4B is up to 5.6x faster than the stock full-precision MFLUX pipeline.
Compression only matters if the model remains useful. We evaluated Bonsai Image 4B across three complementary benchmarks: GenEval for object composition and attribute binding; HPSv3 human preference and aesthetic quality; DPG-Bench dense prompt following and semantic faithfulness.

Table II: Image quality benchmark comparison across Ternary Bonsai Image 4B and other models.
Ternary Bonsai Image 4B is the quality-oriented variant. At 1.21 GB, it retains 95% of the FLUX.2 Klein 4B accuracy across GenEval, HPSv3, and DPG-Bench, while reducing the diffusion transformer footprint by 6.4x.
1-bit Bonsai Image 4B is the footprint-oriented variant. It brings the diffusion transformer below 1 GB, an 8.3x reduction, while still delivering strong benchmark scores across the same three evaluations (it retains 88% of the accuracy of FLUX.2 Klein 4B).
Together, the two variants move the quality–footprint frontier. Bonsai Image remains competitive with modern 4B-class image models while using a fraction of their diffusion-transformer footprint. At the same time, it substantially outperforms smaller models with similar memory footprints. That is the same Pareto shift we have seen in our prior Bonsai language models. Bonsai Image brings modern diffusion-transformer behavior into a memory range that previously belonged to much smaller, lower-capability models.
Image generation is not only a model-quality problem. It is also a deployment problem.
Cloud APIs will continue to be the right choice for many products. But cloud-only generation imposes certain product constraints: every prompt is a remote request, every iteration carries marginal serving cost, and every interaction adds round-trip latency.
That matters because image generation is naturally iterative. Users rarely stop at one image. They revise prompts, compare outputs, generate variations, discard failures, and try again. When each attempt is a server-side job, the creative loop becomes something users have to meter and wait for.
Local inference changes that. Once the model fits on the device, generation can sit directly inside the product experience. It becomes cheaper to run, faster to iterate on, and easier to use in environments where prompts, and generated assets should remain private.
Bonsai Image 4B is a step toward that deployment regime: capable image generation running closer to the user, on hardware they already own.
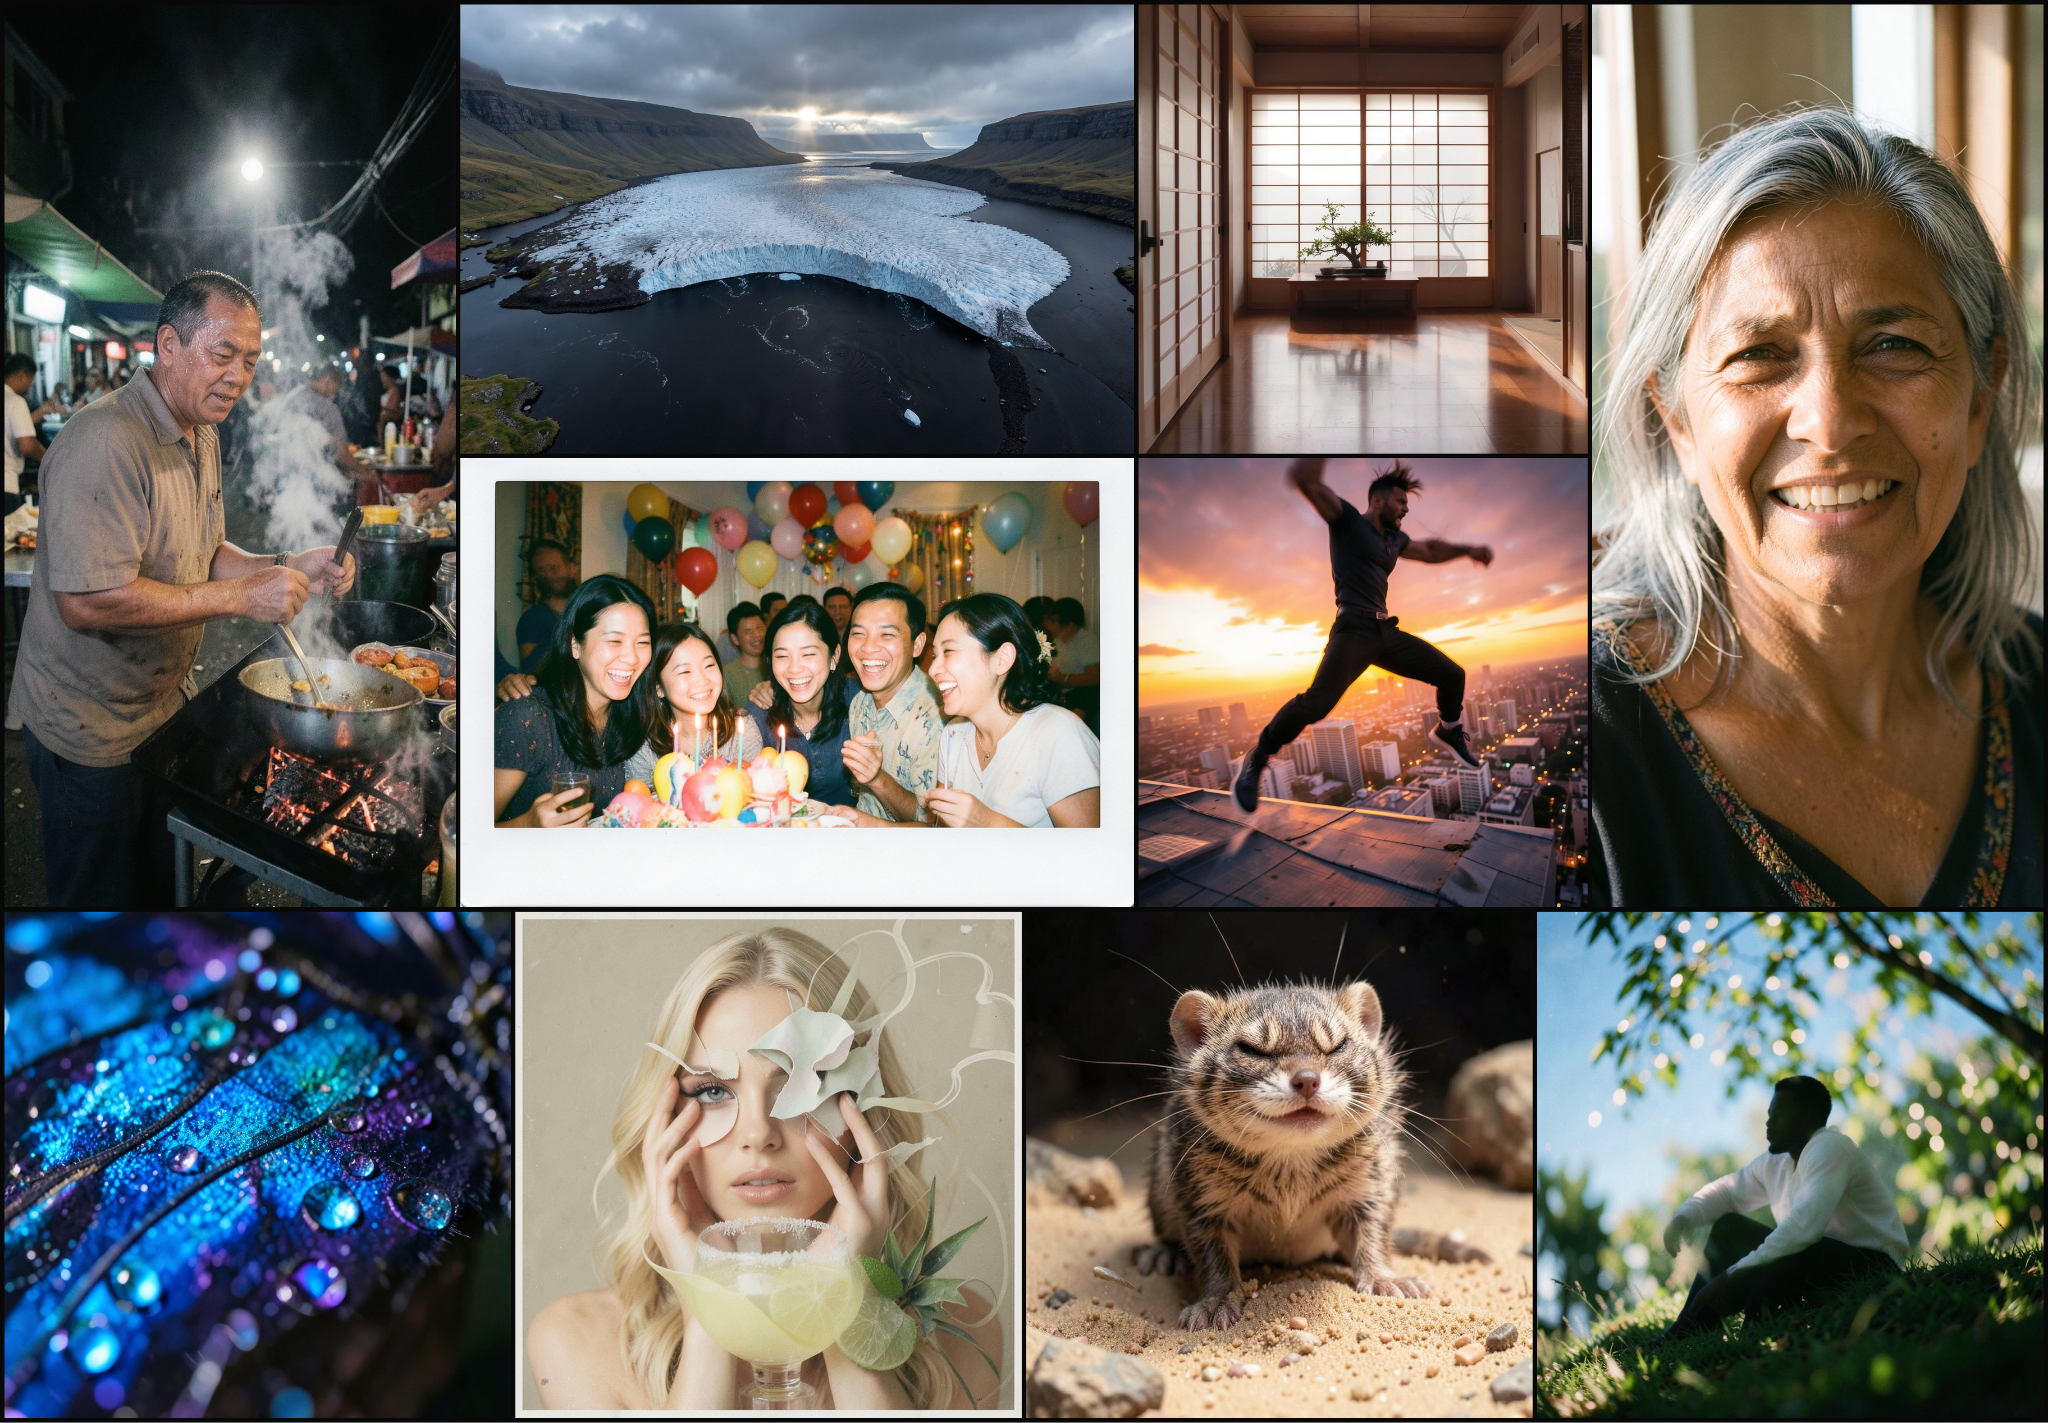
Both 1-bit and Ternary Bonsai Image 4B will be released with open weights and code under the Apache 2.0 license.
With this launch, we are also launching Bonsai Studio, its iOS app for trying Bonsai Image 4B directly on iPhone.
PrismML emerged from a team of Caltech researchers and was founded with support from Khosla Ventures, Cerberus and Google. We’ve spent years tackling one of the field’s hardest problems: compressing neural networks without sacrificing their reasoning ability.
If you want to help build the next generation of state-of-the-art AI, we’d love to hear from you. Check out our careers page.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。