




Moving from a monolith to microservices lets you simplify code deployments, improve the reliability of your applications, and give teams autonomy to work independently in their preferred languages and tooling. But adopting a microservices architecture can bring increased complexity that leads to gaps in your team members’ knowledge about how your services work, what dependencies they have, and which teams own them.
The Datadog Software Catalog helps you consolidate knowledge of your organization’s services and streamline communication between SREs, platform engineers, application developers, and service owners. The catalog is automatically populated for APM customers and takes only seconds to import records from other Datadog telemetry data, such as logs and metrics, or from another asset inventory like ServiceNow or Backstage. Taken together, this information helps you simplify service governance and improve the discoverability and reliability of your applications.
In this post, we’ll demonstrate how the Software Catalog helps you improve how you organize and communicate information about your services, manage incidents that impact services and their downstream dependencies, and confidently deploy code updates to your services.
When domain expertise about applications is distributed across teams, it can be hard to locate the people and information you need to resolve issues. And if there’s deep knowledge of your application held by just a single tenured engineer, teams may have difficulty quickly getting the answers they need to operate and troubleshoot their services. By providing a central repository of what your organization knows about its services, the Software Catalog helps engineering teams coordinate high-stakes activities like on-call rotations and incident management, as well as the day-to-day ownership and operation of your services.
The Software Catalog provides key data—such as documentation, runbooks, deployment history, and code libraries—that can help bridge the knowledge gap between new engineers and their experienced teammates, allowing them to gain an understanding of their systems and start contributing right away. The Software Catalog also helps you plan and implement enhancements and bug fixes by making it easy for independent teams to grasp the dependencies among services without having to rely on subject matter experts, spreadsheets, or unnecessary meetings.
The Software Catalog is automatically populated to include components that are instrumented for APM or RUM. It also includes components that are discovered via Universal Service Monitoring—a lightweight, kernel-based service discovery mechanism that requires no instrumentation. You can then specify ownership details of these monitored components in a Software Catalog definition, which is a YAML manifest that is colocated with your source code.
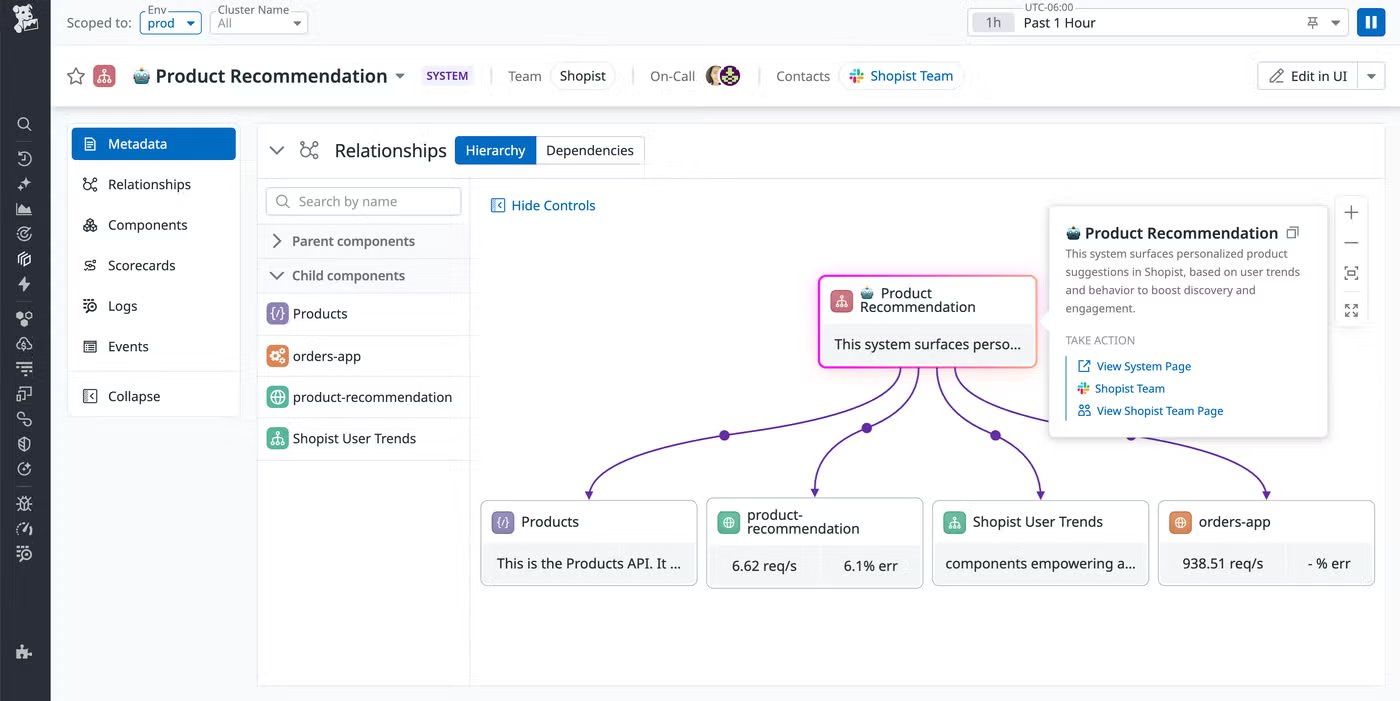
If you use unified service tagging, related telemetry data such as metrics and logs will also be pulled in automatically. Without adding any data manually, you’ll see the dependency map (shown in the following screenshot) plus performance data such as requests, errors, and latency. You’ll also see information about the service’s reliability, security, cloud costs, and pipeline velocity.
You don’t need any Datadog telemetry data to take advantage of the Software Catalog. The flexible Entity Model enables you to keep track of organization-specific object types like cron jobs, packages, and repositories. It also centralizes organizational knowledge about software components alongside observed systems.
The Software Catalog makes it easy for engineers to see on-call contact information for other services—including PagerDuty schedules—so they can quickly communicate with the right people during a live incident. It also gives them critical and current information about services—from performance metrics, dependencies, SLOs, and underlying infrastructure to service owner contact information, documentation, and runbooks. New engineers who are on call may need to quickly learn information that hasn’t been documented, and even experienced incident responders need resources that allow them to confidently investigate and fix problems. The Software Catalog helps on-call engineers reduce incident response time by providing authoritative information—such as code repositories and relevant libraries—within their unified observability platform.
A failing dependency is sometimes the key to understanding an incident, and the Software Catalog’s dependency map makes it easy to see whether a service’s dependencies are in an alert state. You can drill down to get more information about each service—including performance metrics, error rates, and SLO status—as well as recent activity like deployments and incidents. All this information helps you fully understand the state of the services you depend on. By providing at-a-glance status and performance information about your organization’s services—as well as service owner contact information and PagerDuty on-call schedules—the dependency map brings deep context to your troubleshooting and incident management processes.
Successful teams deploy code updates frequently, fixing bugs to maximize reliability and performance and adding features to improve customer satisfaction. But even if you release service updates carefully, each deployment presents a risk to the performance and availability of that service and all the services that depend on it. The Software Catalog makes it easy to see which services call yours so you know the potential blast radius of a faulty deployment.
To help teams collaborate to ensure smooth deployments, you can add service owner contact information to each Software Catalog entry—including a link to the relevant team’s Slack channel. The Software Catalog makes it easy for team members to reach out for ad-hoc communication before or during a deployment. It also shows them performance and reliability information about services, giving all parties a single source of truth to boost collaboration and help troubleshoot any unexpected behavior.
The Software Catalog provides information that’s critical to stakeholders throughout the organization—not just service owners. Although teams outside of engineering may not need the same information as the engineers who operate services and resolve incidents, the Software Catalog lets them independently gather key data to answer important questions.
For example, during an active incident, the Software Catalog helps you ensure that stakeholders throughout the organization—such as support teams and technical account managers—have easy access to the key information they need to manage communication. The Software Catalog can also help you coordinate game days and other reliability exercises by providing contact information for the owners of all relevant services and endpoints.
The Software Catalog brings a high-level view into your organization’s services and can be a vital tool for engineering leadership to recognize observability blindspots. By centralizing all of your service knowledge, the Software Catalog helps engineering managers spot services that aren’t instrumented for tracing or profiling, don’t generate sufficient logs, or that have been orphaned without being properly deprecated. Engineering managers can also use data from the Software Catalog to ensure standardization of reliability practices such as SLO status, deployment frequency, PagerDuty on-call coverage, correlation between logs and traces, and integration between your APM and RUM data.
The Software Catalog is a powerful way to collect knowledge of your services within the Datadog platform, helping you eliminate knowledge gaps even as your environment scales to comprise hundreds of services. Together with Scorecards and Self-Service Actions, the Software Catalog is a foundational piece of Datadog’s Internal Developer Portal (IDP) product. Many of its features are generally available and free to use for all Datadog customers as part of the platform. Advanced features, such as custom entities, are part of IDP and may come with additional costs. See the pricing page for details. See the Software Catalog docs to start using the Software Catalog, and if you’re not already using Datadog, you can start today with a 14-day free trial.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。