


Paul Gottschling
Datadog Technical Content Writer
AWS Elastic Compute Cloud (EC2) makes it easy to launch and terminate virtual machines. AWS Auto Scaling goes a step further and makes the process automatic. With Datadog’s Auto Scaling integration, you can track metrics and events from your Auto Scaling groups in the same place as the rest of your AWS services.
The integration comes with an out-of-the-box screenboard that lists recent Auto Scaling events, shows you how your groups have changed over time, and gives you a sense of how large your groups are, both in aggregate and as a distribution.
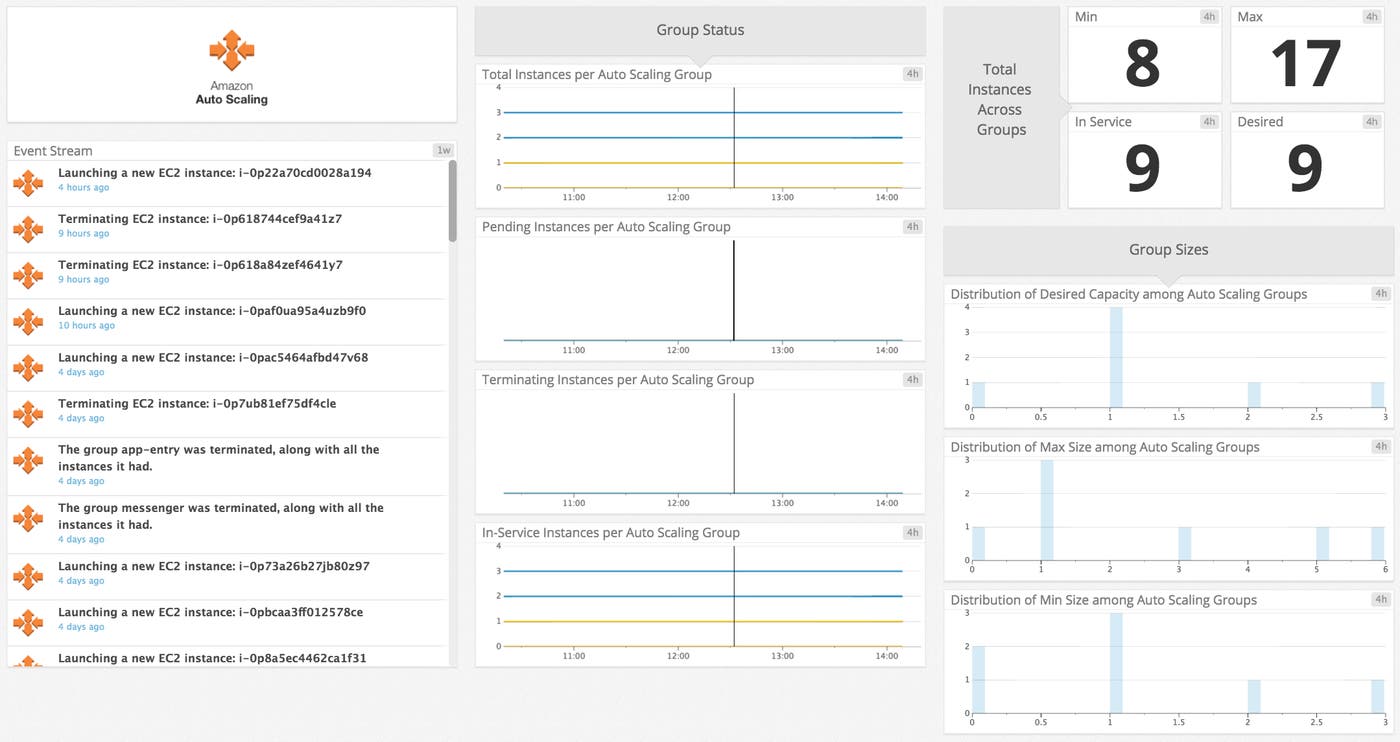
The load on your EC2 fleet changes over time. You might have routine fluctuations in resource usage, a threshold of acceptable load, or a definite number of instances to which you want to scale. AWS Auto Scaling lets you specify how your fleet responds, automatically, to changes in demand, in order to ensure the performance and availability of your applications.
You can configure Auto Scaling to scale resources based on your applications’ specific needs. For example, you can specify:
a regular scaling schedule that, for instance, keeps pace with typical traffic patterns over a given week
a scaling policy that responds dynamically to demand, which you define based on metrics you choose
an explicit number of instances to maintain at a given time, with maximum and minimum limits (manual scaling)
As your EC2 fleet grows, Datadog’s integration can help you determine the most appropriate ways to configure your Auto Scaling groups to ensure that your infrastructure stays in step with demand.
With dynamic scaling, AWS Auto Scaling will spin up and shut down EC2 instances based on the value of a metric of your choice. To determine the best metric for your instances, you can graph, compare, and correlate resource metrics across your Auto Scaling groups. In Datadog, each Auto Scaling metric is tagged automatically with its autoscaling_group. You can use this tag to create targeted dashboards like the one below. Here we are comparing CPU, IO, and memory usage per host across three Auto Scaling groups.
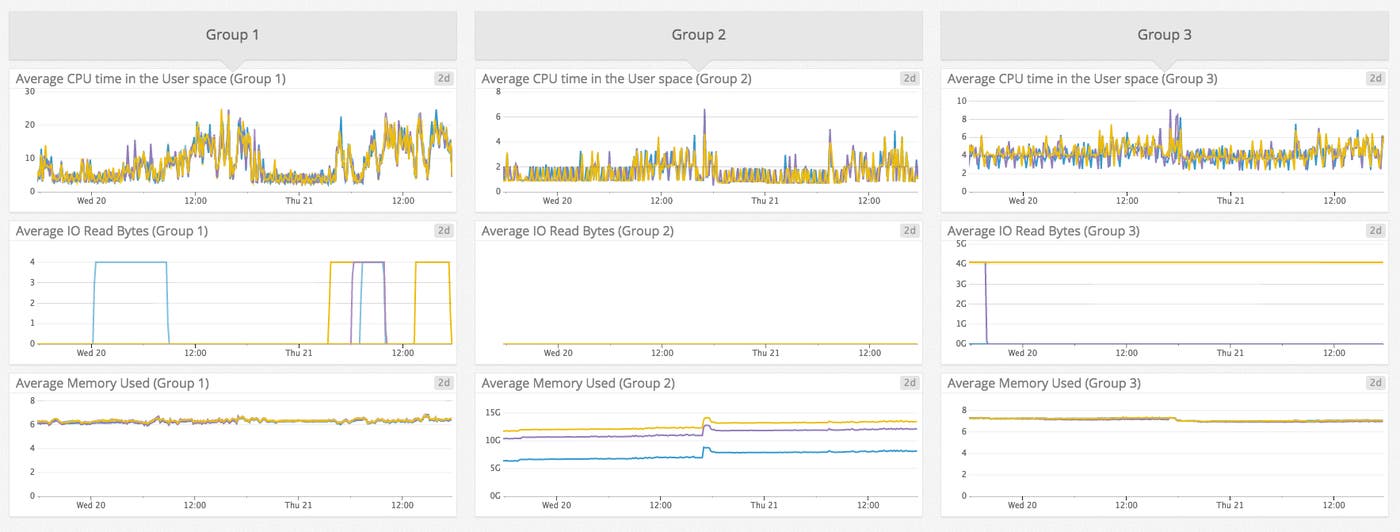
By tracking the resource usage of your groups over time, you can select an appropriate metric to specify in each group’s scaling policy.
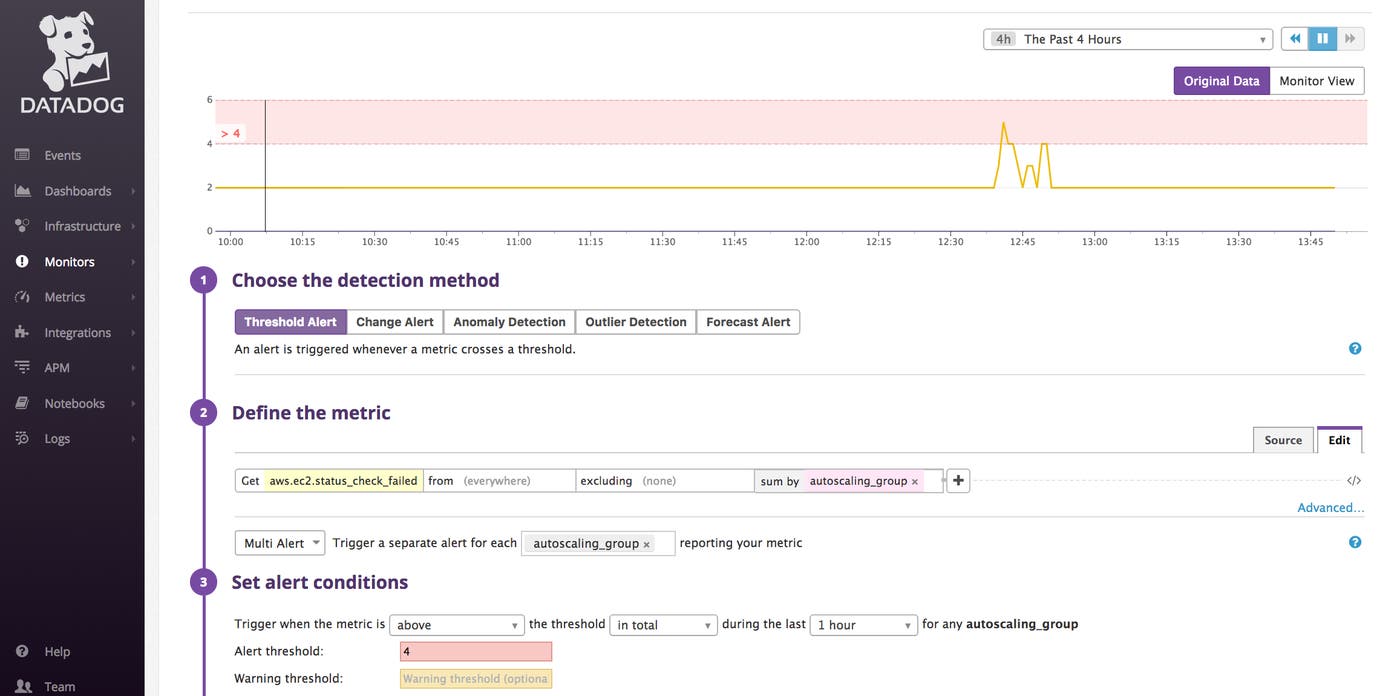
Auto Scaling periodically checks the health of your instances, and relaunches any unhealthy instances as needed, in order to maintain each group’s minimum size. In Datadog, you can set alerts to gauge the health of your Auto Scaling groups and determine if they respond appropriately when the demand on your fleet changes.
As shown below, we have set an alert to trigger whenever there are more than four EC2 instance failures in a given Auto Scaling group in one hour.
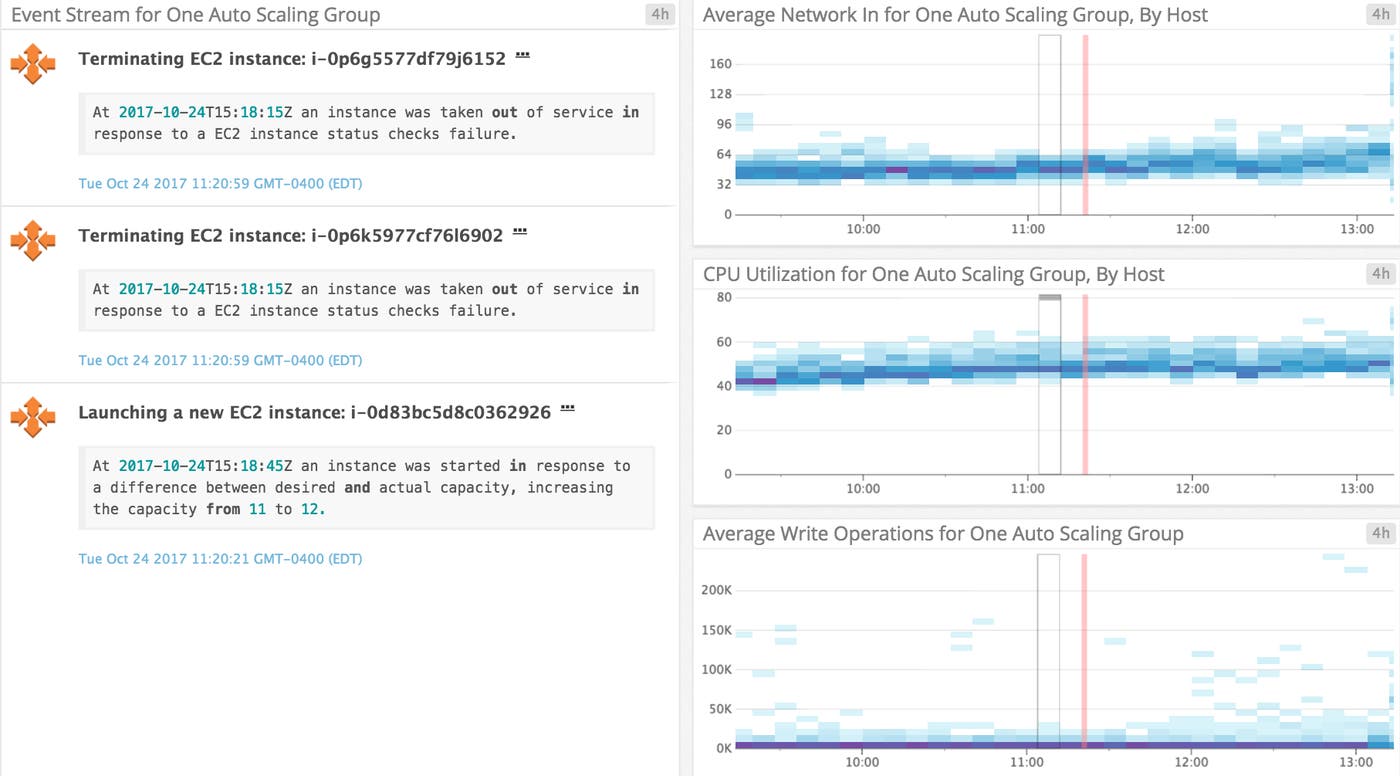
With Datadog’s Auto Scaling integration, you can tell at a glance whether failed health checks or other events correspond to changes in your instances’ metrics. Display events from any Auto Scaling group by creating an event stream with the query, sources:autoscaling, or focus on a single group using the autoscaling_group tag to filter your query. Alongside these events, you can track metrics for hosts within your groups to see if a spike in failed status checks correlates with a resource issue such as surging CPU usage or plummeting instance memory.
Once you’ve set up Datadog’s Amazon Web Services integration, simply enable Auto Scaling in the AWS integration tile to start monitoring Auto Scaling metrics and events. If you’re not using Datadog yet, get started with a 14-day free trial.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。