









Elijah Andrews
This post is the second of a two-part series on Memcached. In my first Memcached post, I showed you a typical web application request that can be optimized using Memcached and detailed how to collect general Memcached performance metrics using the Datadog Agent. This week, I’m going to show you how to dive a bit deeper into your cache’s performance.
While the integration dashboard is great for a general overview of Memcached performance metrics, Datadog also makes it easy to instrument custom metrics. These metrics will allow you to instrument Memcached performance metrics for requests specific to your application. To report these metrics, you’ll need our client-side instrumentation library, DogStatsD.
In this post, we’re going to cover how to calculate hit ratios for individual requests and time your requests using DogStatsD in order to get the most out of your cache.
The Memcached integration dashboard provides hit and miss rates for your entire cache, giving insight into the general functionality of the system. However, once you start using Memcached in multiple locations across your code, you’ll likely want to evaluate hit and miss counts for individual requests. Let’s take another look at our get_user function that we defined last week, adding a few lines to count the number of hits and misses for this request:
Every time we hit the cache, we’ll increment the get_user.hit counter. We’ll do the same thing with the get_user.miss counter, except that it will be incremented on a cache miss.
Once we start reporting these metrics, we can graph them on Datadog:
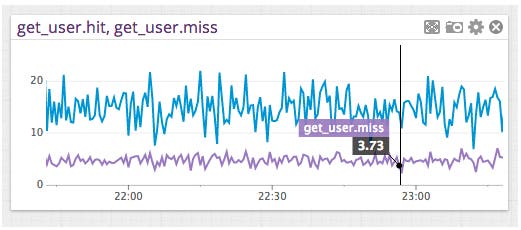
The blue line represents the number of cache hits per second, while the purple line represents the same metric for misses.
A useful metric for evaluating the effectiveness of a cache is its hit ratio, which tells you the percentage of requests that result in a cache hit. A good cache will have a hit ratio close to 1, while a bad cache will have a hit ratio near 0. The hit ratio can be calculated using the following formula:
hit_ratio = number_of_cache_hits / (number_of_cache_hits + number_of_cache_misses)
Using the Datadog Graph Editor’s JSON tab, we can easily update our previous graph to display our cache’s hit ratio for the get_user request:
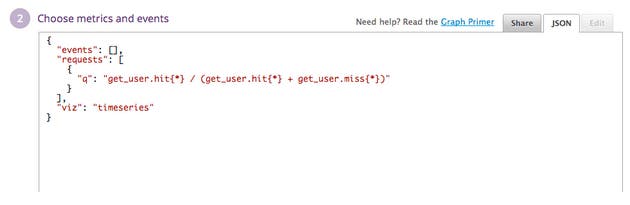
When you submit the JSON updates to the graph, you’ll see the hit ratio for the get_user request:
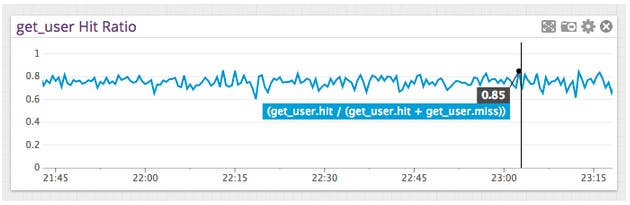
It looks like the average hit ratio for this cache is around 0.8, which means that it’s working quite well.
We can also use DogStatsD to measure precisely how long a request is taking within your application code. A high hit ratio is usually a good sign that your cache is working effectively, but it is not the only metric you should pay attention to. Perhaps the cached result was not expensive to obtain, and the overhead incurred when serializing and deserializing the result into Memcached is greater than the cost of the original query. Therefore, we should also time our request to verify that Memcached is beneficial:
Here, we’ve added a few lines to send a timer for our request though DogStatsD, using the metric name response_time. We can now graph the average time for this request on Datadog:
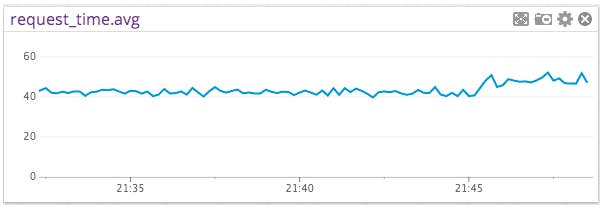
You probably noticed that we tagged the metric with request:get_user, and either cache:hit or cache:miss depending on whichever occurred. This allows us to slice the response_time metric across any of these dimensions. If we start reporting the response time for other requests using the response_time metric, the graph above will show us the average response time for all of the requests that report this metric. We can single out the get_user request by jumping into the Graph Editor and specifying to only display metrics with the request:get_user tag:
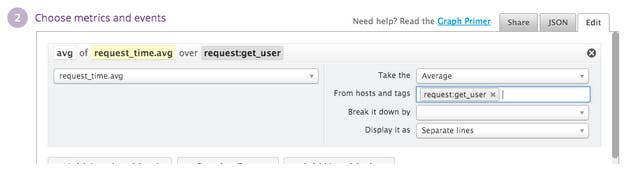
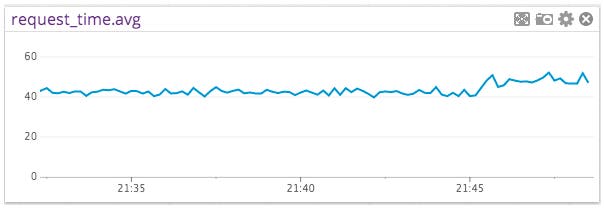
Finally, the cache tags allows us to break the data down into occurrences where the cache is either hit or missed:
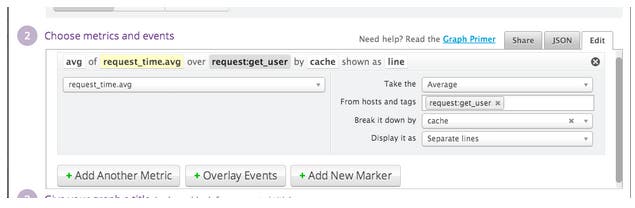
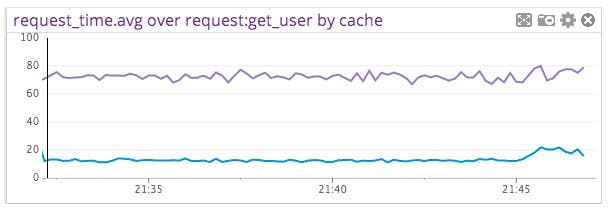
The purple line in the above graph represents the average time taken by get_user when the cache missed, while the blue line represents the same metric when the cache is hit. Clearly, the requests that hit the cache are much faster. Therefore, our cache is doing its job.
In conclusion, we’ve used DogStatsD to instrument custom metrics for a specific request utilizing Memcached, allowing us to gain insight into the effectiveness of the cache for this specific application. However, we’ve only scratched the surface of what Memcached and Datadog can do for your web application. For more information about the subtleties of Memcached, head over to the Memcached home page. To check out all the ways Datadog can monitor your web application’s performance, try a free trial for 14 days.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。