


If you’ve configured your application to expose metrics to a Prometheus backend, you can now send that data to Datadog. Starting with version 6.5.0 of the Datadog Agent, you can use the OpenMetric exposition format to monitor Prometheus metrics alongside all the other data collected by Datadog’s built-in integrations and custom instrumentation libraries. In this post, we’ll take a look at how the integration works.
Prometheus is an open source monitoring system for timeseries metric data. Prometheus provides a dimensional data model—metrics are enriched with metadata known as labels, which are key-value pairs that add dimensions such as hostname, service, or data center to your timeseries. Labels are equivalent to Datadog tags and allow you to categorize, filter, and aggregate your metrics by any attribute that is important to you. Applications expose monitoring data to Prometheus using a text-based exposition format that encodes the name of the metric, the metric value corresponding to a given timestamp, and any associated labels. And, as part of an ongoing project, OpenMetrics is working to provide a standard text-based format for exposing that metric data.
Below is an example of a Prometheus metric counting HTTP requests to a server, with labels denoting the HTTP request type, response code, and environment:
# HELP http_requests_total The total number of HTTP requests.
# TYPE http_requests_total counter
http_requests_total{method="post",code="200",env="qa"} 500 1592064363100
http_requests_total{method="post",code="400",env="dev"} 1 1592064363100
Datadog strives to make instrumentation as easy as possible. As members of the Cloud Native Computing Foundation, we are dedicated to open source and committed to providing you with the ability to seamlessly monitor all your systems with our integrations and support for common data formats. Whether your applications send metrics using the StatsD protocol, via JMX, or using one of our open and extensible instrumentation libraries, you can start monitoring your data with minimal changes to your infrastructure and services. We have added the OpenMetrics exposition format to our supported data types to make it just as easy to monitor your applications that are already set up to report metrics to Prometheus or to another OpenMetrics backend.
Datadog pulls data for monitoring by running a customizable Agent check that scrapes available endpoints for any exposed metrics.
To start collecting these metrics, you will need to edit the Agent’s conf.yaml.example configuration file for the OpenMetrics check. You can find it in your host’s /etc/datadog-agent/conf.d/openmetrics.d/ directory.
Below is an example configuration:
instances:
# The prometheus endpoint to query from
- prometheus_url: http://targethost:9090/metrics
namespace: "myapp"
metrics:
- prometheus_target_interval_length_seconds: target_interval_length
- http_requests_total
- http*
This basic setup includes the Prometheus endpoint, a namespace that will be prepended to all collected metrics, and the metrics you want the Agent to scrape. You can use * wildcards to pull in all metrics that match a given pattern, and you can also map existing Prometheus metrics to custom metric names. In the example above, the Prometheus metric prometheus_target_interval_length_seconds will appear in Datadog as myapp.target_interval_length.
Save the file as conf.yaml, then restart the Agent. If configured properly, you should see the openmetrics check under Running Checks when you run the Agent’s status command:
openmetrics
----------
Total Runs: 4096
Metrics: 3, Total Metrics: 12288
Events: 0, Total Events: 0
Service Checks: 1, Total Service Checks: 4096
For a comprehensive list of options, take a look at this example config file for the generic OpenMetrics check.
Once the Agent is configured to grab Prometheus metrics, you can use them to build comprehensive Datadog graphs, dashboards, and alerts.
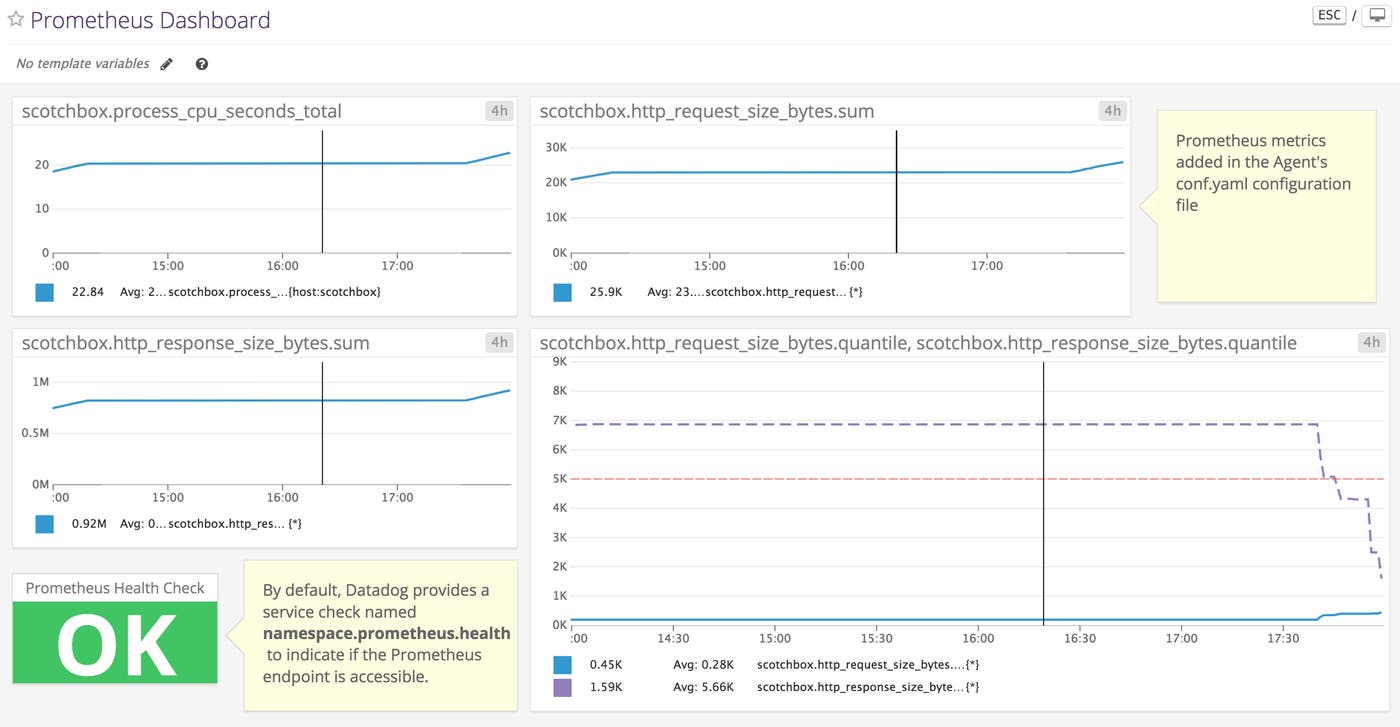
Our new integration works with the Prometheus data model by mapping labels to Datadog tags automatically for all collected metrics. With this integration, you can filter and aggregate your data using any dimension you care about.
In addition to pulling in application metrics, Datadog provides a service check that monitors the health of your Prometheus endpoint.
If you need more control over what the Agent monitors and provides through its generic OpenMetrics check, you can create a custom check. Custom checks are useful when you need to include additional, pre-processing logic around the metrics you collect. Check out the advanced usage guide for more information on how to create a custom OpenMetrics check.
Prometheus is often deployed alongside Kubernetes and other cloud-native technologies. Building on our extensive support for Kubernetes monitoring, Datadog integrates seamlessly with Kubernetes components that expose metrics via the OpenMetrics exposition format, such as CoreDNS and kube-dns. And Datadog’s Autodiscovery feature, which continually monitors dynamic containers and services, allows you to automate the collection of Prometheus metrics in your cluster. Autodiscovery tracks containerized services by applying configuration templates that are attached to those services via Kubernetes pod annotations. Similar to the configuration of the Agent check above, you can include the OpenMetrics check, the Prometheus URL, namespace, and metrics in an annotation to enable the Datadog Agent to start collecting metrics from that service whenever it starts up in your cluster:
annotations:
ad.datadoghq.com/container.check_names: '["openmetrics"]'
ad.datadoghq.com/container.init_configs: '[{}]'
ad.datadoghq.com/container.instances: '[{"prometheus_url": "http://%%host%%:9090/metrics","namespace": "myapp","metrics": ["http_requests_total"],"type_overrides": {"http_requests_total": "gauge"}}]'
With customizable OpenMetrics checks and Datadog’s Autodiscovery feature, you can proactively monitor all the containerized services in your cluster.
Note that Prometheus metrics monitored by the Agent fall under the custom metric category and are therefore subject to certain limits. Read up on custom metric allowances to learn more.
Datadog makes it easy to gather all the monitoring data you need by integrating with a wide variety of platforms, applications, programming languages, and data formats. Setting up Datadog’s integration to scrape Prometheus endpoints with OpenMetrics allows you to monitor your instrumented applications alongside all the infrastructure components, applications, and services that you have already integrated with Datadog.
To start monitoring your Prometheus metrics in Datadog, visit our integration docs for the Agent. And if you aren’t using Datadog yet, you can sign up for a free trial to bring all your monitoring data together in one platform.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。