


Edith Méndez

Melanie Yu

Aaron Kaplan
As distributed systems grow in complexity and the threat landscape evolves, Security, DevOps, and other teams are faced with an explosion of log data—often hundreds of terabytes per day—from a growing number of on-prem and multi-cloud sources. As a result, managing log data efficiently has become more complex, more costly, and more challenging than ever before.
Meanwhile, organizations are grappling with the rigid pricing models and rising, frequently unpredictable costs of many logging platforms and SIEM tools. Cold-storage solutions, truncated retention periods, and data filtering and sampling can help rein in the growing costs associated with log management, but not without trade-offs: Overreliance on these methods can put critical data out of reach in moments of urgency, weakening security, prolonging incidents, and damaging trust. As a result, organizations are often forced into difficult compromises between visibility, security, and cost efficiency.
This post will explore strategies for optimizing how you manage high-volume logs in order to maintain critical visibility while controlling costs. In it, we’ll discuss the importance of knowing how your logs align with your business priorities as well as three best practices for cost-effective log management at scale:
Different teams have different priorities when it comes to logs, and every team tends to believe their logging needs are paramount. Governance engineers often want unrestricted access to every possible type of log for compliance and auditing purposes. SREs and DevOps teams collect a diverse range of logs for troubleshooting. Security teams prioritize log retention for threat detection and forensic investigations. And CTOs and business leaders are left to balance all of these needs with budget constraints.
As a first step, it’s essential to understand where your log spend is going and consider exactly how each of the many types of logs you collect fits into your business priorities. This means answering a few key questions:
When it comes to understanding your logging spend, tagging is key: Tag logs with their sources, the teams associated with them, and level or tiering info (e.g., hot, warm, cold, debugging, compliance) to facilitate cost analysis. For logs sent to Datadog, organizations can rely on features such as Usage Attribution and the out-of-the-box estimated usage dashboard for Log Management for granular analysis of their logging costs.
Understanding your logs in the context of your business priorities—and cultivating this understanding across teams—is essential to making informed decisions on which logs to collect, how they should be handled, and how to manage logging costs effectively. Otherwise, logging costs can easily spiral out of control.
Once you’ve determined which logs you need to collect, you can zero in on the precise data you need from them. Noisy, context-heavy logs can drive up storage costs and slow down investigations. For example, CDN and firewall logs, which provide indispensable visibility to security and operations teams, often contain extraneous data.
Before your logs leave your environment, ensure that you’ve filtered out any redundant data, and stay ahead of potentially costly log surges by sampling and imposing quotas where appropriate. Dropping redundant metadata, stripping null fields, and normalizing data (such as dates, times, IP addresses, and location information) for consistency prior to routing can have a significant impact on your log management overhead. Generating metrics from logs can also help you control log volumes while effectively tracking KPIs. Instead of storing every CDN or WAF log, for example, you may want to simply generate metrics from them for alerts and general performance monitoring, so you can still extract meaningful insights without incurring unnecessary costs.
Meanwhile, bugs, errors, and various unpredictable events triggered in the course of CI/CD can lead to unexpected surges in log volumes. By configuring rule-based quotas for your log sources, you can prevent surges from inundating your storage and causing cost overruns.
For example, say a DevOps team managing a payment service notices an uptick in log volume after rolling out a new feature to improve transaction validation. The surge includes redundant error messages, verbose debugging logs mistakenly enabled in production, and a surplus of user interaction logs offering little to no aid in troubleshooting. While some of these logs provide valuable insights, their sheer volume makes it difficult to pinpoint real issues and unnecessarily drives up storage and observability costs. To address this, the team takes several steps to reduce noise while preserving meaningful data:
With these adjustments, their log volume drops by 50 percent, allowing them to quickly pinpoint issues while significantly reducing their log storage and observability costs.
To help teams manage their log volumes, Datadog Observability Pipelines provides a range of out-of-the-box processing capabilities for filtering and sampling logs before they leave your environment, generating metrics from logs, and imposing rule-based quotas in order to control log volumes. This type of control over your log data can help you attain essential visibility while managing costs.
Once you’ve homed in on how you are collecting and processing log data, it’s crucial to ensure that you’re sending that data exactly (and only) where you need it. Organizations are collecting log data from more and more parts of their distributed systems and sending that data to a wide variety of endpoints, such as cloud storage, log management systems, and SIEM providers. In the midst of this complexity, following a tiered logging strategy and proactively routing your logs is essential to cost efficiency.
As a general rule, selectively route your log data at the earliest possible points in your data pipelines (ideally at the edge) in order to avoid unnecessary costs. Not all data demands storage in a premium log management platform. For example, CDN, load balancer, and VPC flow logs are typically high-volume and often essential to collect, but they are queried relatively infrequently. Other logs may only be used to support keyword searches or other basic aggregation queries, or stored strictly for compliance reasons.
To optimize costs, there are a few general guidelines to follow when it comes to where to send which of your logs:
Proactively routing logs can be a challenge when you’re managing multiple agents, collectors, or log forwarders. In addition to the processing capabilities covered in the previous section of this post, Observability Pipelines can help you orchestrate routing before your logs leave your on-prem or cloud environments, easily integrating with many popular downstream logging applications and storage environments. With Observability Pipelines, you can build, manage, and deploy pipelines in your own environment from Datadog’s SaaS control plane.
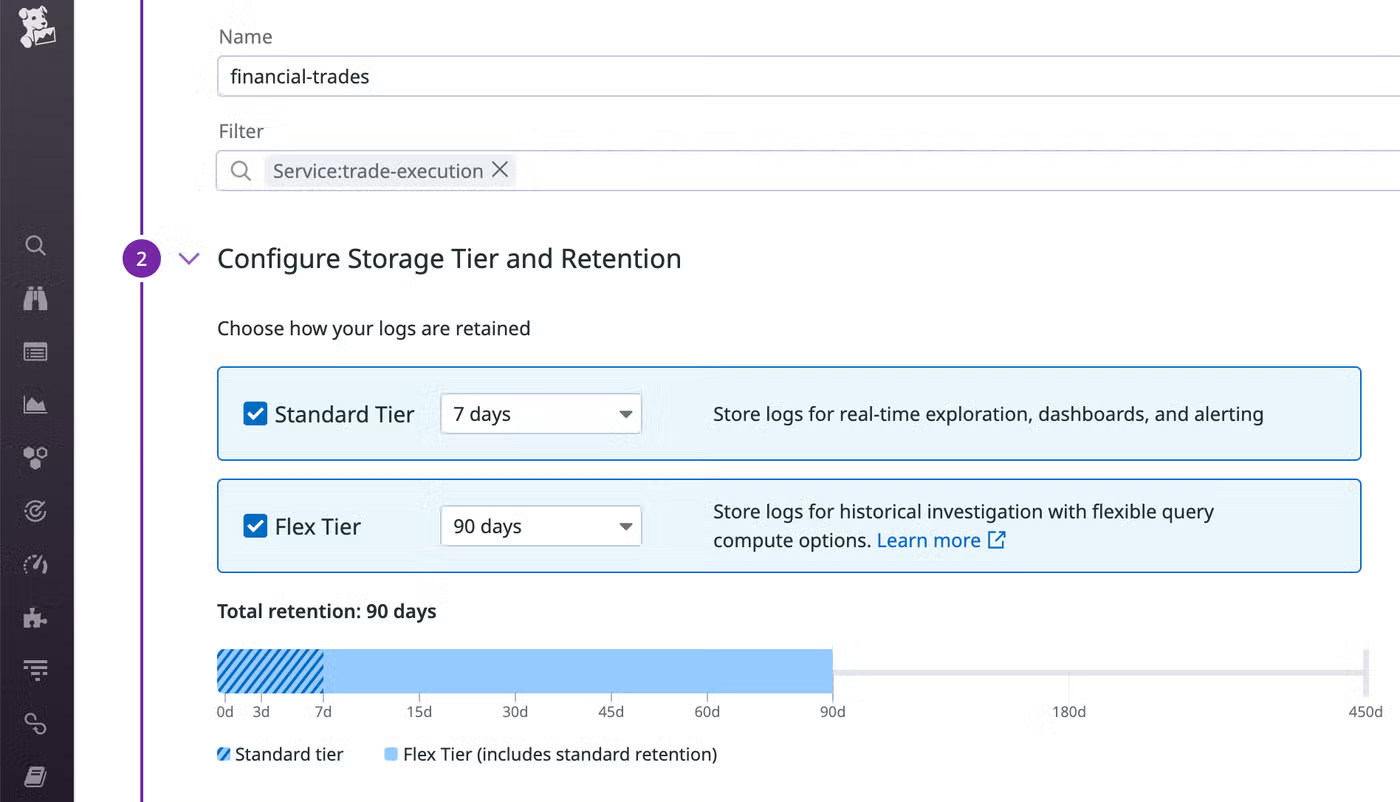
The configurability of different storage solutions is an important consideration when it comes to making routing decisions. Controlling how your logs are stored is not just a matter of pointing them to the right endpoints: When it comes to balancing costs with visibility, it’s important to fine-tune your storage to your logging use cases as much as possible. This means tailoring indexing and retention for each type of log you collect, on a case-by-case basis, in each of your log storage solutions.
For example, organizations in highly regulated industries like banking, healthcare, and insurance are often required to store certain types of high-volume logs long-term for auditing and security purposes. While simply sending these logs to cold storage may be the most economical option, rehydrating security and transaction logs every time you need to query them can be burdensome and cost precious time during incidents.
Datadog provides various solutions for reining in your log storage costs without the sacrifices to rapid queryability imposed by cold storage solutions: Logging Without Limits™ allows you to enrich, parse, and archive 100 percent of your logs while storing only what you need. And Flex Logs decouples log storage and querying costs, enabling teams to take more granular control over their log storage by maintaining logs in a rapidly queryable state for between 30 and 450 days. Datadog Log Management allows you to choose between Standard Indexing, archiving, and Flex Indexing—or dynamically combine these solutions—on a per-use-case basis.
In this post, we’ve outlined some key strategies for cost-effectively managing high-volume logs without compromising critical visibility. We’ve also shown how you can implement these recommendations using Datadog Observability Pipelines, Logging Without Limits, and Flex Logs.
If you’re looking to learn more about controlling log costs, you may want to check out our guides to reducing log volumes, strategically indexing your logs, and getting started with Logging Without Limits™. You can also sign up to receive our solution brief on modern log management or our webinar on controlling log volumes and costs while boosting visibility. And if you’re new to Datadog, you can sign up for a 14-day free trial.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。