





When you’re first building an AI agent, a single, monolithic system prompt is usually fine. You have a few instructions, maybe a tool definition or two, and everything lives in one readable file.
But as you start using them for production purposes, that format simply just breaks down. Teams start layering on safety policies, domain-specific rules, formatting requirements, and escalation behaviors. Suddenly, you have your entire agent’s control plane within a single instruction file which is exactly where the trouble starts.
This is a classic software engineering scaling problem. When you push every concern into a single file, you lose the ability to reason about the system. Collaboration becomes a nightmare, testing gets finicky, and a small change meant to improve one workflow can quietly break another.
At production scale, prompt maintainability becomes agent reliability.
We typically see three main failure modes when prompts grow beyond a certain size:
Templates are a good start, but they aren't enough. Production systems require deterministic builds, static validation, and CI/CD integration.
The solution here is to treat prompts like build artifacts as opposed to just static text.
Instead of maintaining one monolithic prompt file, you can author modular skill files. This allows you to reduce the scope of each file and encapsulate a specific behavior, which allows teams to separate concerns and iterate on components individually.
A top-level agent prompt template might look something like this:
# agents/sre_agent.prompt.md (prompt template file)

{% include "shared/safety.prompt.md" %}
{% include "shared/tool_usage.prompt.md" %}

You are an SRE triage agent operating in the {{ environment }} environment.

{% if allow_remediation %}
You may recommend remediation steps, but destructive actions require human approval.
{% else %}
You may inspect, summarize, and explain the issue, but do not recommend remediation actions.
{% endif %}

{% macro bullet_section(title, items) %}
## {{ title.rstrip() }}
{% for item in items %}
- {{ item.rstrip() }}
{% endfor %}
{% endmacro %}

{{ bullet_section("Required investigation steps", [
  "Inspect recent deployment events",
  "Check service metrics for latency or error-rate changes",
  "Review logs for repeated failure patterns"
]) }}
Plain text
Copied
This gives you the best of both worlds. The templating layer lets you compose shared instructions, inject environment-specific values, and make use of macros. But for the build system, every include is a dependency, and every variable is a requirement. The result is a deterministic, fully rendered artifact that you can test, audit, and diff before it ever reaches the model. We can then use a transpiler to resolve the template imports to generate a file that is ready to be ingested by an agent.
For example, if environment = production and allow_remediation = true, the transpiled artifact would look like this:
You are an SRE triage agent operating in the production environment.

You may recommend remediation steps, but destructive actions require human approval.

## Required investigation steps

- Inspect recent deployment events
- Check service metrics for latency or error-rate changes
- Review logs for repeated failure patterns
Plain text
Copied
A high-level transpilation pipeline would look something like this:

A production-grade transpiler should catch errors before runtime.
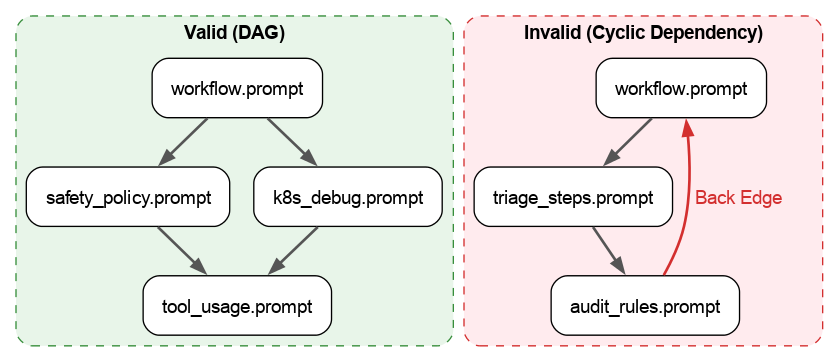
We should be running validation checks for missing imports, undefined variables, and circular dependencies during the build process. Dependency graphs are invaluable here, reinforcing the need for a solid template engine. If you treat each prompt fragment as a node in a directed graph, you can easily catch recursive imports that would otherwise cause a silent failure in production.
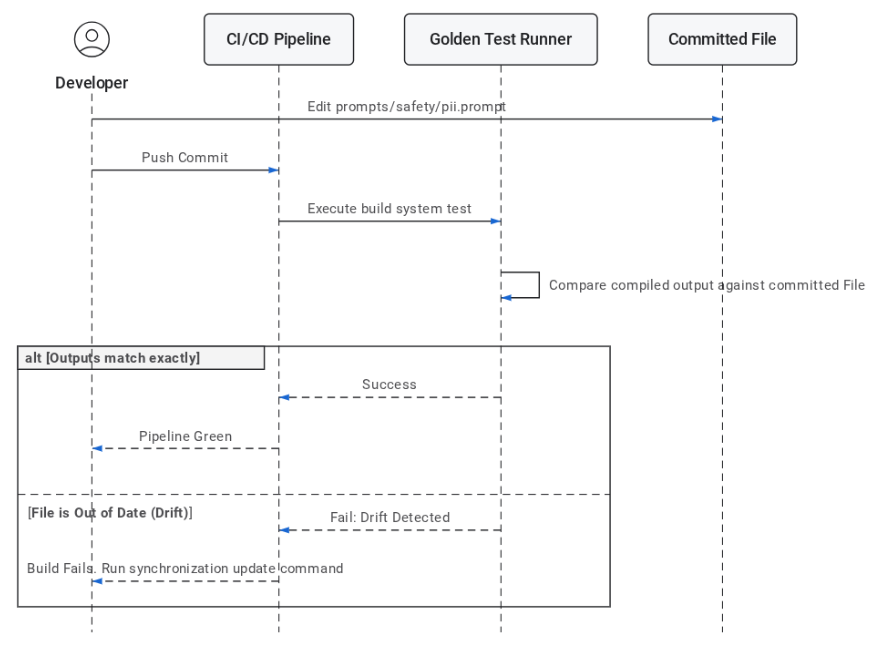
This also enables drift checking. You can set your CI pipelines to be able to regenerate the transpiled prompt from source (referred to as the golden file) and compare it against the currently committed artifact. If the outputs differ, the build fails. This ensures that the code in your repo is exactly what’s running in production, eliminating the gap between source files and deployed artifacts.
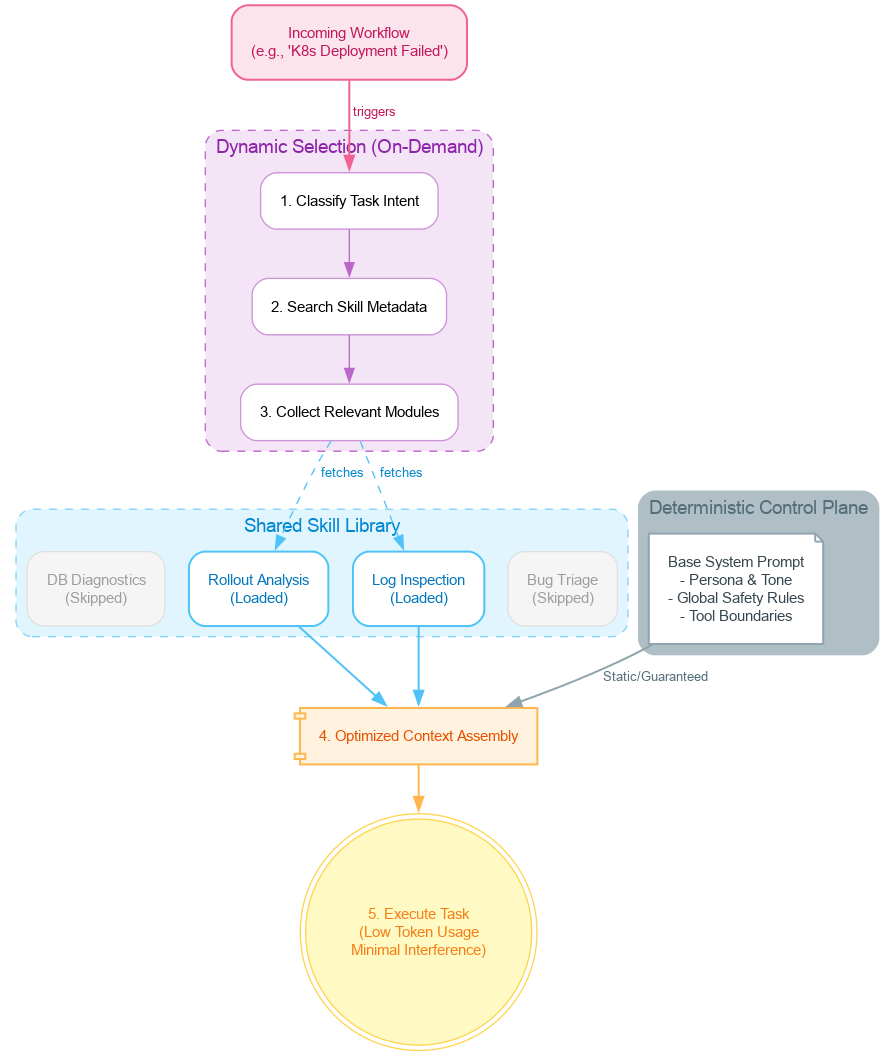
As your skill library of modular prompt fragments grows, you don't necessarily want every agent to load every skill every time. Doing so consumes tokens and introduces noise that can interfere with the agent's task-specific performance.
A better architectural pattern would be to leverage progressive disclosure. This is where we separate the stable control plane from task-specific context. The compiled base prompt should enforce non-negotiable behaviors like identity and safety boundaries. Then, at runtime, the agent can use a tool to dynamically retrieve only the specific skill modules required for the task at hand; this reduces context exhaustion and helps to keep the agent focused on its task.
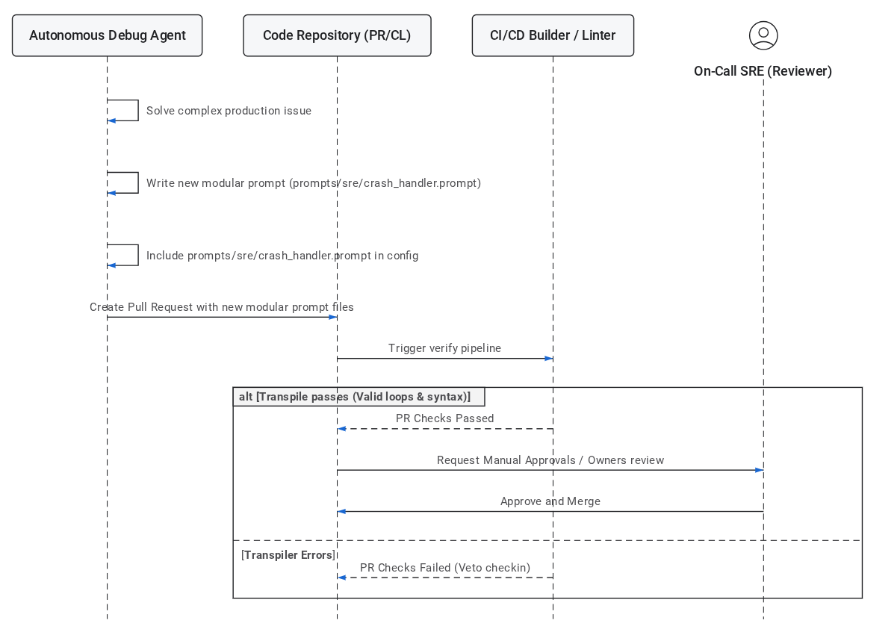
Once you have this modular system, you unlock a powerful workflow: agents can help maintain their own instruction layer, helping to create a self-sustaining agentic system. When an agent resolves a new type of incident, it could theoretically draft a new skill module, update the relevant imports, and open a pull request.
The agent isn't mutating its own instructions in real-time; it's proposing a code change. The transpiler then subjects that proposal to the same validation and review rigors as any other code change. A human reviewer can inspect the PR, run the evals, and merge the change.
A production prompt transpiler reframes prompt engineering as a build-system problem.
When we build modular skill files, we can resolve dependencies, validate imports, and enforce drift checks just as we do with our standard software infrastructure. Agents become capable of suggesting improvements to their own logic, provided those changes pass through our existing validation and review processes.
As AI agents become deeply integrated into critical workflows, their instruction layers need the same reliability standards we demand of our software. Prompts shouldn't just be edited, they should be built, validated, versioned, and deployed.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。