


Originally published on Towards AI.
10 experiments, 3 models, one honest verdict: the quality story is real, the speed story needs a disclaimer, and there’s a finding in the entropy data nobody talks about.
⏱ ~14 min read🔬 Deep Dive⚙️ LLM Inference🗜 Quantization🚀 Serving
When Google published TurboQuant at ICLR 2026, the headline was hard to ignore: compress your LLM’s key-value cache to 3 bits, keep quality intact, get up to 6× memory savings.
I built a 10-experiment evaluation pipeline, ran it across three models — Gemma-2B base, Gemma-2B-IT, and TinyLlama 1.1B Chat — and measured everything I could: factual accuracy, RAG retrieval quality, multi-task generation fidelity, throughput, memory footprint, layer sensitivity, and something most quantization write-ups skip entirely: what compression does to attention entropy.
Most KV-cache quantization schemes treat compression as a reconstruction problem: minimize mean squared error on cached vectors. TurboQuant is smarter than that. It targets the thing that actually matters for attention — inner-product preservation.
Each pair of consecutive vector coordinates gets converted to polar form (radius + angle). The radius stays in full float. The angle — which lives in a bounded, roughly uniform range after an optional random rotation — is quantized at low bitwidth. The rotation is the real trick: it spreads outlier energy so that scalar quantization on the angle isn’t wrecked by a few dominant values.
The reconstruction error from Stage 1 gets projected into a random subspace, and only the sign of each projection is stored — 1 bit per projection. The Johnson-Lindenstrauss lemma says random projections approximately preserve inner products. So this step specifically corrects for dot-product error that distorts attention scores, not just MSE. That distinction is what separates TurboQuant from naive quantizers.
Disclaimer: My implementation hooks into the model’s forward pass and compresses cached K and V tensors between decode steps using int8 containers with per-vector float16 scale factors. It is not a packed 3-bit kernel — it does not use fused CUDA or Triton. This distinction matters a lot for speed results and somewhat for memory results. I will be explicit about both throughout.
Ten experiments, two phases. All text evaluations used a fixed external encoder (sentence-transformers/all-MiniLM-L6-v2) separate from the tested models. Throughput used a fixed 80-step greedy decode benchmark with alternating load order to reduce warm/cold GPU bias.
Start with the synthetic bit-depth comparison — PolarQuant alone vs. the full TurboQuant-style path on attention MSE and KL divergence.

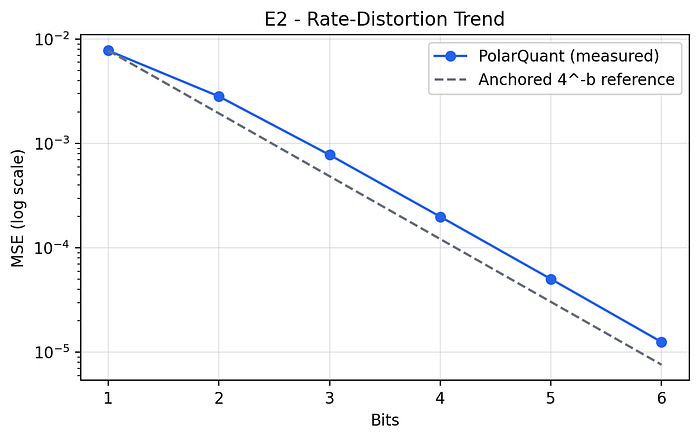
The MSE table shows that 2-bit is worse, but it doesn’t explain why. The attention entropy experiment does. Entropy measures how focused or diffuse the softmax distribution is — high entropy means the model is attending broadly, low entropy means it’s locked onto a few positions.
The key distinction is between random key distributions (noise-floor conditions) and structured key distributions — vectors with dominant directional clusters, which is closer to what real LLM attention heads actually produce.
At 2-bit compression, structured key distributions experience a 65% entropy collapse — the quantizer is actively reshaping the attention geometry in ways that cut off access to broader context. This is not just elevated MSE. It is the underreported reason why 2-bit compression quietly damages multi-hop reasoning, long-document synthesis, and complex RAG chains.
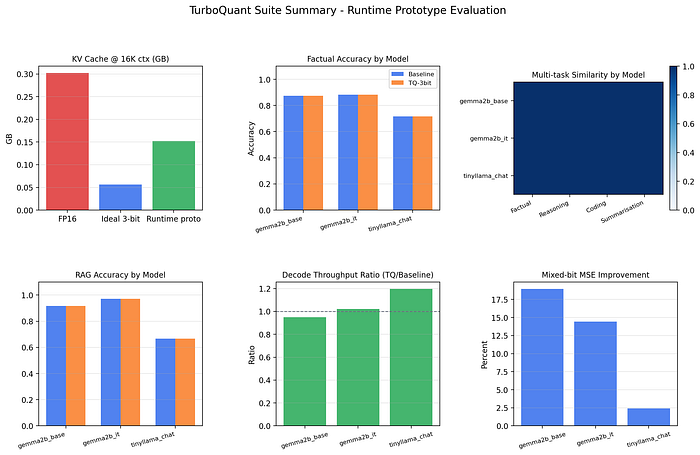
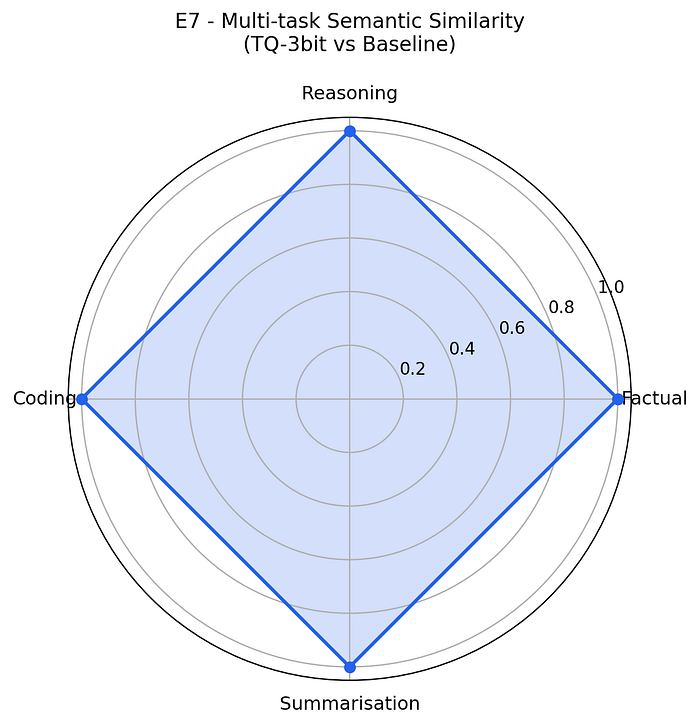
Multi-task semantic similarity (factual, reasoning, coding, summarization) between baseline and TQ-3bit generations: 1.0 across all categories and all three models.
For Gemma-2B (18 layers, MQA with 1 KV head per group, 256-dim heads), the idealized 3-bit target vs. what the int8 prototype actually stores:
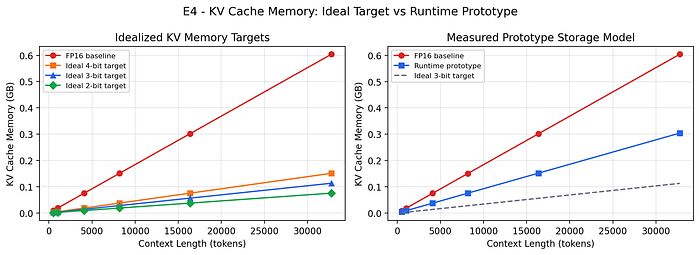
If someone tells you TurboQuant gives 5× memory savings, ask what storage backend they’re using. An int8 prototype gives ~2×. That’s still useful — it can extend context window or increase batch size on constrained hardware — but it’s a different product story. The ~5× headline requires truly packed sub-byte storage with custom memory layouts.
Throughput sweep: 80 fixed greedy decode steps, 5 measured trials, 2 alternating rounds, three prompt lengths.
The speed question is not “is TurboQuant fast?” It is “is your model’s bottleneck memory bandwidth or arithmetic?” Faster models like TinyLlama spend proportionally more time on cache I/O — compressing the cache loosens that bottleneck. Compute-heavy models like Gemma-2B are less responsive. Know your bottleneck before optimizing for it.
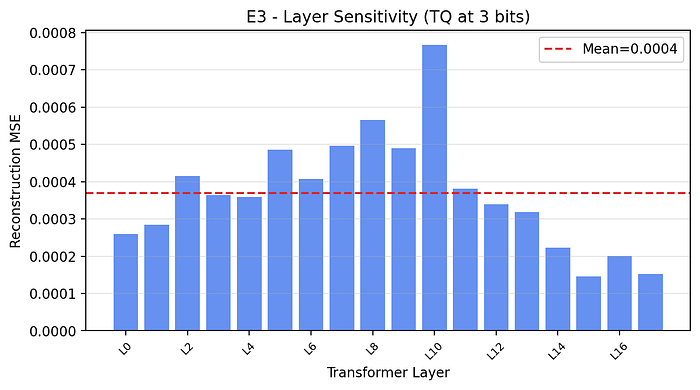
Layer sensitivity analysis showed that for both Gemma variants, compression sensitivity peaks in layers 7–10 — the middle of the stack. Uniform bit allocation is leaving quality on the table for free.
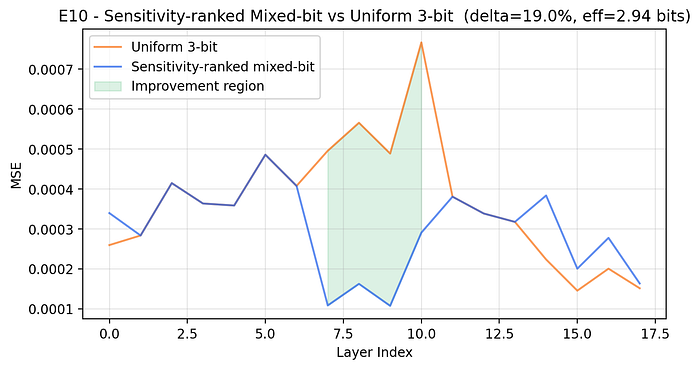
A sensitivity-ranked schedule — 4 bits for the top 25% most sensitive layers, 3 bits for the middle, 2 bits for the least sensitive — at ~2.94 effective bits:
Here’s what the scan looks like in practice:
def compute_layer_sensitivity(model, bits=3):
 """Single-pass sensitivity scan over key-projection layers."""
 sensitivity = {}
 for i, layer in enumerate(model.model.layers):
 W = layer.self_attn.k_proj.weight.data
 W_hat, _, _, _ = turboquant_apply(W, bits)
 mse = ((W - W_hat.to(W.dtype)) ** 2).mean().item()
 sensitivity[i] = mse
 return sensitivitydef build_mixed_bit_schedule(sensitivity, top_pct=0.25, bottom_pct=0.25):
 """Assign 4/3/2 bits by sensitivity rank."""
 ranked = sorted(sensitivity.items(), key=lambda x: x[1], reverse=True)
 n = len(ranked)
 schedule = {i: 3 for i in sensitivity}
 for idx, _ in ranked[:int(n * top_pct)]:
 schedule[idx] = 4 # most sensitive → more bits
 for idx, _ in ranked[-int(n * bottom_pct):]:
 schedule[idx] = 2 # least sensitive → fewer bits
 return schedule
One forward pass. Three lines of logic. ~19% MSE improvement on middle-weight models. If you’re building TurboQuant into an inference system, run this scan before defaulting to uniform bit allocation.
TurboQuant is not a free 5x win you can drop into production tomorrow. It is more interesting than that.
The experiments suggest a clear distinction between the algorithmic promise and the current engineering reality. On quality, the results are encouraging: 3-bit quantization held up well, and the mixed-bit schedule helped stabilize the fragile middle layers in Gemma-2B. On memory, the theoretical savings are real, but today’s PyTorch implementation is limited by int8 containers and the lack of packed sub-byte kernels. On speed, the story depends heavily on the model and runtime path.
The most useful takeaway is not simply that “lower bits are better.” It is that quantization changes attention geometry. The 2-bit runs did not just add harmless noise; they collapsed entropy in structured key distributions, which helps explain why context-sensitive tasks degrade so quickly under aggressive compression.
That makes the practical lesson fairly concrete: treat 3-bit quantization as the safer default, scan layers before choosing a uniform bitwidth, and reserve 2-bit compression for places where the model can actually tolerate it. Mixed-bit scheduling is likely to matter more in production than headline compression ratios.
The algorithm is credible, the quality findings are promising, and the deployment story will ultimately be decided by kernel support. The paper numbers are worth taking seriously, but not blindly. The real production opportunity begins when packed storage and fused attention kernels catch up with the algorithm.
Published via Towards AI
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。