惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

G
Google Developers Blog
F
Fortinet All Blogs
Microsoft Azure Blog
腾讯CDC
Vercel News
Vercel News
Recent Announcements
博客园 - Franky
小众软件
小众软件
freeCodeCamp Programming Tutorials: Python, JavaScript, Git & More
The Cloudflare Blog
宝玉的分享
宝玉的分享
I
InfoQ
博客园 - 聂微东
Jina AI
Jina AI
J
Java Code Geeks
V
V2EX
U
Unit 42
Stack Overflow Blog
Stack Overflow Blog
奇客Solidot–传递最新科技情报
奇客Solidot–传递最新科技情报
Cyber Security Advisories - MS-ISAC
阮一峰的网络日志
阮一峰的网络日志
L
LangChain Blog
T
The Blog of Author Tim Ferriss
量子位

Runpod Blog.

DeepSeek V4 in the wild, and how to run it on Runpod New Runpod datacenter now live: AP-IN-1 Track GPU spend across your team with Cost Centers The GPU supply supercycle is here. Here’s what AI builders need to know. Community Spotlight: One-click AI image and video generation on Runpod with SwarmUI | Runpod Blog Community Spotlight: LoRA Pilot Data Prep to Inference Introducing the Runpod Assistant: Manage Your Cloud GPU Resources with Natural Language OpenAI's Parameter Golf: Train the Best Language Model That Fits in 16MB on Runpod LLM inference optimization: techniques that actually reduce latency and cost Pruna P-Video and Vidu Q3 public endpoints now available on Runpod Runpod brand spelling guide Quickstart - Runpod Documentation The AI market looks nothing like the narrative Training StyleGAN3 with Vision-Aided GAN on Runpod KoboldAI – The Other Roleplay Front End, And Why You May Want to Use It How to Connect Cursor to LLM Pods on Runpod for Seamless AI Dev Community Spotlight: How AnonAI Scaled Its Private Chatbot Platform with Runpod Prompt Scheduling with Disco Diffusion on Runpod Runpod's Latest Innovation: Dockerless CLI for Streamlined AI Development Run Your Own AI from Your iPhone Using Runpod Introducing Flash: Run GPU workloads on Runpod Serverless: No Docker required Use Claude Code with your own model on Runpod: No Anthropic account required Avoid Errors by Selecting the Proper Resources for Your Pod What hackers built on Runpod at TreeHacks 2026 Easily Back Up and Restore Your Pod with Cloud Sync + Backblaze B2 The Complete Guide to GPU Requirements for LLM Fine-Tuning AI Guides, Tutorials & GPU Infrastructure Insights | Runpod Your first Claude Code project within Runpod: a complete setup guide 10 billion Serverless requests and counting Building for resilience: Runpod’s response to the AWS us-east-1 outage
Run vLLM on Runpod Serverless: Deploy Open Source LLMs in...
Shaamil Karim · 2026-02-14 · via Runpod Blog.

In this blog you’ll learn:

  1. When to choose between closed source LLMs like ChatGPT and open source LLMs like Llama-7b
  2. How to deploy an open source LLM with vLLM

If you're not familiar, vLLM is a powerful LLM inference engine that boosts performance (up to 24x) - if you'd like to learn more about how vLLM works, check out our blog on vLLM and PagedAttention.

Choosing Between Closed Source and Open Source LLMs

When deciding between a closed source LLM like OpenAI's ChatGPT API and a open source LLM like Meta’s Llama-7b, it's crucial to consider cost efficiency, performance, and data security. Standard models are convenient and powerful, but open source LLMs offer tailored performance, cost savings, and enhanced data privacy.

Open source models can be fine-tuned for specific applications, ensuring accuracy in niche tasks. While the initial costs might be higher, ongoing expenses can be lower than standard APIs, especially for high-volume use cases. These models also provide greater control over data, which is essential for sensitive information, and offer scalability and adaptability to meet evolving needs. Here’s a table to help you understand the differences better:

Criteria Open Source LLMs Closed Source LLM APIs
Tailored Solutions Domain-specific General-purpose capabilities
Cost Lower long-term costs Lower short-term costs
Data Privacy Greater control Limited control
Scalability Flexible and adaptable Fixed
Performance Superior for specific tasks Robust general performance

Now that we’ve established why open source LLMs could be the right fit for your use case, let’s explore a popular open source LLM inference engine that will help run your LLM much faster and cheaper.

What is vLLM and why should you use it?

vLLM is a blazingly fast LLM inference engine that lets you run open source models at 24x higher throughput than other open source engines.

vLLM achieves this performance by utilizing a memory allocation algorithm called PagedAttention. For a deeper understanding of how PagedAttention works, check out our blog on vLLM.

Here are the key reasons why you should use vLLM:

  • Performance: vLLM achieves 24x higher throughput than HuggingFace Transformers (HF) and 3.5x higher throughput than HuggingFace Text Generation Inference (TGI).
  • Compatibility: vLLM supports thousands of LLMs and an ever-growing list of transformer architectures. vLLM is also GPU agnostic, working with NVIDIA and AMD GPUs, making it compatible with any GPU workload.
  • Developer ecosystem: vLLM has a thriving community of 350+ contributors who constantly work to improve its performance, compatibility, and ease of use. Typically within a few days of a new breakthrough open source model being released, it is vLLM compatible.
  • Ease of use: vLLM is easy to install and get started with.

Now let's dive into how you can start running vLLM in less than a few minutes.

How to deploy your model with vLLM on Runpod Serverless

Follow the step-by-step guide below with screenshots and video walkthrough at the end to deploy your open source LLM with vLLM in less than a few minutes.

Pre-requisites:

  1. Create a Runpod account. Heads up, you'll need to load your account with funds to get started.
  2. Pick your Hugging Face model and have your Hugging Face API access token ready if needed.

Create a Runpod Account

Step-by-step Guide:

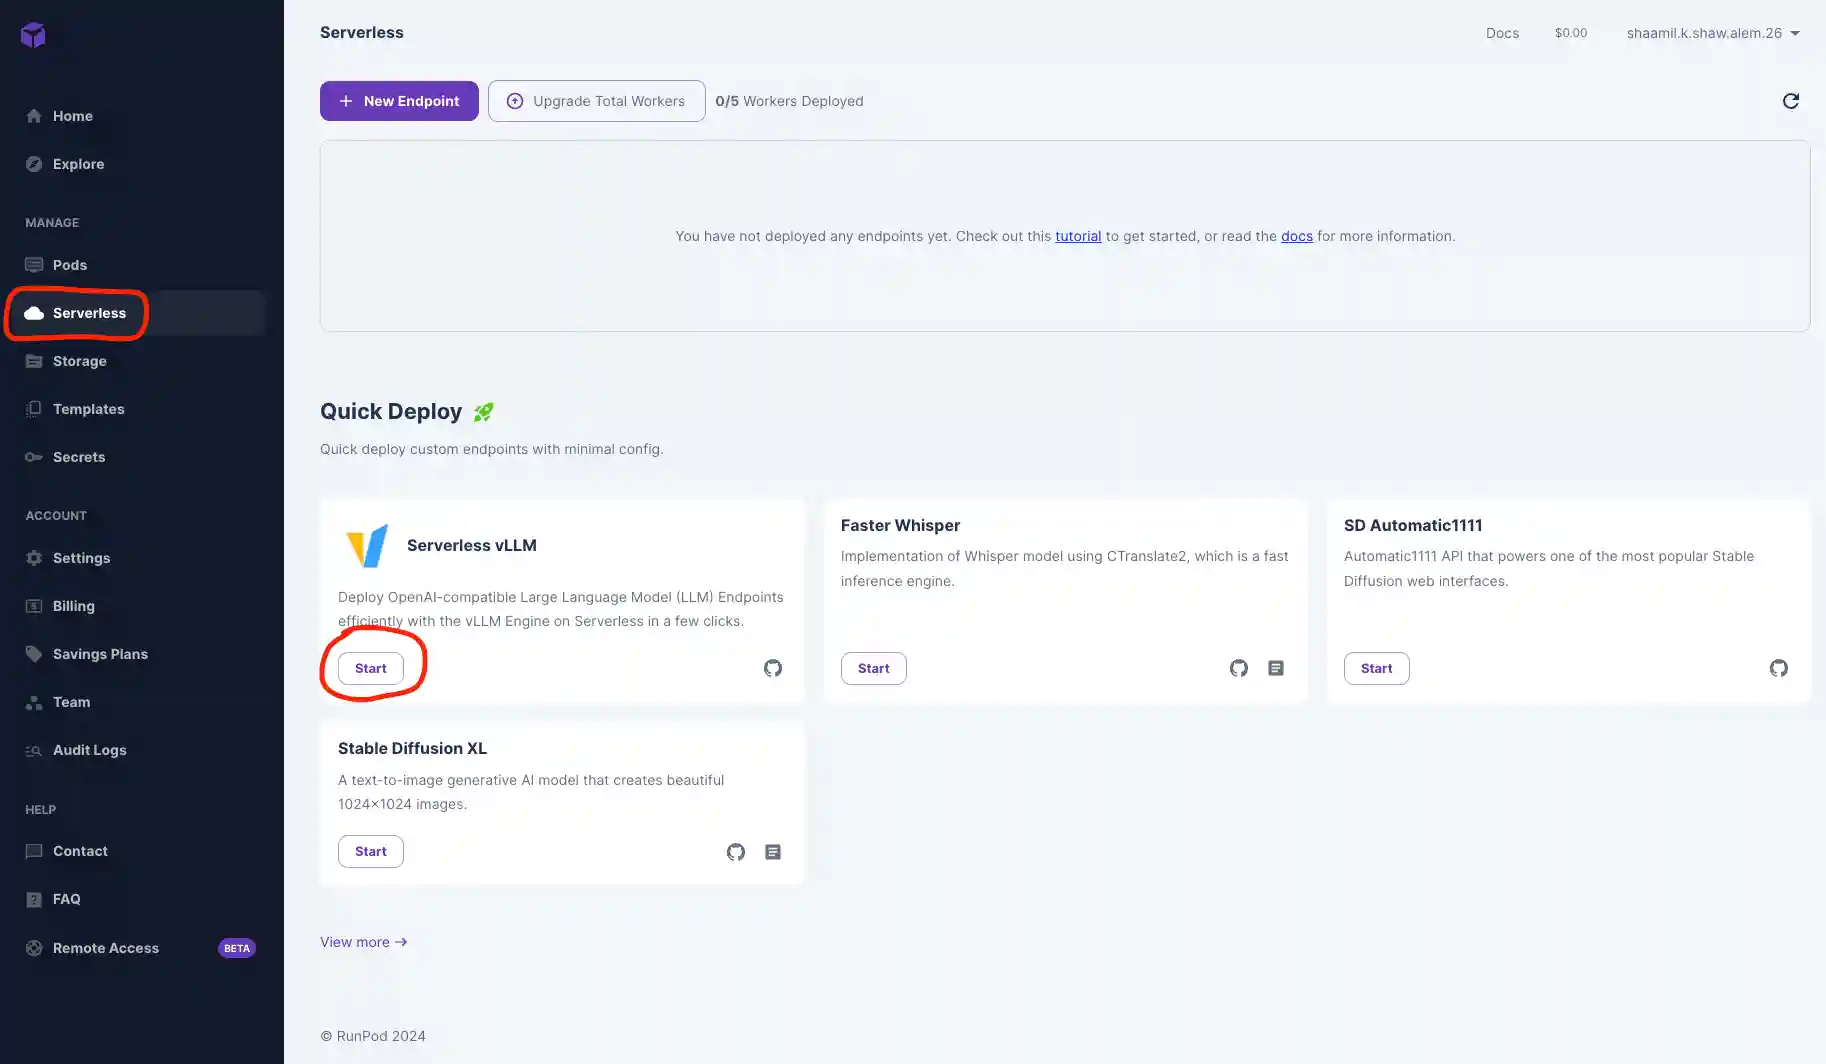
  1. Navigate to the Serverless tab in your Runpod console and hit the Start button on the Serverless vLLM card under Quick Deploy.

Runpod console Serverless page with Quick Deploy cards and the Serverless vLLM Start button circled

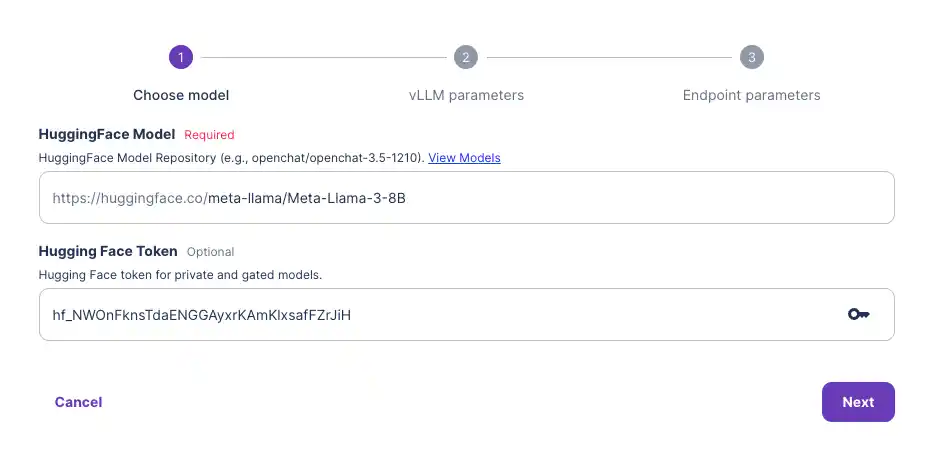
  1. Input your Hugging Face model along with the access token that you can get from your Hugging Face account.

Serverless vLLM setup step 1 with Hugging Face model field set to meta-llama/Meta-Llama-3-8B and token input

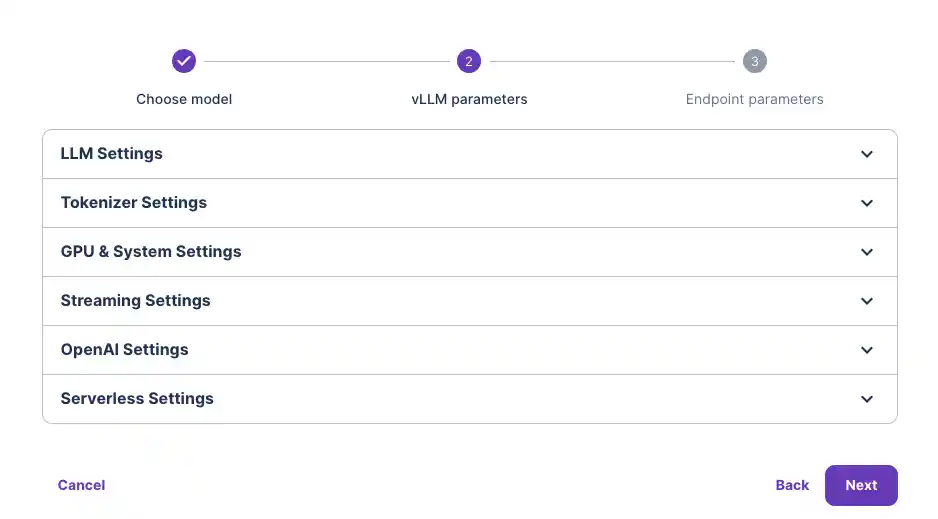
  1. You are given the option to customize your vLLM model settings. For most models, this is not required to get them running out of the box. But it may be required for your model if you're using a quantized version like GPTQ, for example, in which case you would need to specify the quantization type in the “Quantization” drop-down input.

vLLM endpoint setup step 2 with collapsed LLM, tokenizer, GPU, streaming, OpenAI, and serverless settings

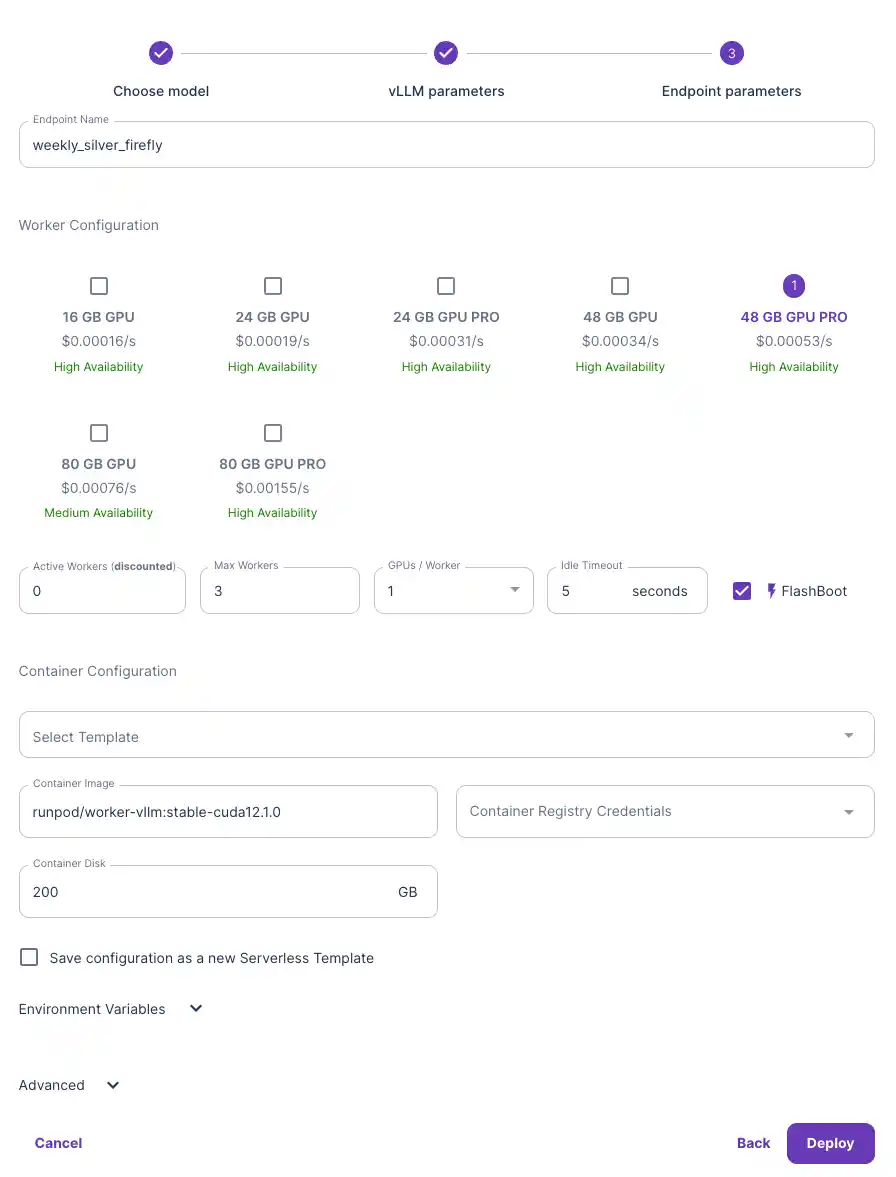
  1. Select the GPU type you would like to use. For a guide to selecting the right GPU VRAM for your LLM, checkout our blog: Understanding VRAM and how Much Your LLM Needs. For now, 48 GB should do fine for my Llama3-8b model. Now deploy!

Endpoint parameters form with 48 GB GPU PRO selected, worker counts, and Runpod/worker-vLLM container image

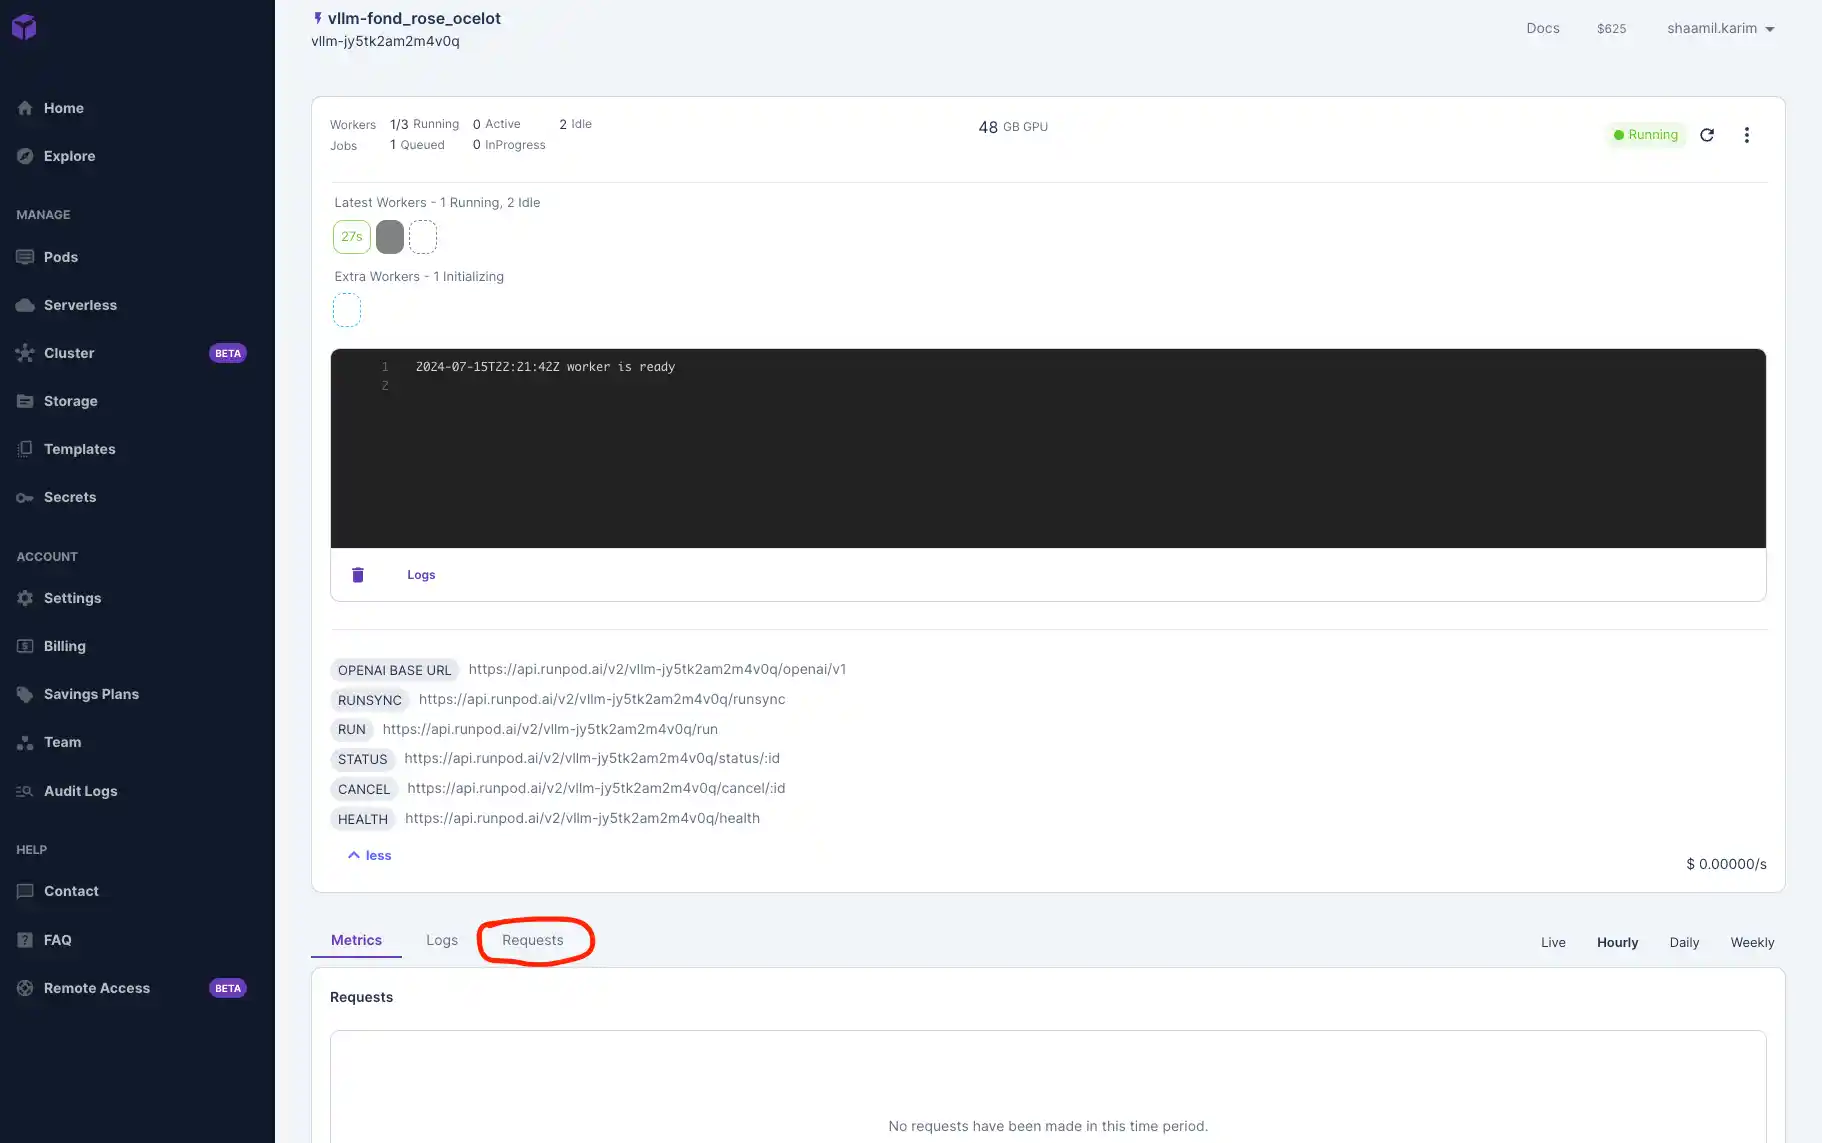
  1. Now that you’ve deployed your model, let’s navigate to the “Requests” tab and test that our model is working.

Runpod vLLM endpoint detail page with worker status, API endpoint URLs, and the Requests tab circled

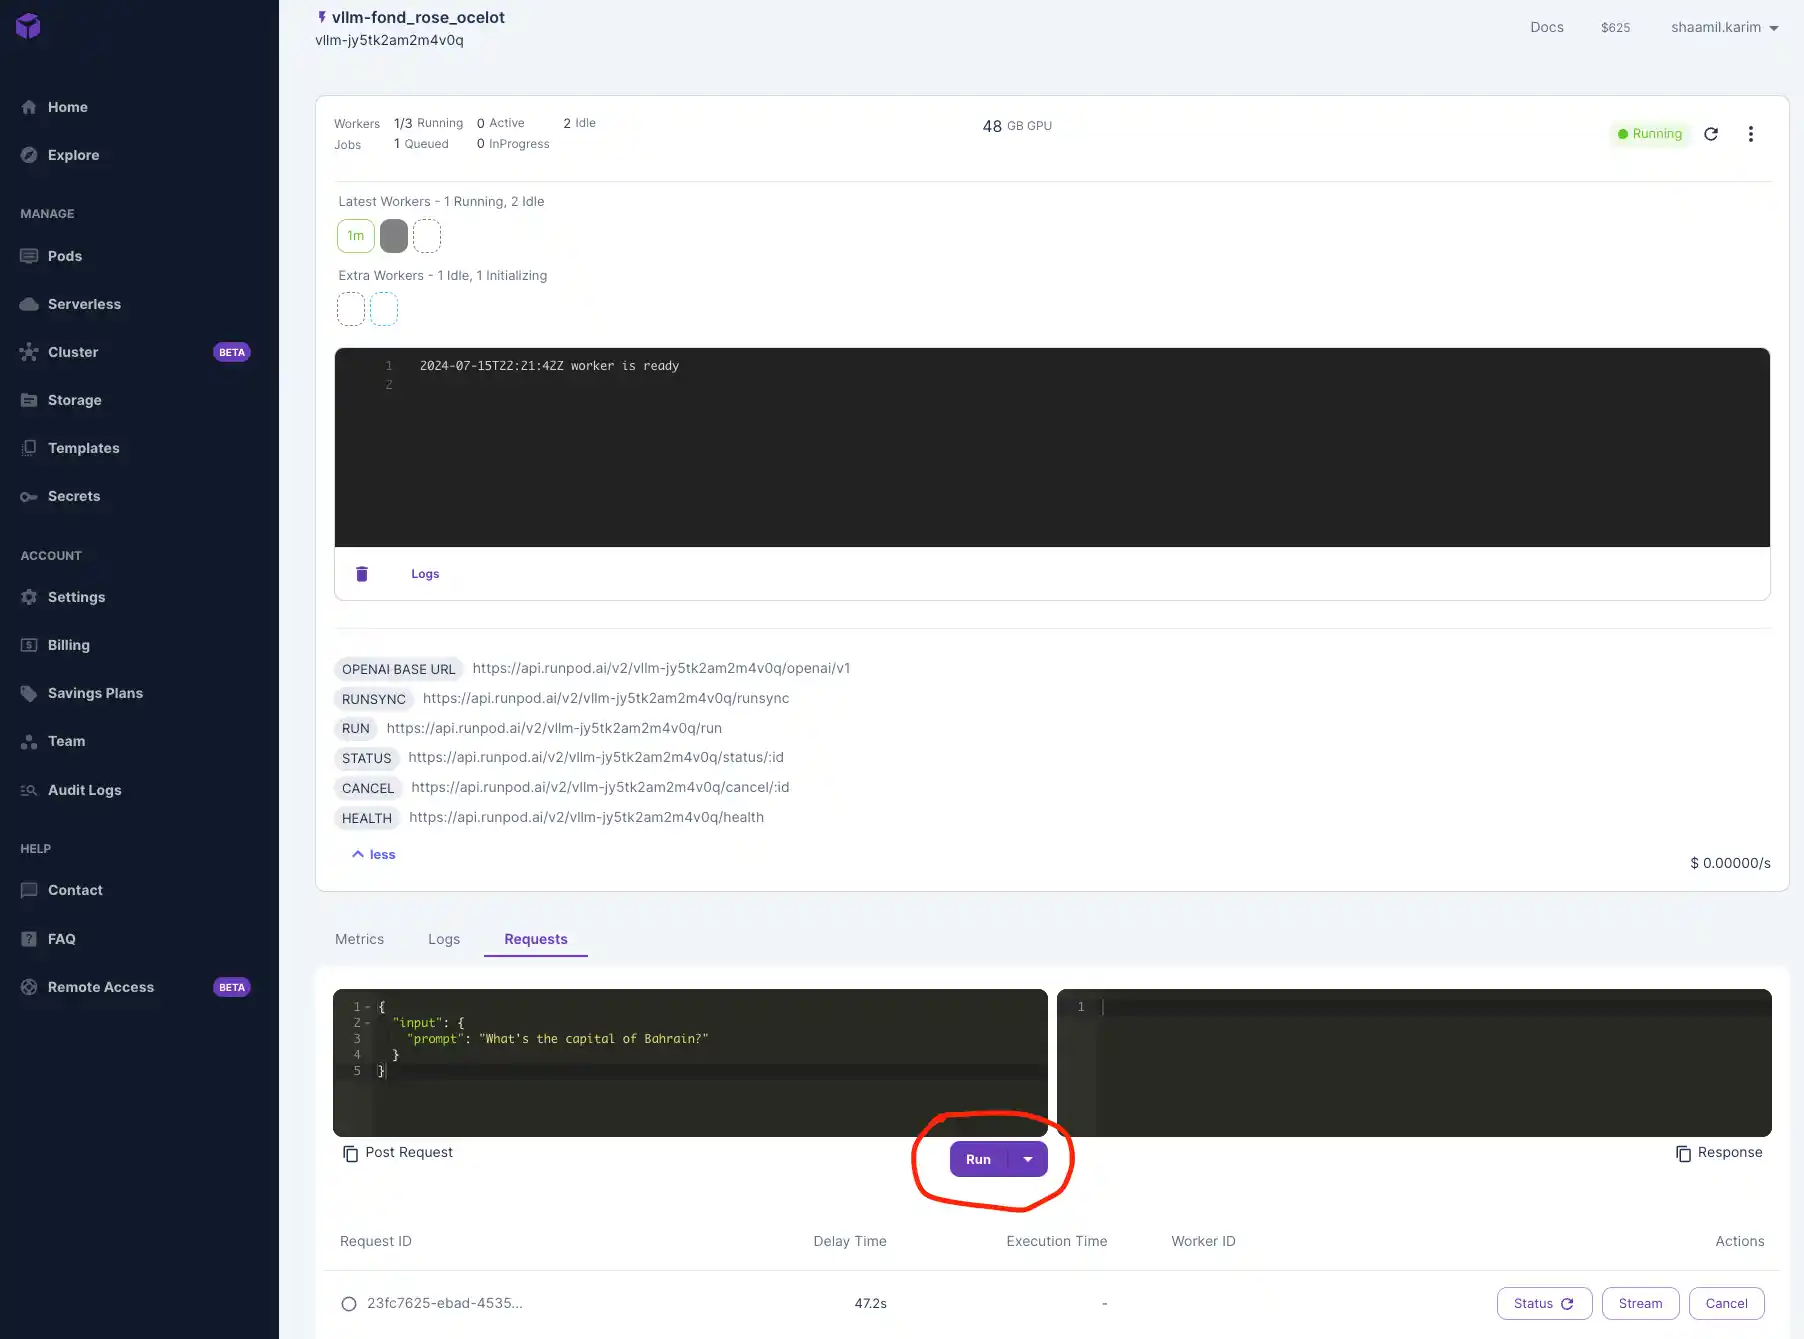
  1. Use the placeholder prompt or input a custom one and hit Run!

Endpoint Requests tab with a sample JSON prompt asking the capital of Bahrain and the Run button circled

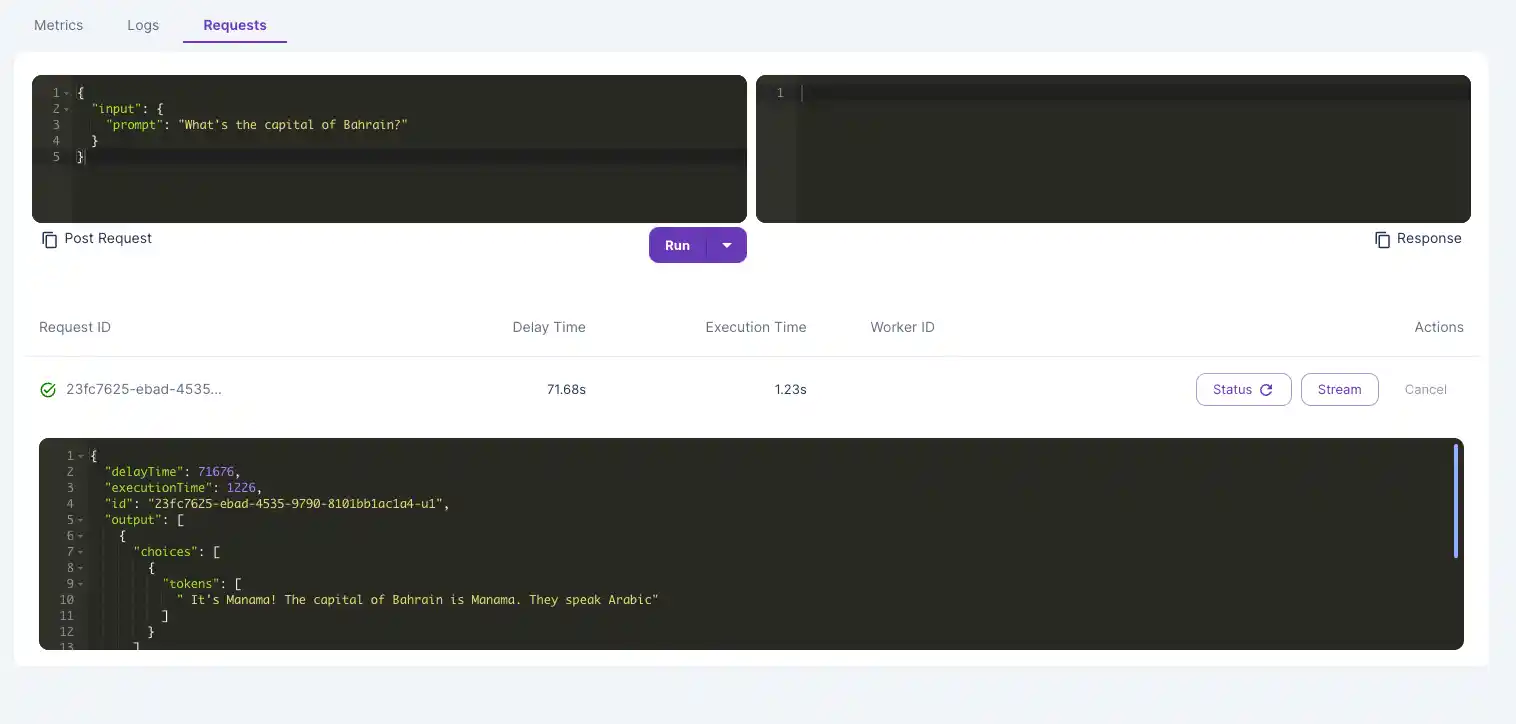
  1. After your model is done running, you’ll see your outputs below the Run button.

Completed endpoint request with JSON output answering that Manama is the capital of Bahrain

Video guide:

Troubleshooting

When sending a request to your LLM for the first time, your endpoint needs to download the model and load the weights. If the output status remains "in queue" for more than 5-10 minutes, read below!

  • Check the logs to pinpoint the exact error. Make sure you didn't pick a VRAM that was too small. You can estimate the amount VRAM you'll need by using an estimator tool.
  • If your model is gated (ex. Llama), first make sure you have access, then paste your access token from your hugging face profile settings when creating your endpoint.

Conclusion

To recap, open source LLMs boost performance through fine-tuning for specific applications, reduce inference costs, and maintain control over your data. To run your open source LLM, we recommend using vLLM - an inference engine that's highly-compatible with thousands of LLMs and increases throughput by up to 24x vs. other engines.

Hopefully by now, you should have a stronger grasp of when you should use closed source vs open source models and how to run your own open source models with vLLM on Runpod.

Deploy vLLM on Runpod Serverless

Author profile: Shaamil Karim