






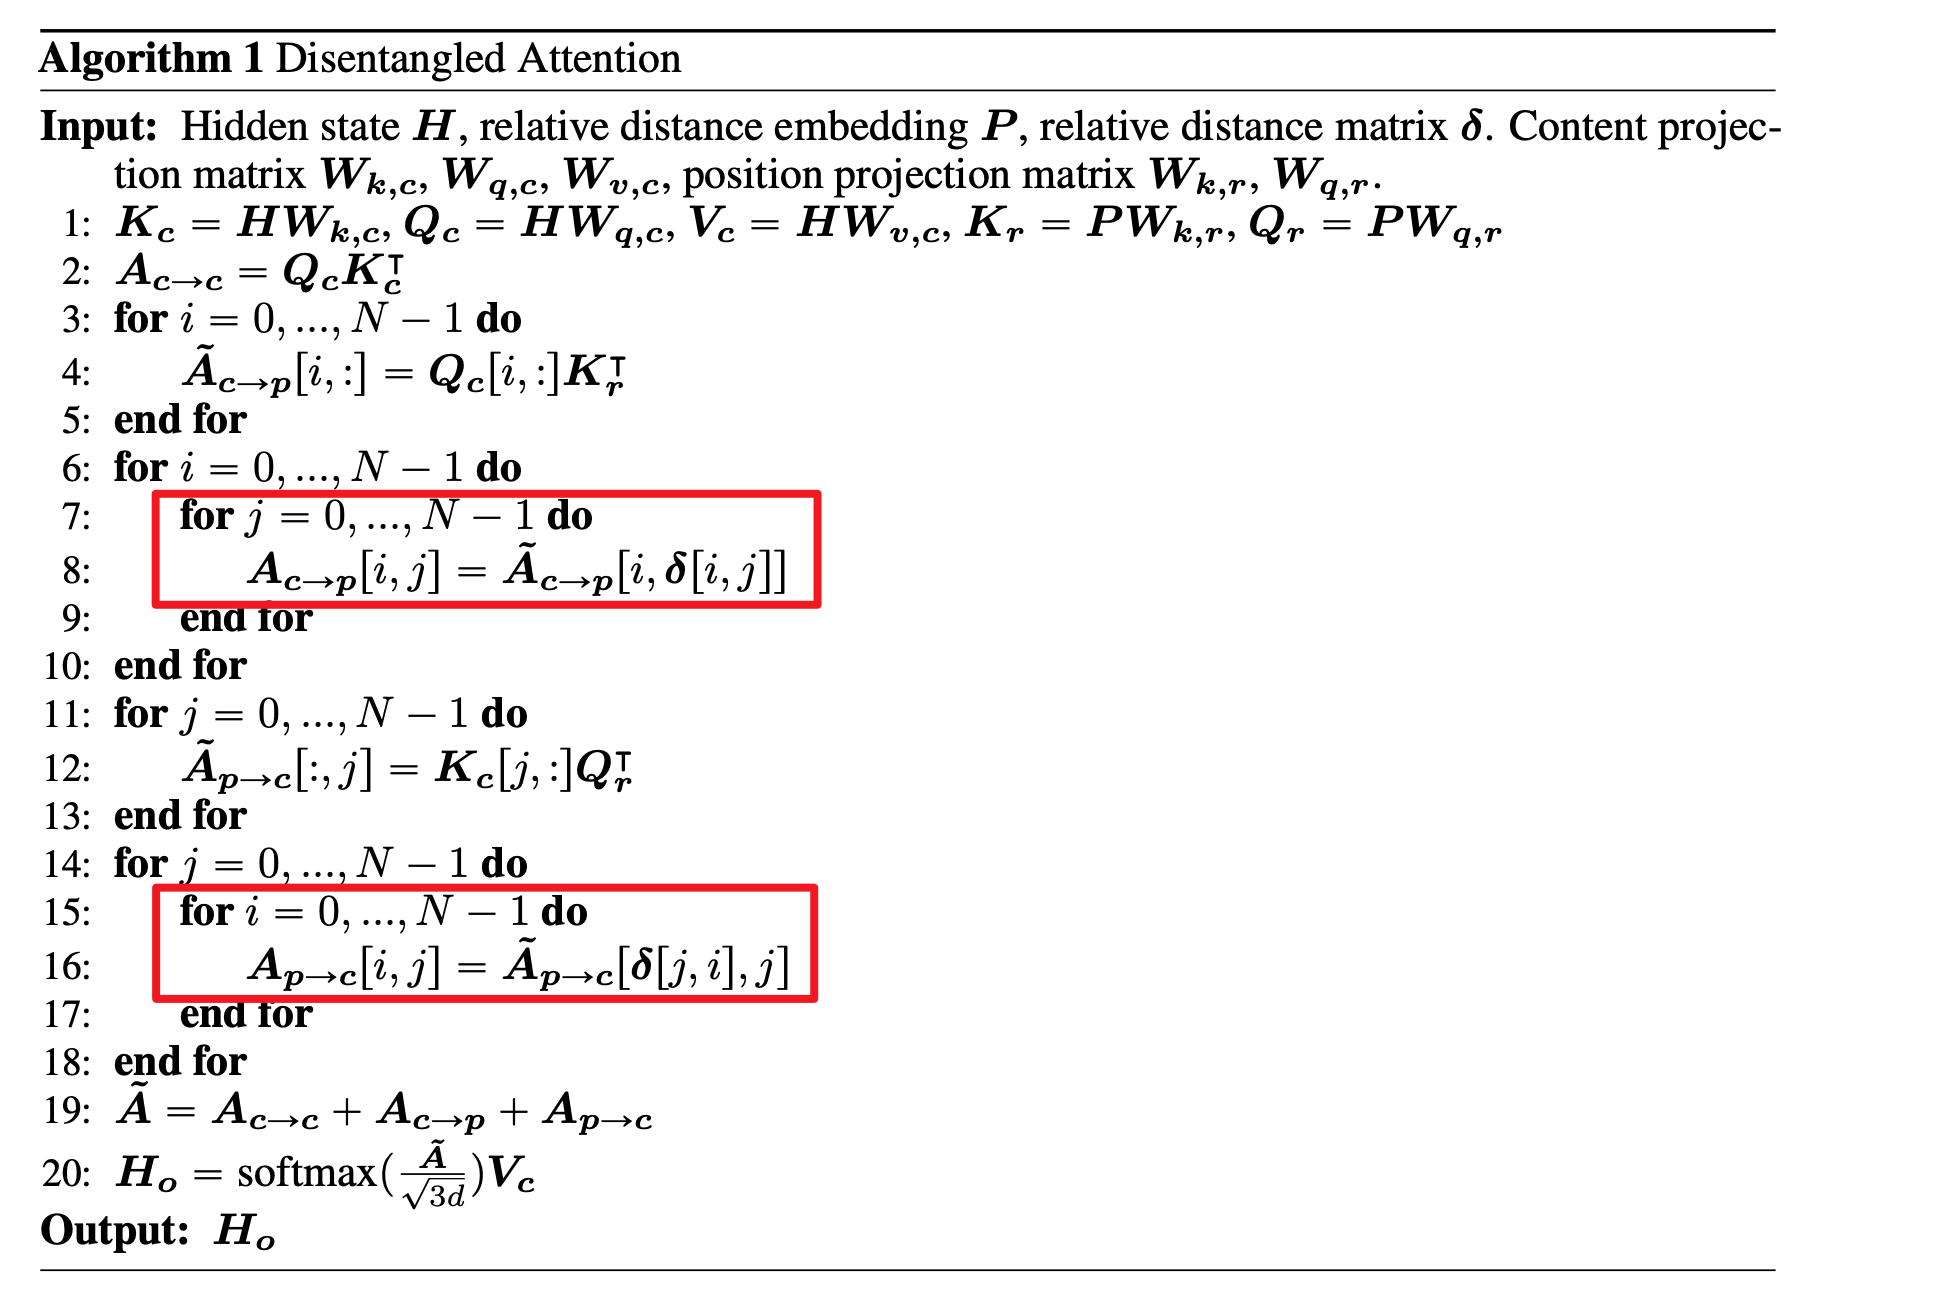
参考原 bert 参数,A100 机器上跑一轮得3个小时,算力是在顶不住,放弃了。 所以就只用 paddle 实现一下 DeBERTa,跑通 demo 锻炼下编码能力,过程中主要是 disentangled attention 实现起来有点复杂。
class="highlight"> 可以逐行读入,代码中自己设置随机 class="highlight"> 逐行读入:DataLoader提供了IterableDataset 自己写随机逻辑:感谢神秘网友的答案 DeBERTa 实现起来比较复杂的两个步骤 pytorch 中有对应的 gather 接口可以简单实现,但 paddle 的 gather 函数实现原理不同,paddle 中的 index 只能是一个一维函数,重定向 index 时无法参考其他维度的值,这样实现起来就更复杂一些。详细对比 绝对位置编码:attention中引入了相对位置编码,除此之外,mlm 预测时还引入了绝对位置编码,缺一不可。 样本扰动:传统机器学习实验时可以添加输入扰动提升模型鲁棒性,但 nlp 中 word太多、参数量太大(个人觉得主要还是 word多的原因)导致扰动的试验效果不稳定,原文发现在 layer normalized 之后的 embedding 上添加扰动,对提升扰动训练的稳定性很有帮助。1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
def _process_qkv(self, x):
x = paddle.reshape(x = x, shape = [0, 0, self.nhead, self.dim_head])
x = paddle.transpose(x = x, perm = [0, 2, 1, 3])
return x
def MultiHeadAttention(self, input, p, ptq):
qr = self._process_qkv(self.wqr(p))
kr = self._process_qkv(self.wkr(p))
qc = self._process_qkv(self.wqc(input))
kc = self._process_qkv(self.wkc(input))
vc = self._process_qkv(self.wvc(input))
qc_kr = paddle.matmul(qc, paddle.transpose(x = kr, perm = [0, 1, 3, 2]))
qc_kr_ = []
for i in range(self.max_len):
qc_kr_.append(paddle.gather(qc_kr[:, :, i, :], axis = 2, index = ptq[i, :]))
qc_kr = paddle.to_tensor(qc_kr_)
qc_kr = paddle.transpose(qc_kr, perm = [1, 2, 0, 3])
kc_qr = paddle.matmul(kc, paddle.transpose(x = qr, perm = [0, 1, 3, 2]))
kc_qr = paddle.transpose(kc_qr, perm = [0, 1, 3, 2])
kc_qr_ = []
ptk = paddle.transpose(x = ptq, perm = [1, 0])
for i in range(self.max_len):
kc_qr_.append(paddle.gather(kc_qr[:, :, :, i], axis = 2, index = ptk[:, i]))
kc_qr = paddle.to_tensor(kc_qr_)
kc_qr = paddle.transpose(kc_qr, perm = [1, 2, 0, 3])
weight = paddle.matmul(qc, paddle.transpose(x = kc, perm = [0, 1, 3, 2])) + qc_kr + kc_qr
val = paddle.matmul(F.softmax(weight * ((self.dim_head*3)**0.5)), vc)
val = paddle.transpose(x = val, perm = [0, 2, 1, 3])
val = paddle.reshape(x = val, shape = [0, 0, self.d_model])
return val
其他
数据集过大
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
def __iter__(self):
azip = zipfile.ZipFile(self.intpus)
self.cache = []
self.cache_cnt = 10000 # 缓存池大小
for fi in azip.namelist():
if fi.endswith('/'): continue
for line in azip.open(fi):
line = json.loads(line.decode("utf-8", "ignore"))
text = line['title'].strip('\n') + ' ' + line['text'].strip('\n')
self.cache.append(text)
if len(self.cache) > self.cache_cnt:
text = random.choice(self.cache)
self.cache.remove(text)
idx, mask_token, mask_idx = self.__process__(text)
yield idx, mask_token, mask_idx
while len(self.cache) > 0:
text = random.choice(self.cache)
self.cache.remove(text)
idx, mask_token, mask_idx = self.__process__(text)
yield idx, mask_token, mask_idx
gather 问题
其他优化
Trending Tags
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。