










Based on previous knowledge on fast cross-entropy, realizing it by triton doesn’t spend too much.
There are only 1e-7 difference between Pytorch and my Triton kernel, But the speed is significantly lower.
Getting advise on gpumode discord group, I can read how it realized in other great Triton kernel repository.
Liger-Kernel is the best option, but the speed is still lower than Pytorch, one result of them is 3053.16ms vs 0.04ms, even it save a lot of memmory, result is 0.51 vs 1.25
Attorch is another Triton kernel repository, withou any adobt, there aren’t much difference among My previous Triton kernel, Liger-Kernel and Attorch.
Pytorch is 1000x faster than Triton kernel which I have ever tried, it’s unreasonable. There should be another reason except core kernel code, but I cannot find it.
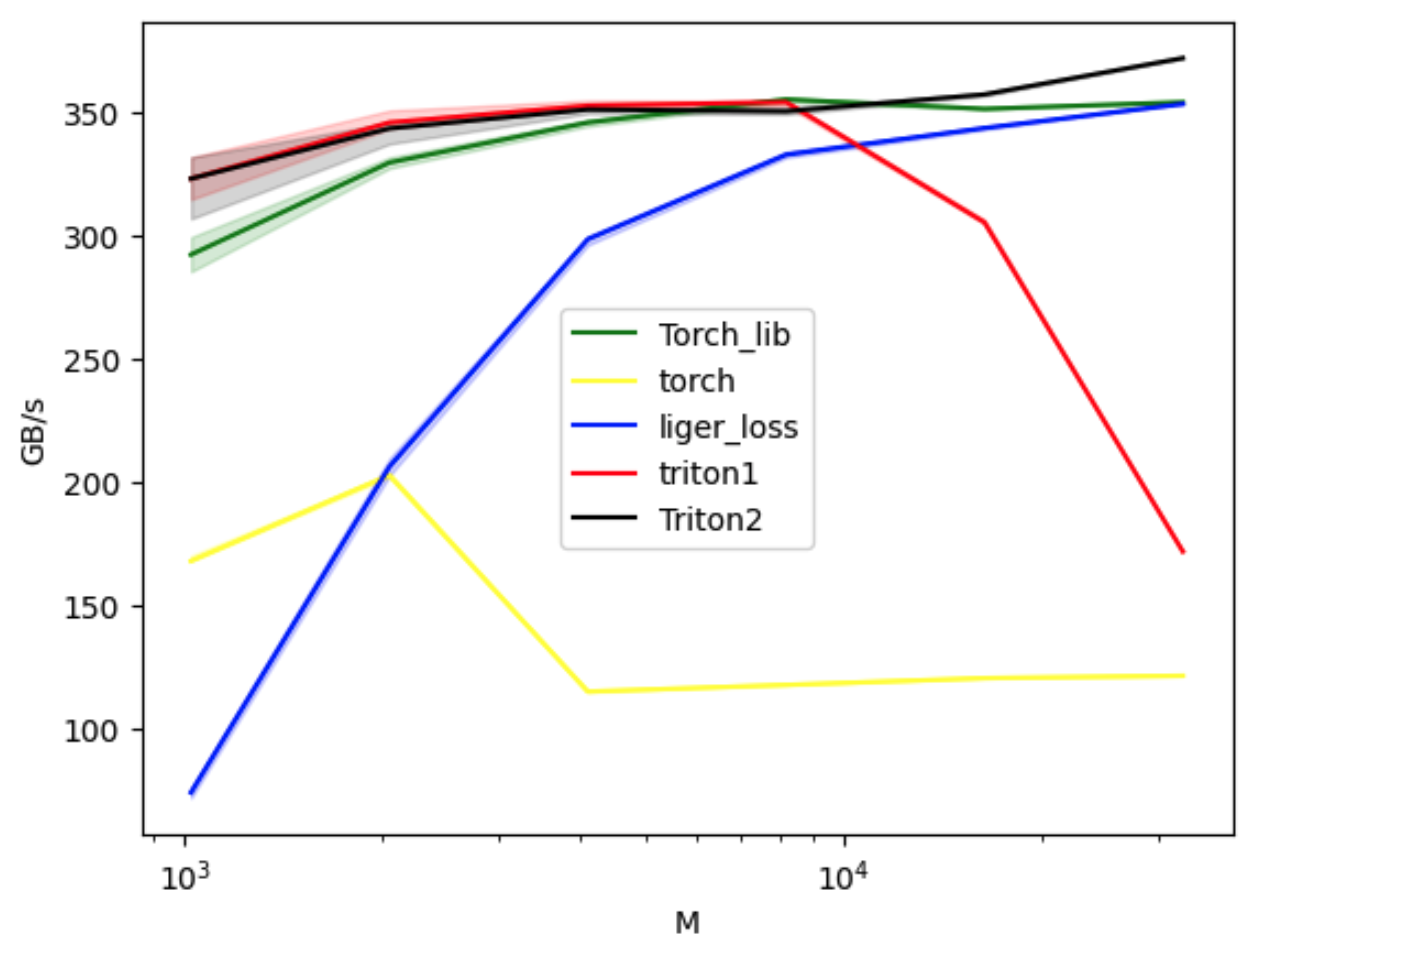
With help of friend in gpumode discord server, I found the environment variable is the root reason of self-made triton kernel. After realise the backward, the result as below picture show:
code:
@triton.jit
def loss_kernel(input_ptr,
                target_ptr,
                output_ptr,
                M, N,
                BLOCK_SIZE_N: tl.constexpr,
               ):
    pid_m = tl.program_id(0)
    input_ptr += pid_m * N
    target_ptr += pid_m
    output_ptr += pid_m
    offsets_cols = tl.arange(0, BLOCK_SIZE_N)

    target = tl.load(target_ptr)
    max_val = -float("inf")
    sumexp = 0.0
    allcurx = 0.0

    for index in tl.range(0, N, BLOCK_SIZE_N):
        offsets_input = (offsets_cols + index)
        mask_input = (offsets_cols + index) < N
        input_val = tl.load(input_ptr + offsets_input, mask=mask_input, other = -float("inf"))

        if index == 0:
            new_max_val = tl.max(input_val)
        else:
            new_max_val = tl.maximum(max_val, tl.max(input_val))

        sumexp /= tl.exp(new_max_val)
        sumexp *= tl.exp(max_val)
        sumexp += tl.sum(tl.exp(input_val - new_max_val))
        max_val = new_max_val

        if (target >= index) and (target < index + BLOCK_SIZE_N):
            curx = tl.load(input_ptr + target)
            allcurx += curx
    for index in tl.range(0, N, BLOCK_SIZE_N):
        offsets_input = (offsets_cols + index)
        mask_input = (offsets_cols + index) < N
        input_val = tl.load(input_ptr + offsets_input, mask=mask_input, other = -float("inf"))
        target_1d = (offsets_cols + index)
        grad = tl.div_rn(tl.exp(input_val - max_val), sumexp) - tl.where(target_1d == target, 1, 0)
        tl.store(input_ptr + offsets_input, grad, mask = mask_input)
    output = tl.log(sumexp) + max_val - allcurx
    tl.store(output_ptr, output)

def triton_loss(input: torch.Tensor, target: torch.Tensor, bm = 1, bn = 256):
    output = torch.empty(target.shape, dtype = torch.float32, device = input.device)
    grid_loss = (input.shape[0], )
    loss_kernel[grid_loss](input, target, output, M = input.shape[0], N = input.shape[1], BLOCK_SIZE_N = bn)
    return output
This post is licensed under CC BY 4.0 by the author.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。