






Paper · 2026
Dingbang Wu1,*, Rui Hao1,*, Haiyang Wang2, Shuzhe Wu, Han Xiao3, Zhenghong Li1, Bojiang Zhou1, Zheng Ju1, Zichen Liu1, Lue Fan1,†,‡, Zhaoxiang Zhang1,†
1Institute of Automation, Chinese Academy of Sciences · 2Peking University · 3The Chinese University of Hong Kong
*Equal contribution. †Corresponding authors. ‡Project lead.
TL;DR
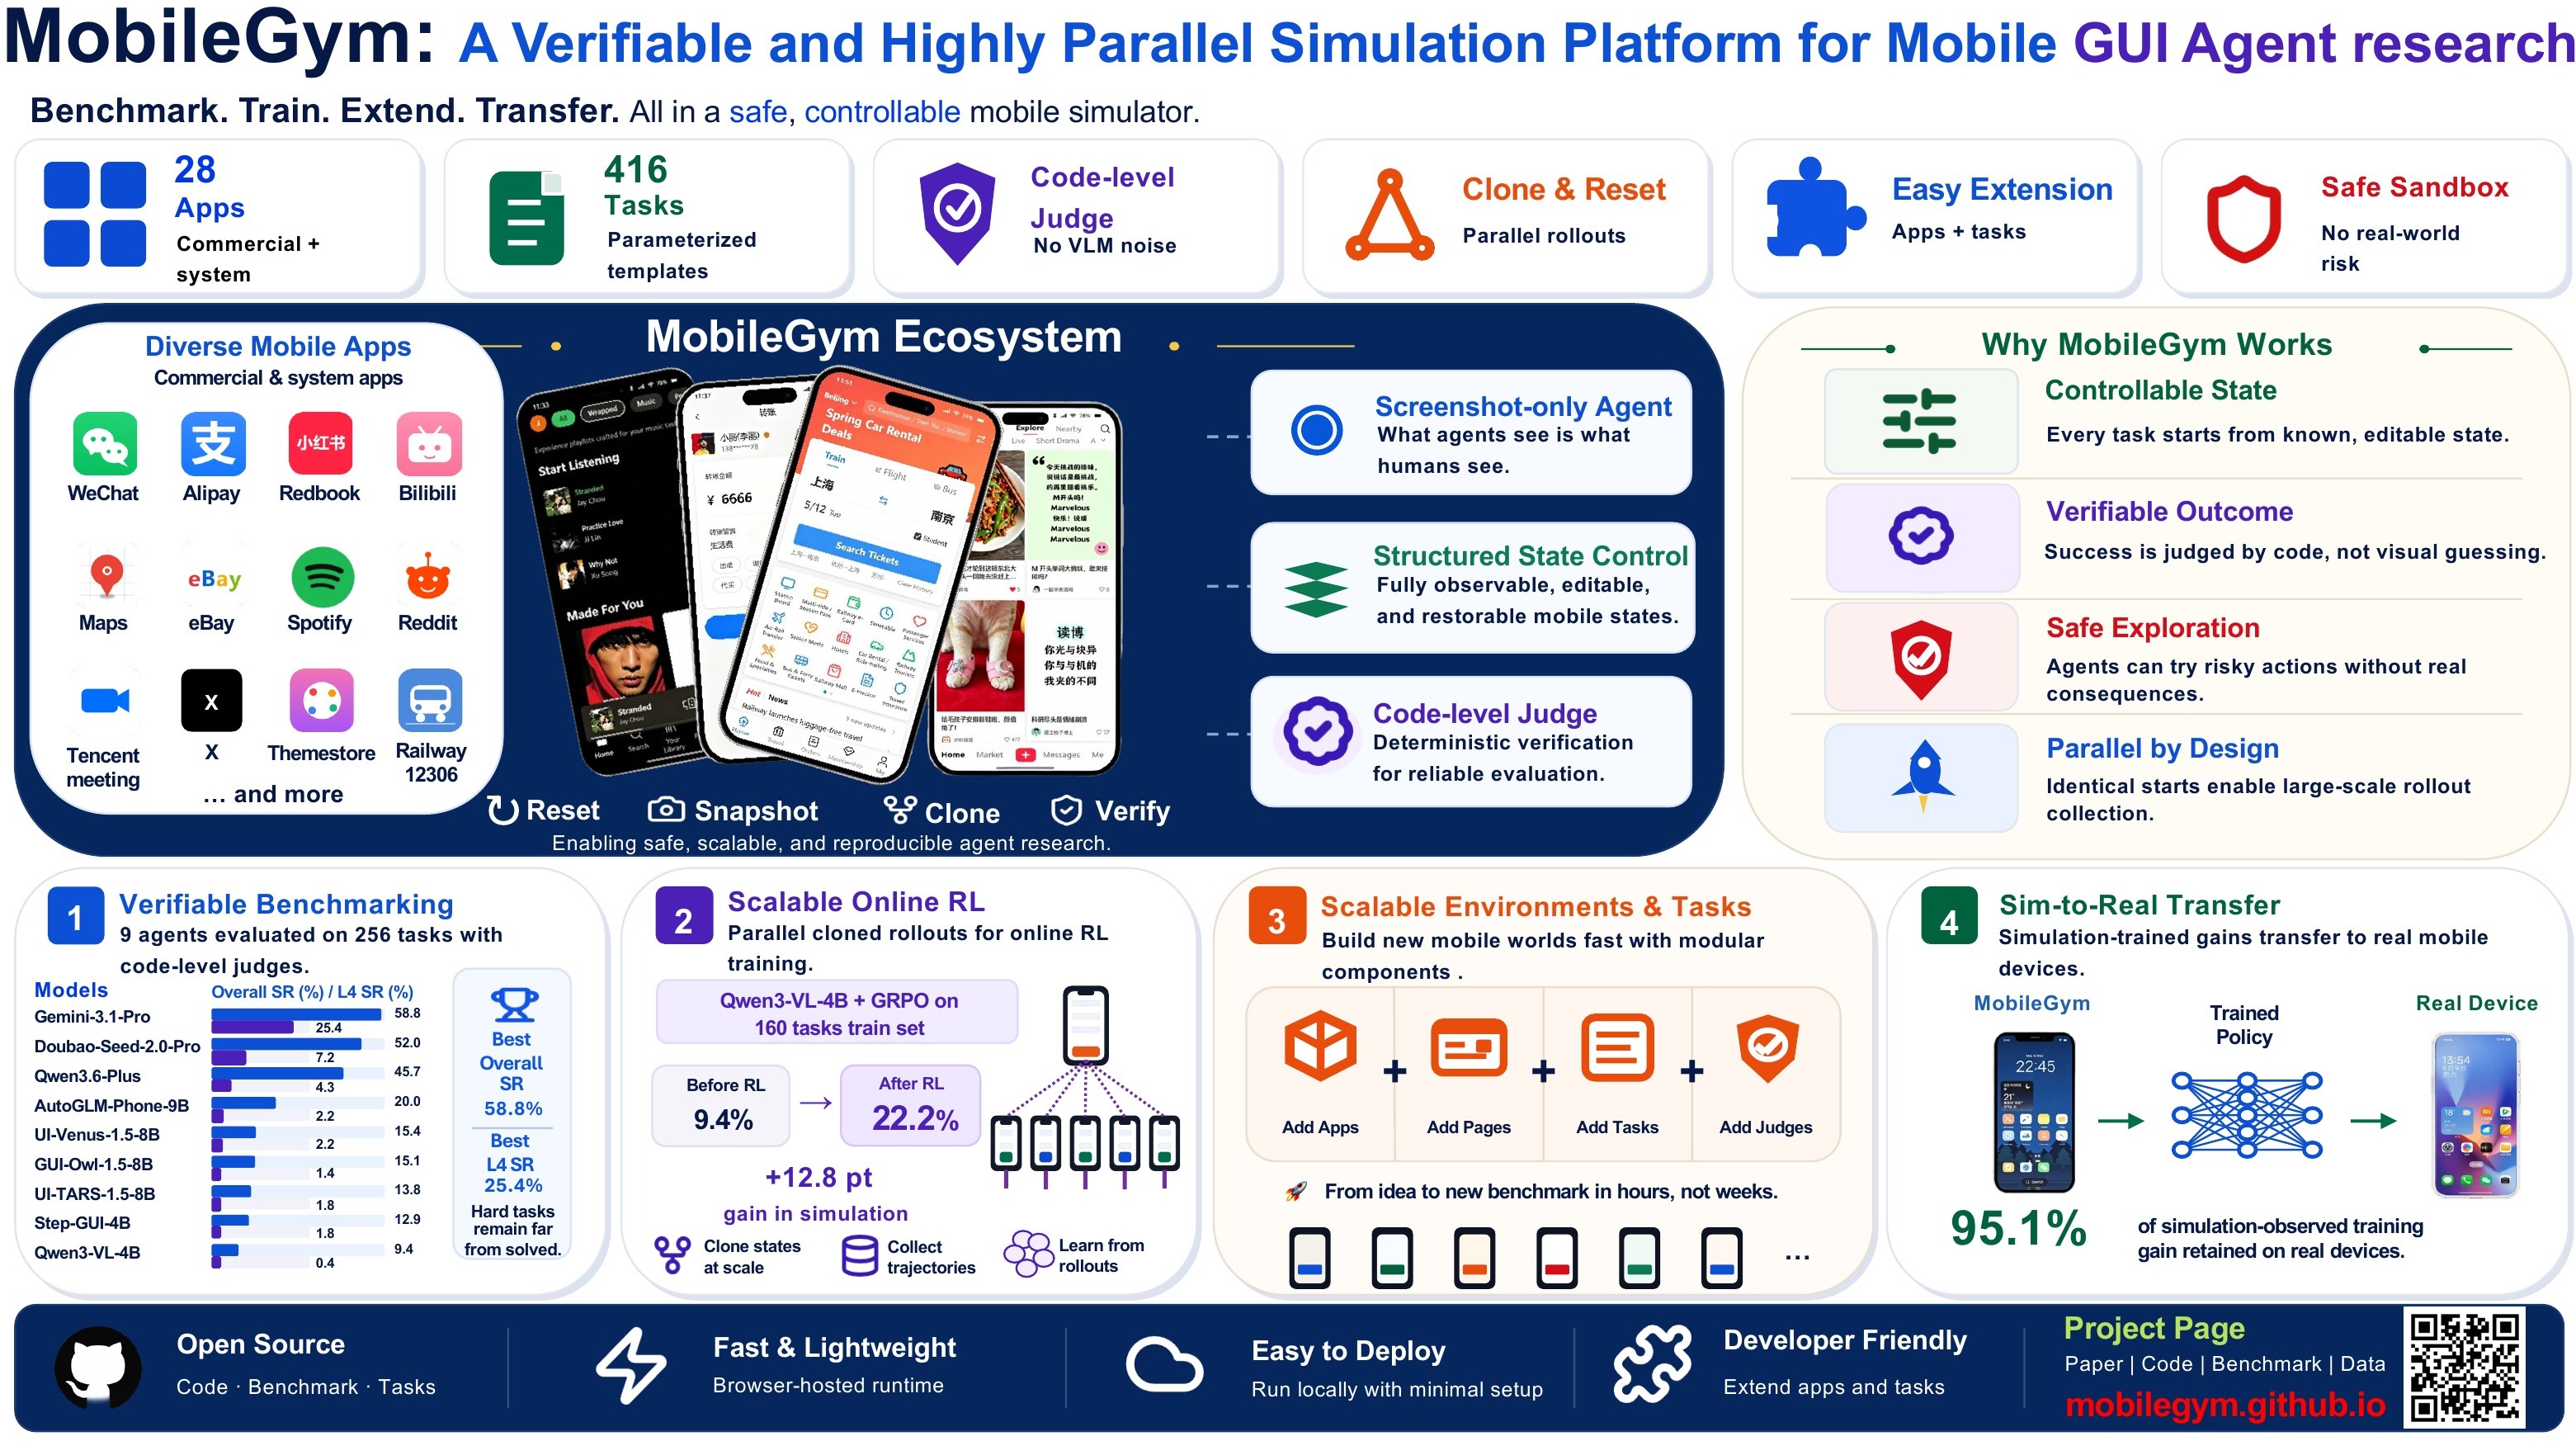
MobileGym is a verifiable and highly parallel simulation platform for mobile GUI agent research — the first to make online RL training and deterministic evaluation feasible on real-world daily apps, long a structural blind spot of real-device pipelines. It covers 28 mobile apps (12 daily + 16 system) in the browser. Across the released validation suite, programmatic state judges show no false accept/reject cases over 416 parameterized task templates (vs. 10.2% misjudgment when the same real-device trajectories are scored by a VLM), giving a clean RL reward signal; structured state replication (∼400 MB per browser instance) makes single-machine batch-parallel GRPO cheap. Sim-to-Real: GRPO fine-tuning of Qwen3-VL-4B lifts overall simulation SR by +12.8 pt (9.4%→22.2%); on the 59-task real-device-runnable signal-bucket subset, the +42.8 pt simulation gain is preserved as +40.7 pt on the real device — 95.1% retention.
28
Apps simulated
12 daily + 16 system
416
Parameterized task templates
256 test + 160 train
0
False accept/reject
released checks vs. 10.2% VLM judge error
+40.7pt
Real-device gain
Qwen3-VL-4B trained on sim
Each app is a faithful in-browser re-implementation in React/TypeScript, with Android-style task stacks, Intent routing, ContentProviders, and permission flows. Hover a row to pause.
All registered via manifest auto-discovery — adding a new app needs zero changes to the OS or benchmark layer. ~3–4 person-days per daily app, <1 day per system app.
Why daily apps stay out of reach
That's why benchmarks quietly avoid WeChat, Alipay, and 12306 — and why online RL on the apps users actually live in has barely been attempted at scale. Three structural walls in the real-device pipeline:
And it gets worse. GUI agents — and the VLM judges that grade them — observe the world as discrete screenshots sampled at intervals, not continuous video. A success toast captured at exactly the wrong frame turns a failed transfer into a passing test; a half-rendered loading spinner can swing the verdict either way. The screen isn't just a summary — it's an unreliable witness.
One Mechanism, Three Answers
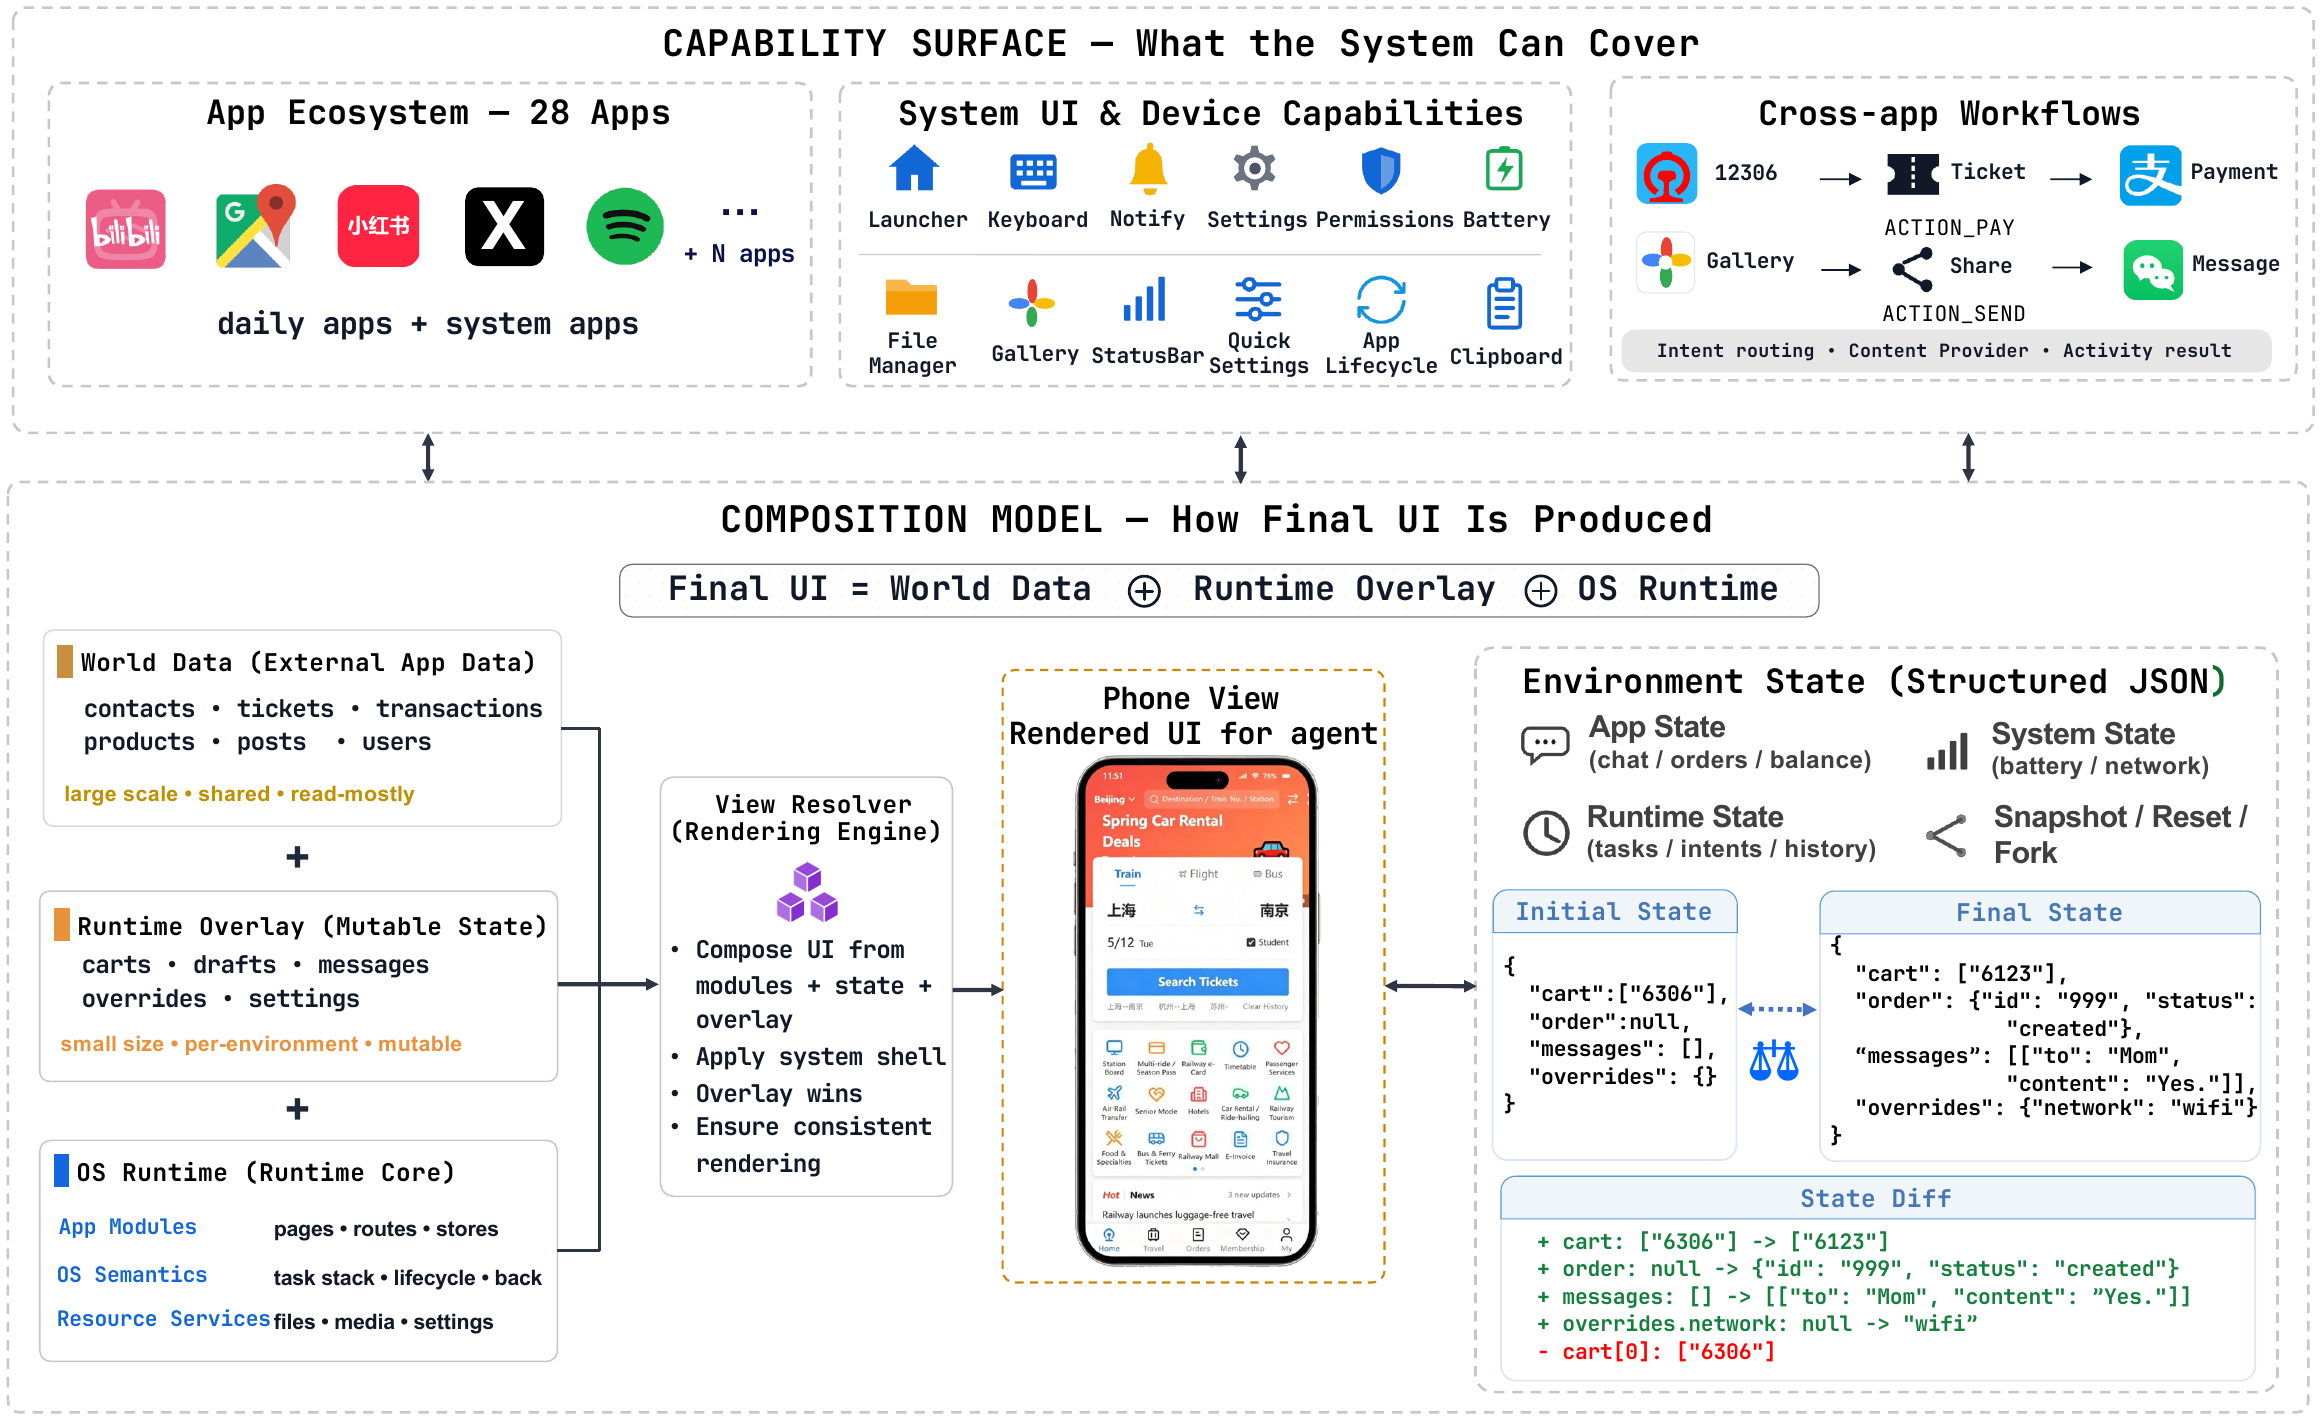
MobileGym answers all three with the same primitive: the entire environment is structured JSON. State is readable (judges inspect the structure directly — no VLM, no screenshots), writable (snapshot, fork, and restore in milliseconds; hundreds of identical rollouts on one machine), and consequence-free (every transfer, deletion, and purchase lives in a sandbox). Payment, ticketing, and account management — long skipped by real-device pipelines — become benchmarkable and trainable.
The whole stack runs in a single browser tab on top of React + TypeScript + Vite. The figure below shows what MobileGym covers and how each phone view is produced.
We evaluate 9 representative agents on the test set. L1-L4 are diagnostic strata calibrated jointly on the reference panel's mean SR and PR; L1 is relatively saturated, while L4 captures frontier-level tasks. SR is overall Success Rate.
| Model | L1 (20) |
L2 (73) |
L3 (83) |
L4 (80) |
SR |
|---|---|---|---|---|---|
| Proprietary models | |||||
| Gemini 3.1 Pro | 97.5 | 83.6 | 63.3 | 21.9 | 58.8 |
| Doubao-Seed-2.0-Pro | 100.0 | 93.2 | 48.2 | 6.2 | 52.0 |
| Qwen3.6-Plus | 100.0 | 78.1 | 44.6 | 3.8 | 45.7 |
| Open-source GUI-specialized models | |||||
| AutoGLM-Phone-9B | 86.2 | 33.6 | 9.6 | 1.9 | 20.0 |
| UI-TARS-1.5-8B | 77.5 | 21.9 | 3.0 | 1.6 | 13.8 |
| UI-Venus-1.5-8B | 85.0 | 21.9 | 6.0 | 1.9 | 15.4 |
| GUI-Owl-1.5-8B-Think | 76.2 | 26.0 | 4.2 | 1.2 | 15.1 |
| Step-GUI-4B | 83.8 | 17.8 | 2.4 | 1.6 | 12.9 |
| Open-source generalist models | |||||
| Qwen3-VL-4B | 71.2 | 12.3 | 0.6 | 0.3 | 9.4 |
Even Gemini 3.1 Pro reaches only 21.9 on L4, indicating substantial remaining headroom for future mobile GUI agents. Difficulty bins are calibrated jointly on the reference panel's mean SR and PR; calibration excludes Qwen3-VL-4B and its fine-tuned variants.
Reinforcement-fine-tuning Qwen3-VL-4B with GRPO on a single 3×RTX Pro 6000 node (10 training steps, 96 parallel browser instances) lifts overall simulation SR from 9.4% → 22.2% (+12.8 pt). On the 59-task real-device-runnable signal-bucket subset, simulation SR rises from 33.9% → 76.7% (+42.8 pt) and the real-device pass rate rises from 32.2% → 72.9% (+40.7 pt) — a 95.1% retention of the simulation gain:
| Bucket | n | Base | Trained (after GRPO) | ||
|---|---|---|---|---|---|
| Sim | Real | Sim | Real | ||
| Uplift | 23 | 2.2% | 17.4% | 80.7% | 73.9% |
| Stable-pass | 18 | 95.8% | 61.1% | 95.8% | 94.4% |
| Mid | 18 | 12.5% | 22.2% | 52.6% | 50.0% |
| Total | 59 | 33.9% | 32.2% | 76.7% | 72.9% |
Δ retention sim → real: 95.1% — gains preserved on real device
The gains are not only aggregate: the trained model also recovers from an out-of-distribution real-device constraint. On Reddit_CreatePostToCommunity, the real-device community requires a flair tag on every post — a constraint the simulator does not enforce. The base model loops on a greyed-out "Post" button for the full 60-step budget; the trained model, after two failed clicks, notices the asterisk on the flair selector, picks a flair, and submits successfully.
The flair-required behavior is unique to the real-device community and is absent from the simulator's training distribution. Recovery is driven by visual reasoning over the greyed button + asterisk cue, a concrete example of the behavior that online RL on a controllable substrate can induce. Full trace and verbatim think-trace in the paper appendix.
Single-instance, headless, measured against a Docker AndroidWorld setup (no KVM). MobileGym uses roughly one-tenth the memory and less than one-hundredth the disk footprint of the emulator baseline. Its structured JSON state can be restored and forked directly, which enables GRPO-style same-initial-state parallel sampling at single-machine scale.
Memory / instance
∼400 MB vs ∼4.5 GB
Disk footprint
∼50 MB vs ∼20 GB
Headless / single instance, measured against Docker AndroidWorld (no KVM); see paper Appendix for measurement details.
@misc{wu2026mobilegymverifiablehighlyparallel,
      title={MobileGym: A Verifiable and Highly Parallel Simulation Platform for Mobile GUI Agent Research},
      author={Dingbang Wu and Rui Hao and Haiyang Wang and Shuzhe Wu and Han Xiao and Zhenghong Li and Bojiang Zhou and Zheng Ju and Zichen Liu and Lue Fan and Zhaoxiang Zhang},
      year={2026},
      eprint={2605.26114},
      archivePrefix={arXiv},
      primaryClass={cs.AI},
      url={https://arxiv.org/abs/2605.26114}
}
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。