



百度反爬在2020年明显比以往严重,而且反爬策略中除了限制ip、header头等常规操作外,还有一些高级反爬。以往查询排名的脚本直接拼接访问搜索url获取源码就行,比如查询seo排名则直接请求https://www.baidu.com/s?wd=seo即可。
现在这种拼接url的方式不准确了,因为直接请求搜索url没有鼠标的动作无法触发gif请求,正常的人类在搜索的时候会点击输入框然后打字点击搜索,这个过程会触发一些gif请求。如下:
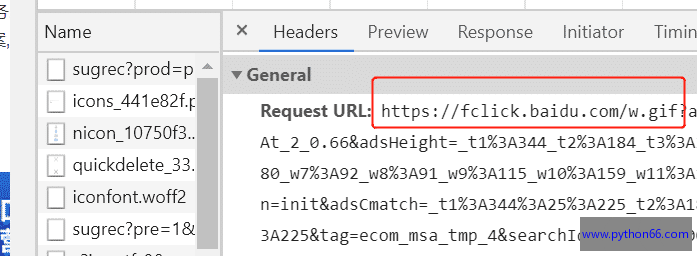
没有鼠标的动作,直接拼接搜索Url已经无法100%获取准确的源码(有时候准确有时候不准),所以改用selenium来真正的模拟浏览器的动作。百度PC多站点排名监控脚本如下
# ‐*‐ coding: utf‐8 ‐*‐
"""
必须单线程,1是因为百度反爬2是写入文件未加锁可能错乱
selenium驱动浏览器的方式 默认为无头模式,
selenium不支持长时间操作浏览器,为了解决该问题代码检测抛出异常就重启
log.txt记录异常
准备headers.txt 一行一个UA
准备cookies.txt 一行一个cookie
功能:
   1)指定几个域名,分关键词种类监控首页词数
   2)抓取serp所有url,提取域名并统计各域名首页覆盖率
   3)通过tpl属性记录serp排名url的特征
提示:
  1)含自然排名和百度开放平台的排名
  2)百度开放平台的样式mu属性值为排名url,mu不存在提取article里的url
  3)2020xiaoqu_kwd_city_new.xlsx:sheet名为关键词种类,sheet第一列放关键词
结果:
    bdpc1_index_info.txt:各监控站点词的排名及url,如有2个url排名,只取第一个
    bdpc1_index_all.txt:serp所有url及样式特征,依此统计各域名首页覆盖率-单写脚本统计
    bdpc1_index.xlsx:自己站每类词首页词数
    bdpc1_index_domains.xlsx:各监控站点每类词的首页词数
    bdpc1_index_domains.txt:各监控站点每类词的首页词数
"""

from pyquery import PyQuery as pq
import threading
import queue
import time
from urllib.parse import urlparse
from openpyxl import load_workbook
from openpyxl import Workbook
import time
import gc
import random
import urllib3
import requests
import os
from selenium import webdriver
from selenium.webdriver.common.by import By
from selenium.webdriver.support.ui import WebDriverWait
from selenium.webdriver.support import expected_conditions as EC
from selenium.webdriver.chrome.options import Options
import random
from selenium.webdriver.common.desired_capabilities import DesiredCapabilities
import traceback


urllib3.disable_warnings(urllib3.exceptions.InsecureRequestWarning)


# 杀死进程
def kill_process(p_name):
    try:
        os.system('taskkill /im {0}.exe /F'.format(p_name))
    except Exception as e:
        pass
    else:
        pass


# 计算最终结果
def get_result(file_path, result):
    for line in open(file_path, 'r', encoding='utf-8'):
        line = line.strip().split('	')
        rank = line[2]
        group = line[3]
        domain = line[4]
        if rank != '无':
            result[domain][group]['首页'] += 1
        result[domain][group]['总词数'] += 1
    return result


# 写txt,所有监控域名的结果
def write_domains_txt(result_last):
    with open('{0}bdpc1_index_domains.txt'.format(today), 'w', encoding="utf-8") as f_res:
        f_res.write('{0}	{1}	{2}	{3}	{4}
'.format('日期', '域名', '词类', '首页词数', '查询词数'))
        for now_domain, dict_value in result_last.items():
            for group, dict_index_all in dict_value.items():
                f_res.write('{0}	{1}	{2}	'.format(today, now_domain, group))
                for key, value in dict_index_all.items():
                    f_res.write(str(value) + '	')
                f_res.write('
')


# 写excel
def write_myexcel(group_list, result_last, today, my_domain):
    wb = Workbook()
    wb_all = Workbook()
    # 创建sheet写表头
    for group in group_list:
        sheet_num = 0
        wb.create_sheet(u'{0}'.format(group), index=sheet_num)
        wb_all.create_sheet(u'{0}'.format(group), index=sheet_num)
        row_first = ['日期', '首页', '总词数']
        row_first2 = ['日期', '域名', '首页', '总词数']
        # 写表头
        wb[group].append(row_first)
        wb_all[group].append(row_first2)
        sheet_num += 1
    # 写内容
    for domain, dict_value in result_last.items():
        if domain == my_domain:
            for group, dict_index_all in dict_value.items():
                # 写数据
                row_value = [today]
                for key, value in dict_index_all.items():
                    row_value.append(value)
                wb[u'{0}'.format(group)].append(row_value)

        for group, dict_index_all in dict_value.items():
            # 写数据
            row_value = [today, domain]
            for key, value in dict_index_all.items():
                row_value.append(value)
            wb_all[u'{0}'.format(group)].append(row_value)
    wb.save('{0}bdpc1_index.xlsx'.format(today))
    wb_all.save('{0}bdpc1_index_domains.xlsx'.format(today))


def get_driver(chrome_path,chromedriver_path,ua):
    ua = ua
    option = Options()
    option.binary_location = chrome_path
    # option.add_argument('disable-infobars')
    option.add_argument("user-agent=" + ua)
    option.add_argument("--no-sandbox")
    option.add_argument("--disable-dev-shm-usage")
    option.add_argument("--disable-gpu")
    option.add_argument("--disable-features=NetworkService")
    # option.add_argument("--window-size=1920x1080")
    option.add_argument("--disable-features=VizDisplayCompositor")
    option.add_argument('headless')
    option.add_argument('log-level=3') #屏蔽日志
    option.add_argument('--ignore-certificate-errors-spki-list') #屏蔽ssl error
    option.add_argument('-ignore -ssl-errors') #屏蔽ssl error
    No_Image_loading = {"profile.managed_default_content_settings.images": 2}
    option.add_experimental_option("prefs", No_Image_loading)
    option.add_argument('--disable-dev-shm-usage')
    caps = DesiredCapabilities.CHROME
    caps['acceptSslCerts'] = False #屏蔽ssl error
    driver = webdriver.Chrome(options=option, chrome_options=option,executable_path=chromedriver_path,desired_capabilities=caps)
    # 屏蔽特征
    driver.execute_cdp_cmd("Page.addScriptToEvaluateOnNewDocument", {
        "source": """
    Object.defineProperty(navigator, 'webdriver', {
      get: () => undefined
    })
  """
    })
    return driver


# 只解密加密url用
def get_header():
    my_header = {
        'Accept': 'text/html,application/xhtml+xml,application/xml;q=0.9,image/webp,image/apng,*/*;q=0.8,application/signed-exchange;v=b3;q=0.9',
        'Accept-Encoding': 'deflate',
        'Accept-Language': 'zh-CN,zh;q=0.9,en;q=0.8',
        'Cache-Control': 'max-age=0',
        'Connection': 'keep-alive',
        'Cookie': random.choice(list_cookies),
        'Host': 'www.baidu.com',
        'Sec-Fetch-Dest': 'document',
        'Sec-Fetch-Mode': 'navigate',
        'Sec-Fetch-Site': 'same-origin',
        'Sec-Fetch-User': '?1',
        'Upgrade-Insecure-Requests': '1',
        'User-Agent': random.choice(list_headers),
        }
    return my_header


class bdpcIndexMonitor(threading.Thread):
    def __init__(self):
        threading.Thread.__init__(self)

    @staticmethod
    def read_excel(filepath):
        q = queue.Queue()
        group_list = []
        kwd_dict = {}
        wb_kwd = load_workbook(filepath)
        for sheet_obj in wb_kwd:
            sheet_name = sheet_obj.title
            group_list.append(sheet_name)
            kwd_dict[sheet_name] = []
            col_a = sheet_obj['A']
            for cell in col_a:
                kwd = (cell.value)
                # 加个判断吧
                if kwd:
                    q.put([sheet_name, kwd])
        return q, group_list

    # 初始化结果字典
    @staticmethod
    def result_init(group_list):
        result = {}
        for domain in domains:
            result[domain] = {}
            for group in group_list:
                result[domain][group] = {'首页': 0, '总词数': 0}
        print("结果字典init...")
        return result

    # 获取某词serp源码所有url
    def get_encrpt_urls(self, html, url):
        encrypt_url_list = []
        real_urls = []
        doc = pq(html)
        title = doc('title').text()
        if '_百度搜索' in title and 'https://www.baidu.com/' in url:
            div_list = doc('.result').items()  # 自然排名
            div_op_list = doc('.result-op').items()  # 非自然排名
            for div in div_list:
                rank = div.attr('id')
                tpl = div.attr('tpl') if div.attr('tpl') else 'xxx'
                if rank:
                    try:
                        a = div('h3 a')
                    except Exception as e:
                        print('未提取自然排名加密链接')
                    else:
                        encrypt_url = a.attr('href')
                        encrypt_url_list.append((encrypt_url, rank, tpl))
            for div in div_op_list:
                rank_op = div.attr('id')
                tpl = div.attr('tpl') if div.attr('tpl') else 'xxx'
                if rank_op:
                    link = div.attr('mu')  # 真实url,有些op样式没有mu属性
                    # print(link,rank_op)
                    if link:
                        real_urls.append((link, rank_op, tpl))
                    else:
                        encrypt_url = div('article a').attr('href')
                        encrypt_url_list.append((encrypt_url, rank_op, tpl))

        else:
            print('源码异常,可能反爬', title)
            time.sleep(60)

        return encrypt_url_list, real_urls

    # 解密某条加密url
    def decrypt_url(self, encrypt_url, my_header, retry=1):
        real_url = None  # 默认None
        if encrypt_url:
            try:
                encrypt_url = encrypt_url.replace('http://', 'https://')
                r = requests.head(encrypt_url, headers=my_header)
            except Exception as e:
                print(encrypt_url, '解密失败', e)
                time.sleep(60)
                if retry > 0:
                    self.decrypt_url(encrypt_url, my_header, retry - 1)
            else:
                real_url = r.headers['Location'] if 'Location' in r.headers else None
        return real_url


    # 获取某词serp源码首页排名真实url
    def get_real_urls(self, encrypt_url_list):
        real_url_list = [self.decrypt_url(encrypt_url) for encrypt_url in encrypt_url_list]
        real_url_set = set(real_url_list)
        real_url_set.remove(None) if None in real_url_set else real_url_set
        real_url_list = list(real_url_set)
        return real_url_list

    # 提取某url的域名部分
    def get_domain(self, real_url):
        domain = None
        if real_url:
            try:
                res = urlparse(real_url)
            except Exception as e:
                print(e, 'real_url解析异常', real_url)
            else:
                domain = res.netloc # real_url为None返回字节数据
        return domain

    # 获取某词serp源码首页排名所有域名
    def get_domains(self, real_url_list):
        domain_str = ''
        domain_list = [self.get_domain(real_url) for real_url in real_url_list]
        # 一个词某域名多个url有排名,计算一次
        domain_set = set(domain_list)
        domain_set.remove(None) if None in domain_set else domain_set
        try:
            domain_str = ','.join(domain_set) if domain_set else ''  # 避免domain_list都是None
        except Exception as e:
            print(domain_set,e)
        else:
            pass
        return domain_str

    # 线程函数
    def run(self):
        global driver
        my_header = get_header()
        while 1:
            group_kwd = q.get()
            group, kwd = group_kwd
            print(group, kwd)
            try:
                driver.get('https://www.baidu.com/')
                # exit()
                input = WebDriverWait(driver, 30).until(
                    EC.visibility_of_element_located((By.ID, "kw"))
                )
                input_click_js = 'document.getElementById("kw").click()'
                driver.execute_script(input_click_js)  # 点击输入框

                input_js = 'document.getElementById("kw").value="{0}"'.format(kwd)
                driver.execute_script(input_js)  # 输入搜索词

                baidu = WebDriverWait(driver, 20).until(
                    EC.visibility_of_element_located((By.ID, "su"))
                )
                click_js = 'document.getElementById("su").click()'
                driver.execute_script(click_js)  # 点击搜索
                # 等待首页元素加载完毕
                next_page = WebDriverWait(driver, 20).until(
                    EC.visibility_of_element_located((By.ID, "help"))
                )
                # 页面下拉
                js_xiala = 'window.scrollBy(0,{0} * {1})'.format('document.body.scrollHeight', random.random() / 5)
                driver.execute_script(js_xiala)
                html = driver.page_source
                now_url = driver.current_url
                encrypt_url_list_rank, real_urls_rank = self.get_encrpt_urls(html, now_url)
            except Exception as e:
                print(e, '重启selenium')
                traceback.print_exc(file=open('log.txt', 'a'))
                driver.quit()
                # kill_process('chromedriver')
                gc.collect()
                driver = get_driver(chrome_path,chromedriver_path,ua)
            else:
                # 源码ok再写入
                if encrypt_url_list_rank:
                    for my_serp_url, my_order, tpl in encrypt_url_list_rank:
                        my_real_url = self.decrypt_url(my_serp_url, my_header)
                        time.sleep(0.01)
                        real_urls_rank.append((my_real_url, my_order, tpl))
                    real_urls = []  # 存真实urls,判断目标domain是否存在
                    for my_real_url, my_order, tpl in real_urls_rank:
                        real_urls.append(my_real_url)
                        # print(tpl)
                        f_all.write('{0}	{1}	{2}	{3}	{4}
'.format(kwd, my_real_url, my_order, tpl, group))
                    domain_str = self.get_domains(real_urls)
                    if domain_str:
                        # 目标站点是否出现
                        for domain in domains:
                            if domain not in domain_str:
                                f.write('{0}	{1}	{2}	{3}	{4}
'.format(kwd, '无', '无', group, domain))
                            else:
                                # my_url可能为None
                                for my_url, my_order, tpl in real_urls_rank:
                                    if domain in str(my_url):
                                        f.write(
                                            '{0}	{1}	{2}	{3}	{4}	{5}
'.format(kwd, my_url, my_order, group, domain,
                                                                                    tpl))
                                        # print(my_url, my_order)
                                        break  # 取第一个排名url
                f.flush()
                f_all.flush()
            finally:
                del group_kwd, kwd, group
                gc.collect()
                q.task_done()


if __name__ == "__main__":
    start = time.time()
    local_time = time.localtime()
    today = time.strftime('%Y%m%d', local_time)
    list_headers = [i.strip() for i in open('headers.txt', 'r', encoding='utf-8')]
    list_cookies = [i.strip() for i in open('cookies.txt', 'r', encoding='utf-8')]
    domains = ['5i5j.com', 'lianjia.com', 'anjuke.com', 'fang.com']  # 目标域名
    my_domain = '5i5j.com'
    chrome_path = 'C:/Program Files (x86)/Google/Chrome/Application/chrome.exe'
    chromedriver_path = 'D:/install/pyhon36/chromedriver.exe'
    ua = 'Mozilla/5.0 (Windows NT 6.1; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/84.0.4147.135 Safari/537.36'
    driver = get_driver(chrome_path,chromedriver_path,ua)
    q, group_list = bdpcIndexMonitor.read_excel('2020kwd_url_core_city_unique.xlsx')  # 关键词队列及分类
    result = bdpcIndexMonitor.result_init(group_list)  # 结果字典
    # print(result)
    all_num = q.qsize()  # 总词数
    f = open('{0}bdpc1_index_info.txt'.format(today), 'w', encoding="utf-8")
    f_all = open('{0}bdpc1_index_all.txt'.format(today), 'w', encoding="utf-8")
    file_path = f.name
    # 设置线程数
    for i in list(range(1)):
        t = bdpcIndexMonitor()
        t.setDaemon(True)
        t.start()
    q.join()
    f.close()
    f_all.close()
    # 根据bdpc1_index_info.txt计算结果
    result_last = get_result(file_path, result)
    # 写入txt文件
    write_domains_txt(result_last)
    # 写入excel
    write_myexcel(group_list, result_last, today, my_domain)
    # 统计查询成功的词数
    with open(file_path, 'r', encoding='utf-8') as fp:
        success = int(sum(1 for x in fp) / len(domains))
    end = time.time()
    print('关键词共{0}个,查询成功{1}个,耗时{2}min'.format(all_num, success, (end - start) / 60))
很赞哦!
python编程网提示:转载请注明来源www.python66.com。
有宝贵意见可添加站长微信(底部),获取技术资料请到公众号(底部)。同行交流请加群

此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。