








This blog post is also available as a recorded talk with slides.
Table of Contents
Performance optimization techniques in time series databases:
Internally, VictoriaMetrics makes heavy use of sync.Pool, a data structure built into
Go’s standard library. sync.Pool is intended to store temporary, fungible objects for reuse to relieve pressure on
the garbage collector. If you are familiar with free lists,
you can think of sync.Pool as a data structure that allows you to implement them in a thread-safe way.
A good example of where sync.Pool comes in handy is reusing bytes.Buffer objects.
bytes.Buffer objects are great for scenarios where you have to read some raw data and temporarily store it in the memory.
For example, VictoriaMetrics makes heavy use of bytes.Buffer objects when decompressing data from the database,
and when parsing metric metadata on scrapes.
Importantly, bytes.Buffer objects are little more than allocated sections of memory with some capacity
and availability tracking built in. They are temporary helper objects, and one bytes.Buffer can be easily swapped
in for another — they are fungible.
To avoid unnecessary allocations of bytes.Buffer objects, and to ease pressure on the garbage collector,
VictoriaMetrics has an internal data structure that uses sync.Pool to maintain a life-cycle of already allocated
bytes.Buffer objects:
type ByteBufferPool struct {
    p sync.Pool
}

func (bbp *ByteBufferPool) Get() *ByteBuffer {
    bbv := bbp.p.Get()
    if bbv == nil {
        return &ByteBuffer{}
    }
    return bbv.(*ByteBuffer)
}

func (bbp *ByteBufferPool) Put(bb *ByteBuffer) {
    bb.Reset()
    bbp.p.Put(bb)
}
The code above defines a type ByteBufferPool that contains a sync.Pool for storing bytes.Buffer objects.
It defines two methods on this type:
Get either returns a bytes.Buffer from the pool, or allocates and returns a new object.Put resets a bytes.Buffer and then adds it back into the pool, so it can be reused via Get later.ByteBufferPool is used a lot in the VictoriaMetrics codebase, and it significantly reduces the number
of new allocations it needs to perform.
There are a couple of things to be aware of when using sync.Pool in this way, however.
Internally, sync.Pool is implemented using per-processor local pools.
When goroutine is scheduled to run on a specific thread associated with specific
processor and will try to retrieve an object from the pool, sync.Pool will first look in the current processor local pool.
If it can’t find an object there it will try to “steal” an object from another processor pool.
Stealing an object from another pool takes time because of inter-CPU synchronization. If it can’t steal it, a new
object will be allocated.
Due to these local pools, the ideal scenario for using sync.Pool is where objects are retrieved and released
in the same goroutine, so these objects will belong to the same local processor pool where goroutine runs.
This heavily reduces context switches between retrieving the object from the pool and returning it to the pool.
It prevents object stealing and reduces the number of objects that are allocated overall,
further relieving pressure on the garbage collector.
A less ideal, but still viable use case for sync.Pool is where objects are synchronously processed by a single
goroutine at a time. For example, an object is retrieved from the pool in one goroutine, and then passed to another
goroutine, which uses the object and returns it to the pool.
The problem with the synchronous processing case is that there’s a higher chance for different goroutines to get scheduled
on different threads, which means the object will be retrieved from one local pool of one processor and returned to the
pool of another processor. This increases the chances that sync.Pool needs to steal an object, reducing performance.
Using sync.Pool to reuse objects in I/O-bound tasks is much less efficient than reusing objects for CPU-bound tasks.
I/O can be slow and sporadic, meaning that there is a high degree of randomness to how long an I/O operation will take.
This can lead to the number of calls to Get and Put becoming unbalanced, resulting in suboptimal reuse of objects:
sync.Pool are just sitting there occupying the memory;sync.Pool could be already removed by garbage collector
resulting in new allocations.ByteBufferPool usageOne use case VictoriaMetrics has for ByteBufferPool is decompressing stored data. Decompression is a CPU-bound
operation that allocates some temporary memory, which makes it a perfect candidate to use ByteBufferPool.
The code below illustrates the use of ByteBufferPool during a decompression operation:
bb := bbPool.Get() // acquire buffer from pool
// perform decompressing in acquired buffer
bb.B, err = DecompressZSTD(bb.B[:0], src)
if err != nil {
    return nil, fmt.Errorf("cannot decompress: %w", err)
}
// unmarshal from temporary buffer to destination buffer
dst, err = unmarshalInt64NearestDelta(dst, bb.B)
bbPool.Put(bb) // release buffer to the pool, so it can be reused
The above code gets a bytes.Buffer from bbPool, a ByteBufferPool type. It then decompresses a block that has
already been read from disk and places the result into the retrieved bytes.Buffer. It’s important to note that
the block has already been read from disk, as this makes the decompression operation entirely CPU-bound
and maintains the balance between Get and Put calls.
Once the code has decompressed the block, it writes the result to a destination, dst, and returns the buffer to the pool,
so it can be reused. It is important not to return bb or store references to it, as it can be acquired and modified
by another goroutine at any moment after being returned to pool.
bytes.Buffer poolsSo far, the examples in this article have assumed that all bytes.Buffers are interchangeable.
While this is technically true, in the real world buffers come in a wide range of sizes.
This can lead to inefficient memory usage if code that uses a small amount of memory receives a large buffer from
the pool and vice versa.
As an example, one target for metrics scraping might expose 100 metrics while another might expose 10,000.
The vmagent goroutine that scrapes each target would need a different buffer size. In the ByteBufferPool
implementation above, calling code has no control over the size of the buffer it receives. So the scraping goroutine
can retrieve a smaller buffer than needed and spend extra time on expanding it. This would slowly replace small buffers
in the pool with bigger buffers, increasing the overall memory usage.
You can improve the efficiency of ByteBufferPool by splitting it into multiple levels, or buckets.
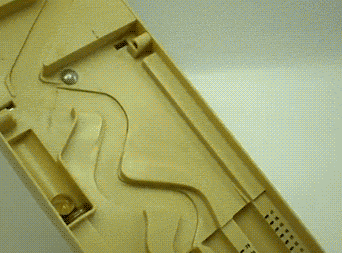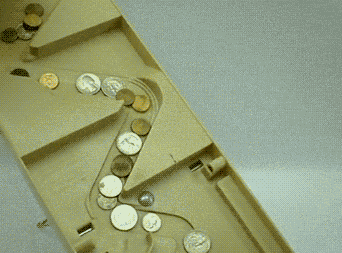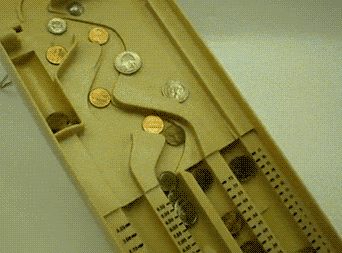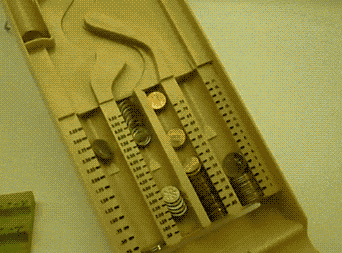 An example of objects sorting to different buckets
Each level contains a different range of buffer sizes and requests to the pool can request a certain size based on the expected requirement.
// pools contains pools for byte slices of various capacities.
//
// pools[0] is for capacities from 0 to 8
// pools[1] is for capacities from 9 to 16
// pools[2] is for capacities from 17 to 32
// ...
// pools[n] is for capacities from 2^(n+2)+1 to 2^(n+3)
//
// Limit the maximum capacity to 2^18, since there are no performance benefits
// in caching byte slices with bigger capacities.
var pools [17]sync.Pool
The above code snippet shows how these levels are represented in VictoriaMetrics’
leveledbytebufferpool package.
The maximum capacity of a cached pool is limited to 2^18 bytes as we’ve found that the RAM cost of storing buffers
larger than this limit is not worth the savings
of not recreating those buffers.
Adding levels to a pool of buffers changes the Get method to require an expected size. This enables the pool to return
a buffer of the appropriate size. See the code snippet below for how this is used in the vmagent scraping example:
func (sw *scrapeWork) scrape() {
    body := leveledbytebufferpool.Get(sw.previousResponseBodyLength)
    body.B = sw.ReadData(body.B[:0])
    sw.processScrapedData(body)
    leveledbytebufferpool.Put(body)
}
The above code snippet gets a buffer based on the size needed for the last request to this scrape target.
The number of metrics a scrape target exposes doesn’t change much on each scrape and so this is a decent guess at how large
a buffer will be needed this time. The Put function signature hasn’t changed since the function can figure out how
large the buffer is itself.
Optimizations are always situation-dependent, but I hope that this series of articles has given you more tools that you can use to optimize your own applications. If this article has interested you in time series databases and the work we do at VictoriaMetrics, please check out our GitHub org. All our code is proudly open source and welcomes contributions.
If you’re interested in performance, I’d strongly recommend VictoriaMetrics: scaling to 100 million metrics per second, a talk given by our CTO in 2022 that is packed with technical details. You can also check out more talks from VictoriaMetrics team members in this YouTube playlist.
This article was originally a talk at GopherCon Europe 2023. You can watch the talk on YouTube, or read the slides.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。