







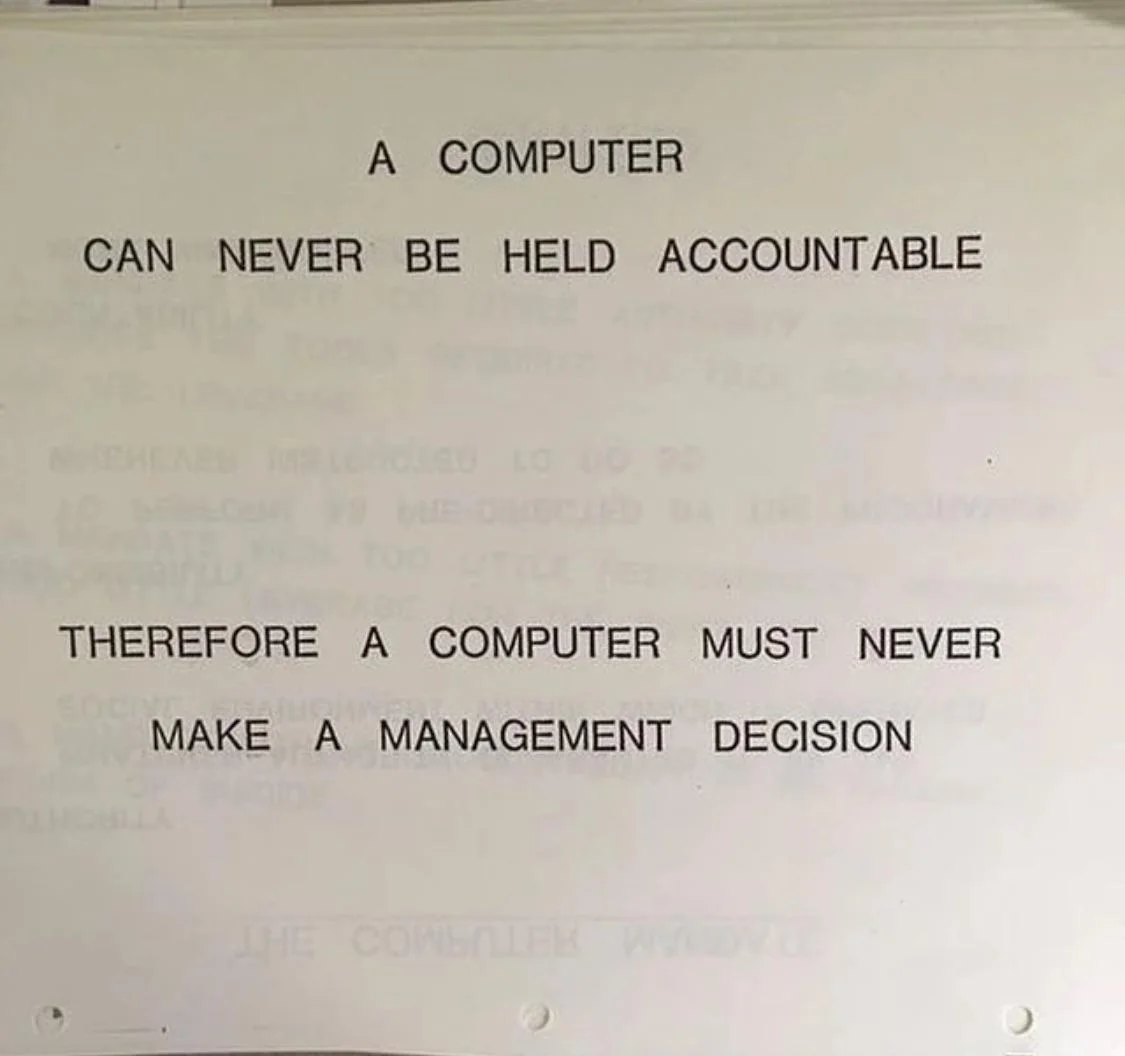
IBM training manual from 1979
When LLMs were really hitting their stride I started experimenting with them, like many others, to see where they could help me. I wanted to see how I could leverage them at work and in my free time. I’ve learned a lot since then, but I especially remember something I started doing, and that I’ve seen other people do as well: push responsibility onto the LLM.
I would say things like “here’s some research Claude did” or “the agent added this function”. Also variations on: “disclaimer, this was written by Claude”, or “I didn’t find the solution, Claude did”.
Looking back at it it's pretty fascinating. It’s like saying “oh I didn’t toast the bread, the toaster did”. Did I clean the floor? No, the vacuum did. Oh, I can’t take responsibility for this code, I just wrote the high level code, the compiler did all of the work. LLMs are just another tool that we can use to do things (although few compiler developers end up having to pay $1.5B for copyright violations). But the tool isn’t responsible for what it does. The computer can’t be held accountable. The police won’t arrest Claude for committing a crime, they’ll arrest the person using it. Because it’s a tool.
Side-note, this is part of why Co-authored-by: Claude feels off to me. Claude didn't co-author your code any more than VSCode or the node runtime did. Maybe it's just semantics but an Assisted-by tag like the Linux project requires makes more sense to me.
Part of it definitely comes down to not feeling like you can take pride in or credit for the work that the agent did, because agents make it so very easy to provide minimal input and get something that looks like effort out. There’s a little bit of shame that comes with that. Maybe it’s my Nordic upbringing, maybe it’s a universal thing. Part of it is definitely the way we all struggle with interacting with and talking about a tool that outputs human language. It's so hard to avoid using words like "thought", "misunderstood", "made a mistake", when talking about LLMs. And the model companies aren't exactly trying to prevent us from anthropomorphizing.
But I also realized it wasn't just not wanting to take credit. I was off-loading responsibility onto the computer too. I didn’t want to own the code in case it was wrong, because I didn’t really feel like it came from me. Even if I had read every line of code, that doesn’t mean I genuinely "grokked" it the way that I would’ve if I wrote it myself. I couldn’t claim to stand for everything in the document, because I didn’t write it. The sentences didn’t belong to me.
This was something that I’ve kept coming back to to reflect on. I’ve otherwise taken a lot of pride in my work, and there I was, pushing both credit and blame on the computer for actions that I took.
And they are our actions. When you prompt the agent and share the output, that's you doing it. You use the tool and you produce something that you share. You’re the only person involved. You’re the only one accountable for your actions. Not the computer. If you choose to have the LLM write the code or the document, for better or worse, it’s your code or document. Own it.
In the end it's a question of empathy. Empathy for the person on the other side who's going to read the thing you send them, the PR you open, the document you share.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。